GeezerVisonThe World Wide Web, restored to 800 pixels of glory. |
| Home|About|Gaming cabinet|Archives|How it works|Starter sites |
GeezerVison is showing crawlee.dev — Crawlee for Python · Fast, reliable Python web crawlers. Build reliable web scrapers. Fast.Crawlee is a web scraping library for JavaScript and Python. It handles blocking, crawling, proxies, and browsers for you. Run on Or start with a template from our CLI Built with 🤍 by Apify. Forever free and open-source. What are the benefits?Unblock websites by defaultCrawlee crawls stealthily with zero configuration, but you can customize its behavior to overcome any protection. Real-world fingerprints included. Learn moreWork with your favorite toolsCrawlee integrates BeautifulSoup, Cheerio, Puppeteer, Playwright, and other popular open-source tools. No need to learn new syntax. Learn more  One API for headless and HTTPSwitch between HTTP and headless without big rewrites thanks to a shared API. Or even let Adaptive crawler decide if JS rendering is needed. Learn moreWhat else is in Crawlee?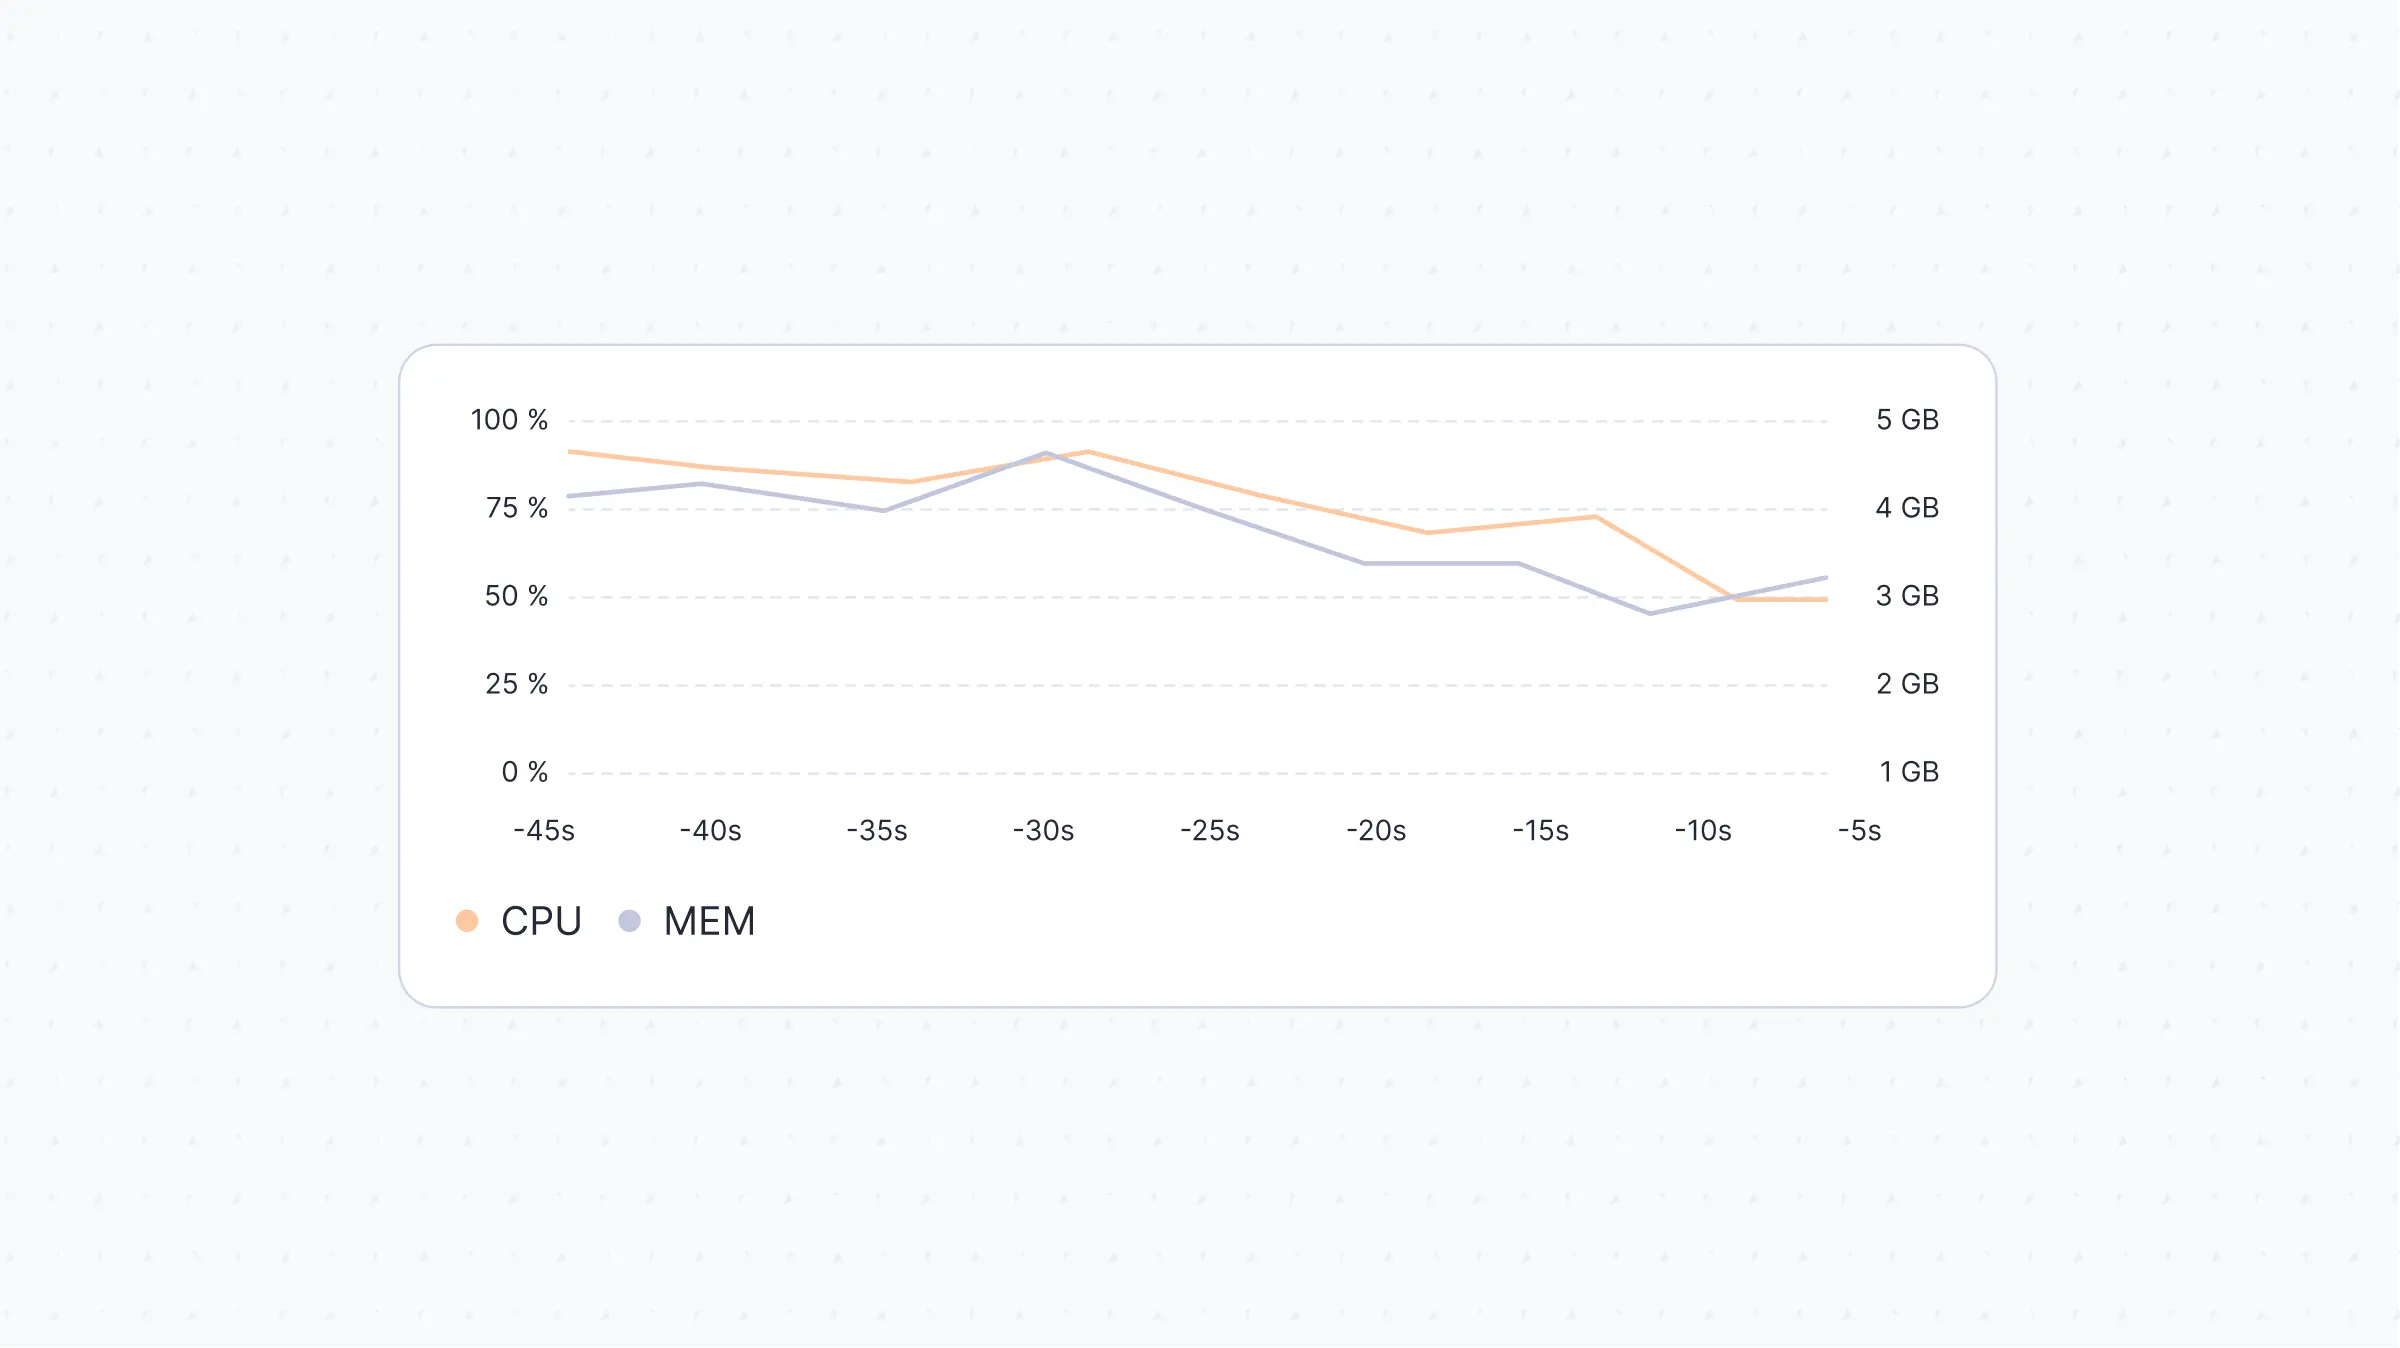 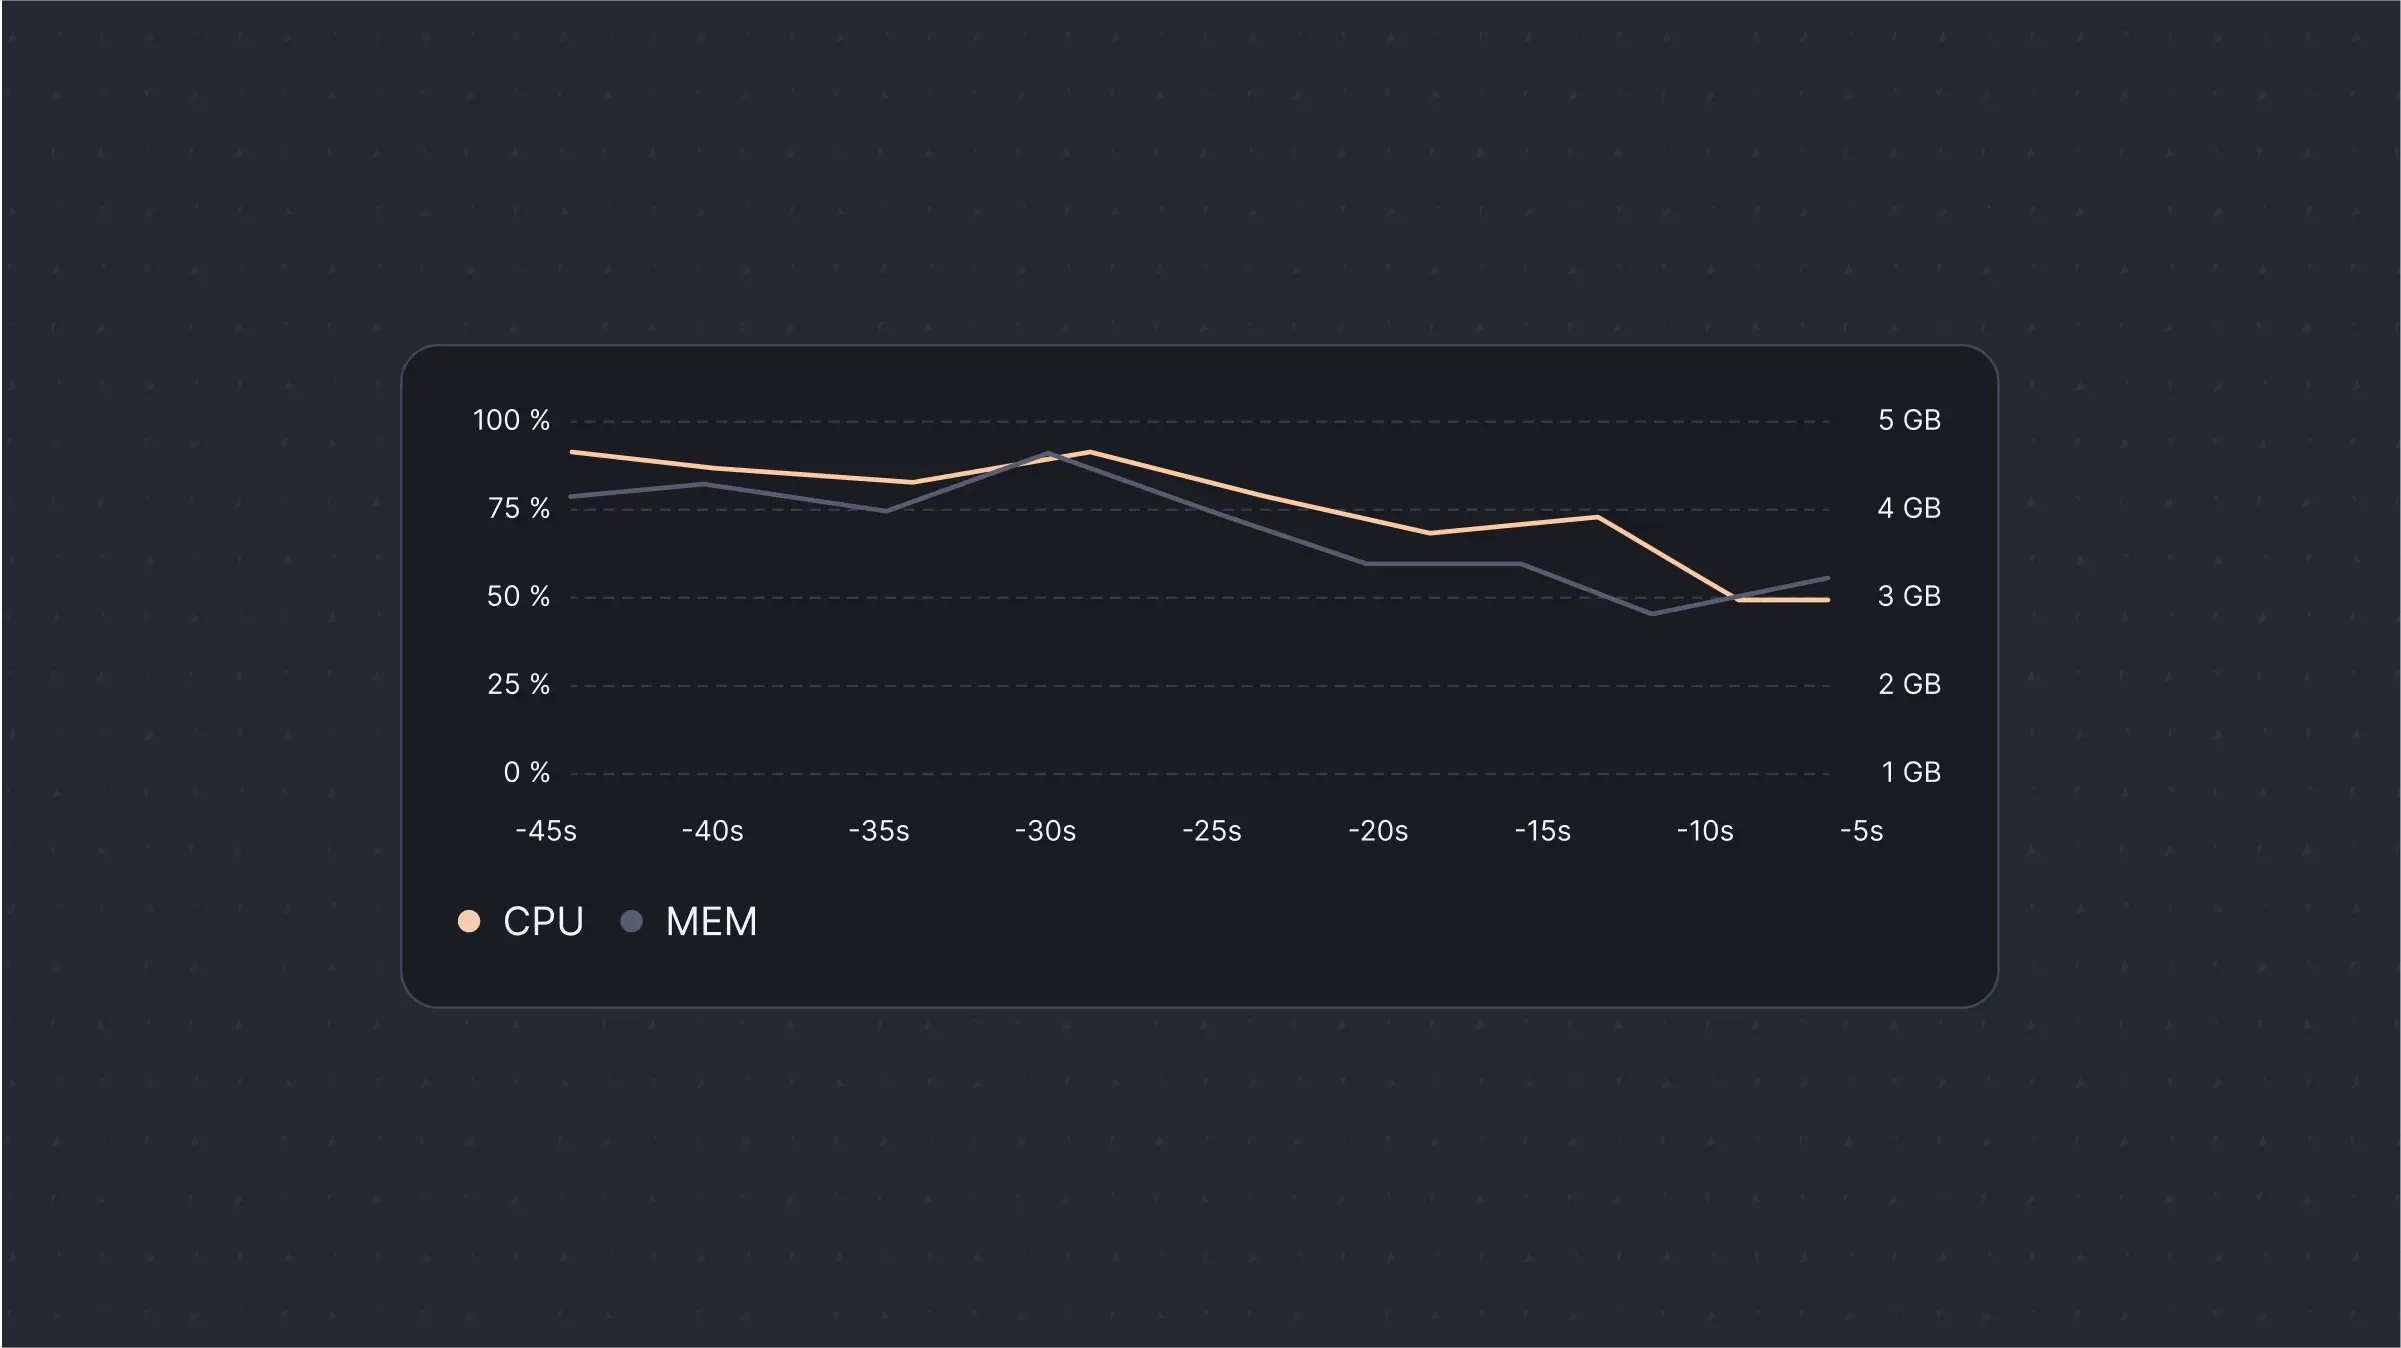 Auto scalingCrawlers automatically adjust concurrency based on available system resources. Avoid memory errors in small containers and run faster in large ones.   Smart proxy rotationCrawlee uses a pool of sessions represented by different proxies to maintain the proxy performance and keep IPs healthy. Blocked proxies are removed from the pool automatically.   Queue and storagePause and resume crawlers thanks to a persistent queue of URLs and storage for structured data.   Handy scraping utilsSitemaps, infinite scroll, contact extraction, large asset blocking and many more utils included.   Routing & middlewareKeep your code clean and organized while managing complex crawls with a built-in router that streamlines the process. Deploy to cloudCrawlee, by Apify, works anywhere, but Apify offers the best experience. Easily turn your project into an Actor—a serverless micro-app with built-in infra, proxies, and storage. Deploy to Apify1 Install Apify SDK and Apify CLI. 2 Add Actor.init()to the beginning and Actor.exit()to the end of your code. 3 Use the Apify CLI to push the code to the Apify platform. Crawlee helps you build scrapers faster  Zero setup requiredCopy code example, install Crawlee and go. No CLI required, no complex file structure, no boilerplate. Get started  Reasonable defaultsUnblocking, proxy rotation and other core features are already turned on. But also very configurable. Learn more  Helpful communityJoin our Discord community of over 10k developers and get fast answers to your web scraping questions. Join DiscordGet started now!Crawlee won’t fix broken selectors for you (yet), but it makes building and maintaining reliable crawlers faster and easier—so you can focus on what matters most. |
| You are visitor 01402503 — GeezerVison does not store the pages you look up. Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required. |

