GeezerVison is showing danielwusg.github.io — Shengguang Wu
Shengguang Wu
Ph.D. Student, Computer Science, Stanford University
Email: shgwu [AT] cs [DOT] stanford [DOT] edu


|
|
About me
I am a CS PhD student at Stanford, advised by Serena Yeung-Levy.
Previously, I worked with Qwen Team on open-source LLMs (Qwen) and post-training techniques (DiverseEvol).

I study how foundation models and agents self-improve and continually learn from experience, refining their skills, memory ( AutoMem), and tools ( TVP) over time, and adapting to new tasks well beyond their initial training. I am especially interested in models grounded in the physical world ( RoboArchitect, 3D-Generalist): sensing and acting in embodied environments, and learning from how the world reacts to their actions.
|
|
Selected Publications
|
|
|
|
Shengguang Wu, Suning Huang, Cherie Ho, Ria Doshi, Hao Zhu, Serena Yeung-Levy
ArXiv, 2026
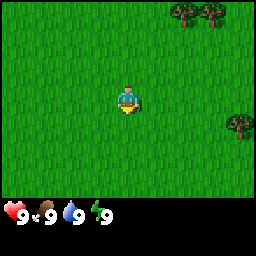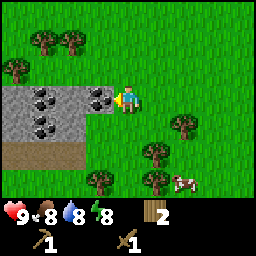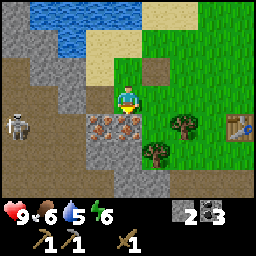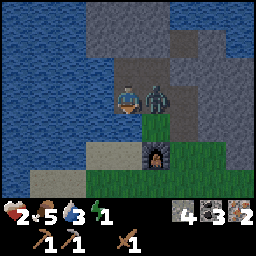
TL;DR: RoboArchitect automatically designs and continually improves a robotic agent around a frozen robot policy, without updating any weights. These agents develop their own control routines. Most converge on a dynamic split between the VLA policy and code-as-policy, and nearly all build a persistent memory across episodes. Average success rises substantially on unseen scenes and tasks. RoboArchitect also manages to evolve a unified agent across different robot platforms that calibrates itself to each robot.
|
|
Shengguang Wu, Hao Zhu, Yuhui Zhang, Xiaohan Wang, Serena Yeung-Levy
NeurIPS, 2026
TL;DR: We make memory management a trainable skill for LLM agents. AutoMem automates the learning of this skill end-to-end: automatically optimizing the agent scaffold (memory structure) and training a dedicated memory specialist from the agent's own traces (memory proficiency). This automated learning alone brings an open-weight Qwen2.5-32B to frontier-level performance on long-horizon tasks.
|
|
Shengguang Wu, Xiaohan Wang, Yuhui Zhang, Hao Zhu, Serena Yeung-Levy
ICLR, 2026
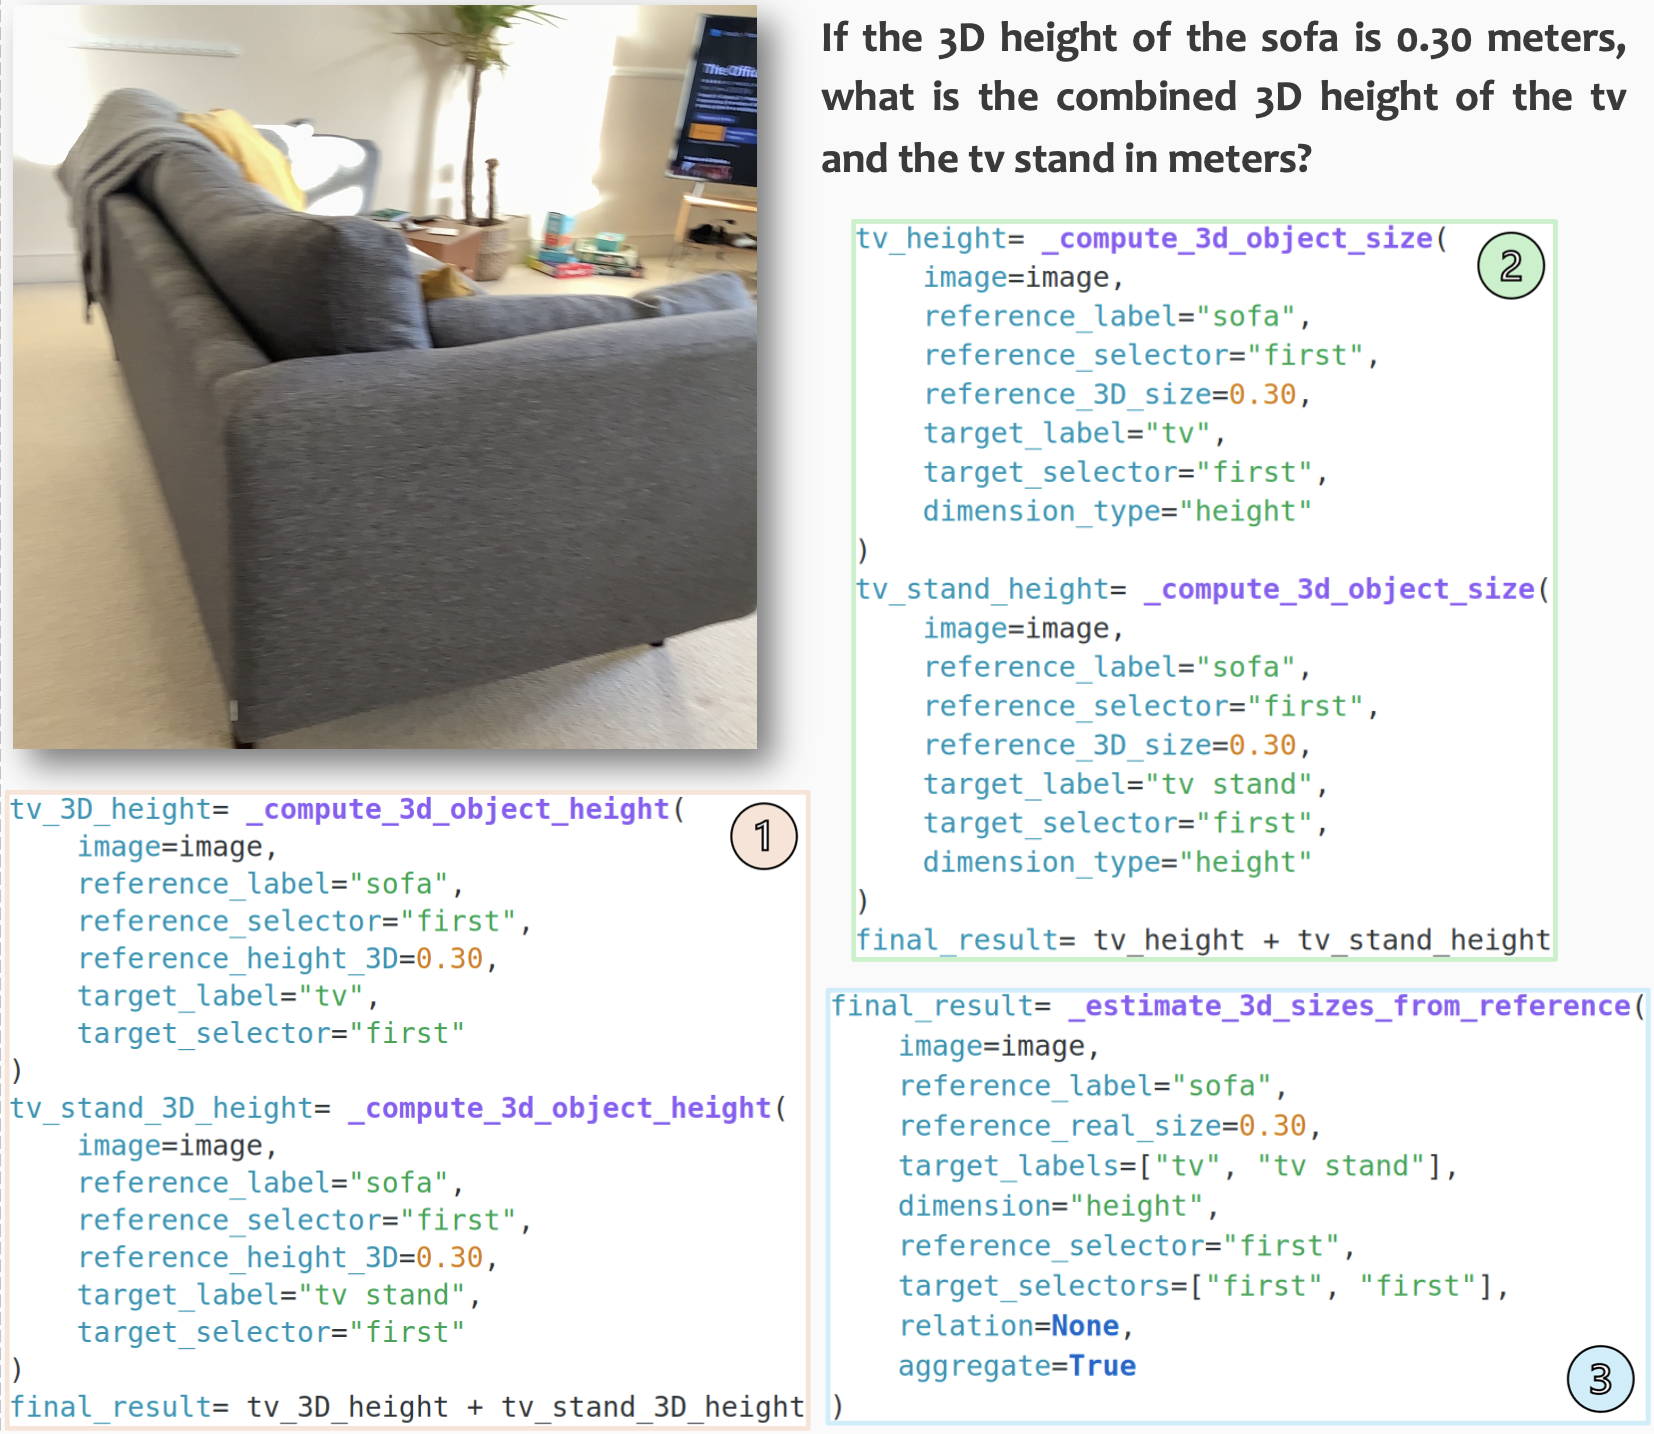
TL;DR: TVP is a new visual programming framework that builds reusable tools from its own problem-solving experience via two interconnected libraries: an Example Library that accumulates program solutions as experience, and a Tool Library that maintains functions abstracted from these programs. The dual-libraries enable the circular program-tool-program cycle: solving problems generates experience, experience guides tool creation, and newly created tools improve future problem-solving.
|
|
"An international restaurant with vibrant decor."
|
Fan-Yun Sun, Shengguang Wu, Christian Jacobsen, Thomas Yim, Haoming Zou, Alex Zook, Shangru Li, Ethem Can, Xunlei Wu, Clemens Eppner, Valts Blukis, Jonathan Tremblay, Jiajun Wu, Stan Birchfield, Nick Haber
3DV, 2026
TL;DR: 3D-Generalist is a generative graphics framework for creating 3D environments. Key modules include: 1. a diffusion-based panoramic generator that renders environment structures; 2. a VLA trained via self-improving loop for code generation to refine the environments; and 3. another VLA for placing diverse unlabeled 3D assets. 3D-Generalist provides a controllable pipeline to scale up synthetic 3D environment data for embodied AI.
|
|
Akaash Kolluri, Shengguang Wu, Joon Sung Park, Michael S. Bernstein
EMNLP-Main, 2025
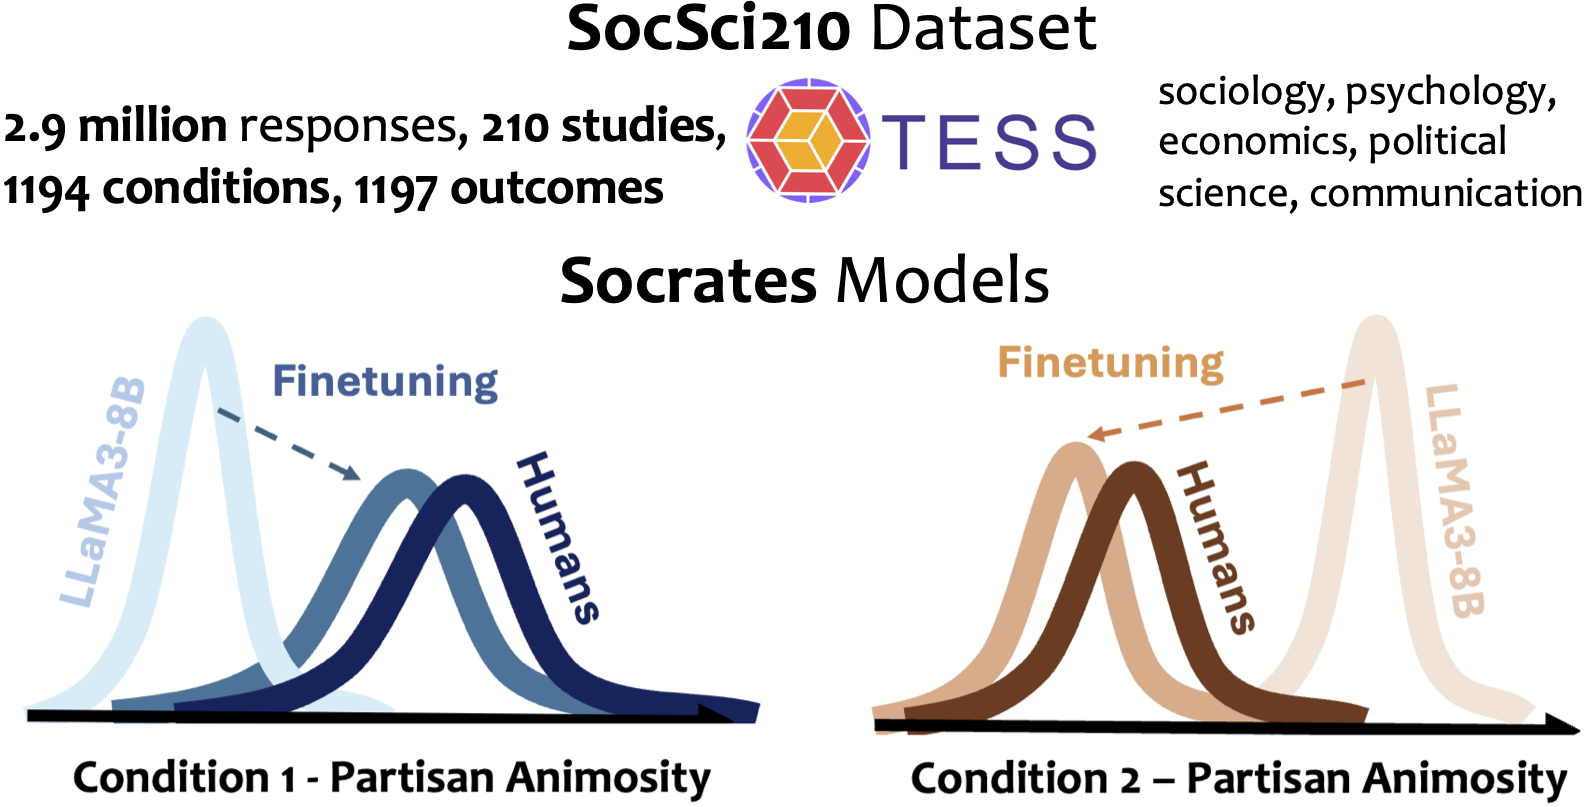
TL;DR: We release SocSci210, a dataset of 2.9 million responses from 400,491 participants across 210 social science experiments. Through finetuning, our Socrates models achieve substantially better alignment with human response distributions under varying experimental conditions. We show that finetuning on just a subset of conditions within a study enables robust generalization to unseen conditions, demonstrating the potential for accurate experimental hypothesis screening with limited sample data.
|
|
Shengguang Wu, Fan-Yun Sun, Kaiyue Wen, Nick Haber
ACL-Main, 2025
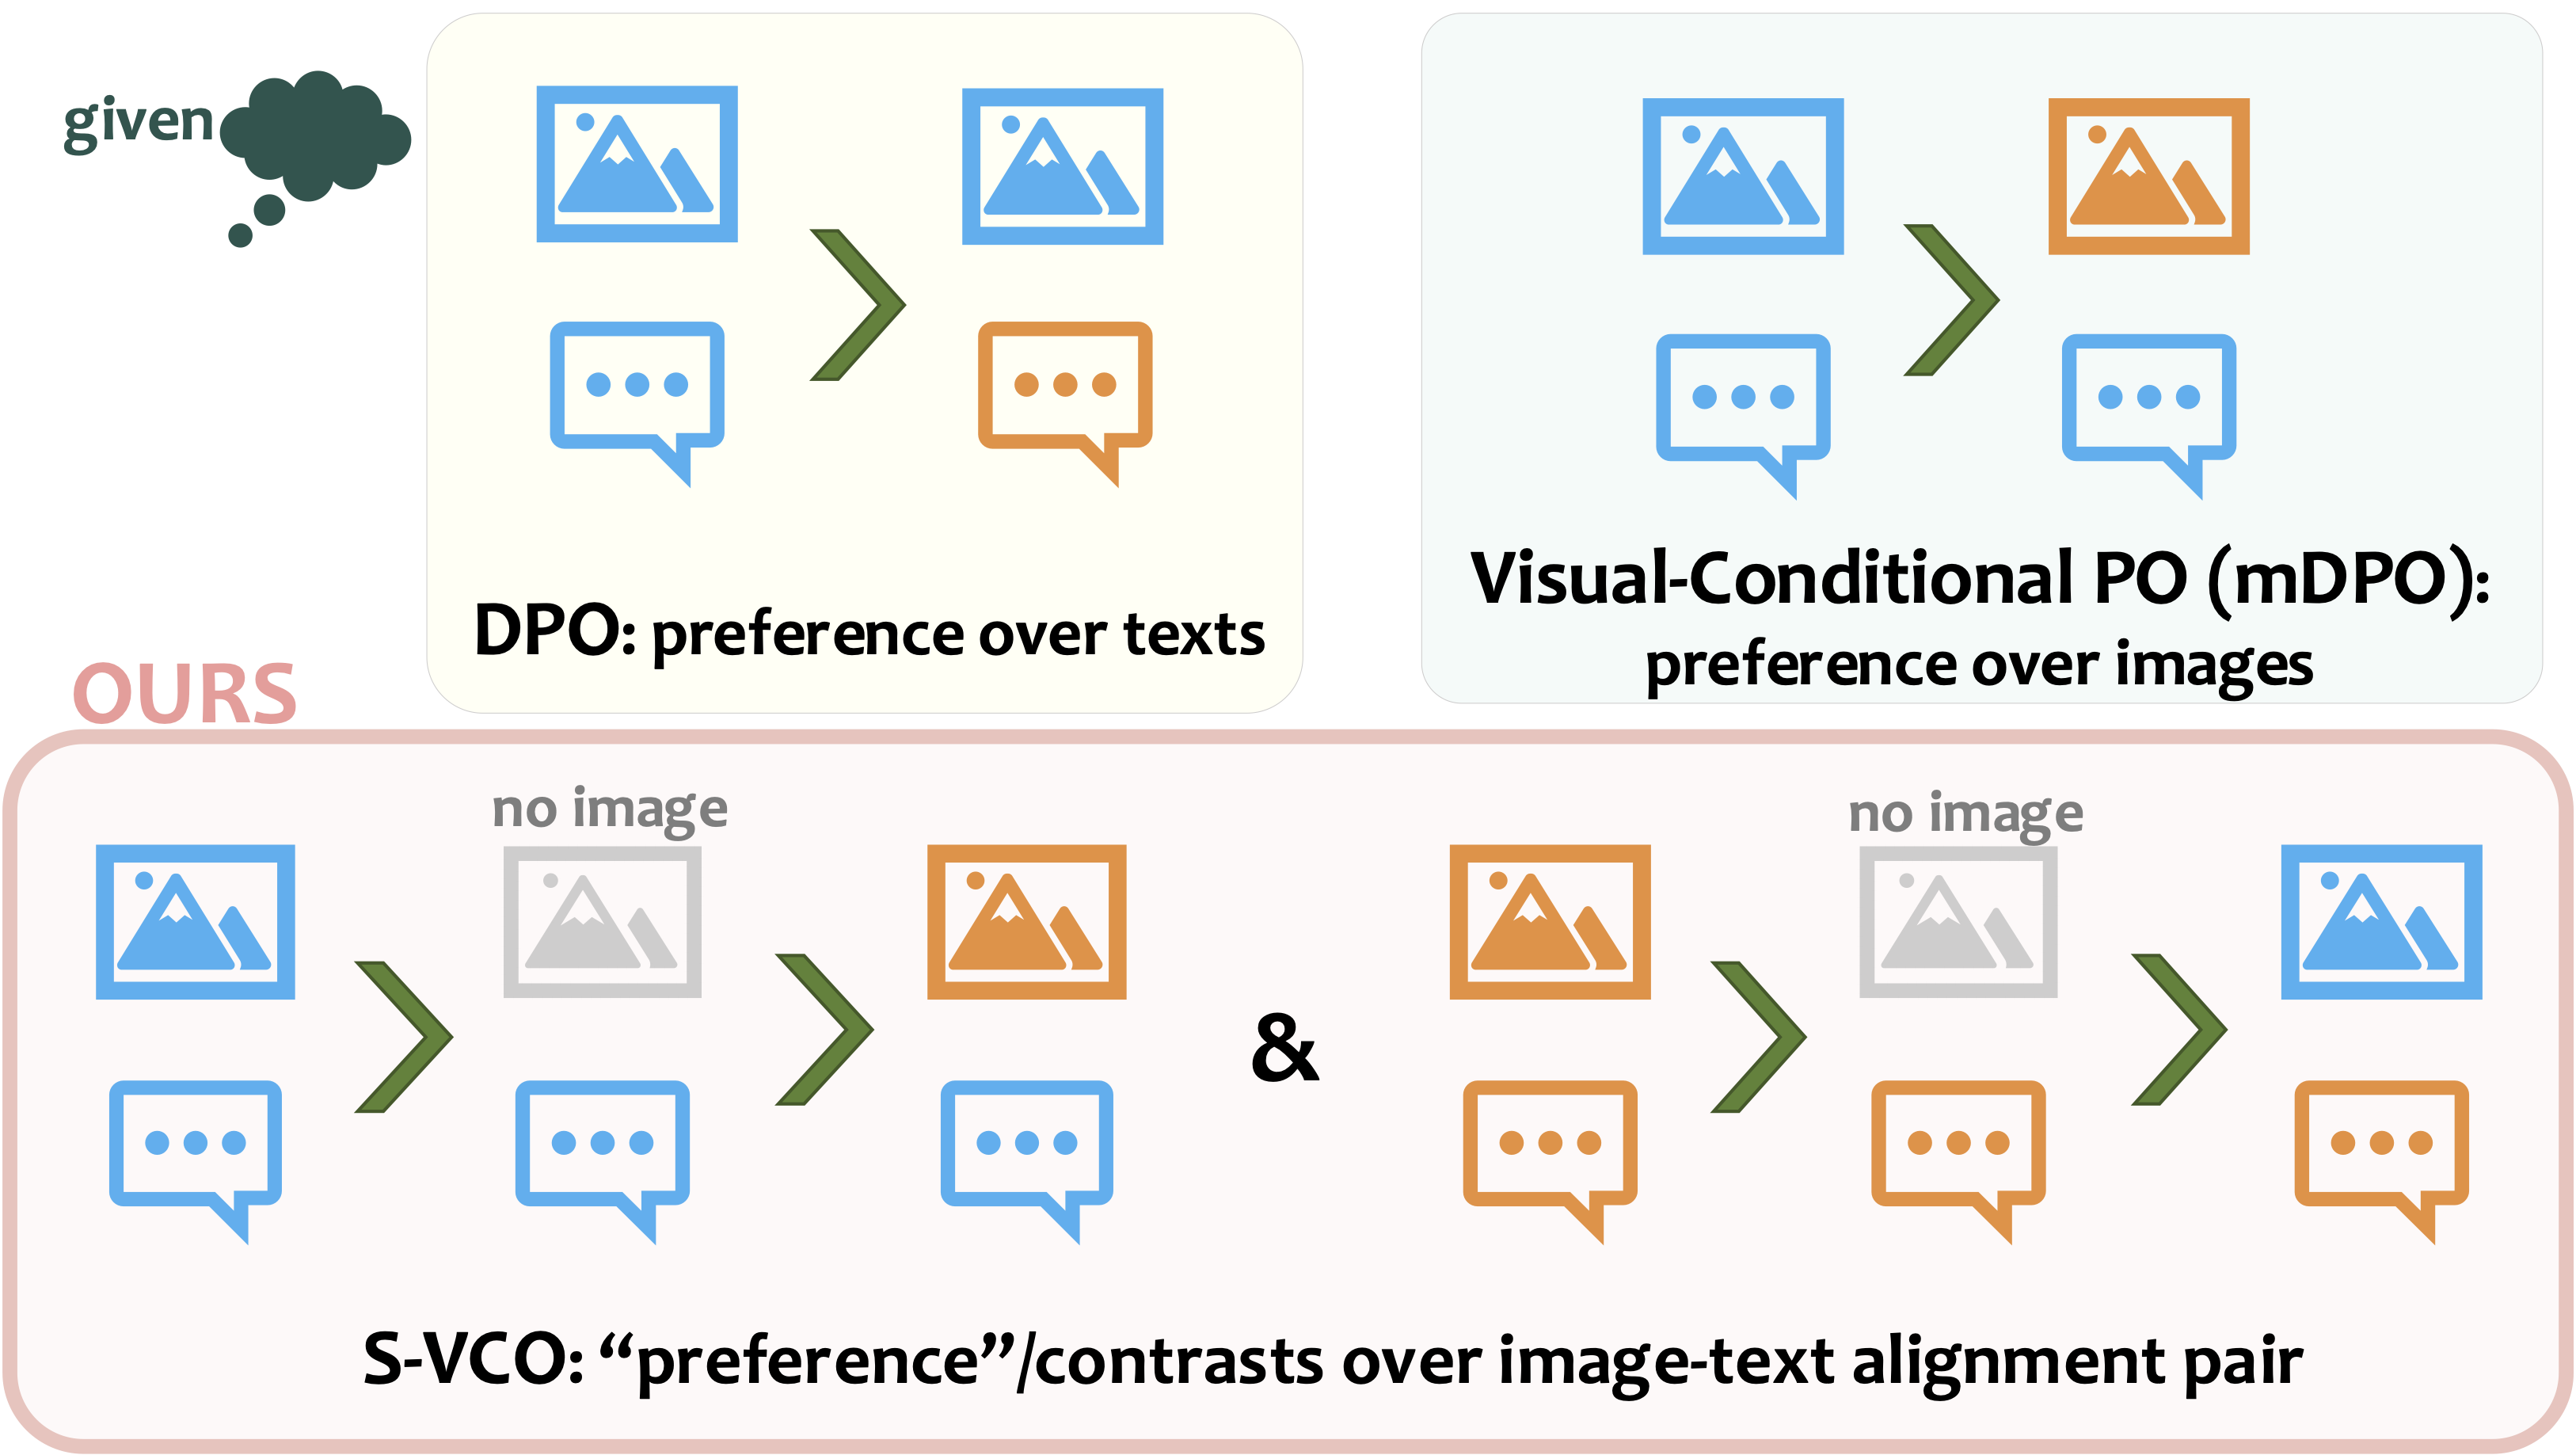
TL;DR: S-VCO is a novel finetuning method that enhances visual-centric capabilties of VLMs while preserving general performance. Key design is a symmetrical visual contrastive objective that optimizes over visual details while avoiding one-sided "preference" formulation. Across various VLM benchmark domains, S-VCO demonstrates most significant and consistent improvements, with especially strong gains on visually demanding tasks.
|
|
Shengguang Wu, Keming Lu, Benfeng Xu, Junyang Lin, Qi Su, Chang Zhou
ArXiv, 2023
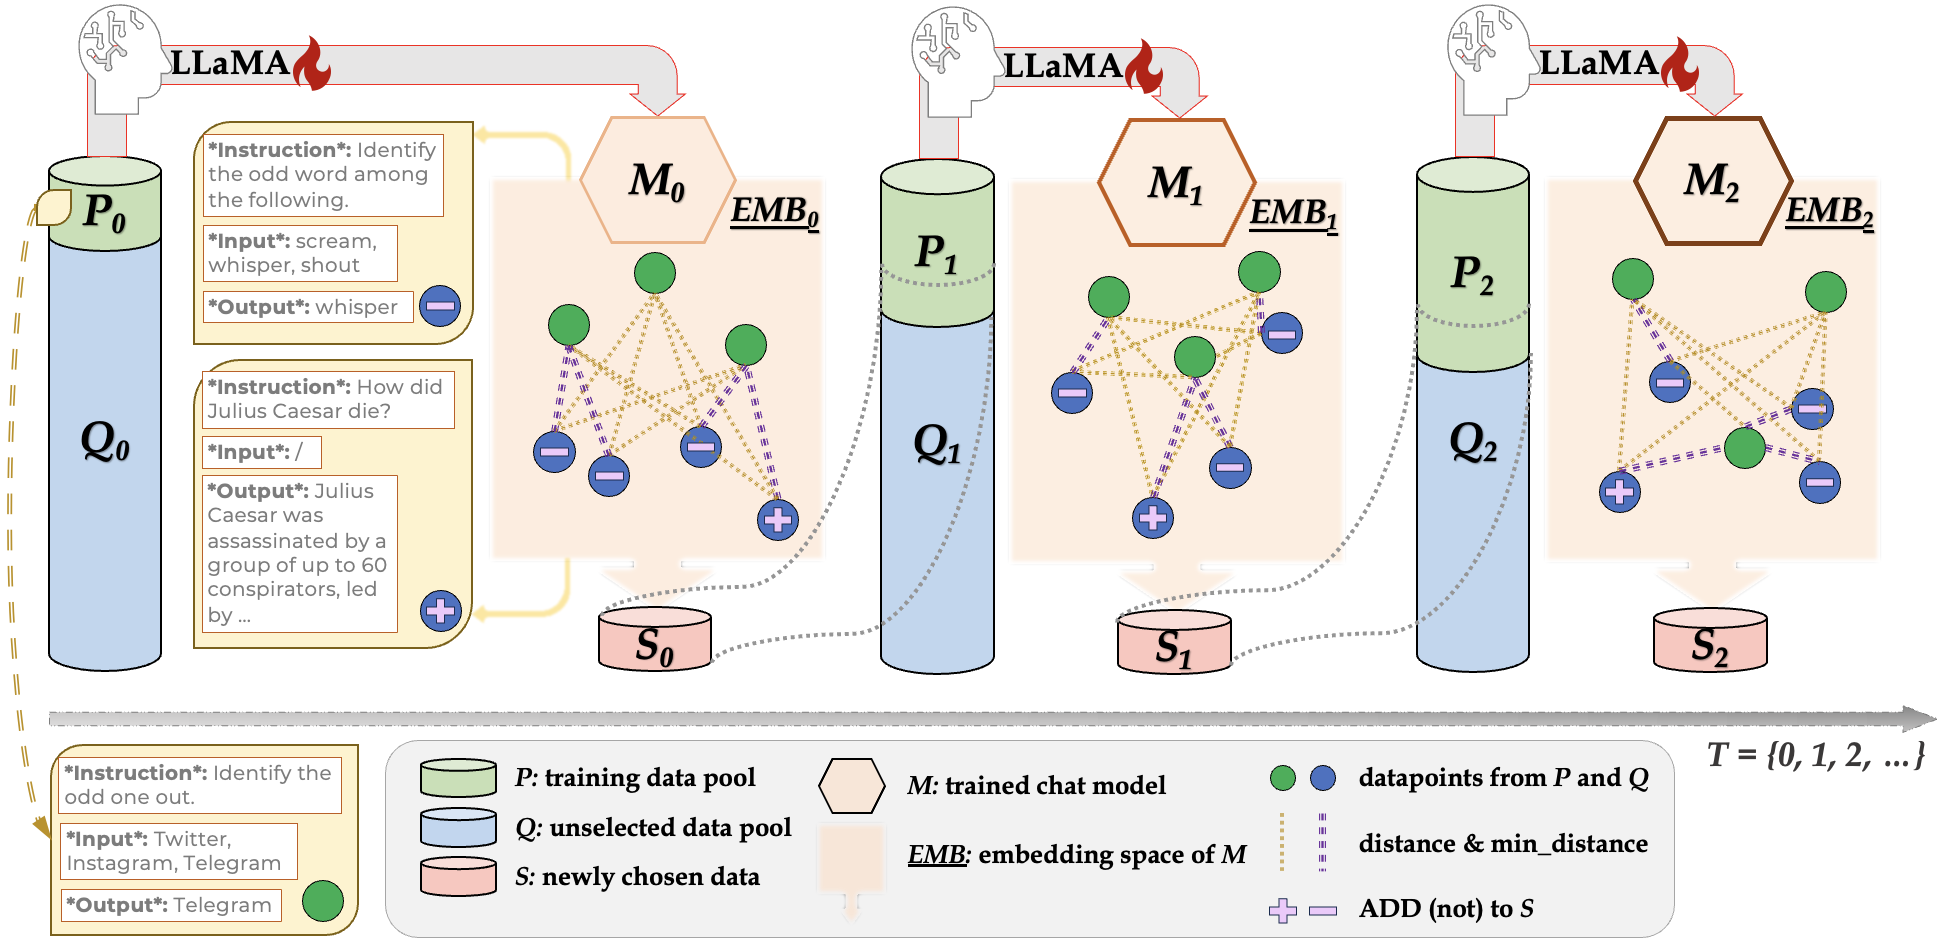
TL;DR: DiverseEvol is an efficient instruction-tuning method that allows the model itself to iteratively sample training subsets to improve its own performance, with a key selection principle of maintaining high diversity in the chosen subsets. Across three datasets and benchmarks, our models, trained on less than 4% of the original dataset, match or improve performance compared with finetuning on full data.
|
|
Qwen Team
ArXiv, 2023
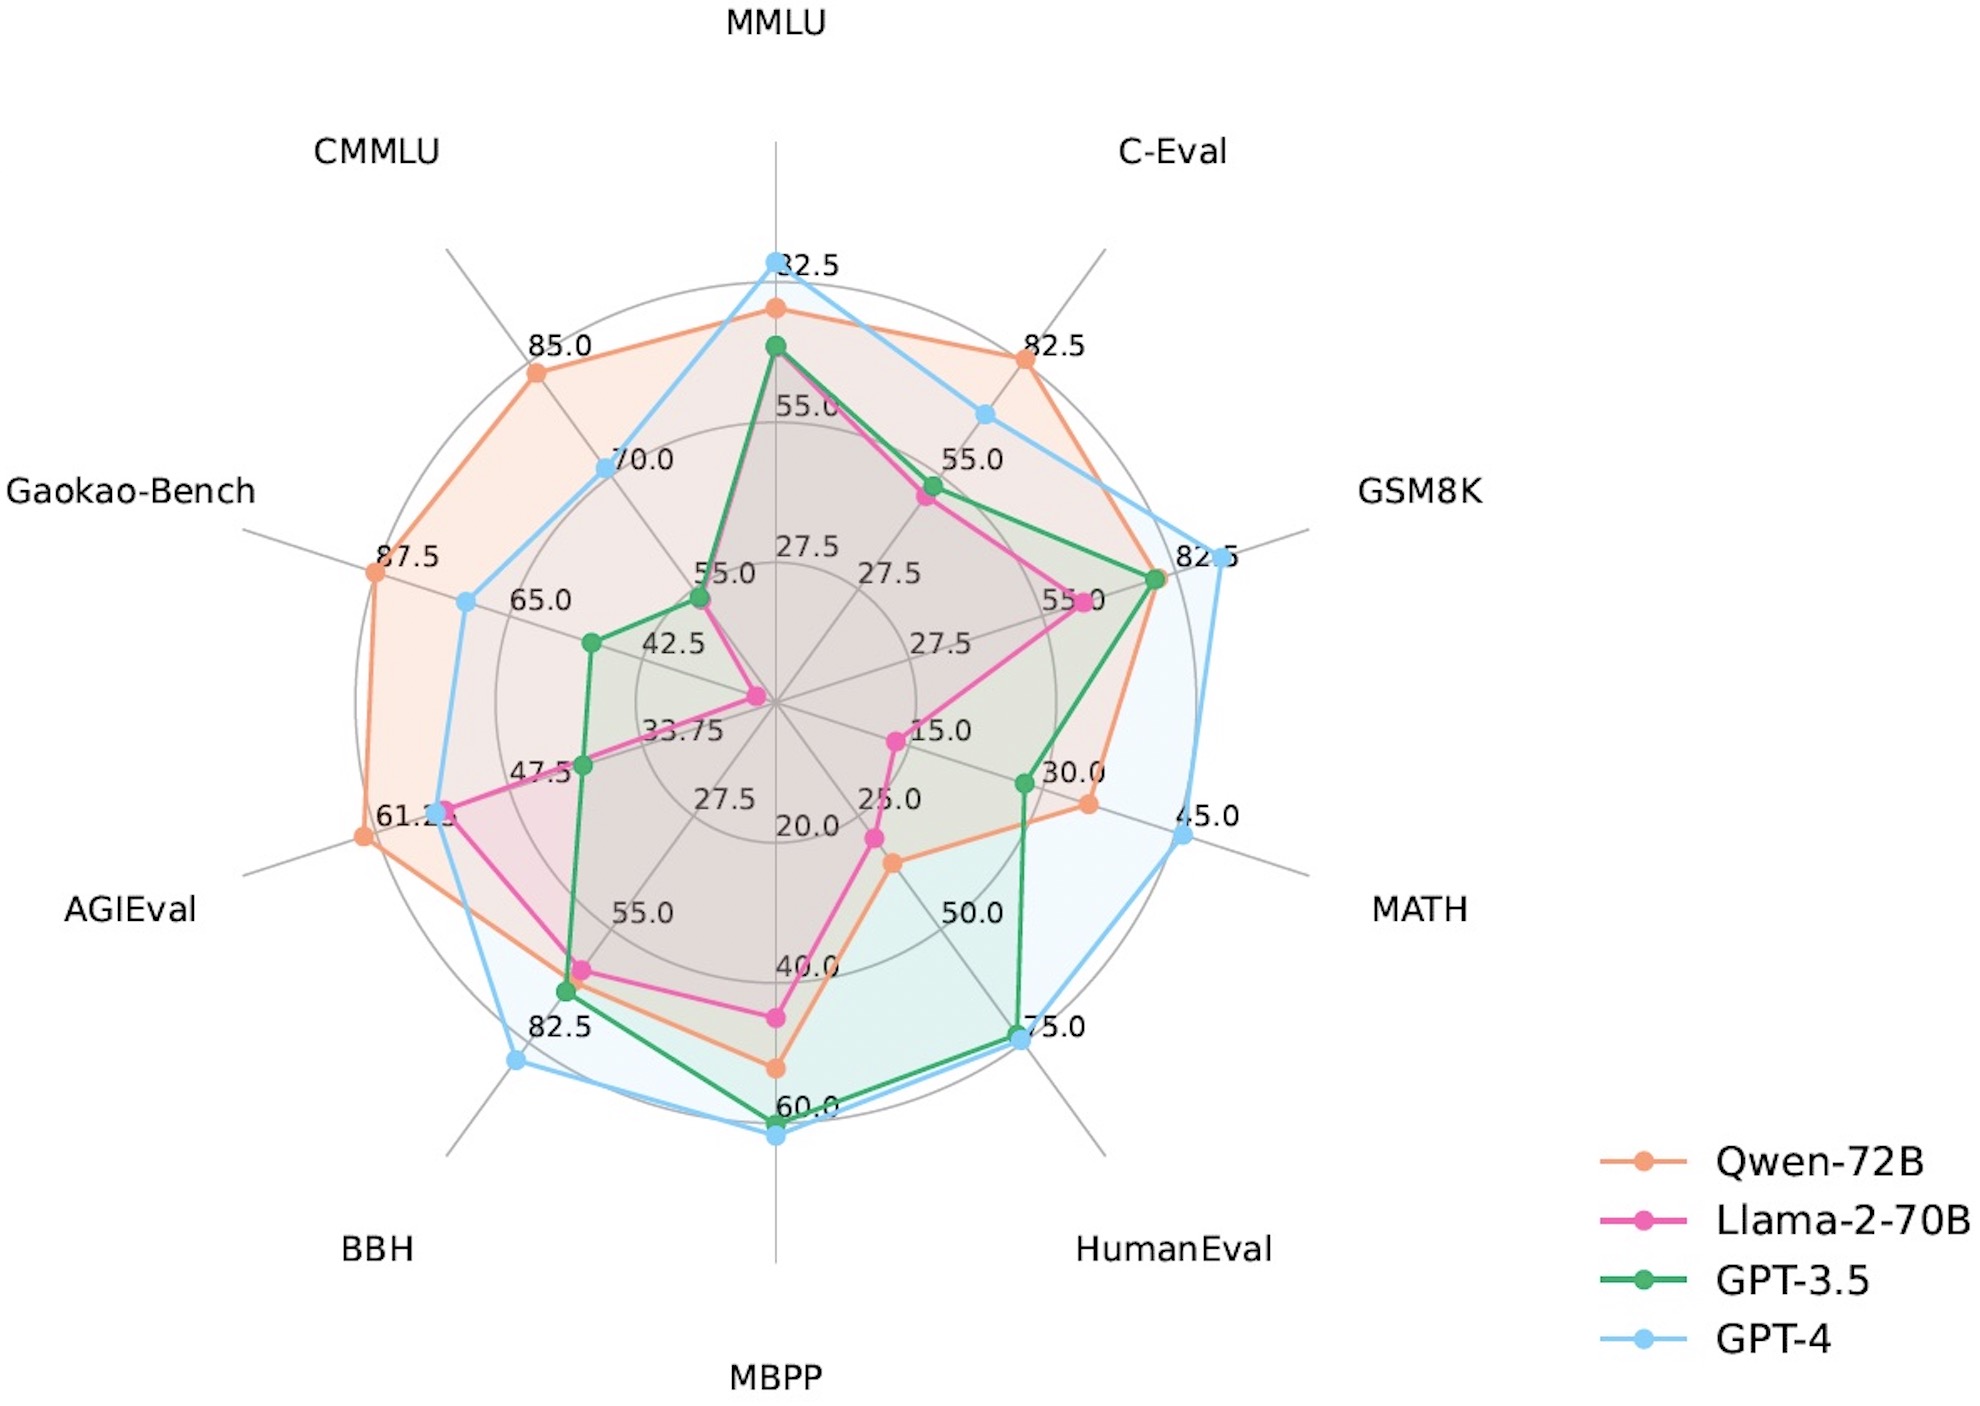
TL;DR: We release Qwen, a family of highly-capabale foundation LLMs and Chat-Models. QwenLMs achieve superior performance than baselines (e.g., LLaMA2) of similar sizes on a wide range of benchmarks that measure natural language understanding, reasoning, problem solving, etc. Qwen-72B also outperforms GPT-3.5 on 70% of all tasks.
|
|
|