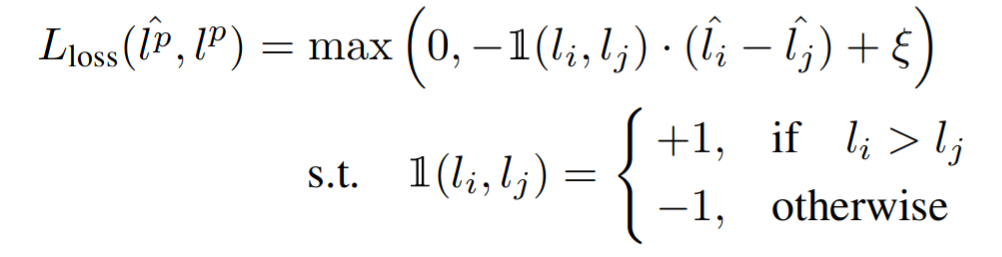GeezerVisonThe World Wide Web, restored to 800 pixels of glory. |
| Home|About|Gaming cabinet|Archives|How it works|Starter sites |
GeezerVison is showing jacobgil.github.io — Overview of Active Learning for Deep Learning Table Of Contents
IntroductionTo train supervised machine learning algorithms, we need:
Most of the focus of the machine learning community is about (2), creating better algorithms for learning from data. But getting useful annotated datasets is difficult. Really difficult. It can be expensive, time consuming, and you still end up with problems like annotations missing from some categories. I think that being able to build practical machine learning systems is a lot about tools to annotate data, and that a lot of the future innovation in building systems that solve real problems will be about being able to annotate high quality datasets quickly. Active Learning is a great building block for this, and is under utilized in my opinion. In this post I will give a short introduction to Classical Active Learning, and then go over several papers that focus on Active Learning for Deep Learning. MotivationIn many scenarios we will actually have access to a lot of data, but it will be infeasible to annotate everything. Just a few examples:
There are two closely related fields that help us deal with these scenarios:
Active Learning: Higher accuracy with less data annotation
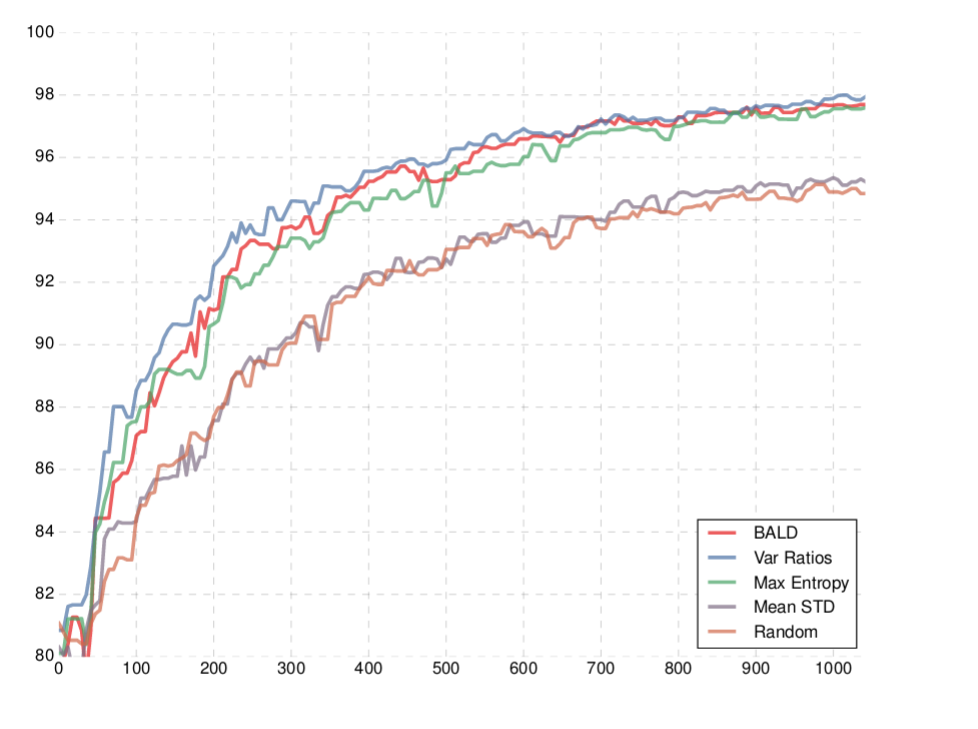
Image from https://arxiv.org/abs/1703.02910 The image above is a typical image in a paper about active learning. The x axis is the size of the dataset. The y axis is accuracy on the test set. A good active learning algorithm is able to cleverly select that data we are going to annotate, so that when we train on it, our model will be better than if we trained on other data. So if for example we have the constraint of being able to annotate only 400 images, the goal of active learning will be to select the best 400 images to annotate. The unlabeled pool scenarioThe most common scenario considered in active learning literature, which is also most similar to what happens in real life problems, is the unlabeled pool scenario. This is a good place to say that I’m going to interchange the words label and annotation, and I’m going to assume we’re using images, because the principles will be the same for everything else. The unlabeled pool scenario:
How should we rank the images for annotation ?At this point I want to write something obvious, that’s probably worth mentioning anyway. A really good strategy would be to select the images the model is just wrong about. But we can’t do that since we don’t know the real labels. There are two main approaches that most of the active learning works follow. Sometimes they are a combination of the two.
A function that gets an image and returns a ranking score, is often called an “acquisition function” in the literature. Let’s look a few examples. Acquisition functions for uncertainty sampling - examplesLets look at a few classic uncertainty acquisition functions. We will cover some more when we get to the deep learning methods.
Query by committee QBCAnother concept from classical active learning papers, is QBC. The idea here is that instead of measuring the uncertainty of a single model, we can train an ensemble of many different models (maybe with different seeds, or hyper-parameters, or structures). Then for a given image, we can check if the output changes a lot between models. If it does, it means the models aren’t very consistent about this image, and some of them aren’t doing a good job on this image. In the typical QBC implementation, every model decides the output category and votes for it, and a vector with the vote count is created.
Active Learning for Deep LearningCombining Active Learning and deep learning is hard.
Now lets cover a few papers about Active Learning for Deep Learning. Deep Bayesian Active Learning with Image DataThe paper: https://arxiv.org/abs/1703.02910 In my opinion this is the currently the most important paper about active learning for deep learning, so we are going to cover this in detail. The idea is that Bayesian neural networks give better uncertainty measures. In a Bayesian neural network, every parameter in the model is sampled from a distribution. Then, when doing inference, we need to integrate over all the possible parameters. So we’re using an ensemble of infinite different networks to compute the output. An uncertainty measure from a single network might be flawed (maybe it’s over confident in the output), but the idea is that going over many networks is going to improve that. Intuitively, if most models agree about one of the categories, the ensembled network will have high confidence for that category. If they disagree, we will get large outputs for several of the categories. It’s intractable to integrate over all possible parameter values in the distribution, so instead Monte Carlo integration can be used. Monte Carlo dropoutWith Monte Carlo dropout, the idea is that we will simulate a case where every neuron output has a Bernoulli prior, multiplied by some value M (the actual value of that neuron output). So a parameter \(i\) is going to be 0 with some probability p, and \(M_i\) otherwise. Now we can sample from the neuron priors by running the network and applying dropout at test time. If we apply dropout many times and sum the results, we’re doing Monte Carlo integration. Lets break this into steps:
We have a Bayesian neural network and an input image x. To get the output for the category c, we’re going over all the possible weight configurations, weighting every configuration by its probability.
This gives us a simple recipe: to approximate the output probability for every category, run the model many times with dropout and taking the average of all the runs. Plugging MC Dropout into the Entropy acquisition functionAn example of Uncertainty Sampling
We need to run the network multiple time with dropout, average the outputs, and take the entropy. Lets see how this measure behaves in two important cases that achieve a high H:
This leads us to a modification that handles the second case: Bayesian Active Learning by Disagreement BALDAn example of Uncertainty Sampling In Uncertainty sampling, the ultimate goal would be to find images the model is wrong about. We can’t do that since we don’t know the labels. So the idea in BALD is to instead find examples for which many of the different sampled networks are wrong about. If we sample many networks using MC Dropout, and they disagree about the output, this means that some of them are wrong. Lets get to the math. The objective is to find the image that maximizes the mutual information between the model output, and the model parameters. \[I(y; \omega | x, D_{train}) = H(y | x, D_{train}) - E_{p(\omega|D_{train})} [H(y|x, \omega, D_{train})]\]
If we plug in the Monte Carlo approximation again, we get: \[I(y; \omega | x, D_{train}) \approx-\sum_c(\frac{1}{T}\sum_tp_c^t)Log(\frac{1}{T}\sum_tp_c^t) + \frac 1 T \sum_{t, c} p_c^t Log p_c^t\]To get the first term, we make many runs, average the output, and measure the entropy. To get the second term, we make many runs, measure the entropy of every run, and take the average. Learning Loss for Active LearningAn example of Uncertainty Sampling The paper: https://arxiv.org/abs/1905.03677 The main idea here is to try to predict what would be the loss of the learning algorithm for a given input. A higher loss means its a more difficult image and should be annotated.
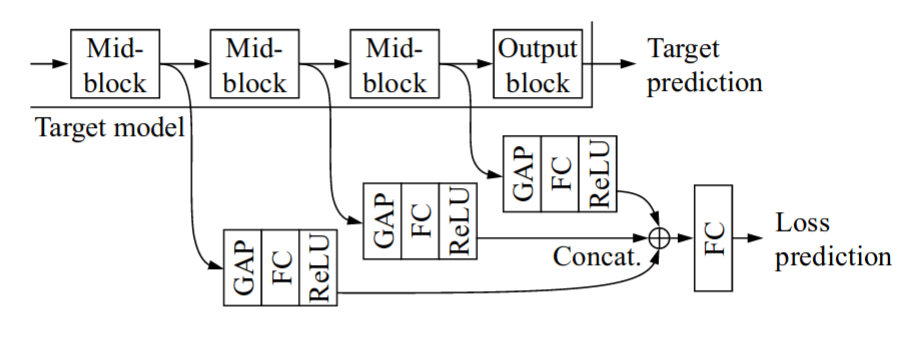
They extract features from intermediate layers and combine them to predict the network loss. To learn the loss, you could just add an additional term to the loss: MSE(Real loss, predicted loss). But during training, the scale of the loss is changing all the time (since the loss is usually going down), and its difficult to learn. Instead, in this paper they suggest comparing the predicted losses between images.
Then during the active learning rounds, you select the images with the highest loss. Mode collapse in active learning
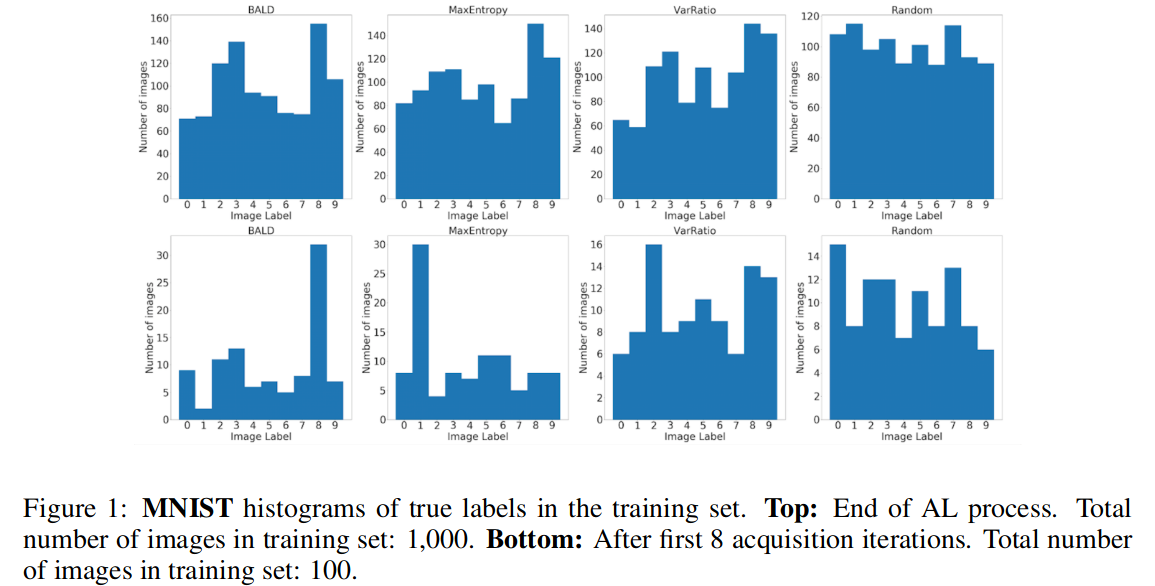
Image from https://arxiv.org/abs/1811.03897 A possible problem with all these methods, is that during training your dataset won’t necessarily be balanced. The acquisition strategy might favor bringing more images from some of the categories. https://arxiv.org/abs/1811.03897 showed this happens for common uncertainty based acquisition functions: random acquisition ends up bringing a much more balanced dataset than active learning. I think this is a really nice visualization that shows that scoring images by how difficult they are, won’t be good enough, and that we have to somehow also optimize for having diverse a diverse dataset. Of course it’s not enough to have enough images from all the categories. Ideally we would capture the sub-categories inside every category as well. This leads us to the next part about “Batch aware” methods, where we will see some works that try to combine Uncertainty sampling and Diversity sampling. Batch aware methodsMost of the active learning works selects a single image, at every active learning round. However for expensive/data hungry methods like Deep Learning we need to select a batch with many images at every round. After all, we’re going to train on the entire new dataset and not just only on the new images, so we can’t afford to train again every time a single new image is added to the dataset. Problem: Datasets can have many near duplicates. If we just select the top ranking images, we might select many near duplicate images that all rank high.
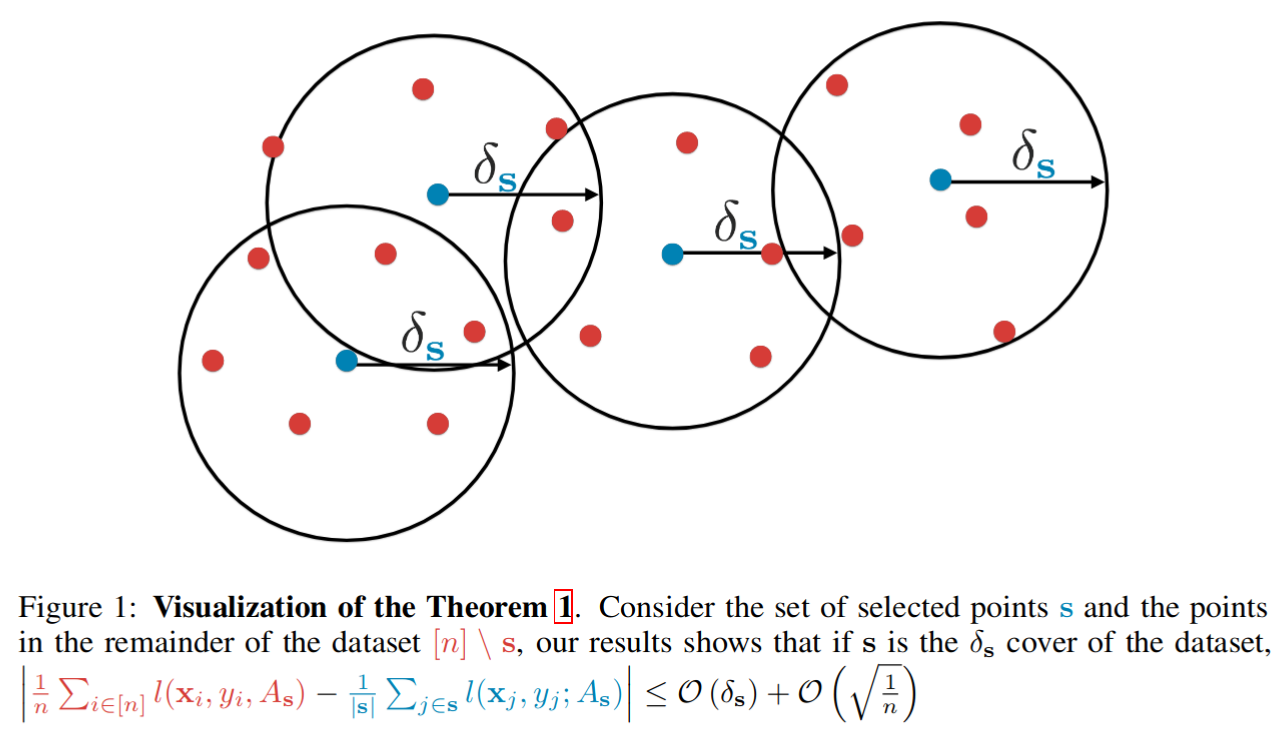
Image from https://arxiv.org/abs/1906.08158 Next we are going to go over a few “batch aware” methods, that try to select a good batch of images. Active Learning for Convolutional Neural Networks: A Core-Set ApproachAn example of Diversity sampling The paper: https://arxiv.org/abs/1708.00489
This paper is an example from the diversity sampling family of active learning algorithms, and is also a “batch aware” method, that tries to choose a batch of B images at once. The main idea here is that we want the training set to capture the diversity in the dataset. To find the data that isn’t represented well yet by the training set, we need to find the “Core Set” at every step. The core set: B images such that when added to the training set, the distance between an image in the unlabeled pool and it’s closest image in the training set, will be minimized. Finding the ideal B images is NP hard. Instead a simple greedy approximation is used:
How do we define distances between images? It’s an open question with place for creativity. For images they use the Euclidian distance between feature vectors extracted from the end of the network. BatchBALDAn example of combining Uncertainty and Diversity Sampling
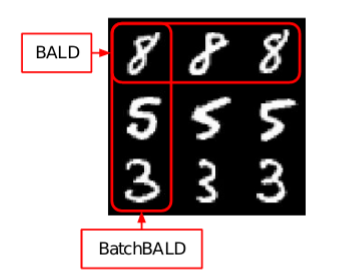
In BALD, the acquisition function for a single data point was the mutual information between the model parameters and the model output: \[I(y; \omega | x, D_{train}) = H(y | x, D_{train}) - E_{p(\omega|D_{train})} [H(y|x, \omega, D_{train})]\]In this work the goal is to select a batch of images at once, so they the change the acquisition function to: \[I(y_1,...,y_B; \omega | x_1,..,x_B, D_{train}) = H(y_1,...,y_B | x_1,...,x_B, D_{train}) - E_{p(\omega|D_{train})} [H(y_1,...,y_B|x_1,...,x_B, \omega, D_{train})]\]Lets say we have a batch size of 3, and have two images that have a high BALD acquisition score: a and b, and another image that is a duplicate of a: a’. If we select the batch images one by one, we will select a, a’ and b, since they all have high scores. a’ is redundant since it already exists in the batch. BatchBald won’t select a’, since it doesn’t contribute anything to the total mutual information: \[I(a,b,a') = I(a, b)\]This encourages adding informative images that are different from the rest of the images in the batch. Approximating \(H(y_1,...,y_B | x_1,...,x_B, D_{train})\) involves quite a bit of math and details, so refer to the paper for the details. Diverse mini-batch Active LearningAn example of combining Uncertainty and Diversity Sampling Paper: https://arxiv.org/abs/1901.05954 The idea here is to combine uncertainty sampling and diversity sampling. For diversity sampling, they cluster the data into K clusters using K-means (in the case of images, as features they use features extracted from intermediate layers from the neural network classifier). Then they select images that are closest to the centers of each of the clusters, to make sure the sampled images are diverse. To incorporate uncertainty sampling and select difficult images, they use weighted K-means, where every image is assigned a weight from an uncertainty acquisition function. Since K-means can be slow, they pre-filter the unlabeled images to keep the top \(\beta*K\) images with the highest uncertainty scores, and do the clustering only on them (\(\beta\) is typically 10). Deep Batch Active Learning by Diverse, Uncertain Gradient Lower BoundsAn example of combining Uncertainty and Diversity Sampling This is really similar in nature to the previous paper, and in my opinion also to Core Sets, but has a unique twist.
What’s K-means++? From Wikipedia: If you recall the Core-Set work, it’s really similar to K-means++ ! In Core-Sets, the embeddings were features from one of the last layers. In this work it’s almost the same thing, but with gradient embeddings. SummaryThanks for reading. We went over active learning methods for Deep Learning. These methods are really creative, and it was a joy to write. We were focusing on images, but these methods can be used for other domains like text. I hope this will do some help to demystify active learning for Deep Learning. |
| You are visitor 01402503 — GeezerVison does not store the pages you look up. Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required. |