GeezerVison is showing orlitany.github.io — Or Litany - 3D Computer Vision & Generative AI Researcher News- [Sep 25, 2026] Two papers accepted to NeurIPS 2026!
- [Aug 17, 2026] Retrieval-Augmented Gaussian Avatars accepted to the Interactive Social Avatars (ISA) workshop at ECCV 2026!
- [Nov, 2025] "Appreciate the View" is accepted at 3DV 2026.
- [August, 2025] "Gaussian See, Gaussian Do" accepted at SIGGRAPH-ASIA 2025.
- [June, 2025] Two papers accepted at ICCV 2025.
- [May, 2025] "FRIDU" is accepted at SGP 2025.
- [March, 2025] Honored to chair the Research Interaction sessions at the upcoming 3DV 2026.
- [Feb 12, 2025] OmniRe got a spotlight at ICLR 2025.
- [Feb 2, 2025] I will serve as an Area Chair for the upcoming ICCV 2025.
- [Jan 5, 2025] Epi-NAF is accepted at ISBI 2025 as an Oral.
- [Dec 21, 2024] Two workshops accepted at CVPR 2025.
- [June 18, 2026] Two papers accepted to ECCV 2026!
- [May 19, 2026] Honored to receive the Outstanding Area Chair award at CVPR 2026.
- [May 1, 2026] Test-Time Training with KV Binding accepted to ICML 2026!
- [Mar 28, 2026] Prox-E accepted to SIGGRAPH 2026!
- [Feb 21, 2026] Three papers accepted to CVPR 2026!
- [Jan 26, 2026] Two papers accepted to ICLR 2026!
- [Dec 22, 2025] Our workshop "OpenSUN3D: Open-World 3D Scene Understanding with Foundation Models", has been accepted as a Half-Day workshop at CVPR 2026!
- [Dec, 2025] Grateful to Meta for awarding an Academic Gift to support our lab's research.
StudentsI am actively seeking talented and motivated Postdoctoral and PhD candidates to join my new lab at the Technion. To get a sense of the research areas I am most passionate about, I encourage you to explore my recent publications and invited talks. As an ELLIS scholar, I also invite eligible candidates to consider applying through the ELLIS PhD and Postdoc Program. 13 current • 15 alumni • 5 PhD • 6 MSc • 1 Postdoc • 1 Intern▶ PhD (5)- Tomer Borreda (2026-present)
- Ido Sobol (2025-present)
- Daniel Gilo (2024-present)
- Gal Harari (2024-present)
- Assaf Singer (2024-present)
MSc (6)- Ido Raizman (2026-present)
- Maroun Khriesh (2026-present)
- Nitzan Leshem (2025-present)
- Merav Keidar (2025-present)
- Roi Teichman (2025-present) — Joint advising with Prof. Oren Salzman
- Amir Mann (2025-present)
Postdoc (1)- Matan Levy (2026-present) — Joint advising with Prof. Hadar Elor
Intern (1)- Noam Rotstein (2026-present)
MSc (4)- Tomer Borreda (2026)
- Yarin Bekor (2025)
- Saar Stern (2025)
- Guy Levavi (2024) — Joint advising with Prof. Assaf Marom
Intern (10)- Junchen Liu (2026)
- Chenfeng Xu (2023) — Assistant professor at UT Austin
- Davis Rempe (2023) — Research Scientist at Nvidia
- Shengyu Huang (2023) — Research Scientist at Nvidia
- Tzofi Klinghoffer (2023) — PhD at MIT Media Lab
- Zan Gojcic (2022) — Sr. Research Manager at Nvidia
- Francis Williams (2022) — Sr. Research Scientist at Nvidia
- Derek Liu (2022) — Sr. Research Scientist at Roblox and an Adjunct Professor at UBC
- Ge Zhang (2021) — Software Engineer at Righthand Robotics — Summer intern at Stanford University
- Cinjon Resnick (2021) — Research Scientist at Sesame
Teaching- Deep Learning (CS 02360781)
An introductory course covering the fundamentals of deep learning, neural networks, and their applications in computer vision and natural language processing. - Compter Vision (CS 02360873) - Course Page
Topics in computer vision including classic methods like hough voting and RANSAC, multiview stereo, and modren methods like vision transformers and generative modeling. - 3D Computer Vision Seminar (CS 02360007) - Course Page
Advanced topics in 3D computer vision including point cloud processing, neural rendering, and 3D scene understanding.
Invited talks- Seeing by Generating: NVS as a route to 3D understanding. Slides
- How to train and steer generative models in 3D, motion, 2D and video.
- VoteNet and ImVoteNet. Slides Video
- Geometric Deep Learning: Introduction. Slides Video
- Deep Learning for “Exotic” Data Like 3D Meshes and Point-Clouds. Slides Video
- Deep Hough Voting for 3D object detection in point clouds. Slides Video
- SOSELETO: A Unified Approach to Transfer Learning and Training with Noisy Labels. Slides Video
- Lights, Camera, Action! Revolutionizing Computer Vision with Video Generative AI. Video
- EmerNeRF: Emergent Spatial-Temporal Scene Decomposition via Self-Supervision. Video
- Data-driven simulation for AV. Slides Video
- Data-driven simulation for AV (short). Slides
- Manipulating neural fields. Slides Video
- 3D scene understanding from pointclouds. Video
- PointContrast. Slides
- Latent Canonicalizers. Slides Video
Workshops / Tutorials- Open-Vocabulary 3D Scene Understanding 6th workshop at CVPR, 2026.
- Open-Vocabulary 3D Scene Understanding 5th workshop at ICCV, 2025.
- 3DOVScene: Open-Vocabulary 3D Scene Understanding workshop at ICCV, 2023.
- Neural Fields in Computer Vision workshop at CVPR, 2022.
- Learning 3D Representations for Shape and Appearance workshop at ICCV, 2021.
- iGDL: Israeli Geometric Deep Learning workshop (First) workshop, 2020.
- iGDL: Israeli Geometric Deep Learning workshop (Second) workshop, 2021.
- Learning 3D Representations for Shape and Appearance workshop at ECCV, 2020.
- Deep Learning for Computer Graphics and Geometry Processing tutorial at Eurographics, 2019.
- Deep Learning meets Geometry tutorial at ECCV, 2018.
- Deep Learning and Geometry workshop at EUSIPCO, 2017.
- Open-Vocabulary 3D Scene Understanding 4th workshop at CVPR, 2025.
- Neural Fields Beyond Conventional Cameras 2nd workshop at CVPR, 2025.
- Neural Fields Beyond Conventional Cameras workshop at ECCV, 2024.
- Open-Vocabulary 3D Scene Understanding 3rd workshop at ECCV, 2024.
- Open-Vocabulary 3D Scene Understanding 2nd workshop at CVPR, 2024.
- Data-Driven Autonomous Driving Simulation workshop at CVPR, 2024.
- Neural Fields for Visual Computing workshop at CVPR, 2024.
- Neural Fields for Visual Computing Course at SIGGRAPH, 2023.
Publications2026ReLift: Dense 3D Tracking as Lifted Trajectory Repair Assaf Singer, Maroun Khriesh, Noam Rotstein, Yoni Kasten, Or Litany Preprint @misc{singer2026reliftdense3dtracking,
title = {ReLift: Dense 3D Tracking as Lifted Trajectory Repair},
author = {Assaf Singer and Maroun Khriesh and Noam Rotstein and Yoni Kasten and Or Litany},
year = {2026},
venue = {Preprint},
eprint = {2610.42136},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2610.42136},
image = {./OL_files/relift_teaser.mp4},
paper = {https://arxiv.org/abs/2610.42136},
code = {https://github.com/ReLift3D/ReLift},
page = {https://relift3d.github.io/},
tweet = {https://x.com/assaf_singer/status/2117141154026201529?a=e3G98sEAP-UfbJYPh2Y&s=20}
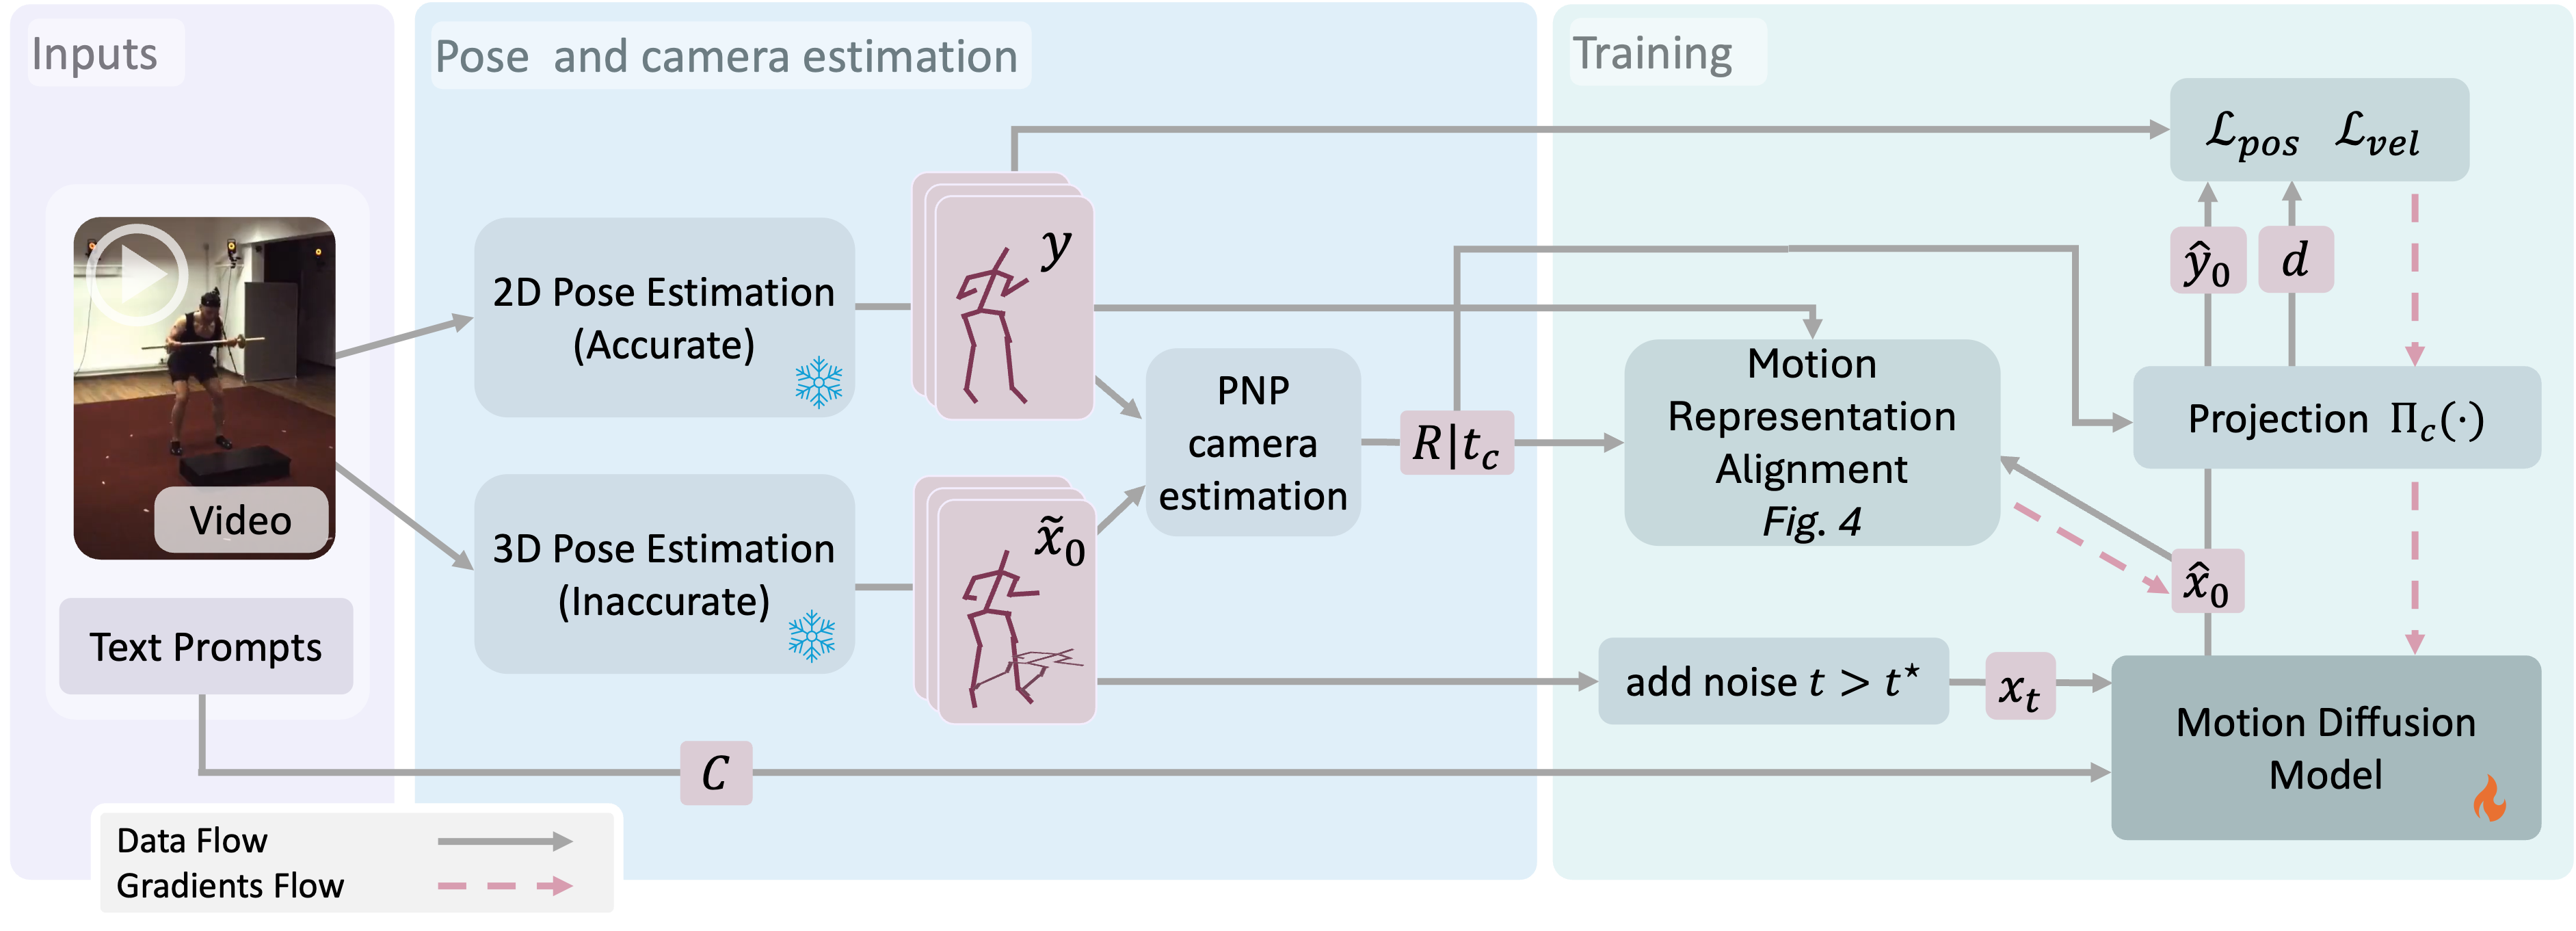
}VideoMDM: Towards 3D Human Motion Generation From 2D Supervision Amir Mann, Gal Michael Harari, Merav Keidar, Or Litany NeurIPS 2026 @misc{mann2026videomdm3dhumanmotion,
title = {VideoMDM: Towards 3D Human Motion Generation From 2D Supervision},
author = {Amir Mann and Gal Michael Harari and Merav Keidar and Or Litany},
year = {2026},
venue = {NeurIPS 2026},
eprint = {2606.13364},
archiveprefix = {arXiv},
primaryclass = {cs.LG},
url = {https://arxiv.org/abs/2606.13364},
image = {./OL_files/videomdm_method.png},
paper = {https://arxiv.org/abs/2606.13364},
page = {https://videomdm.github.io/},
tweet = {https://x.com/orlitany/status/2065344454798500325?s=20}
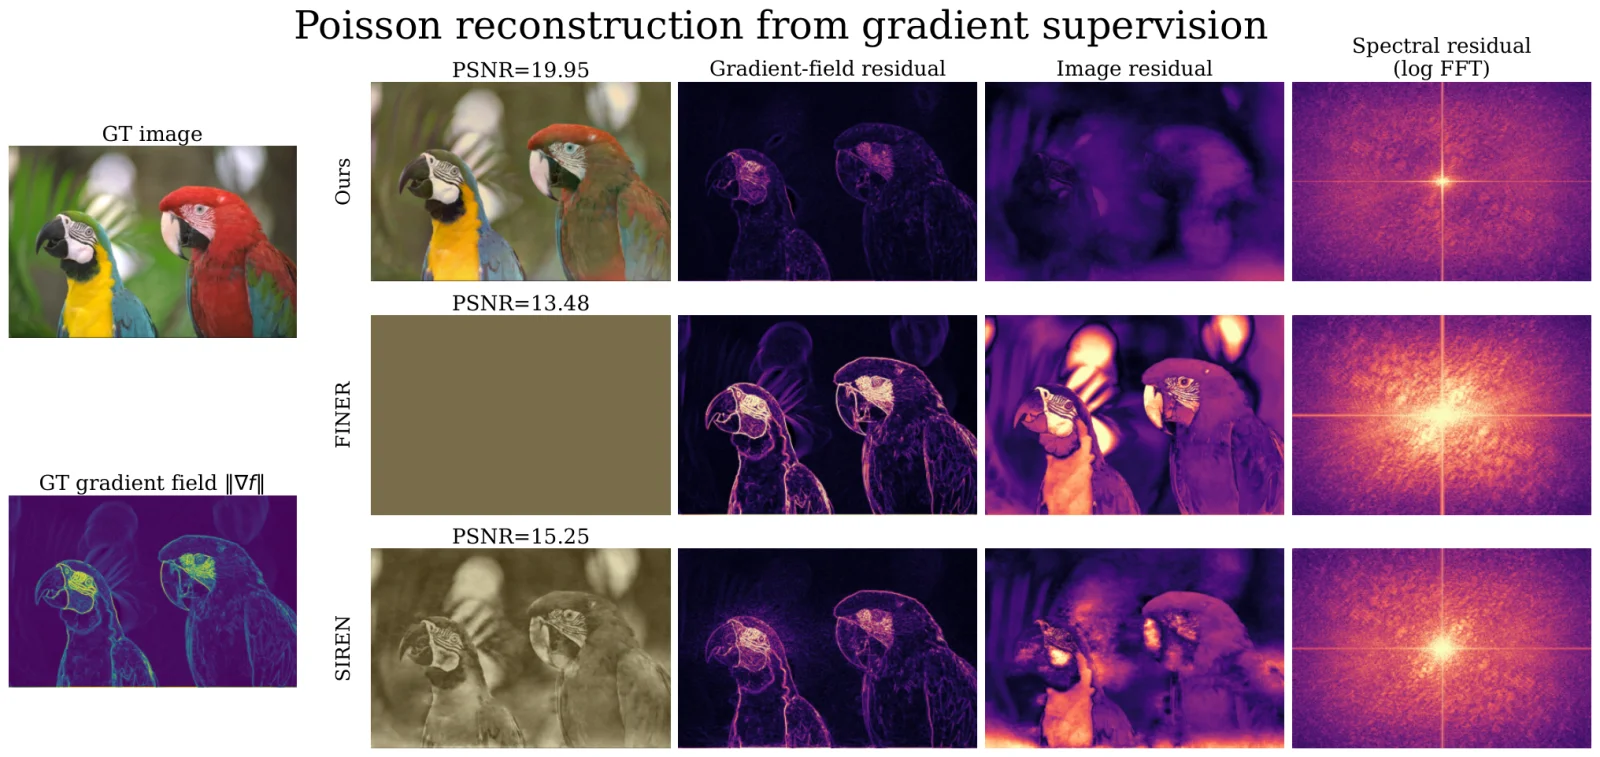
}Learnable Spectral Activations Tamir Shor, Or Litany, Alex Bronstein NeurIPS 2026 @misc{shor2026learnablespectralactivations,
title = {Learnable Spectral Activations},
author = {Tamir Shor and Or Litany and Alex Bronstein},
year = {2026},
venue = {NeurIPS 2026},
eprint = {2610.07419},
archiveprefix = {arXiv},
primaryclass = {cs.LG},
url = {https://arxiv.org/abs/2610.07419},
image = {./OL_files/lsa_teaser.webp},
paper = {https://arxiv.org/abs/2610.07419},
code = {https://github.com/tamirshor7/Learnable-Spectral-Activations},
tweet = {https://x.com/orlitany/status/2113334247343751647?s=20}
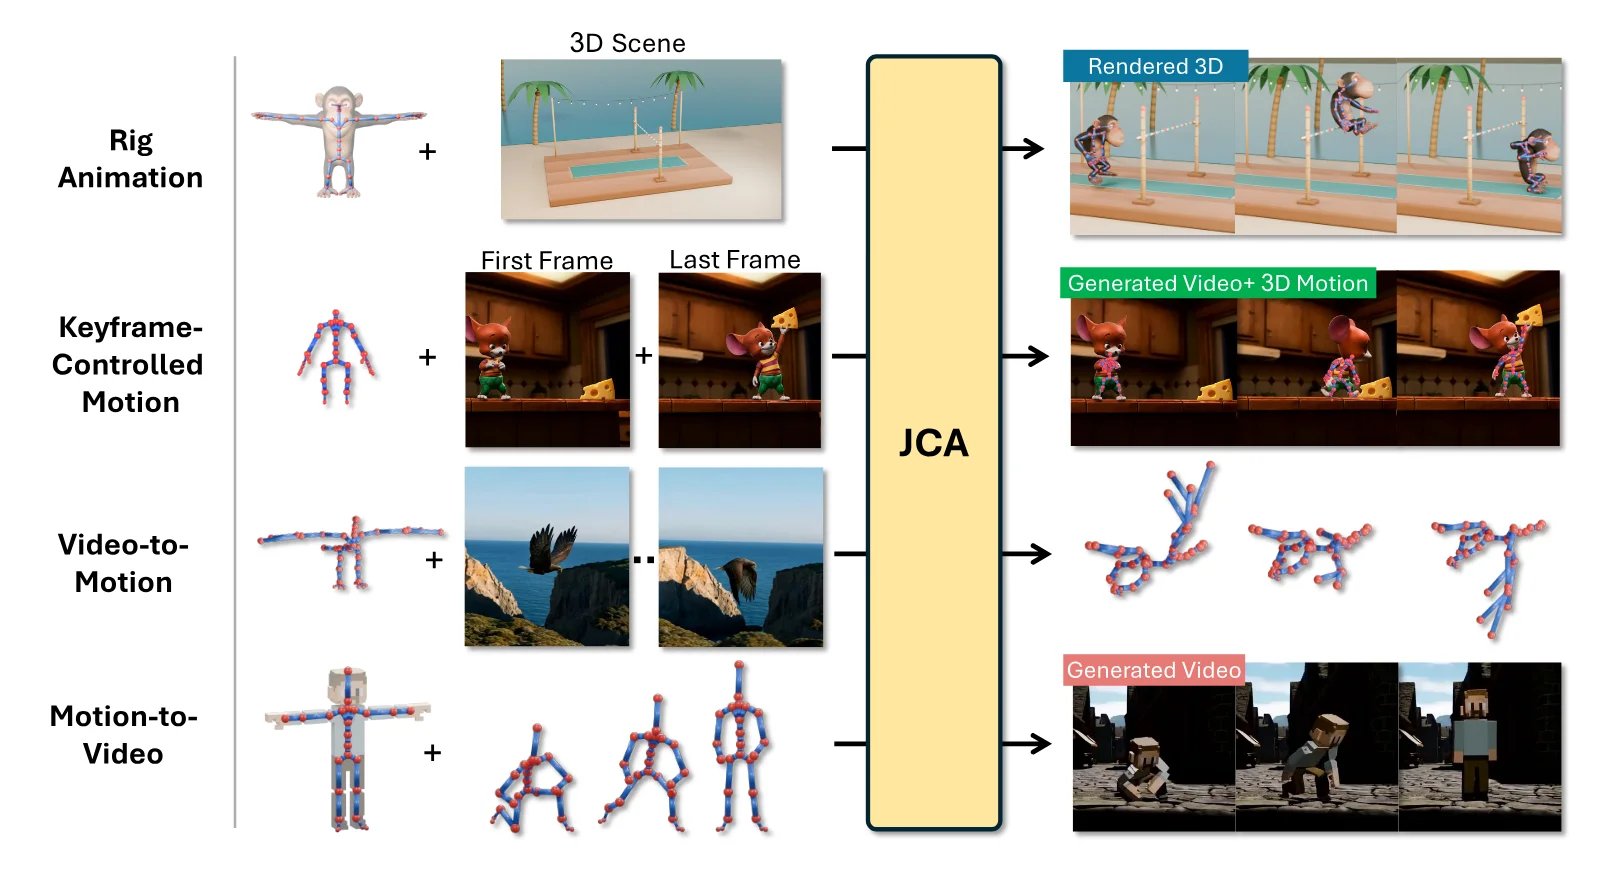
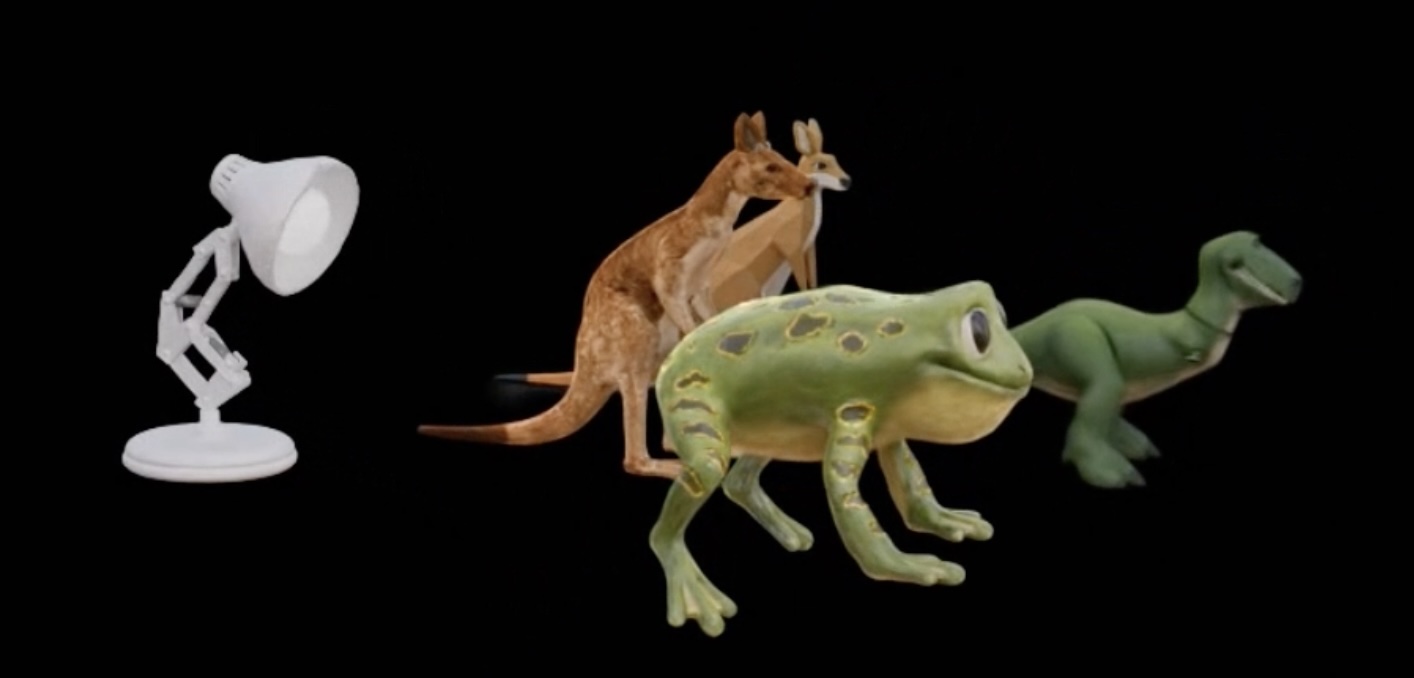
}Joints, Camera, Action! Co-Generating 3D Motion and Video for Arbitrary Rigs Noam Rotstein, Yoad Tewel, Chen Tessler, Haggai Maron, Gal Chechik, Or Litany, Yoni Kasten, Yuval Atzmon Preprint @misc{rotstein2026jointscameraactioncogenerating,
title = {Joints, Camera, Action! Co-Generating 3D Motion and Video for Arbitrary Rigs},
author = {Noam Rotstein and Yoad Tewel and Chen Tessler and Haggai Maron and Gal Chechik and Or Litany and Yoni Kasten and Yuval Atzmon},
year = {2026},
venue = {Preprint},
eprint = {2610.28632},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2610.28632},
image = {./OL_files/jca_teaser.webp},
paper = {https://arxiv.org/abs/2610.28632},
page = {https://research.nvidia.com/labs/par/projects/jca/},
tweet = {https://x.com/NoamRot/status/2112926067979702621?s=20}
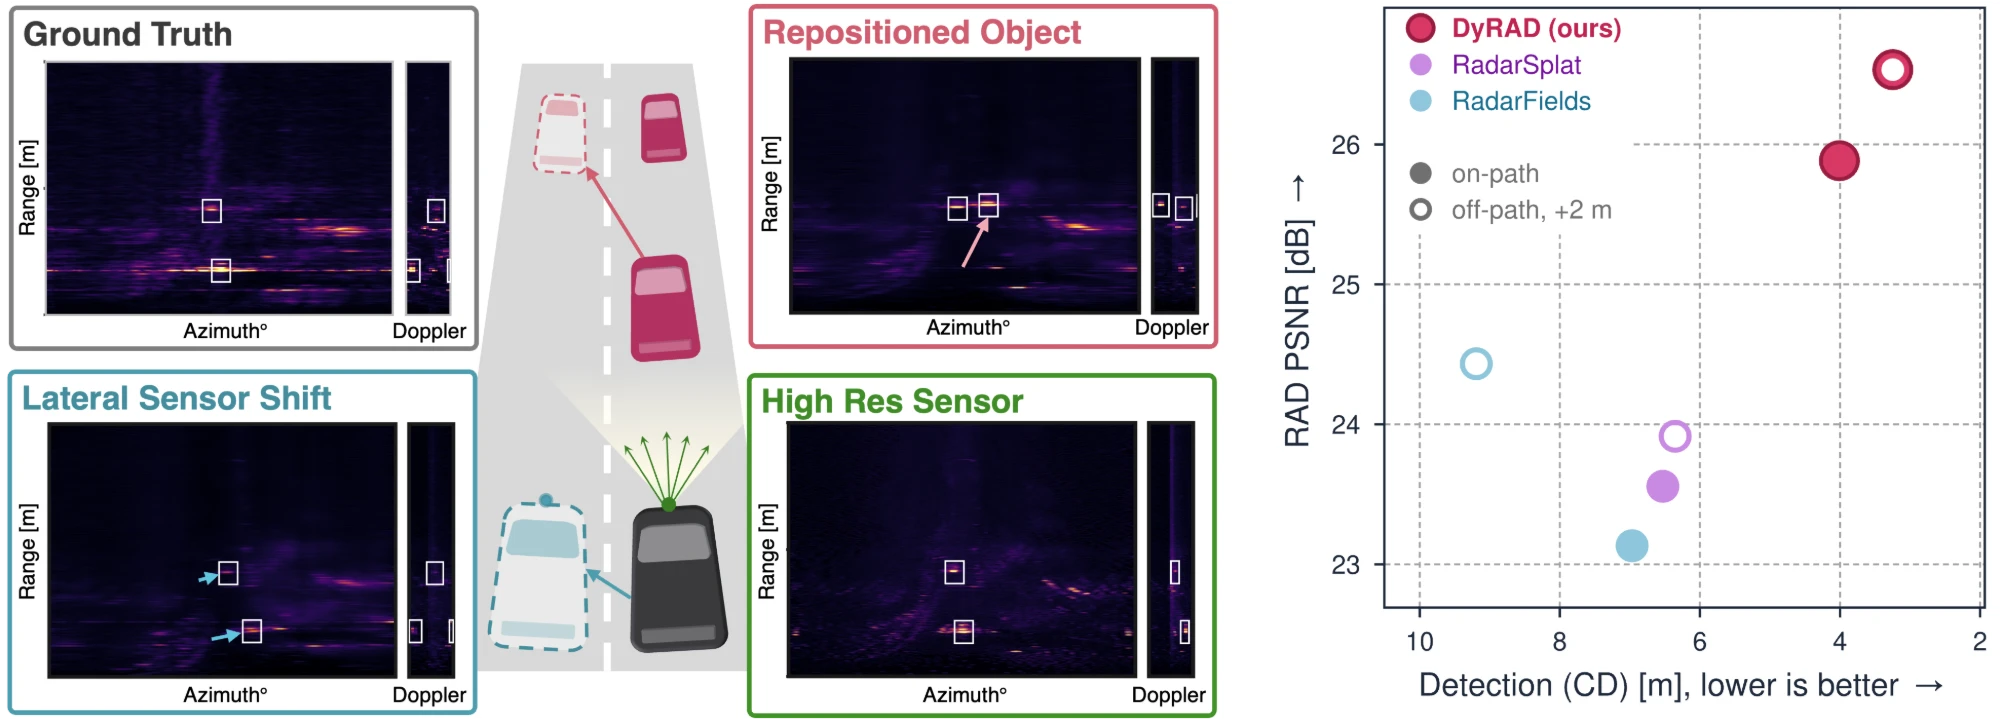
}DyRAD: Radar Novel View Synthesis for Dynamic Driving Scenes Merav Keidar, Tomer Borreda, Rajalakshmi Nandakumar, Or Litany Preprint @misc{keidar2026dyradradarnovelview,
title = {DyRAD: Radar Novel View Synthesis for Dynamic Driving Scenes},
author = {Merav Keidar and Tomer Borreda and Rajalakshmi Nandakumar and Or Litany},
year = {2026},
venue = {Preprint},
eprint = {2609.39841},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2609.39841},
image = {./OL_files/dyrad_teaser.webp},
paper = {https://arxiv.org/abs/2609.39841},
code = {https://github.com/Dyrad-NVS/DyRAD},
page = {https://dyrad-nvs.github.io/},
tweet = {https://x.com/orlitany/status/2106019515037610379?s=20}
}WarpHammer: Densifying Scene Warps with 3D Object Priors for Extreme View Synthesis Michael Green, Gavriel Habib, Dvir Samuel, Tal Berkovitz Shalev, Issar Tzachor, Rami Ben-Ari, Or Litany Preprint @misc{green2026warphammerdensifyingscenewarps,
title = {WarpHammer: Densifying Scene Warps with 3D Object Priors for Extreme View Synthesis},
author = {Michael Green and Gavriel Habib and Dvir Samuel and Tal {Berkovitz Shalev} and Issar Tzachor and Rami Ben-Ari and Or Litany},
year = {2026},
venue = {Preprint},
eprint = {2606.31258},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2606.31258},
image = {./OL_files/warphammer_teaser.mp4},
paper = {https://arxiv.org/abs/2606.31258},
page = {https://pihash2k.github.io/extreme_nvs/}
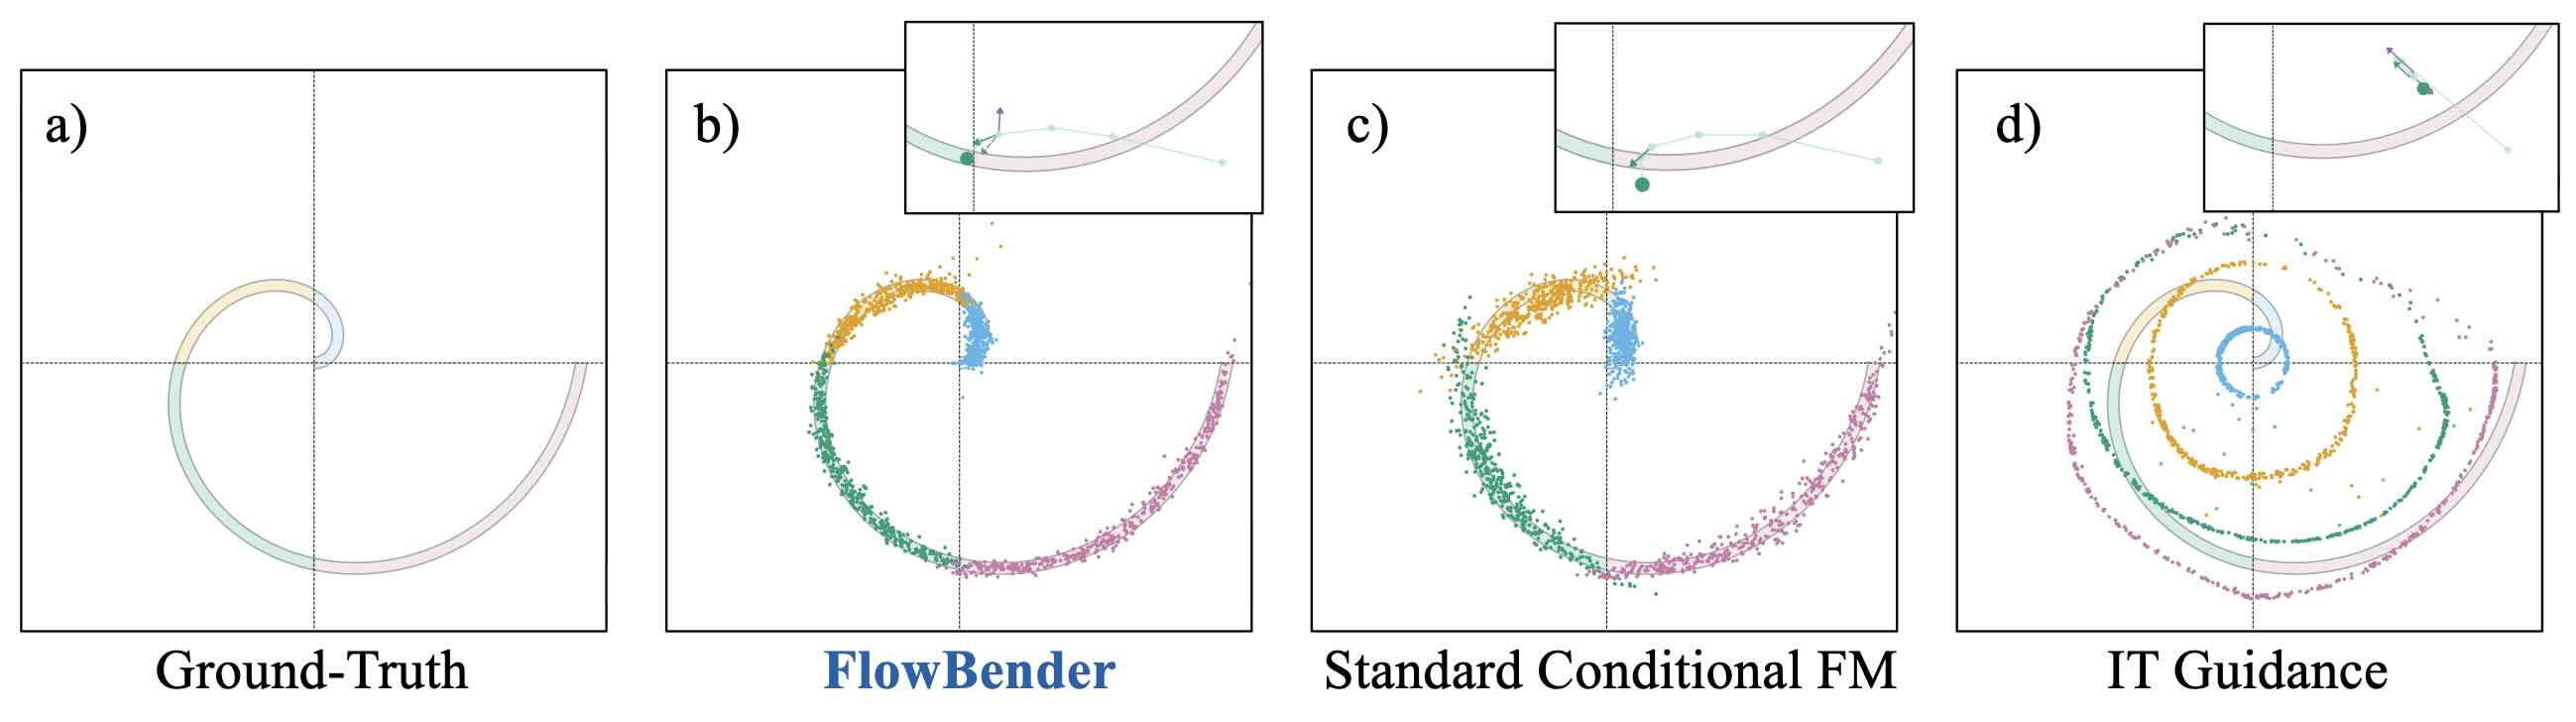
}FlowBender: Feedback-Aware Training for Self-Correcting Conditional Flows Daniel Gilo, Sven Elflein, Ido Sobol, Or Litany Preprint @misc{gilo2026flowbenderfeedbackawaretrainingselfcorrecting,
title = {FlowBender: Feedback-Aware Training for Self-Correcting Conditional Flows},
author = {Daniel Gilo and Sven Elflein and Ido Sobol and Or Litany},
year = {2026},
venue = {Preprint},
eprint = {2606.20404},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2606.20404},
image = {./OL_files/teaser_flowbender.jpg},
paper = {https://arxiv.org/abs/2606.20404},
page = {https://flow-bender.github.io/},
tweet = {https://x.com/danielgilo1/status/2067986128766951885?s=20}
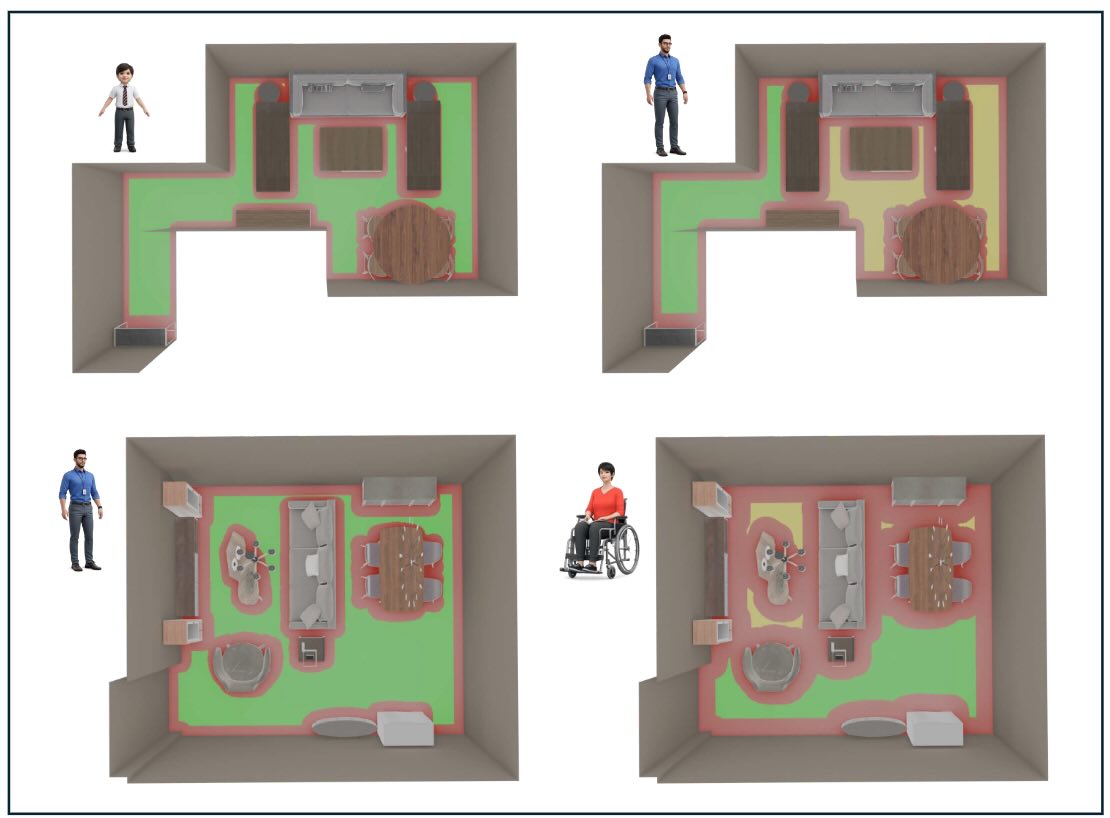
}SceneTeract: Agentic Functional Affordances and VLM Grounding in 3D Scenes Léopold Maillard, Francis Engelmann, Tom Durand, Boxiao Pan, Yang You, Or Litany, Leonidas Guibas, Maks Ovsjanikov Preprint @misc{maillard2026sceneteract,
title = {{SceneTeract: Agentic Functional Affordances and VLM Grounding in 3D Scenes}},
author = {Maillard, L{\'e}opold and Engelmann, Francis and Durand, Tom and Pan, Boxiao and You, Yang and Litany, Or and Guibas, Leonidas and Ovsjanikov, Maks},
year = {2026},
venue = {Preprint},
eprint = {2603.29798},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2603.29798},
image = {./OL_files/teaser_sceneteract.jpg},
paper = {https://arxiv.org/abs/2603.29798},
page = {https://sceneteract.github.io/}
}SpectralSplats: Robust Differentiable Tracking via Spectral Moment Supervision Avigail Cohen Rimon, Amir Mann, Mirela Ben-Chen, Or Litany ECCV 2026 @misc{rimon2026spectralsplatsrobustdifferentiabletracking,
title = {SpectralSplats: Robust Differentiable Tracking via Spectral Moment Supervision},
author = {Avigail {Cohen Rimon} and Amir Mann and Mirela Ben-Chen and Or Litany},
year = {2026},
venue = {ECCV 2026},
eprint = {2603.24036},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2603.24036},
image = {./OL_files/spectralsplats_teaser.mp4},
paper = {https://arxiv.org/abs/2603.24036},
page = {https://avigailco.github.io/SpectralSplats/},
tweet = {https://x.com/orlitany/status/2037133567910674747}
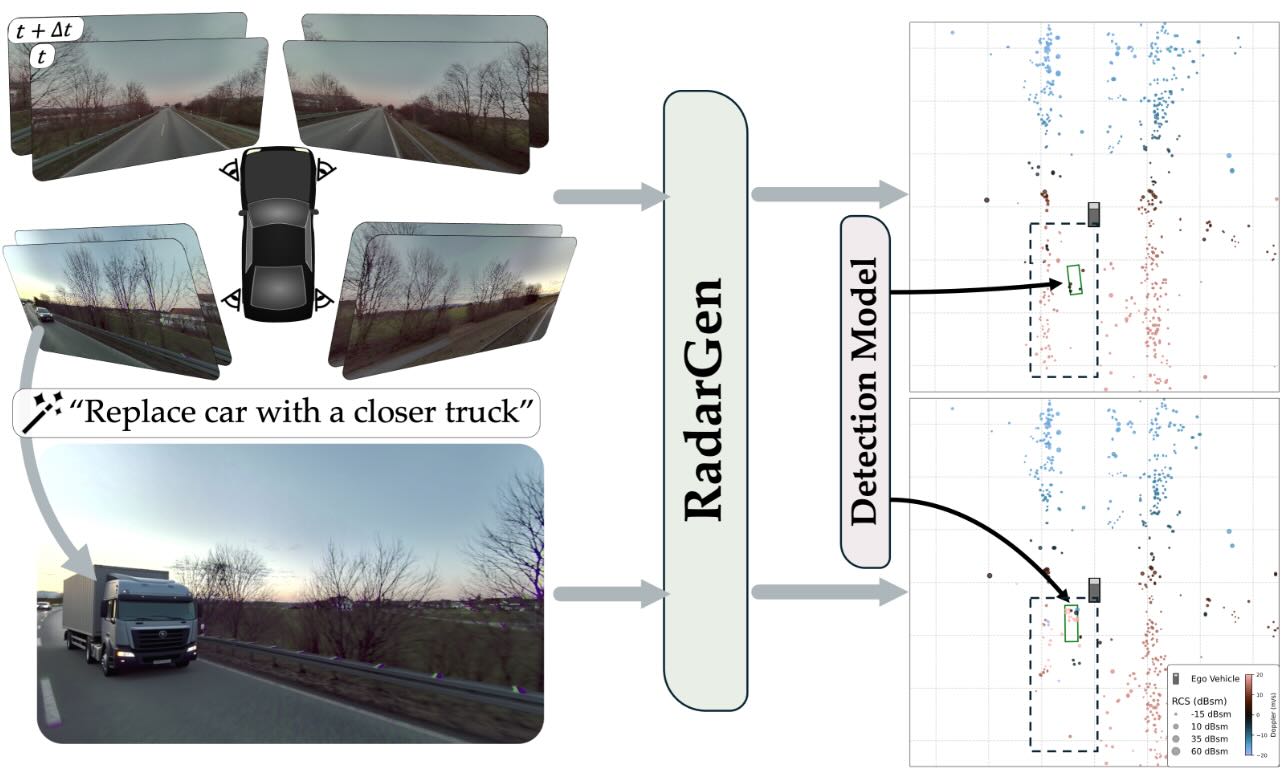
}RadarGen: Automotive Radar Point Cloud Generation from Cameras Tomer Borreda, Fangqiang Ding, Sanja Fidler, Shengyu Huang, Or Litany ECCV 2026 @misc{borreda2025radargenautomotiveradarpoint,
title = {RadarGen: Automotive Radar Point Cloud Generation from Cameras},
author = {Tomer Borreda and Fangqiang Ding and Sanja Fidler and Shengyu Huang and Or Litany},
year = {2025},
venue = {ECCV 2026},
eprint = {2512.17897},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2512.17897},
image = {./OL_files/radargen_teaser.jpg},
paper = {https://arxiv.org/abs/2512.17897},
page = {https://radargen.github.io/},
video = {https://www.youtube.com/watch?v=-g4zf8DzJDo},
tweet = {https://x.com/TomerBorreda/status/2002974157911593179}
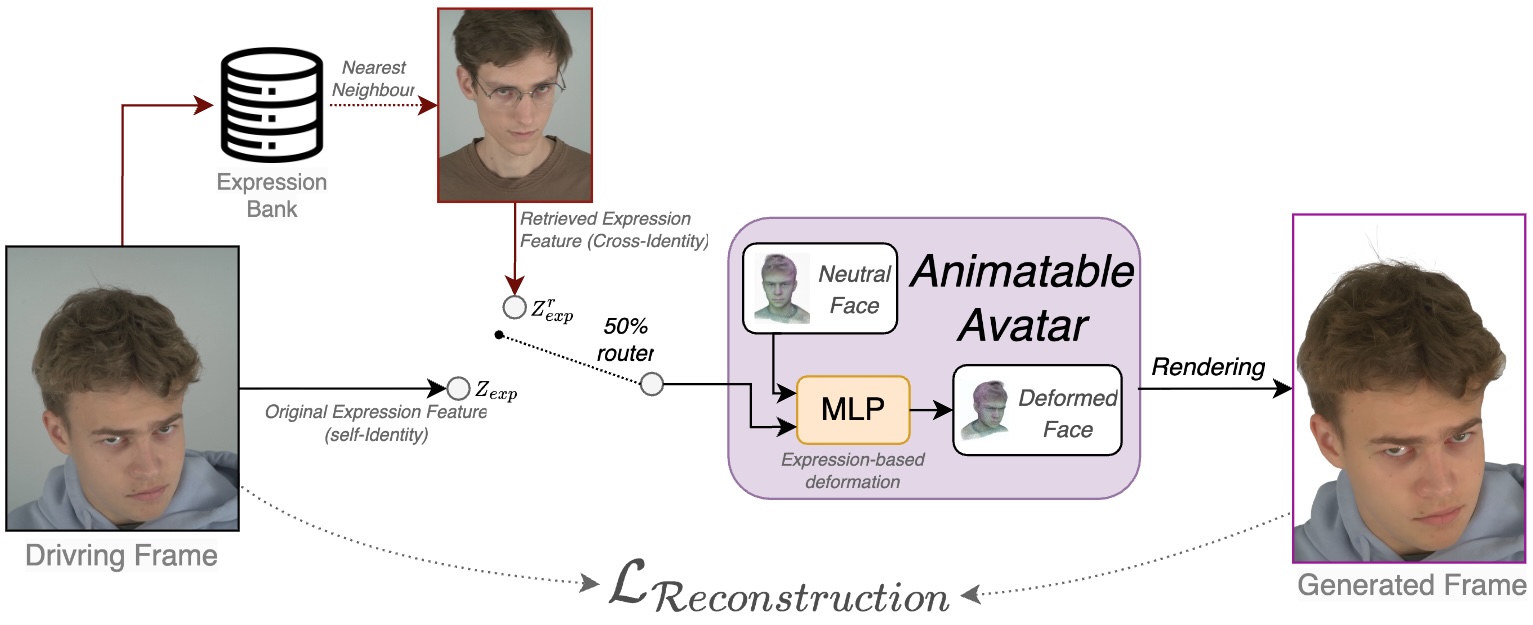
}Retrieval-Augmented Gaussian Avatars: Improving Expression Generalization Matan Levy, Gavriel Habib, Issar Tzachor, Dvir Samuel, Rami Ben-Ari, Nir Darshan, Or Litany, Dani Lischinski ECCV 2026 Workshop on Interactive Social Avatars (ISA) @misc{levy2026retrievalaugmentedgaussianavatarsimproving,
title = {Retrieval-Augmented Gaussian Avatars: Improving Expression Generalization},
author = {Matan Levy and Gavriel Habib and Issar Tzachor and Dvir Samuel and Rami Ben-Ari and Nir Darshan and Or Litany and Dani Lischinski},
year = {2026},
venue = {ECCV 2026 Workshop on Interactive Social Avatars (ISA)},
eprint = {2603.08645},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2603.08645},
image = {./OL_files/teaser_RAGaussianAvaters.jpg},
paper = {https://arxiv.org/abs/2603.08645}
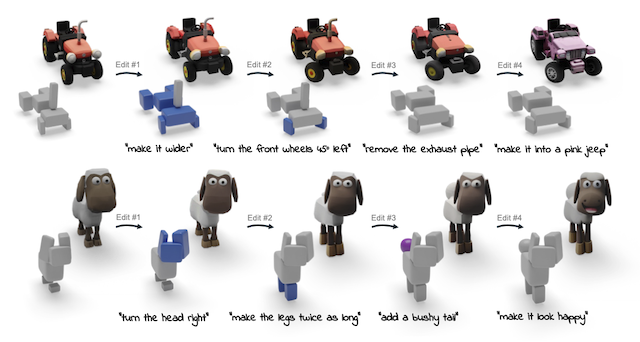
}Prox-E: Fine-Grained 3D Shape Editing via Primitive-Based Abstractions Etai Sella, Hao Phung, Nitay Amiel, Or Litany, Or Patashnik, Hadar Averbuch-Elor SIGGRAPH 2026 @misc{sella2026proxefinegrained3dshape,
title = {Prox-E: Fine-Grained 3D Shape Editing via Primitive-Based Abstractions},
author = {Etai Sella and Hao Phung and Nitay Amiel and Or Litany and Or Patashnik and Hadar Averbuch-Elor},
year = {2026},
venue = {SIGGRAPH 2026},
eprint = {2604.23774},
archiveprefix = {arXiv},
primaryclass = {cs.GR},
url = {https://arxiv.org/abs/2604.23774},
image = {./OL_files/teaser_proxe.png},
paper = {https://arxiv.org/abs/2604.23774},
page = {https://etaisella.github.io/Prox-E/},
tweet = {https://x.com/etai_sella/status/2051284611552936127?s=20}
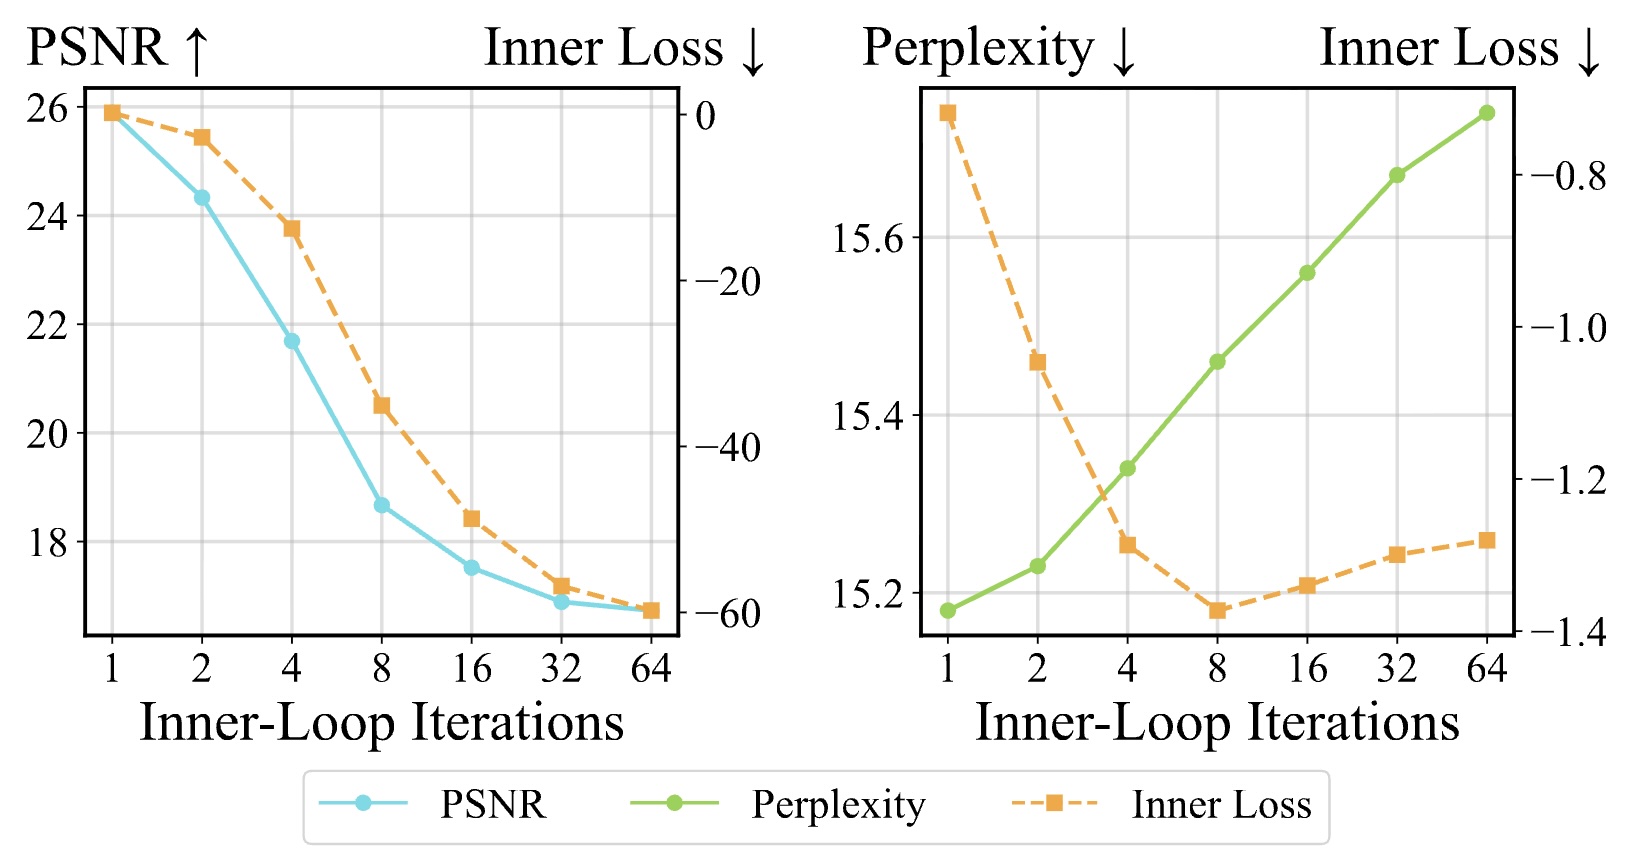
}Test-Time Training with KV Binding Is Secretly Linear Attention Junchen Liu, Sven Elflein, Or Litany, Zan Gojcic, Ruilong Li ICML 2026 @misc{liu2026testtimetrainingkvbinding,
title = {Test-Time Training with KV Binding Is Secretly Linear Attention},
author = {Junchen Liu and Sven Elflein and Or Litany and Zan Gojcic and Ruilong Li},
year = {2026},
venue = {ICML 2026},
eprint = {2602.21204},
archiveprefix = {arXiv},
primaryclass = {cs.LG},
url = {https://arxiv.org/abs/2602.21204},
image = {./OL_files/tttlinear_teaser.jpg},
paper = {https://arxiv.org/abs/2602.21204},
page = {https://research.nvidia.com/labs/sil/projects/tttla/},
tweet = {https://x.com/JunchenLiu77/status/2026665572755198224}
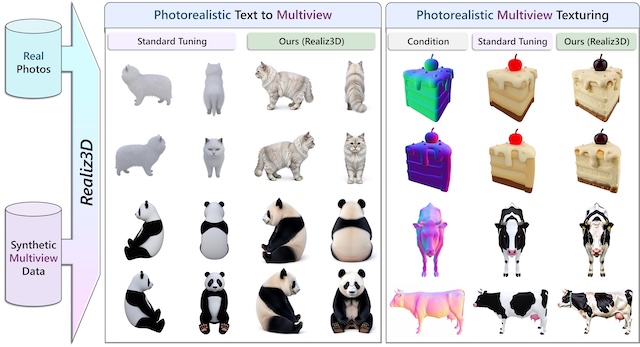
}Realiz3D: 3D Generation Made Photorealistic via Domain-Aware Learning Ido Sobol, Kihyuk Sohn, Yoav Blum, Egor Zakharov, Max Bluvstein, Andrea Vedaldi, Or Litany CVPR 2026 @inproceedings{sobol2026realiz3d,
title = {{Realiz3D}: {3D} Generation Made Photorealistic via Domain-Aware Learning},
author = {Ido Sobol and Kihyuk Sohn and Yoav Blum and Egor Zakharov and Max Bluvstein and Andrea Vedaldi and Or Litany},
year = {2026},
venue = {CVPR 2026},
booktitle = {Proceedings of the {IEEE}/CVF Conference on Computer Vision and Pattern Recognition ({CVPR})},
image = {./OL_files/realiz3d_teaser.jpg},
paper = {https://idosobol.github.io/realiz3d/realiz3d_paper.pdf},
page = {https://idosobol.github.io/realiz3d/},
tweet = {https://x.com/IdoSobol/status/2040039788103754206?s=20}
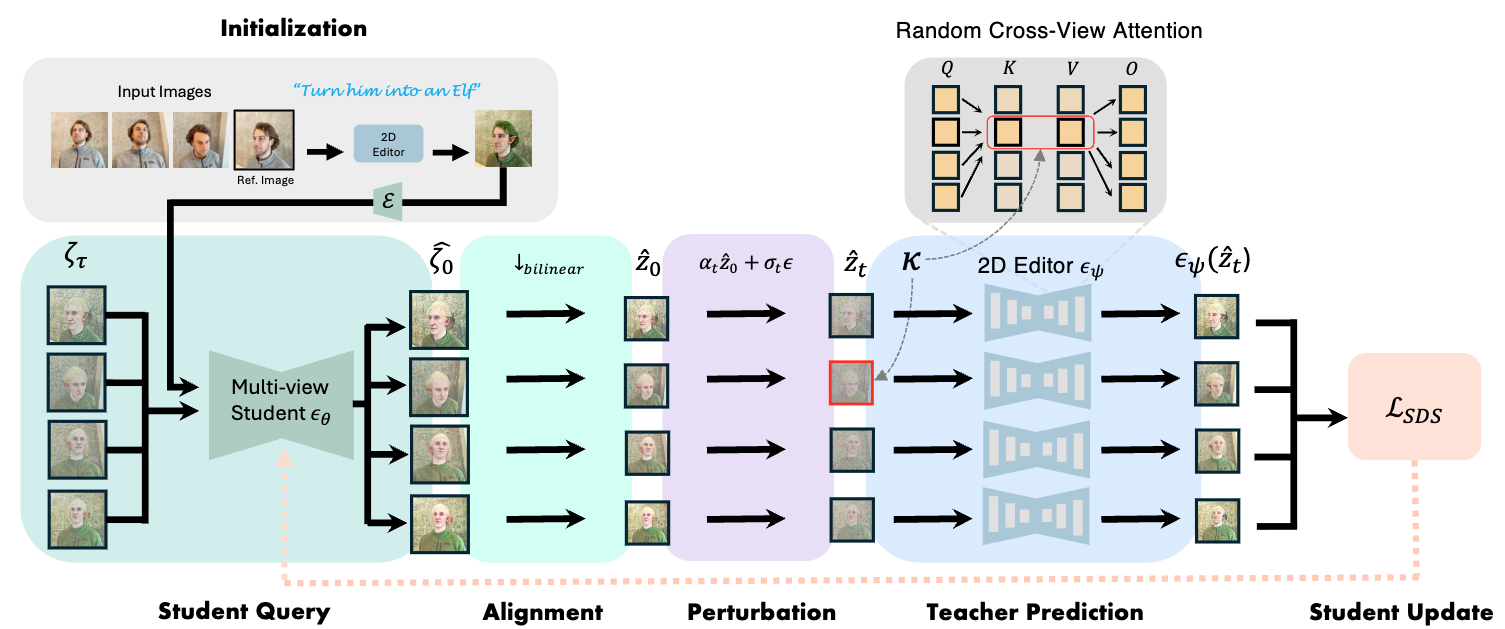
}InstructMix2Mix: Consistent Sparse-View Editing Through Multi-View Model Personalization Daniel Gilo, Or Litany CVPR 2026 @misc{gilo2025instructmix2mixconsistentsparseviewediting,
title = {InstructMix2Mix: Consistent Sparse-View Editing Through Multi-View Model Personalization},
author = {Daniel Gilo and Or Litany},
year = {2025},
venue = {CVPR 2026},
eprint = {2511.14899},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2511.14899},
image = {./OL_files/teaser_IM2M.png},
paper = {https://www.arxiv.org/abs/2511.14899},
page = {https://danielgilo.github.io/instruct-mix2mix/},
code = {https://github.com/DanielGilo/instruct-mix2mix/tree/main},
tweet = {https://x.com/orlitany/status/2026628621968789738?s=20}
}DiffusionHarmonizer: Bridging Neural Reconstruction and Photorealistic Simulation with Online Diffusion Enhancer Yuxuan Zhang, Katarı́na Tóthová, Zian Wang, Kangxue Yin, Haithem Turki, Riccardo de Lutio, Yen-Yu Chang, Or Litany, Sanja Fidler, Zan Gojcic CVPR 2026 @article{zhang2026diffusionharmonizer,
title = {DiffusionHarmonizer: Bridging Neural Reconstruction and Photorealistic Simulation with Online Diffusion Enhancer},
author = {Zhang, Yuxuan and T{\'o}thov{\'a}, Katar{\'\i}na and Wang, Zian and Yin, Kangxue and Turki, Haithem and de Lutio, Riccardo and Chang, Yen-Yu and Litany, Or and Fidler, Sanja and Gojcic, Zan},
year = {2026},
venue = {CVPR 2026},
journal = {arXiv preprint arXiv:2602.24096},
image = {./OL_files/harmonizer_teaser.gif},
paper = {https://arxiv.org/abs/2602.24096},
page = {https://research.nvidia.com/labs/sil/projects/diffusion-harmonizer/}
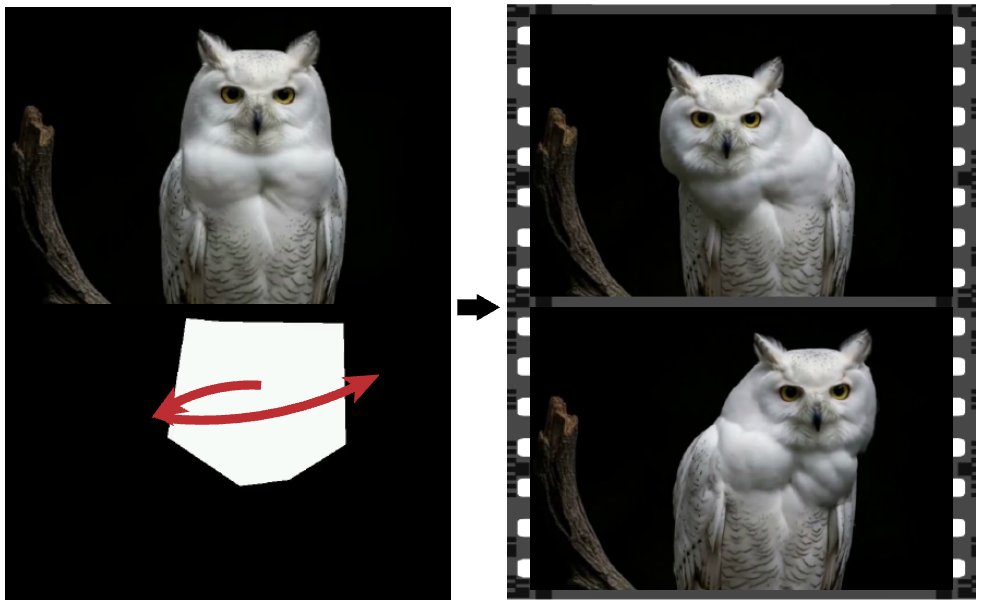
}Time-to-Move: Training-Free Motion Controlled Video Generation via Dual-Clock Denoising Assaf Singer, Noam Rotstein, Amir Mann, Ron Kimmel, Or Litany ICLR 2026 @misc{singer2025timetomovetrainingfreemotioncontrolled,
title = {Time-to-Move: Training-Free Motion Controlled Video Generation via Dual-Clock Denoising},
author = {Assaf Singer and Noam Rotstein and Amir Mann and Ron Kimmel and Or Litany},
year = {2025},
venue = {ICLR 2026},
eprint = {2511.08633},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2511.08633},
image = {./OL_files/teaser_T2M.png},
paper = {https://arxiv.org/abs/2511.08633},
page = {https://time-to-move.github.io/},
code = {https://github.com/time-to-move/TTM},
tweet = {https://x.com/assaf_singer/status/1988967522033647618}
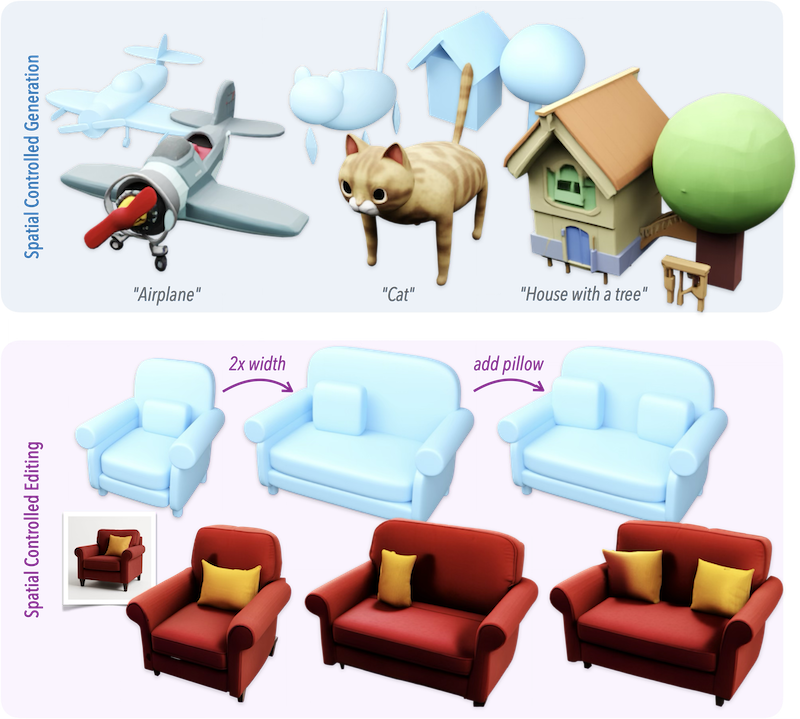
}SpaceControl: Introducing Test-Time Spatial Control to 3D Generative Modeling Elisabetta Fedele, Francis Engelmann, Ian Huang, Or Litany, Marc Pollefeys, Leonidas Guibas ICLR 2026 @misc{fedele2025spacecontrolintroducingtesttimespatial,
title = {SpaceControl: Introducing Test-Time Spatial Control to 3D Generative Modeling},
author = {Elisabetta Fedele and Francis Engelmann and Ian Huang and Or Litany and Marc Pollefeys and Leonidas Guibas},
year = {2025},
venue = {ICLR 2026},
eprint = {2512.05343},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2512.05343},
image = {./OL_files/teaser_supergen.png},
paper = {https://arxiv.org/abs/2512.05343},
page = {https://spacecontrol3d.github.io/},
code = {https://github.com/spacecontrol3d/spacecontrol},
tweet = {https://x.com/efedele16/status/1997978439719305725}
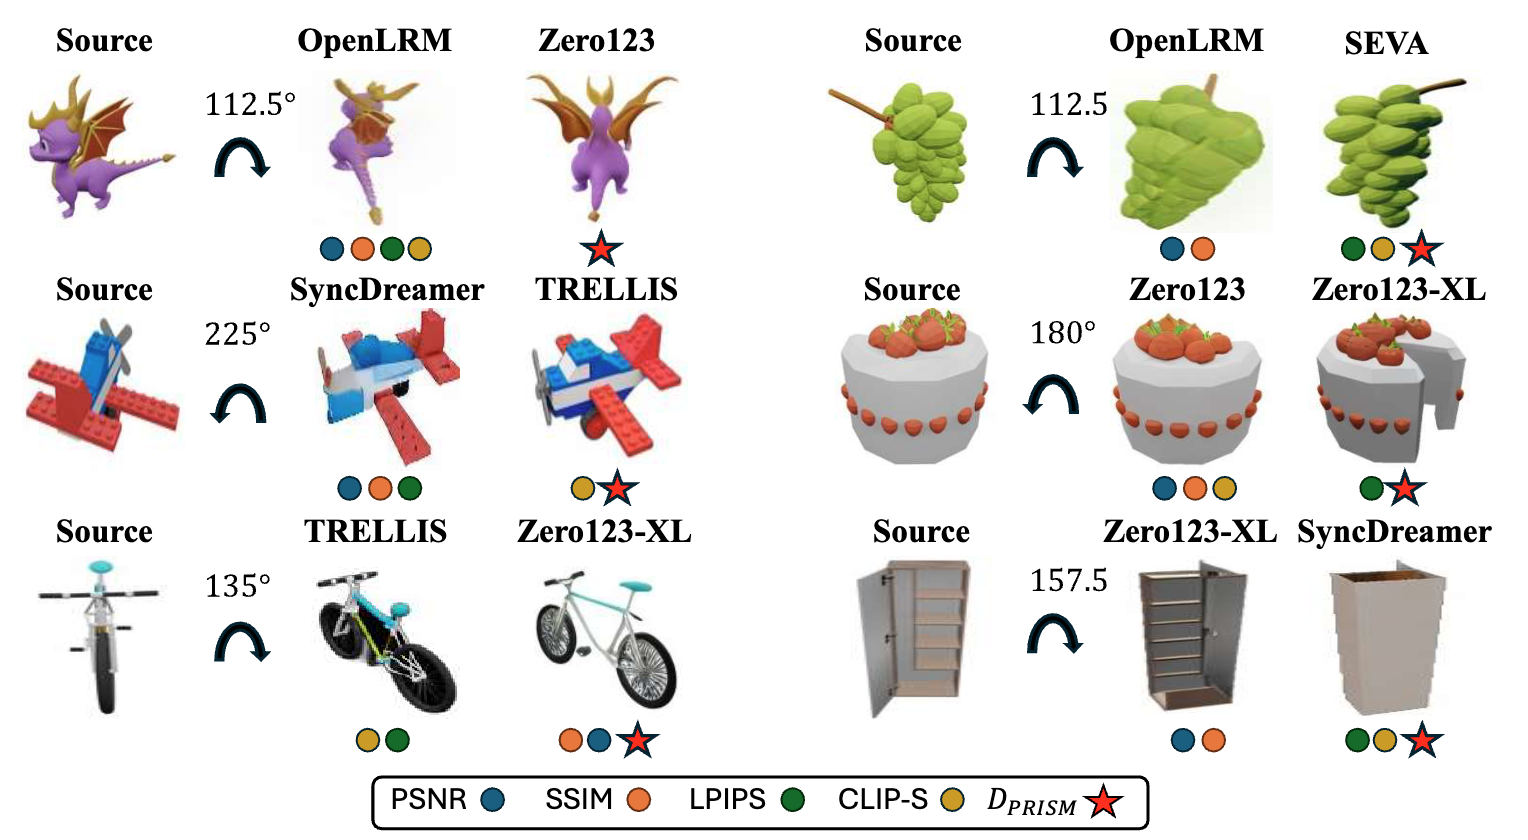
}Appreciate the View: A Task-Aware Evaluation Framework for Novel View Synthesis Saar Stern, Ido Sobol, Or Litany 3DV 2026 @misc{stern2025appreciateviewtaskawareevaluation,
title = {Appreciate the View: A Task-Aware Evaluation Framework for Novel View Synthesis},
author = {Saar Stern and Ido Sobol and Or Litany},
year = {2025},
venue = {3DV 2026},
eprint = {2511.12675},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2511.12675},
image = {./OL_files/teaser_AppreciatetheView.png},
paper = {https://arxiv.org/abs/2511.12675},
page = {https://saarst.github.io/appreciate-the-view-website/},
code = {https://github.com/saarst/appreciate-the-view},
tweet = {https://x.com/SternSaar/status/1991622794925469952}
}2025Gaussian See, Gaussian Do: Semantic 3D Motion Transfer from Multiview Video Yarin Bekor, Gal Michael Harari, Or Perel, Or Litany SIGGRAPH-ASIA 2025 @misc{bekor2025gaussianseegaussiando,
title = {Gaussian See, Gaussian Do: Semantic 3D Motion Transfer from Multiview Video},
author = {Yarin Bekor and Gal Michael Harari and Or Perel and Or Litany},
year = {2025},
venue = {SIGGRAPH-ASIA 2025},
eprint = {2511.14848},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2511.14848},
image = {./OL_files/GSGD_teaser.jpg},
paper = {https://arxiv.org/pdf/2511.14848},
page = {https://gsgd-motiontransfer.github.io/}
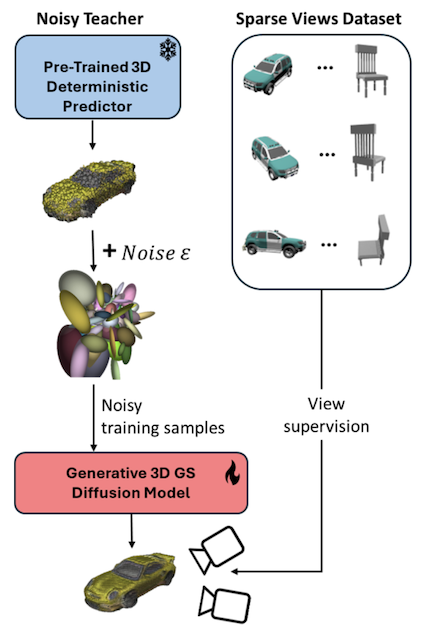
}A Lesson in Splats: Teacher-Guided Diffusion for 3D Gaussian Splats Generation with 2D Supervision Chensheng Peng, Ido Sobol, Masayoshi Tomizuka, Kurt Keutzer, Chenfeng Xu, Or Litany ICCV 2025 @article{peng2024lessonsplatsteacherguideddiffusion,
title = {A Lesson in Splats: Teacher-Guided Diffusion for 3D Gaussian Splats Generation with 2D Supervision},
author = {Chensheng Peng and Ido Sobol and Masayoshi Tomizuka and Kurt Keutzer and Chenfeng Xu and Or Litany},
year = {2025},
venue = {ICCV 2025},
journal = {ICCV},
url = {https://arxiv.org/abs/2412.00623},
image = {./OL_files/lessonInSplats.png},
paper = {https://arxiv.org/abs/2412.00623},
page = {https://lesson-in-splats.github.io/}
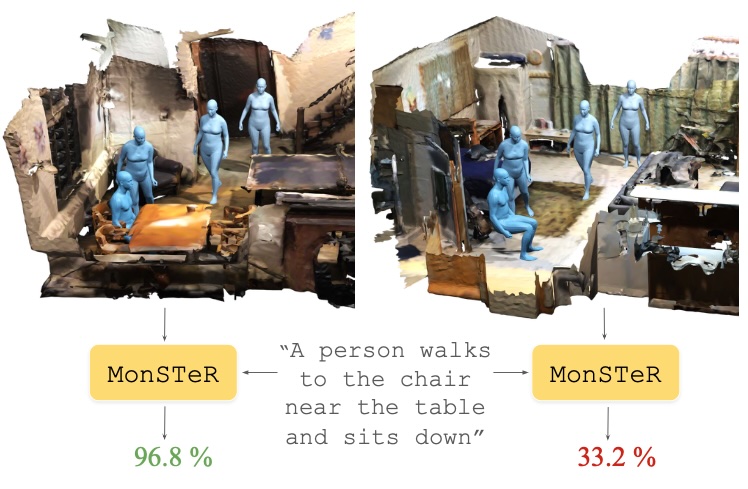
}MonSTeR: a Unified Model for Motion, Scene, Text Retrieval Luca Collorone, Matteo Gioia, Massimiliano Pappa, Paolo Leoni, Giovanni Ficarra, Or Litany, Indro Spinelli, Fabio Galasso ICCV 2025 @article{collorone2025monster,
title = {MonSTeR: a Unified Model for Motion, Scene, Text Retrieval},
author = {Collorone, Luca and Gioia, Matteo and Pappa, Massimiliano and Leoni, Paolo and Ficarra, Giovanni and Litany, Or and Spinelli, Indro and Galasso, Fabio},
year = {2025},
venue = {ICCV 2025},
journal = {ICCV},
image = {./OL_files/monster_teaser.jpg},
paper = {https://arxiv.org/abs/2510.03200},
code = {https://github.com/colloroneluca/MonSTeR?tab=readme-ov-file},
tweet = {https://x.com/IndroSpinelli/status/1940445067959038357}
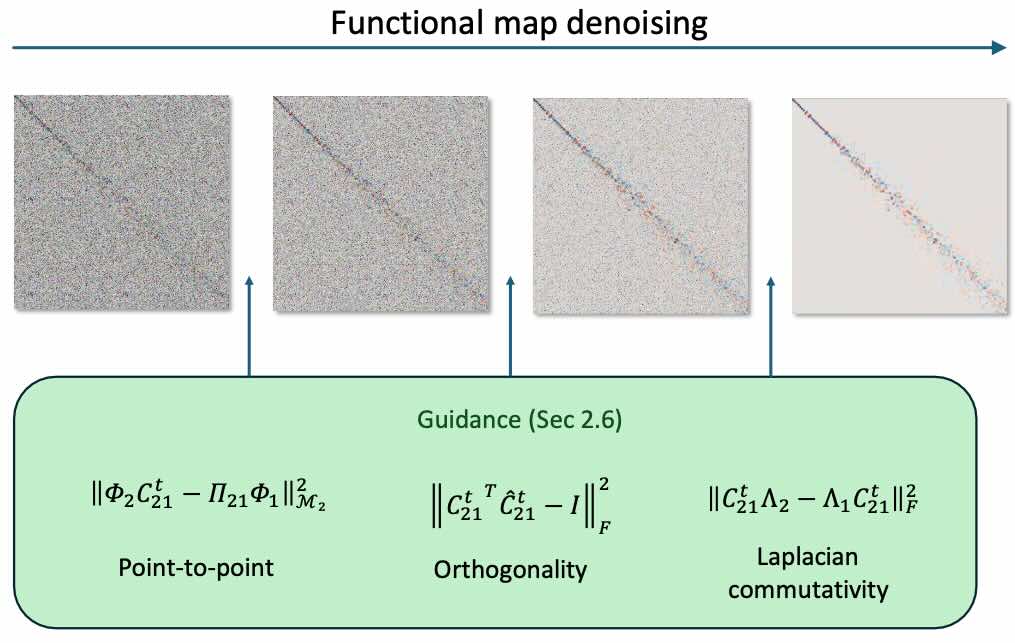
}FRIDU: Functional Map Refinement with Guided Image Diffusion Avigail Cohen Rimon, Mirela Ben-Chen, Or Litany SGP 2025 @article{rimon2025fridu,
title = {FRIDU: Functional Map Refinement with Guided Image Diffusion},
author = {{Cohen Rimon}, Avigail and Ben-Chen, Mirela and Litany, Or},
year = {2025},
venue = {SGP 2025},
journal = {SGP},
image = {./OL_files/FRIDU_teaser.jpg},
paper = {https://arxiv.org/abs/2506.14322},
code = {https://github.com/avigailco/FRIDU}
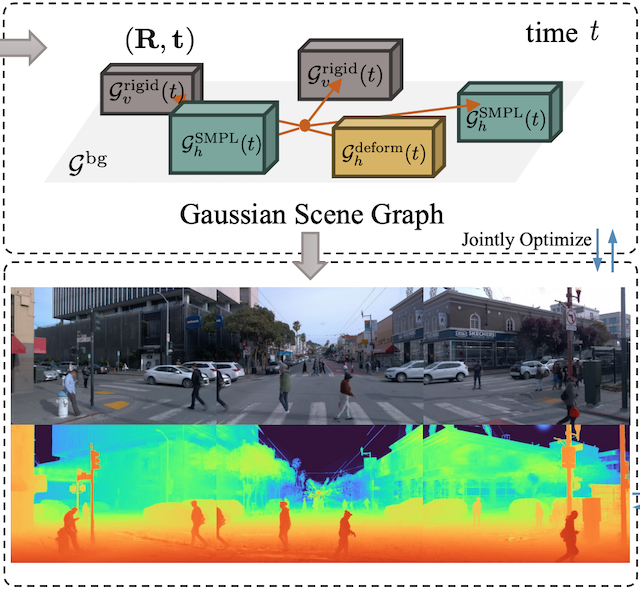
}OmniRe: Omni Urban Scene Reconstruction Ziyu Chen, Jiawei Yang, Jiahui Huang, Riccardo de Lutio, Janick Martinez Esturo, Boris Ivanovic, Or Litany, Zan Gojcic, Sanja Fidler, Marco Pavone, Li Song, Yue Wang ICLR 2025Spotlight @article{chen2024omnire,
title = {OmniRe: Omni Urban Scene Reconstruction},
author = {Ziyu Chen and Jiawei Yang and Jiahui Huang and Riccardo de Lutio and Janick {Martinez Esturo} and Boris Ivanovic and Or Litany and Zan Gojcic and Sanja Fidler and Marco Pavone and Li Song and Yue Wang},
year = {2024},
venue = {ICLR 2025},
journal = {arXiv preprint arXiv:2408.16760},
image = {./OL_files/omnire.png},
paper = {https://arxiv.org/abs/2408.16760},
page = {https://ziyc.github.io/omnire/},
award = {Spotlight}
}GAS-NeRF: Geometry-Aware Stylization of Dynamic Radiance Fields Nhat Phuong Anh Vu, Abhishek Saroha, Or Litany, Daniel Cremers Preprint @misc{vu2025gasnerfgeometryawarestylizationdynamic,
title = {GAS-NeRF: Geometry-Aware Stylization of Dynamic Radiance Fields},
author = {Nhat Phuong Anh Vu and Abhishek Saroha and Or Litany and Daniel Cremers},
year = {2025},
venue = {Preprint},
eprint = {2503.08483},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2503.08483},
image = {./OL_files/GASnerf_teaser.png},
paper = {https://arxiv.org/abs/2503.08483}
}ZDySS – Zero-Shot Dynamic Scene Stylization using Gaussian Splatting Abhishek Saroha, Florian Hofherr, Mariia Gladkova, Cecilia Curreli, Or Litany, Daniel Cremers Preprint @misc{saroha2025zdysszeroshotdynamic,
title = {ZDySS -- Zero-Shot Dynamic Scene Stylization using Gaussian Splatting},
author = {Abhishek Saroha and Florian Hofherr and Mariia Gladkova and Cecilia Curreli and Or Litany and Daniel Cremers},
year = {2025},
venue = {Preprint},
eprint = {2501.03875},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
url = {https://arxiv.org/abs/2501.03875},
image = {./OL_files/teaser_zdyss.png},
paper = {https://arxiv.org/abs/2501.03875}
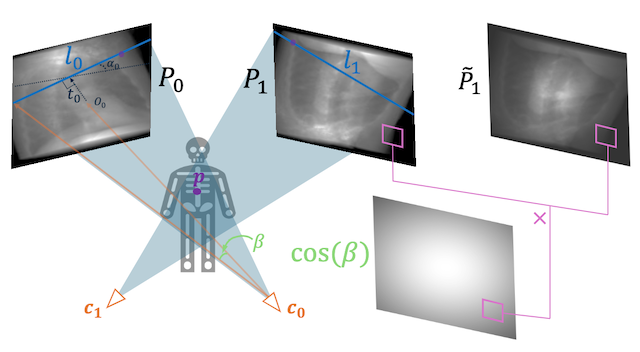
}Epi-NAF: Enhancing Neural Attenuation Fields for Limited-Angle CT with Epipolar Consistency Conditions Daniel Gilo, Tzofi Klinghoffer, Or Litany ISBI 2025Oral @article{gilo2024epi,
title = {Epi-NAF: Enhancing Neural Attenuation Fields for Limited-Angle CT with Epipolar Consistency Conditions},
author = {Gilo, Daniel and Klinghoffer, Tzofi and Litany, Or},
year = {2024},
venue = {ISBI 2025},
journal = {arXiv preprint arXiv:2411.06181},
image = {./OL_files/epinaf_teaser.png},
paper = {https://arxiv.org/abs/2411.06181v1},
award = {Oral}
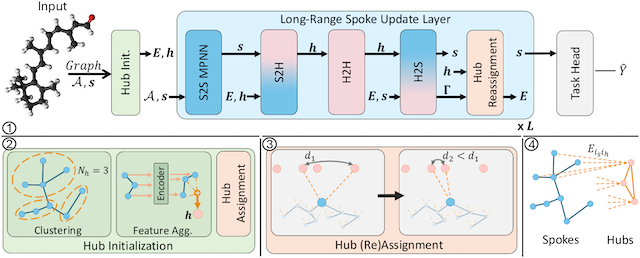
}2024ReHub: Linear Complexity Graph Transformers with Adaptive Hub-Spoke Reassignment Tomer Borreda, Daniel Freedman, Or Litany TMLR @misc{borreda2024rehublinearcomplexitygraph,
title = {ReHub: Linear Complexity Graph Transformers with Adaptive Hub-Spoke Reassignment},
author = {Tomer Borreda and Daniel Freedman and Or Litany},
year = {2024},
venue = {TMLR},
eprint = {2412.01519},
archiveprefix = {arXiv},
primaryclass = {cs.LG},
url = {https://arxiv.org/abs/2412.01519},
image = {./OL_files/rehub.png},
paper = {https://arxiv.org/abs/2412.01519},
page = {https://tomerborreda.github.io/rehub/}
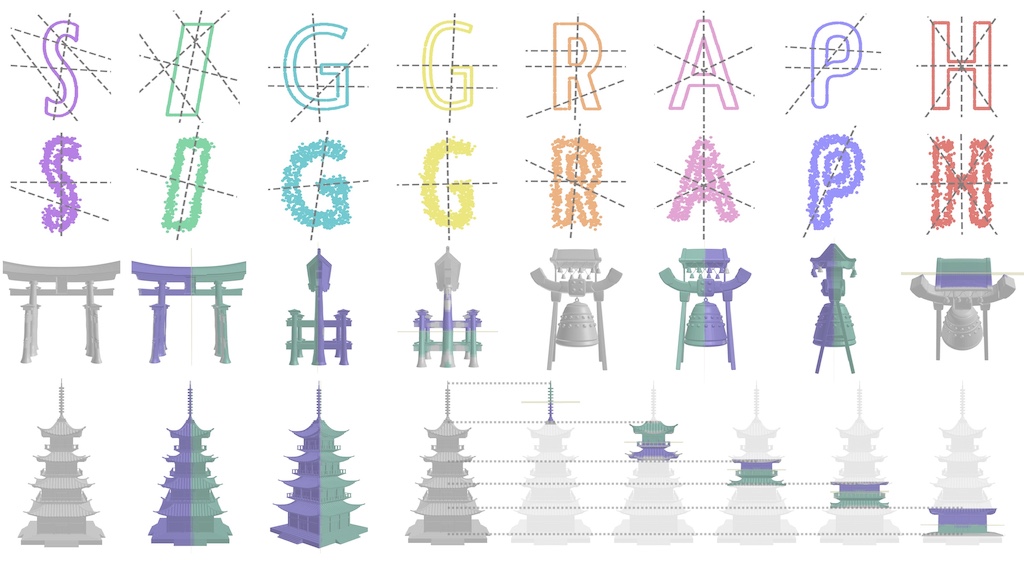
}Robust Symmetry Detection via Riemannian Langevin Dynamics Jihyeon Je, Jiayi Liu, Guandao Yang, Boyang Deng, Shengqu Cai, Gordon Wetzstein, Or Litany, Leonidas Guibas SIGGRAPH-ASIA 2024 @article{je2024robustlangsym,
title = {Robust Symmetry Detection via Riemannian Langevin Dynamics},
author = {Jihyeon Je and Jiayi Liu and Guandao Yang and Boyang Deng and Shengqu Cai and Gordon Wetzstein and Or Litany and Leonidas Guibas},
year = {2024},
venue = {SIGGRAPH-ASIA 2024},
journal = {ACM Trans. Graph.},
eprint = {arXiv:2410.02786},
doi = {10.1145/3680528.3687682},
image = {./OL_files/symmetry_teaser.jpg},
paper = {https://arxiv.org/abs/2410.02786},
page = {https://symmetry-langevin.github.io/}
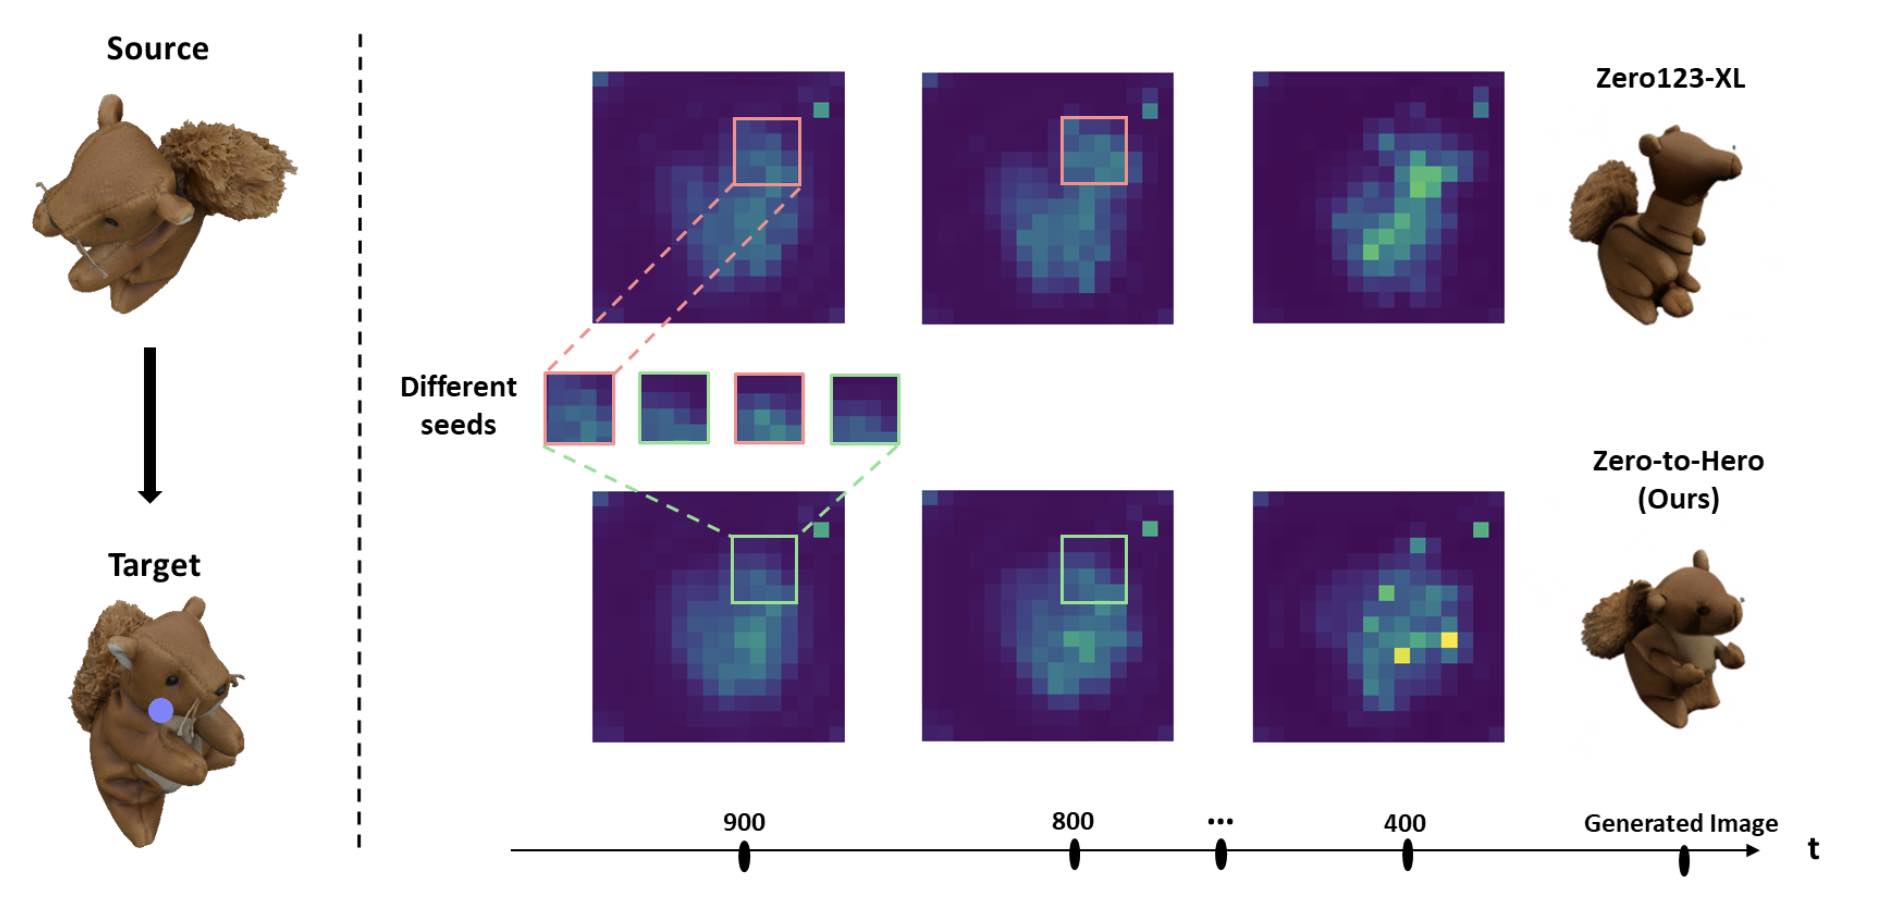
}Zero-to-Hero: Enhancing Zero-Shot Novel View Synthesis via Attention Map Filtering Ido Sobol, Chenfeng Xu, Or Litany NeurIPS 2024 @misc{sobol2024zerotohero,
title = {Zero-to-Hero: Enhancing Zero-Shot Novel View Synthesis via Attention Map Filtering},
author = {Ido Sobol and Chenfeng Xu and Or Litany},
year = {2024},
venue = {NeurIPS 2024},
journal = {NeurIPS},
image = {./OL_files/zero2hero.jpg},
paper = {https://arxiv.org/abs/2405.18677},
page = {https://zero2hero-nvs.github.io/},
tweet = {https://x.com/orlitany/status/1840155773029986480}
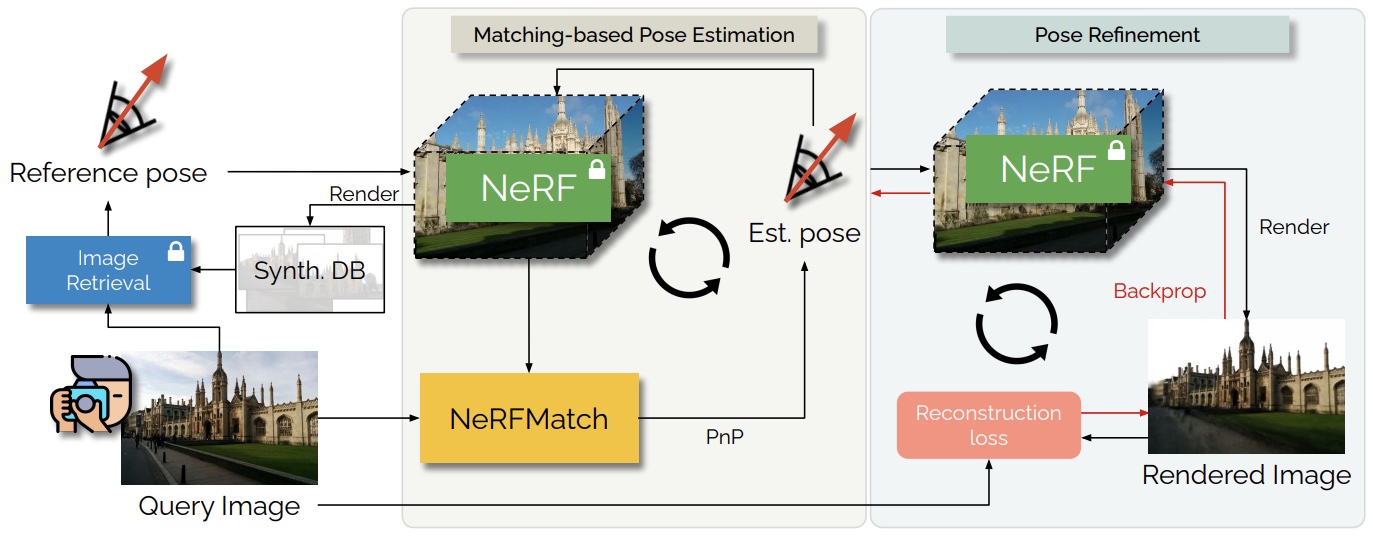
}The NeRFect Match: Exploring NeRF Features for Visual Localization Qunjie Zhou, Maxim Maximov, Or Litany, Laura Leal-Taixé ECCV 2024 @misc{zhou2024nerfect,
title = {The NeRFect Match: Exploring NeRF Features for Visual Localization},
author = {Qunjie Zhou and Maxim Maximov and Or Litany and Laura Leal-Taixé},
year = {2024},
venue = {ECCV 2024},
journal = {ECCV},
image = {./OL_files/nerfmatch_teaser.jpg},
paper = {https://arxiv.org/abs/2403.09577},
page = {https://nerfmatch.github.io/}
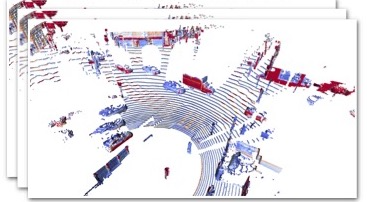
}Dynamic LiDAR Re-simulation using Compositional Neural Fields Hanfeng Wu, Xingxing Zuo, Stefan Leutenegger, Or Litany, Konrad Schindler, Shengyu Huang CVPR 2024 @inproceedings{Wu2023dynfl,
title = {Dynamic LiDAR Re-simulation using Compositional Neural Fields},
author = {Wu, Hanfeng and Zuo, Xingxing and Leutenegger, Stefan and Litany, Or and Schindler, Konrad and Huang, Shengyu},
year = {2024},
venue = {CVPR 2024},
booktitle = {The IEEE Conference on Computer Vision and Pattern Recognition (CVPR)},
image = {./OL_files/dynfl_teaser.png},
paper = {https://arxiv.org/abs/2312.05247},
page = {https://shengyuh.github.io/dynfl/index.html}
}3DiffTection: 3D Object Detection with Geometry-Aware Diffusion Features Chenfeng Xu, Huan Ling, Sanja Fidler, Or Litany CVPR 2024 @article{xu20233difftection,
title = {3DiffTection: 3D Object Detection with Geometry-Aware Diffusion Features},
author = {Chenfeng Xu and Huan Ling and Sanja Fidler and Or Litany},
year = {2023},
venue = {CVPR 2024},
journal = {CVPR},
image = {./OL_files/3difftection.png},
paper = {https://arxiv.org/abs/2311.04391},
page = {https://research.nvidia.com/labs/toronto-ai/3difftection/}
}UnScene3D: Unsupervised 3D Instance Segmentation for Indoor Scenes David Rozenberszki, Or Litany, Angela Dai CVPR 2024 @misc{rozenberszki2023unscene3d,
title = {UnScene3D: Unsupervised 3D Instance Segmentation for Indoor Scenes},
author = {David Rozenberszki and Or Litany and Angela Dai},
year = {2023},
venue = {CVPR 2024},
journal = {arXiv preprint arXiv:2303.14541},
image = {./OL_files/unscene3d_teaser.jpeg},
paper = {https://arxiv.org/abs/2303.14541},
page = {https://rozdavid.github.io/unscene3d}
}Approximately Piecewise E(3) Equivariant Point Networks Matan Atzmon, Jiahui Huang, Francis Williams, Or Litany ICLR 2024 @article{atzmon2024approximately,
title = {Approximately Piecewise {E(3)} Equivariant Point Networks},
author = {Atzmon, Matan and Huang, Jiahui and Williams, Francis and Litany, Or},
year = {2024},
venue = {ICLR 2024},
journal = {ICLR},
image = {./OL_files/APEN_teaser.jpg},
paper = {https://arxiv.org/abs/2402.08529}
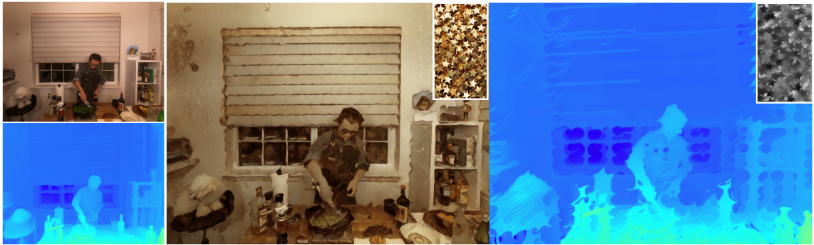
}EmerNeRF: Emergent Spatial-Temporal Scene Decomposition via Self-Supervision Jiawei Yang, Boris Ivanovic, Or Litany, Xinshuo Weng, Seung Wook Kim, Boyi Li, Tong Che, Danfei Xu, Sanja Fidler, Marco Pavone, Yue Wang ICLR 2024 @article{yang2023emernerf,
title = {EmerNeRF: Emergent Spatial-Temporal Scene Decomposition via Self-Supervision},
author = {Jiawei Yang and Boris Ivanovic and Or Litany and Xinshuo Weng and Seung Wook Kim and Boyi Li and Tong Che and Danfei Xu and Sanja Fidler and Marco Pavone and Yue Wang},
year = {2023},
venue = {ICLR 2024},
journal = {arXiv preprint arXiv:2311.02077},
image = {./OL_files/emerf_overview.png},
paper = {https://arxiv.org/abs/2311.02077},
page = {https://emernerf.github.io/}
}STMC: Multi-Track Timeline Control for Text-Driven 3D Human Motion Generation Mathis Petrovich, Or Litany, Umar Iqbal, Michael J. Black, Gül Varol, Xue Bin Peng, Davis Rempe CVPR 2024 Workshop on Human Motion Generation @article{petrovich24stmc,
title = {{STMC}: Multi-Track Timeline Control for Text-Driven 3D Human Motion Generation},
author = {Petrovich, Mathis and Litany, Or and Iqbal, Umar and Black, Michael J. and Varol, G{\"u}l and Peng, Xue Bin and Rempe, Davis},
year = {2024},
venue = {CVPR 2024 Workshop on Human Motion Generation},
journal = {arXiv:2401.08559},
image = {./OL_files/multitrack_teaser.png},
paper = {https://arxiv.org/abs/2401.08559},
page = {https://mathis.petrovich.fr/stmc/}
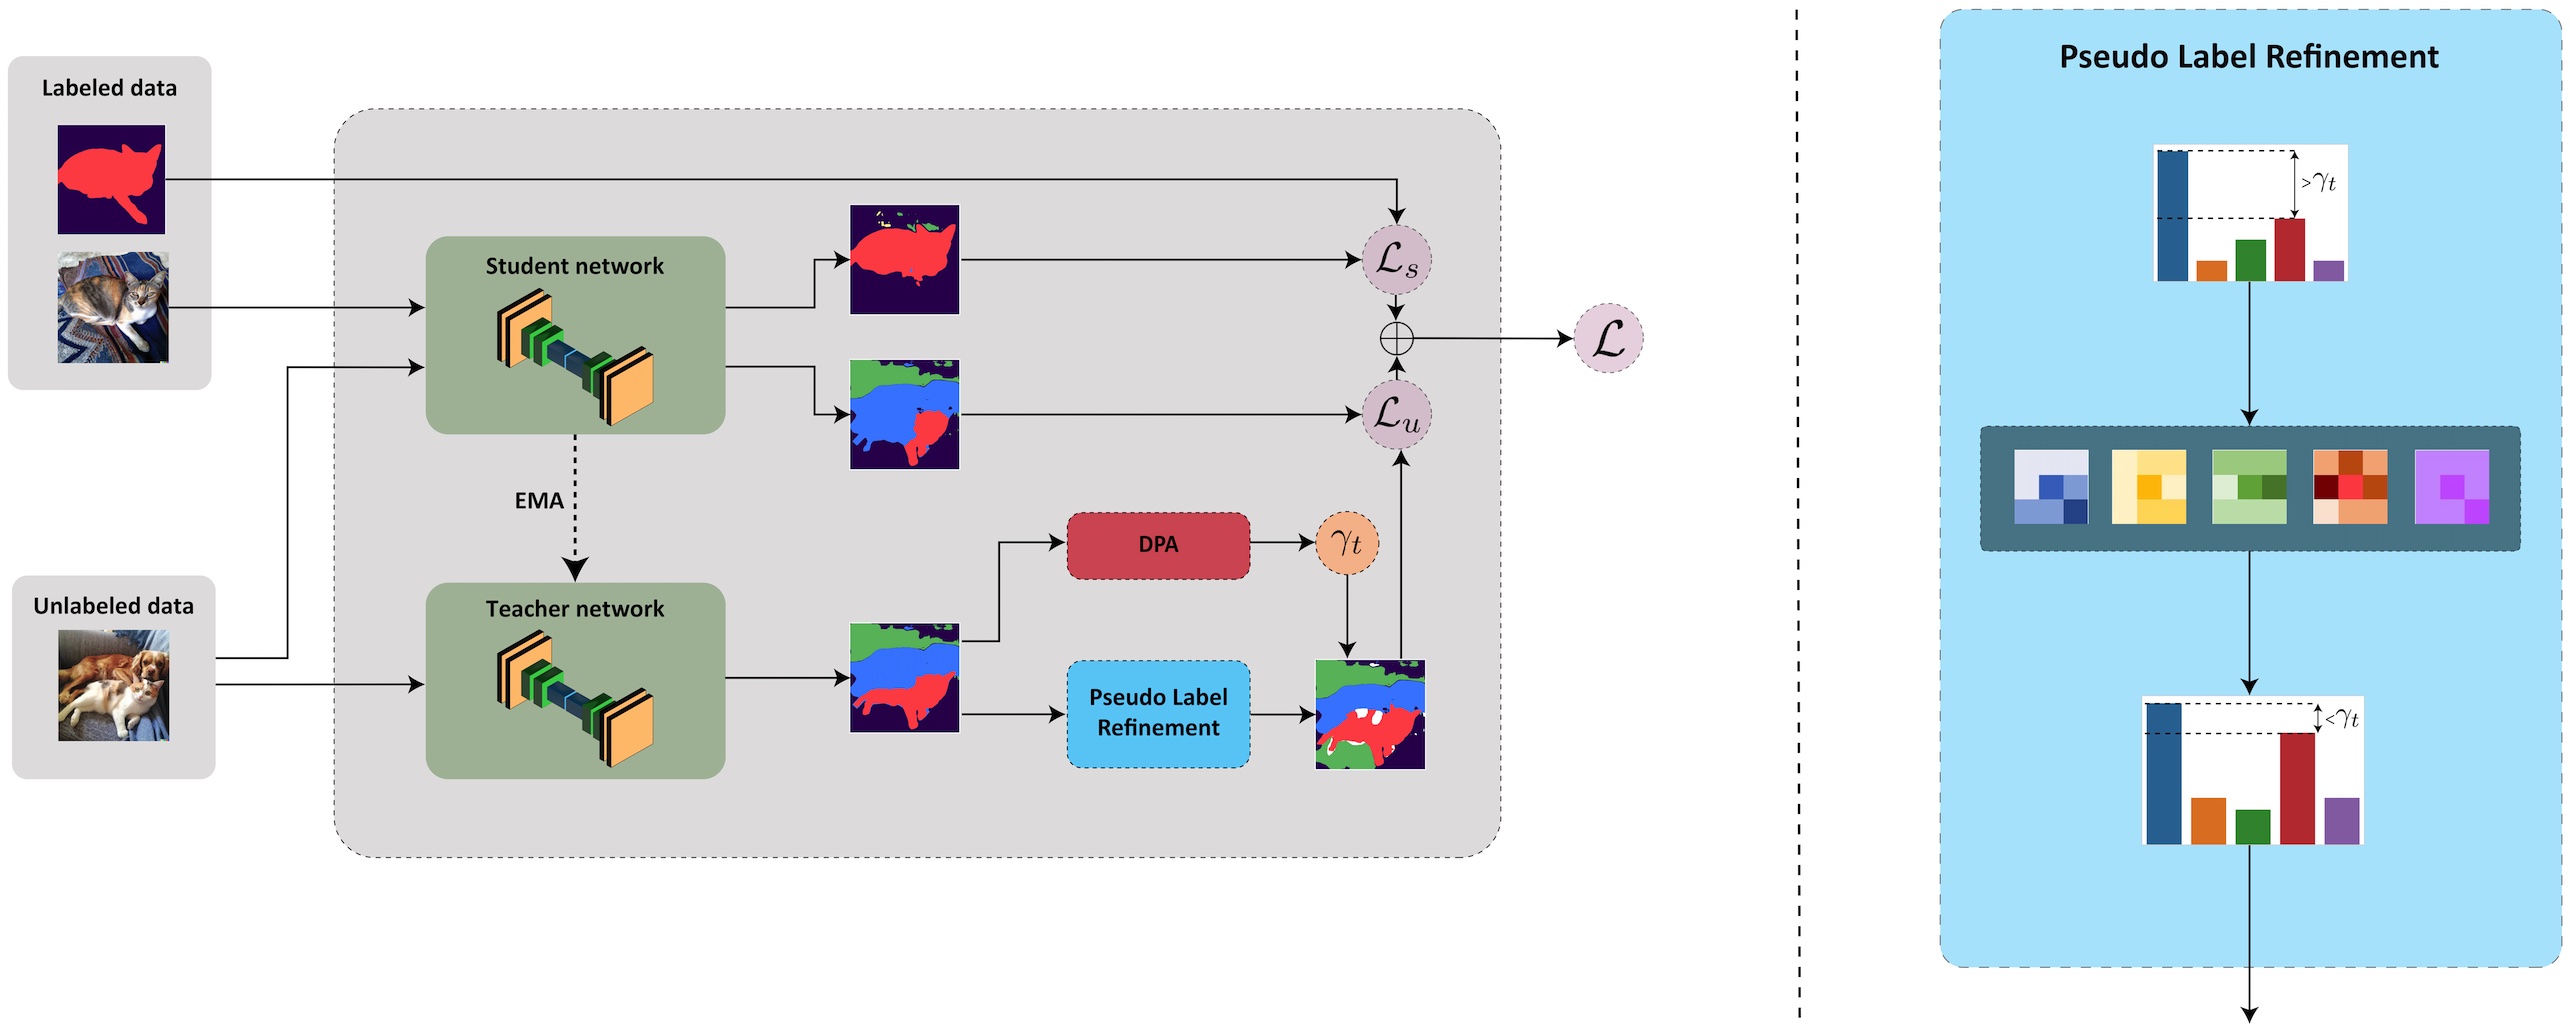
}2023Semi-Supervised Semantic Segmentation via Marginal Contextual Information Moshe Kimhi, Shai Kimhi, Evgenii Zheltonozhskii, Or Litany, Chaim Baskin TMLR @article{kimhi2023semisupervised,
title = {Semi-Supervised Semantic Segmentation via Marginal Contextual Information},
author = {Moshe Kimhi and Shai Kimhi and Evgenii Zheltonozhskii and Or Litany and Chaim Baskin},
year = {2023},
venue = {TMLR},
eprint = {2308.13900},
archiveprefix = {arXiv},
primaryclass = {cs.CV},
image = {./OL_files/s4mc_teaser.png},
paper = {https://arxiv.org/abs/2308.13900},
page = {https://s4mcontext.github.io/}
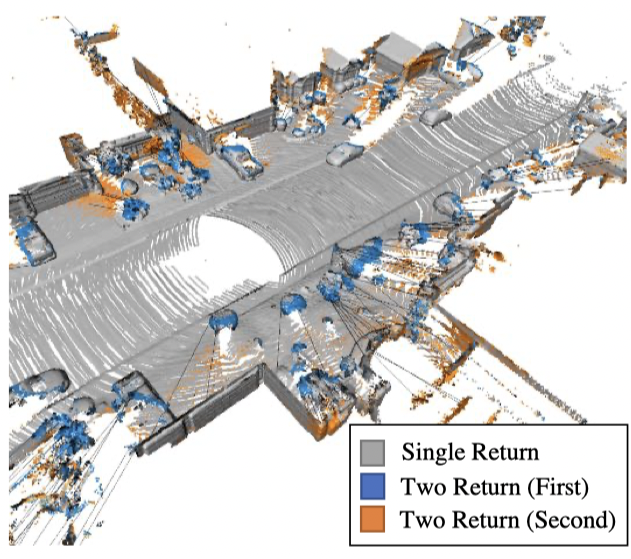
}Neural LiDAR Fields for Novel View Synthesis Shengyu Huang, Zan Gojcic, Zian Wang, Francis Williams, Yoni Kasten, Sanja Fidler, Konrad Schindler, Or Litany ICCV 2023 @article{Huang2023nfl,
title = {Neural LiDAR Fields for Novel View Synthesis},
author = {Huang, Shengyu and Gojcic, Zan and Wang, Zian and Williams, Francis and Kasten, Yoni and Fidler, Sanja and Schindler, Konrad and Litany, Or},
year = {2023},
venue = {ICCV 2023},
journal = {arXiv preprint},
image = {./OL_files/nfl_teaser.png},
paper = {https://arxiv.org/abs/2305.01643},
page = {https://research.nvidia.com/labs/toronto-ai/nfl/}
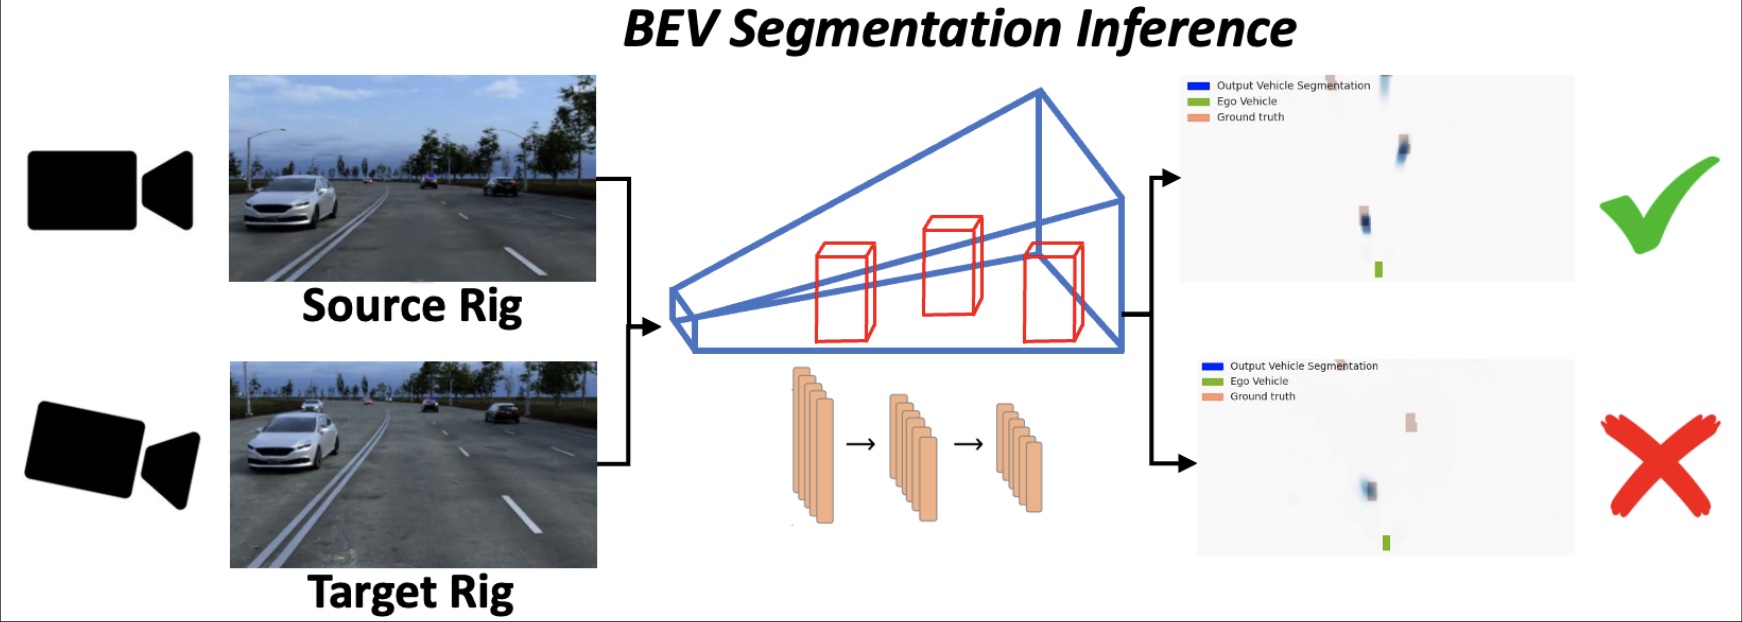
}Towards Viewpoint Robustness in Bird’s Eye View Segmentation Tzofi Klinghoffer, Jonah Philion, Wenzheng Chen, Or Litany, Zan Gojcic, Jungseock Joo, Ramesh Raskar, Sanja Fidler, Jose Alvarez ICCV 2023 @article{tzofi2023view,
title = {Towards Viewpoint Robustness in Bird’s Eye View Segmentation},
author = {Klinghoffer, Tzofi and Philion, Jonah and Chen, Wenzheng and Litany, Or and Gojcic, Zan and Joo, Jungseock and Raskar, Ramesh and Fidler, Sanja and Alvarez, Jose},
year = {2023},
venue = {ICCV 2023},
journal = {ICCV},
image = {./OL_files/viewrobust_teaser.jpg},
paper = {https://arxiv.org/pdf/2309.05192.pdf},
page = {https://nvlabs.github.io/viewpoint-robustness/},
talk = {https://youtu.be/CuJ9gfJpfhc}
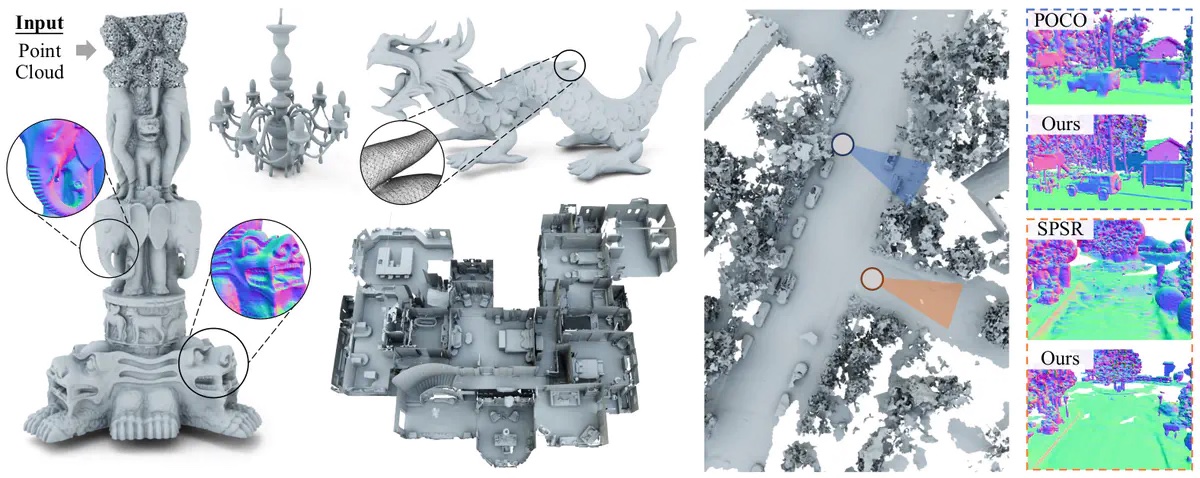
}Neural Kernel Surface Reconstruction Jiahui Huang, Zan Gojcic, Matan Atzmon, Or Litany, Sanja Fidler, Francis Williams CVPR 2023Highlight (top 10 @article{Huang2023nksr,
title = {Neural Kernel Surface Reconstruction},
author = {Huang, Jiahui and Gojcic, Zan and Atzmon, Matan and Litany, Or and Fidler, Sanja and Williams, Francis},
year = {2023},
venue = {CVPR 2023},
journal = {CVPR},
image = {./OL_files/nksr_teaser.jpg},
paper = {https://arxiv.org/pdf/2305.19590.pdf},
page = {https://research.nvidia.com/labs/toronto-ai/NKSR/},
code = {https://github.com/nv-tlabs/nksr},
award = {Highlight (top 10% of accepted papers)}
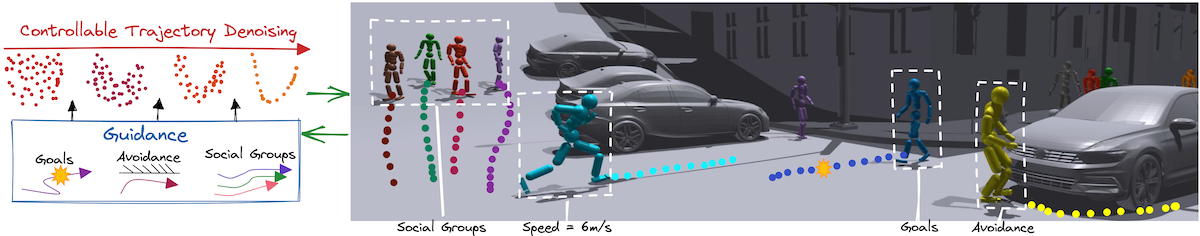
}Trace and Pace: Controllable Pedestrian Animation via Guided Trajectory Diffusion Davis Rempe, Zhengyi Luo, Xue Bin Peng, Ye Yuan, Kris Kitani, Karsten Kreis, Sanja Fidler, Or Litany CVPR 2023 @inproceedings{rempeluo2023tracepace,
title = {Trace and Pace: Controllable Pedestrian Animation via Guided Trajectory Diffusion},
author = {Rempe, Davis and Luo, Zhengyi and Peng, Xue Bin and Yuan, Ye and Kitani, Kris and Kreis, Karsten and Fidler, Sanja and Litany, Or},
year = {2023},
venue = {CVPR 2023},
booktitle = {Conference on Computer Vision and Pattern Recognition (CVPR)},
image = {./OL_files/trace_pace_teaser.png},
paper = {https://nv-tlabs.github.io/trace-pace/docs/trace_and_pace.pdf},
page = {https://nv-tlabs.github.io/trace-pace/}
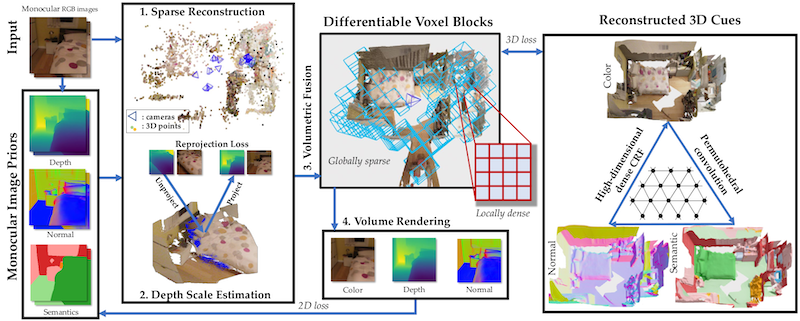
}Fast Monocular Scene Reconstruction with Global-Sparse Local-Dense Grids Wei Dong, Chris Choy, Charles Loop, Yuke Zhu, Or Litany, Anima Anandkumar CVPR 2023 @article{dong2023fast,
title = {Fast Monocular Scene Reconstruction with Global-Sparse Local-Dense Grids},
author = {Dong, Wei and Choy, Chris and Loop, Charles and Zhu, Yuke and Litany, Or and Anandkumar, Anima},
year = {2023},
venue = {CVPR 2023},
journal = {CVPR},
image = {./OL_files/fastmono_teaser.png},
paper = {https://arxiv.org/abs/2305.13220},
page = {https://research.nvidia.com/labs/toronto-ai/publication/2023_cvpr_monocular/},
code = {https://dongwei.info/publication/ash-mono/}
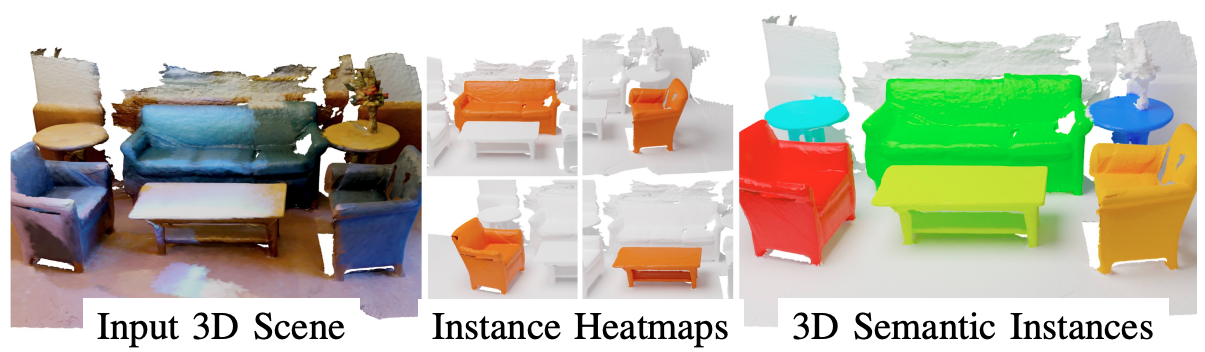
}Mask3D for 3D Semantic Instance Segmentation Jonas Schult, Francis Engelmann, Alexander Hermans, Or Litany, Siyu Tang, Bastian Leibe ICRA 2023 @article{schult2023mask3d,
title = {Mask3D for 3D Semantic Instance Segmentation},
author = {Schult, Jonas and Engelmann, Francis and Hermans, Alexander and Litany, Or and Tang, Siyu and Leibe, Bastian},
year = {2023},
venue = {ICRA 2023},
booktitle = {International Conference on Robotics and Automation (ICRA)},
image = {./OL_files/mask3D.png},
paper = {https://arxiv.org/abs/2210.03105},
page = {https://jonasschult.github.io/Mask3D/},
code = {https://github.com/JonasSchult/Mask3D}
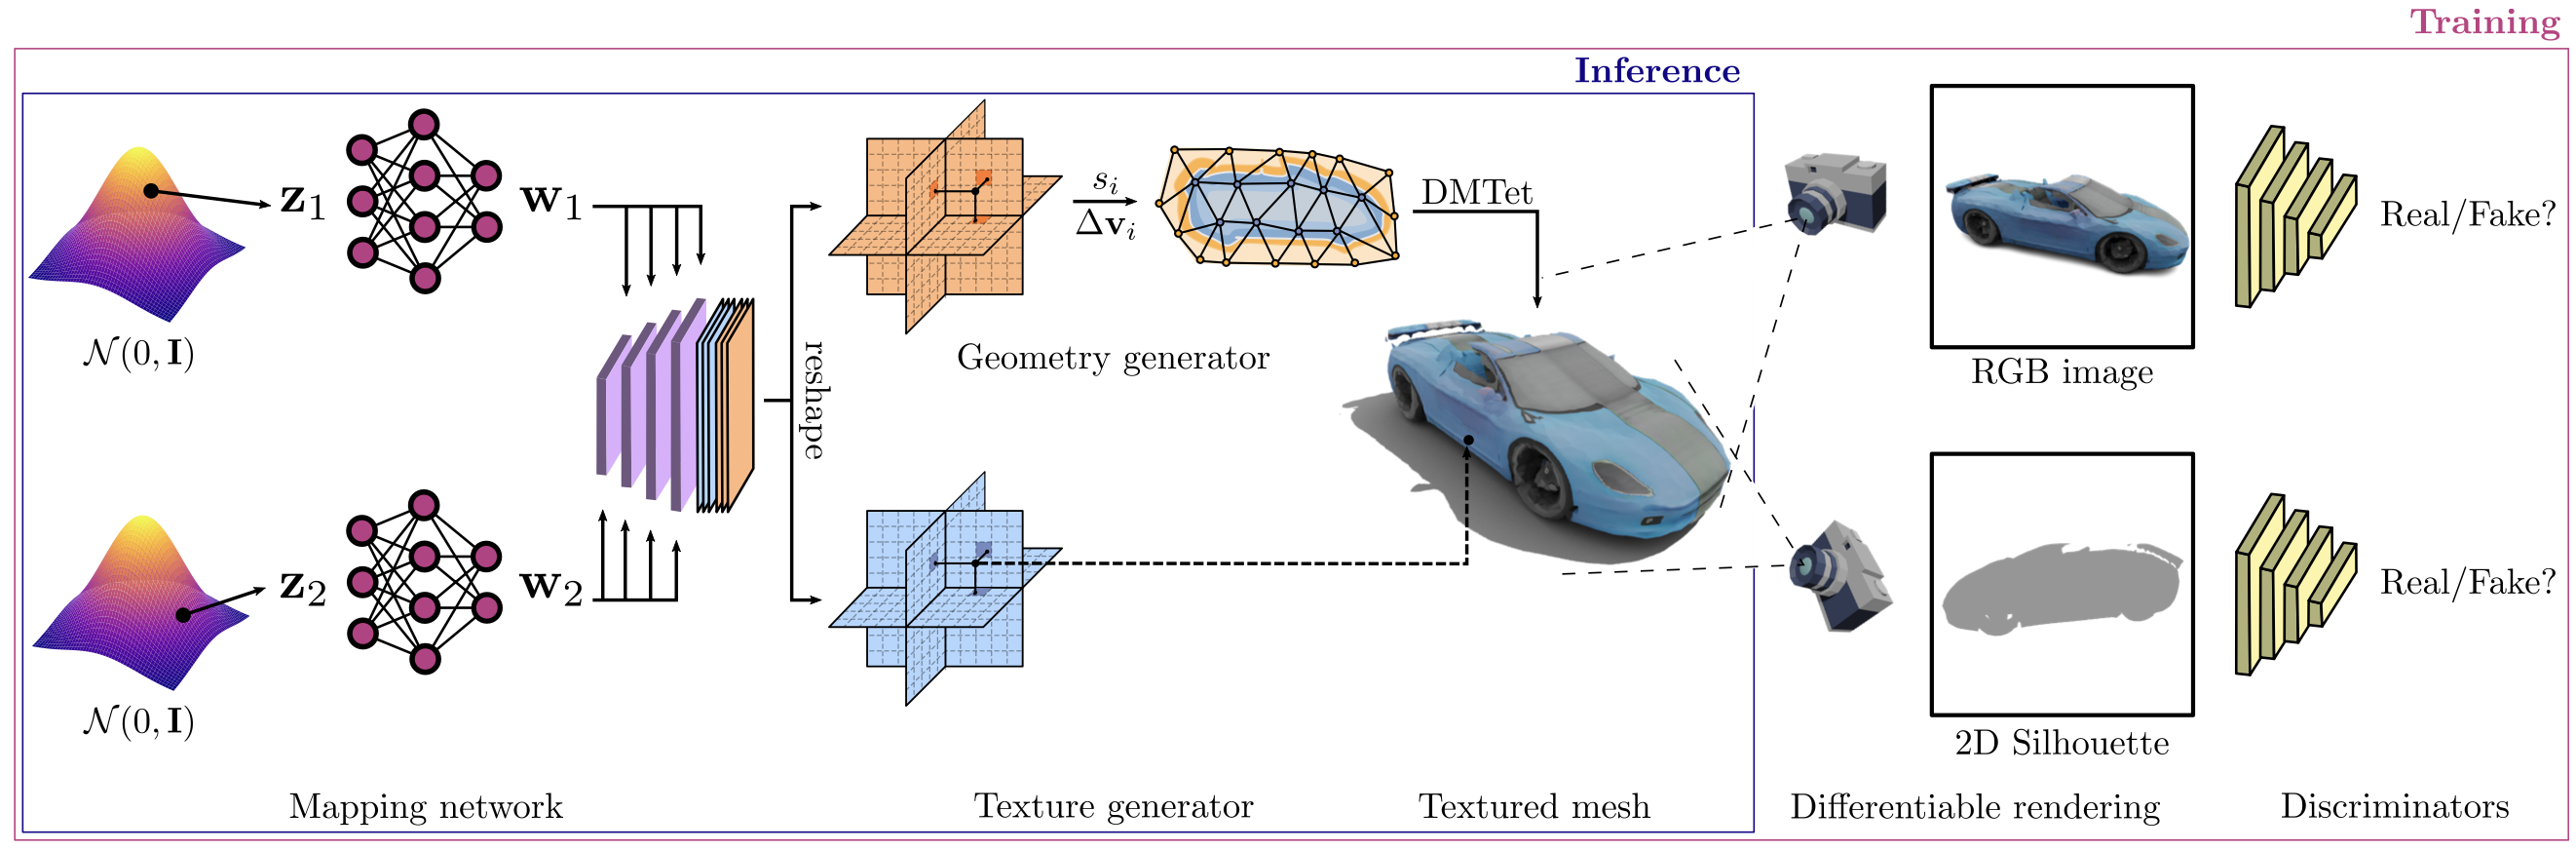
}2022GET3D: A Generative Model of High Quality 3D Textured Shapes Learned from Images Jun Gao, Tianchang Shen, Zian Wang, Wenzheng Chen, Kangxue Yin, Daiqing Li, Or Litany, Zan Gojcic, Sanja Fidler NeurIPS 2022 @inproceedings{gao2022get3d,
title = {{GET3D}: A Generative Model of High Quality {3D} Textured Shapes Learned from Images},
author = {Gao, Jun and Shen, Tianchang and Wang, Zian and Chen, Wenzheng and Yin, Kangxue and Li, Daiqing and Litany, Or and Gojcic, Zan and Fidler, Sanja},
year = {2022},
venue = {NeurIPS 2022},
booktitle = {Advances In Neural Information Processing Systems},
image = {./OL_files/get3D_model.png},
paper = {https://arxiv.org/abs/2209.11163},
page = {https://nv-tlabs.github.io/GET3D/},
code = {https://github.com/nv-tlabs/GET3D}
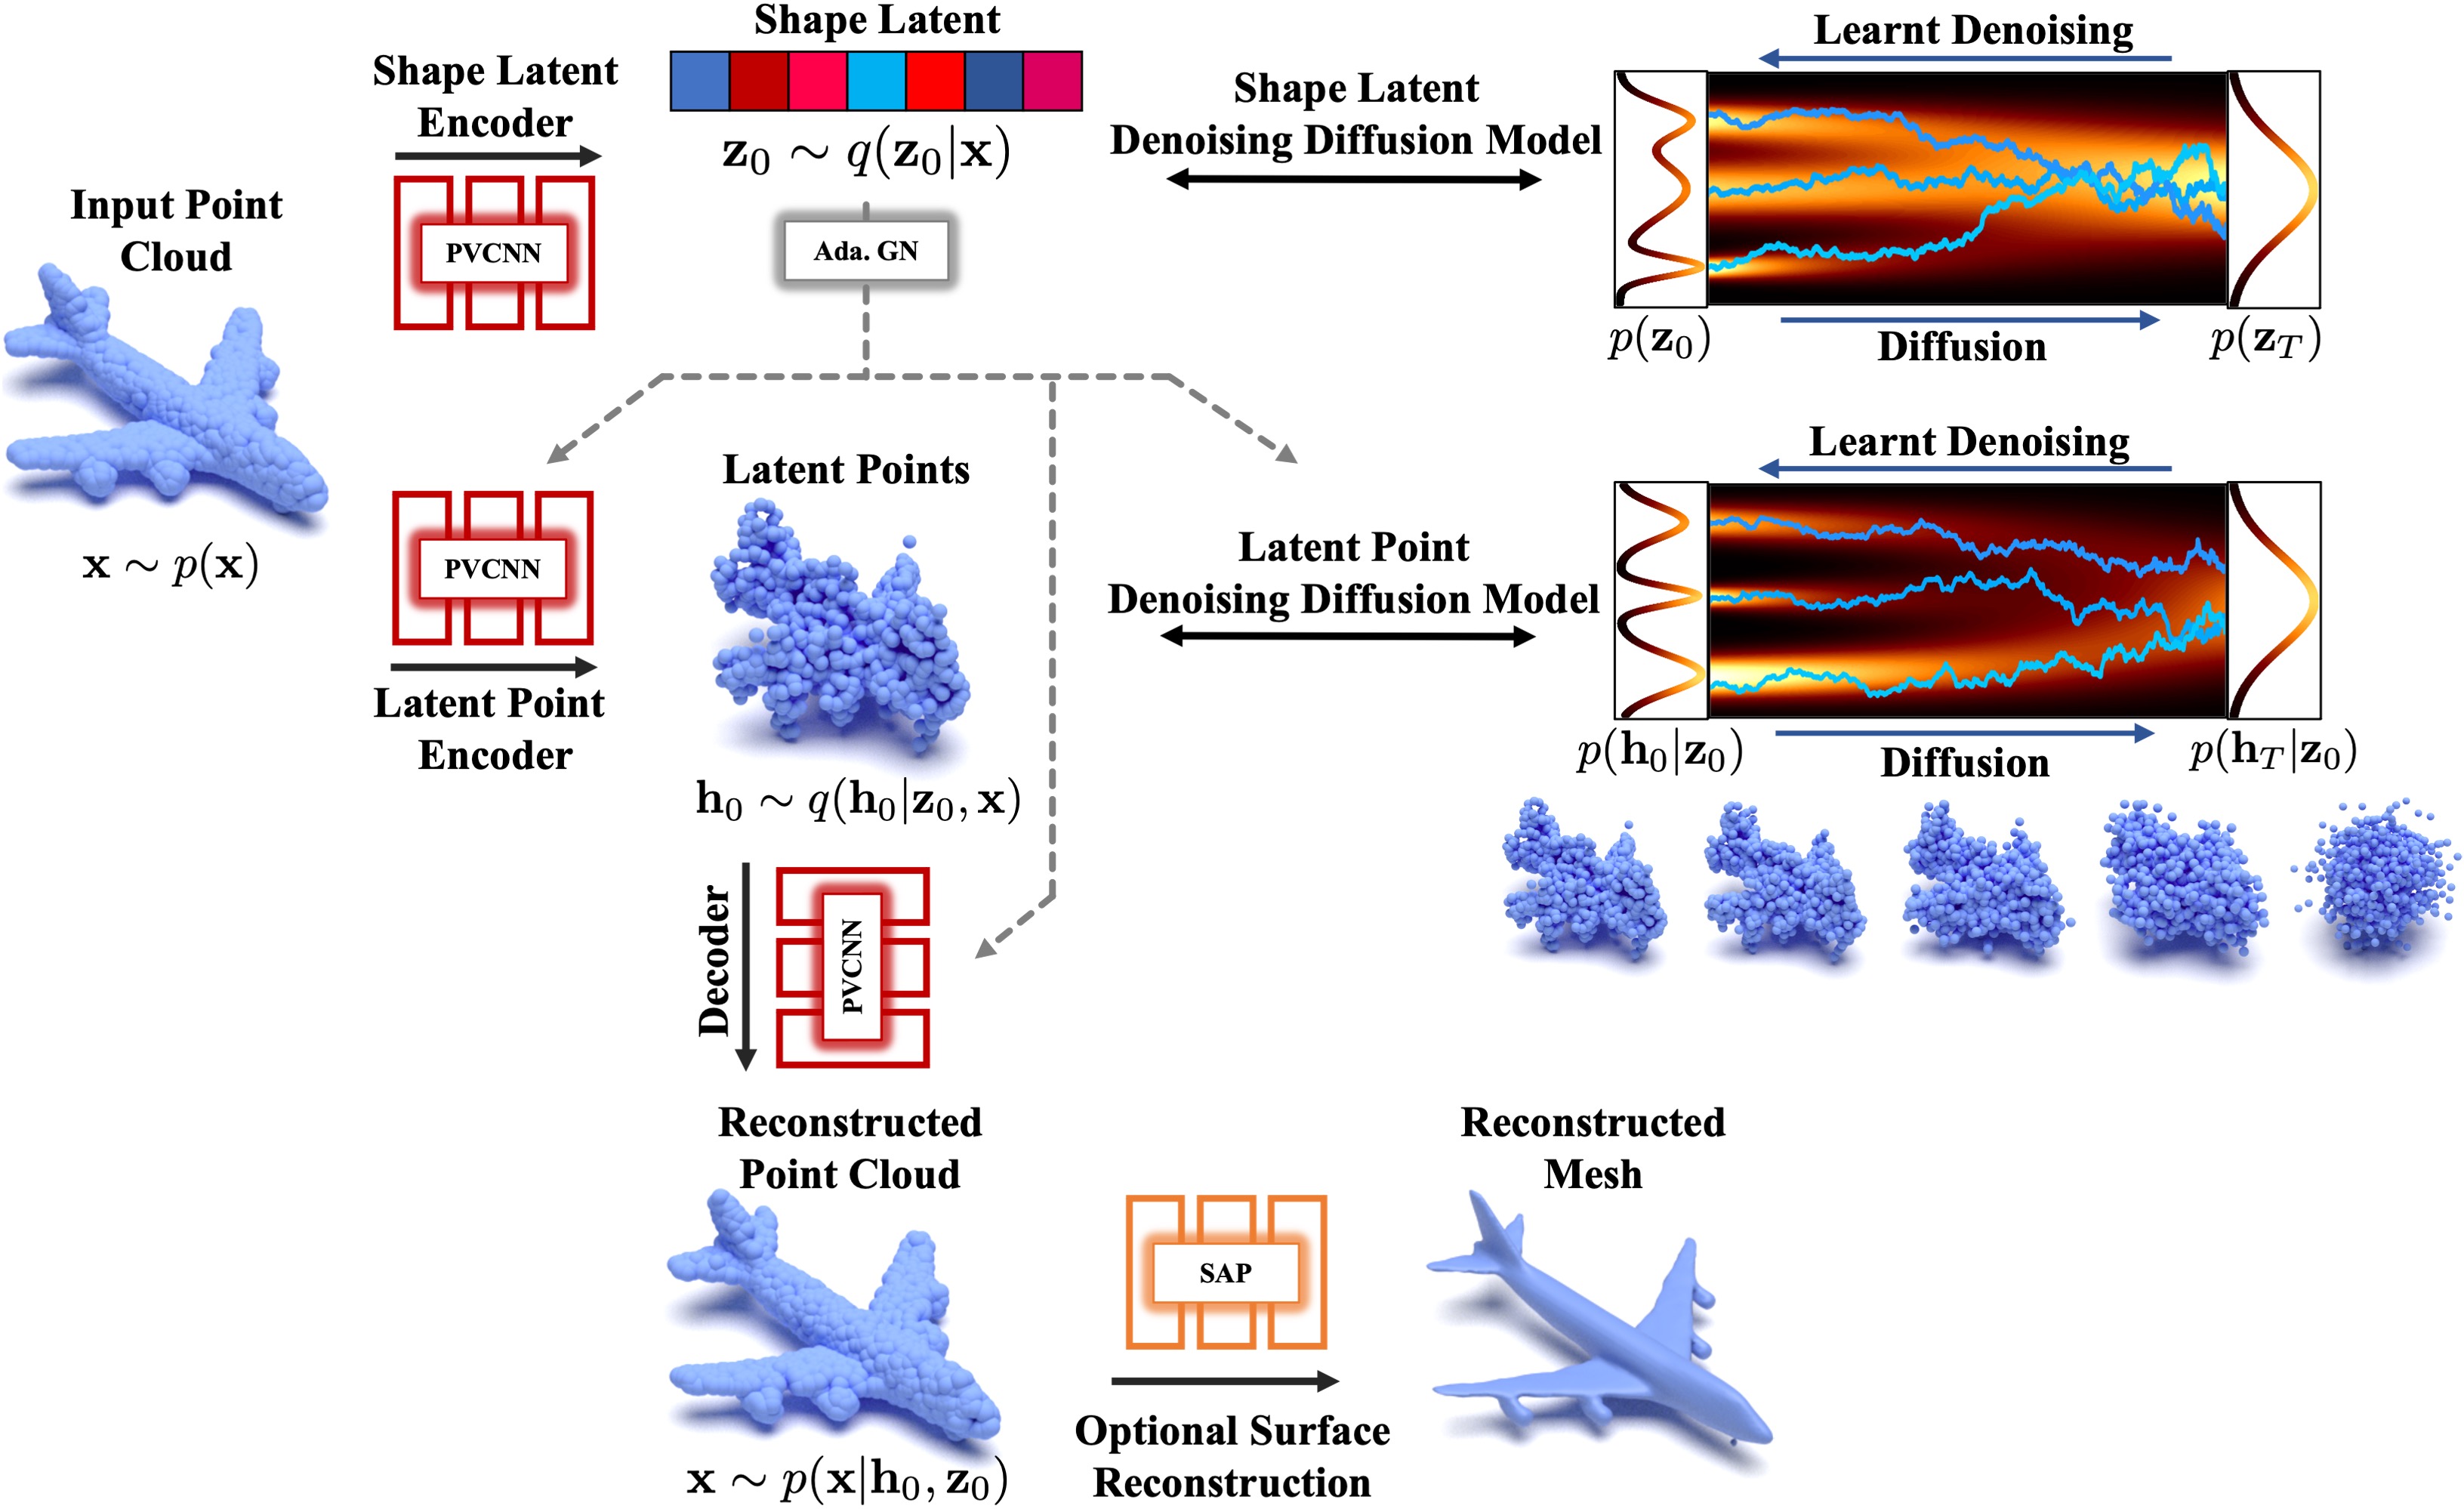
}LION: Latent Point Diffusion Models for 3D Shape Generation Xiaohui Zeng, Arash Vahdat, Francis Williams, Zan Gojcic, Or Litany, Sanja Fidler, Karsten Kreis NeurIPS 2022 @article{zeng2022lion,
title = {LION: Latent Point Diffusion Models for 3D Shape Generation},
author = {Zeng, Xiaohui and Vahdat, Arash and Williams, Francis and Gojcic, Zan and Litany, Or and Fidler, Sanja and Kreis, Karsten},
year = {2022},
venue = {NeurIPS 2022},
journal = {Advances in Neural Information Processing Systems (NeurIPS)},
image = {./OL_files/lion_pipeline.jpeg},
paper = {https://arxiv.org/abs/2210.06978},
page = {https://nv-tlabs.github.io/LION/},
code = {https://github.com/nv-tlabs/LION}
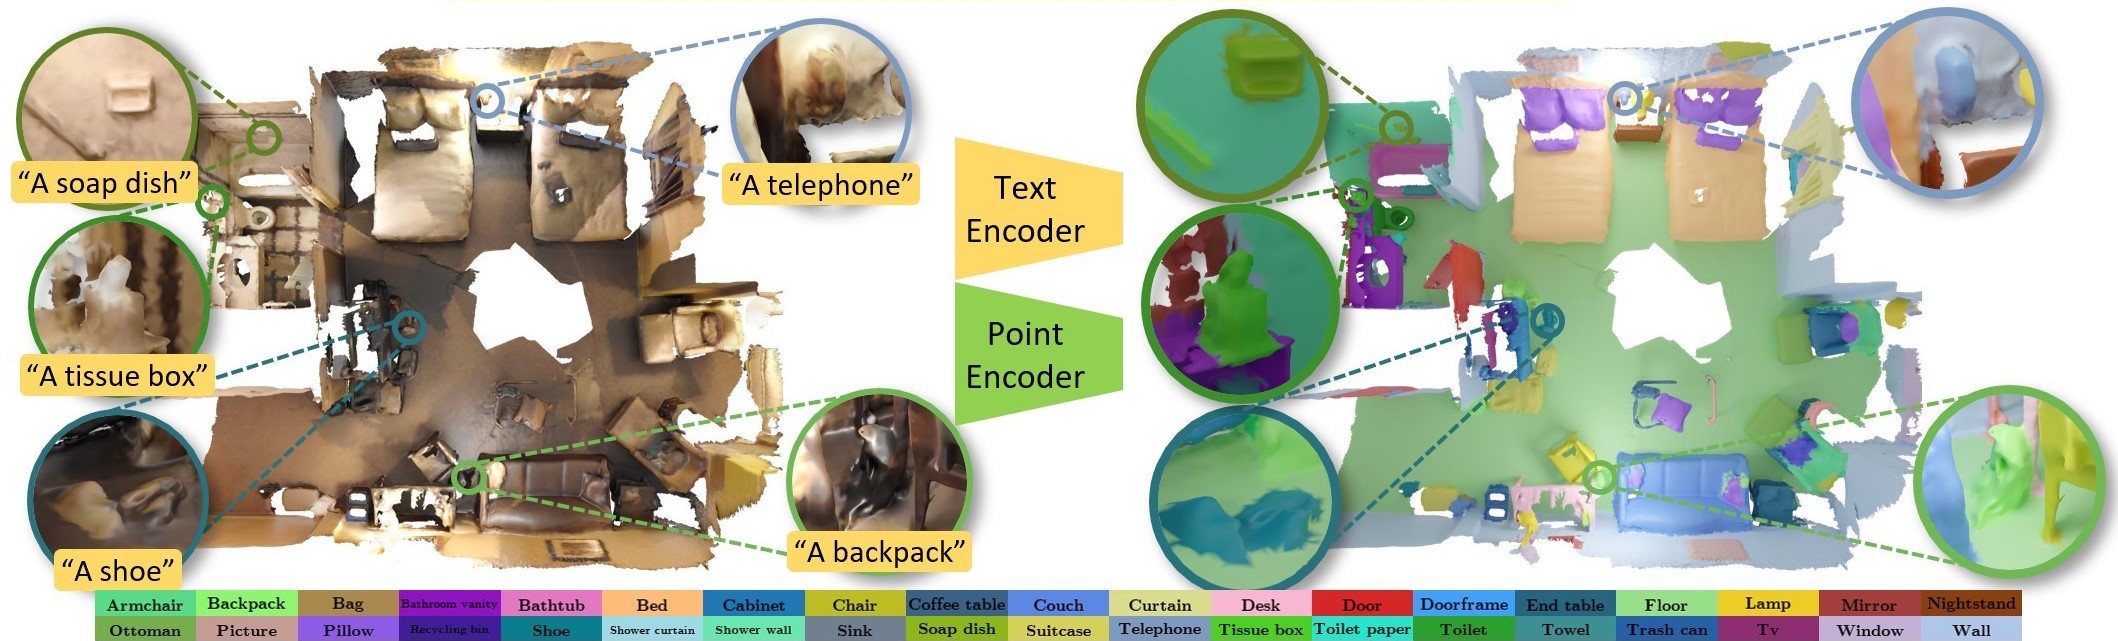
}Language-Grounded Indoor 3D Semantic Segmentation in the Wild David Rozenberszki, Or Litany, Angela Dai ECCV 2022 @article{rozenberszki2022language,
title = {Language-Grounded Indoor 3D Semantic Segmentation in the Wild},
author = {Rozenberszki, David and Litany, Or and Dai, Angela},
year = {2022},
venue = {ECCV 2022},
journal = {ECCV},
image = {./OL_files/scannet200_teaser.jpeg},
paper = {https://arxiv.org/abs/2204.07761},
page = {https://rozdavid.github.io/scannet200},
code = {https://github.com/RozDavid/LanguageGroundedSemseg}
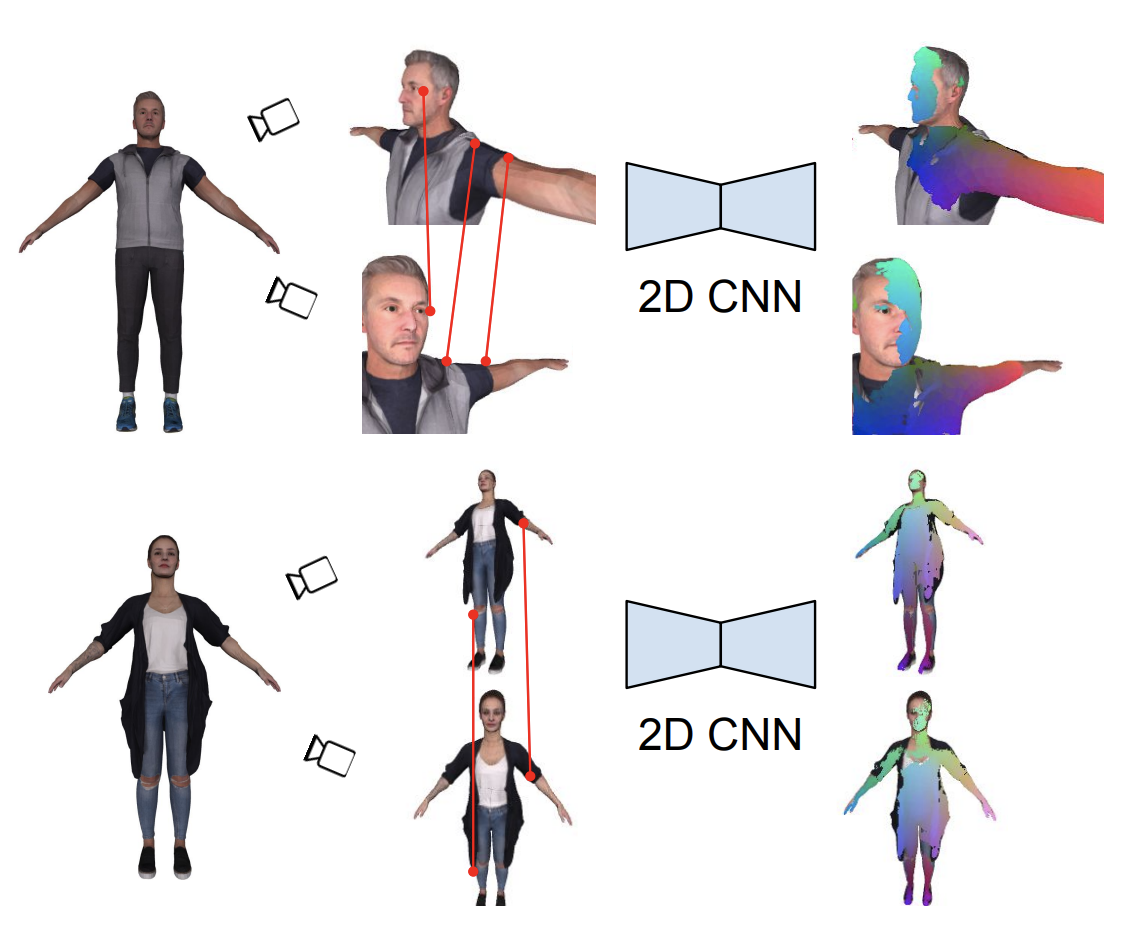
}MvDeCor: Multi-view Dense Correspondence Learning for Fine-grained 3D Segmentation Gopal Sharma, Kangxue Yin, Subhransu Maji, Evangelos Kalogerakis, Or Litany, Sanja Fidler ECCV 2022 @article{sharma2022mvdecor,
title = {MvDeCor: Multi-view Dense Correspondence Learning for Fine-grained 3D Segmentation},
author = {Sharma, Gopal and Yin, Kangxue and Maji, Subhransu and Kalogerakis, Evangelos and Litany, Or and Fidler, Sanja},
year = {2022},
venue = {ECCV 2022},
journal = {ECCV},
image = {./OL_files/mvdecor_teaser.png},
paper = {https://arxiv.org/abs/2208.08580},
page = {https://nv-tlabs.github.io/MvDeCor/},
code = {https://github.com/nv-tlabs/MvDeCor}
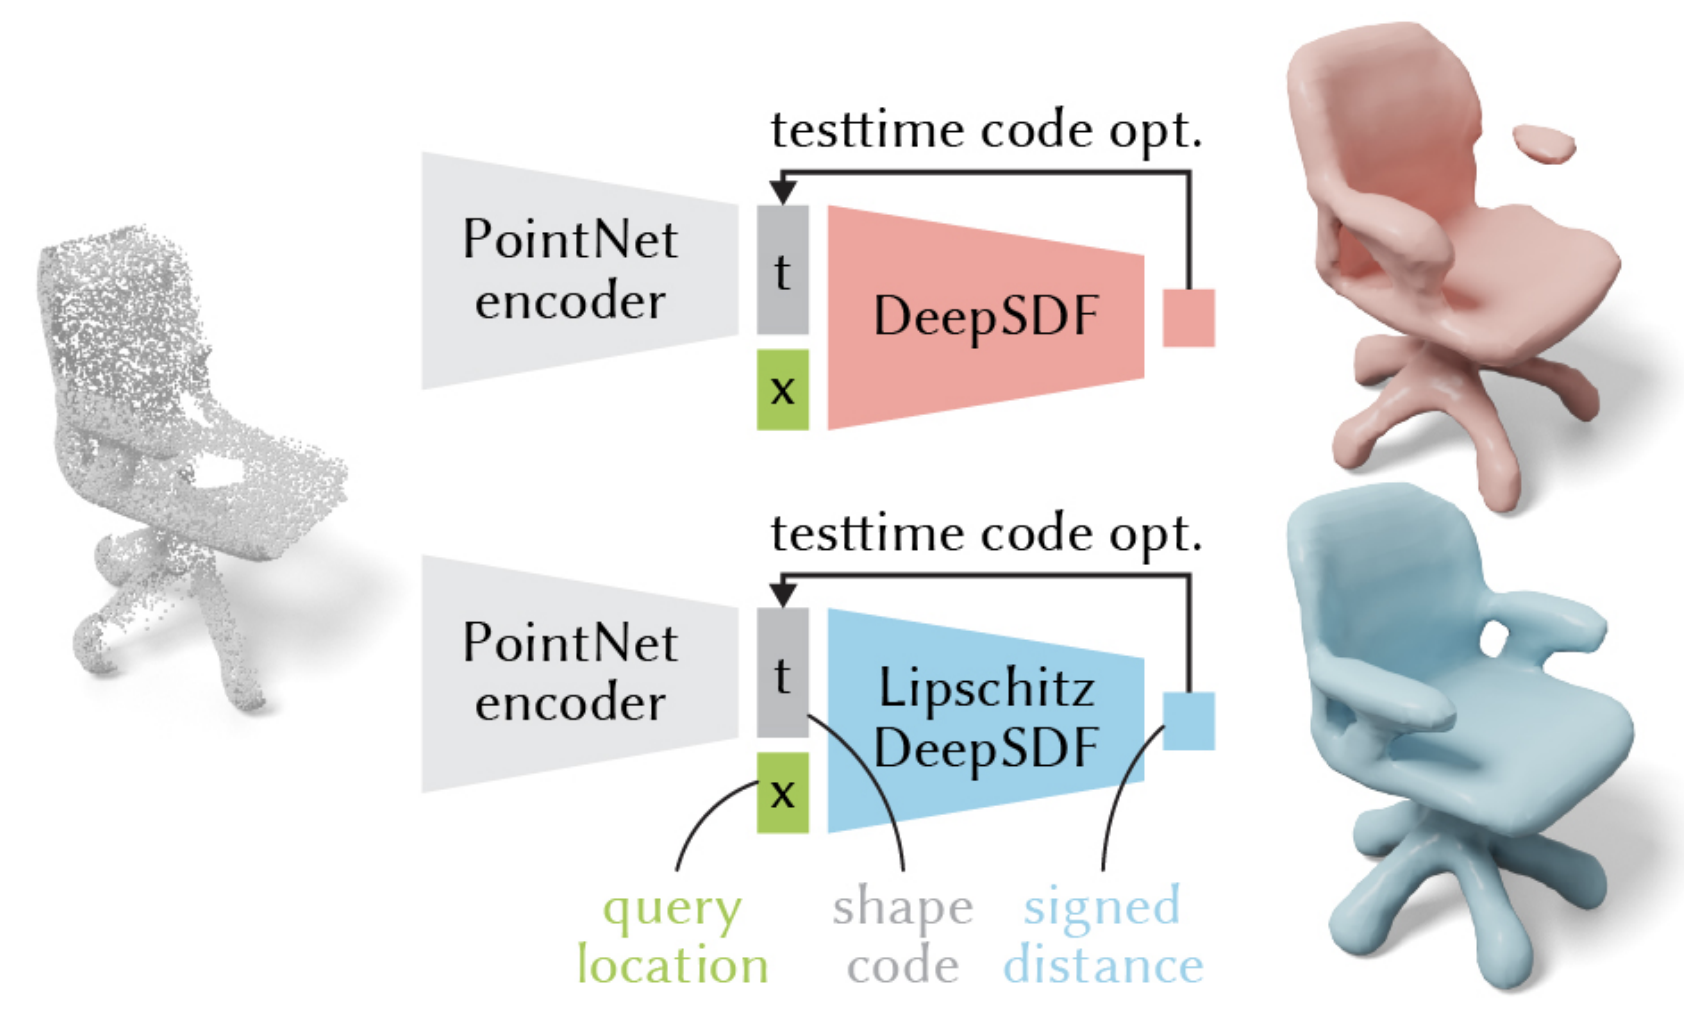
}Learning Smooth Neural Functions via Lipschitz Regularization Hsueh-Ti Derek Liu, Francis Williams, Alec Jacobson, Sanja Fidler, Or Litany SIGGRAPH 2022 @inproceedings{liu2022learning,
title = {Learning Smooth Neural Functions via {Lipschitz} Regularization},
author = {Liu, Hsueh-Ti Derek and Williams, Francis and Jacobson, Alec and Fidler, Sanja and Litany, Or},
year = {2022},
venue = {SIGGRAPH 2022},
booktitle = {ACM SIGGRAPH 2022 Conference Proceedings},
pages = {1--13},
image = {./OL_files/lipschitz_teaser.png},
paper = {https://arxiv.org/abs/2202.08345},
page = {https://nv-tlabs.github.io/lip-mlp/},
code = {https://github.com/ml-for-gp/jaxgptoolbox/tree/main/demos/lipschitz_mlp}
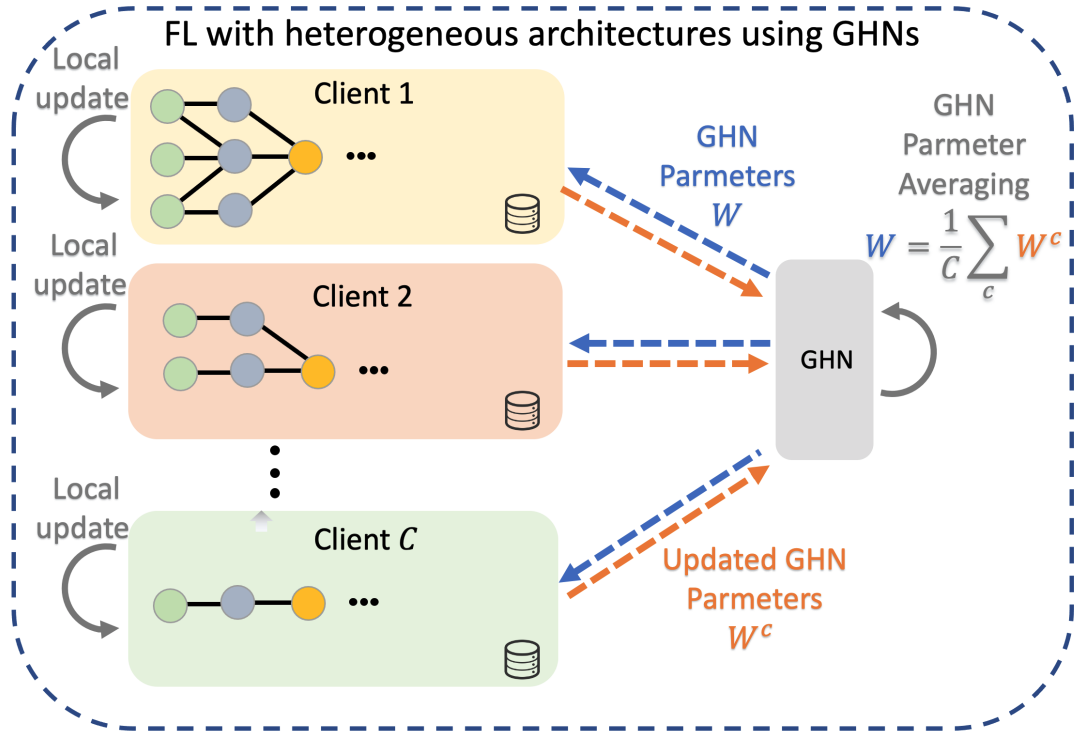
}Federated Learning with Heterogeneous Architectures using Graph HyperNetworks Or Litany, Haggai Maron, David Acuna, Jan Kautz, Gal Chechik, Sanja Fidler Preprint @article{litany2022federated,
title = {Federated Learning with Heterogeneous Architectures using Graph {HyperNetworks}},
author = {Litany, Or and Maron, Haggai and Acuna, David and Kautz, Jan and Chechik, Gal and Fidler, Sanja},
year = {2022},
venue = {Preprint},
journal = {arXiv preprint arXiv:2201.08459},
image = {./OL_files/heterofl.png},
paper = {https://arxiv.org/abs/2201.08459}
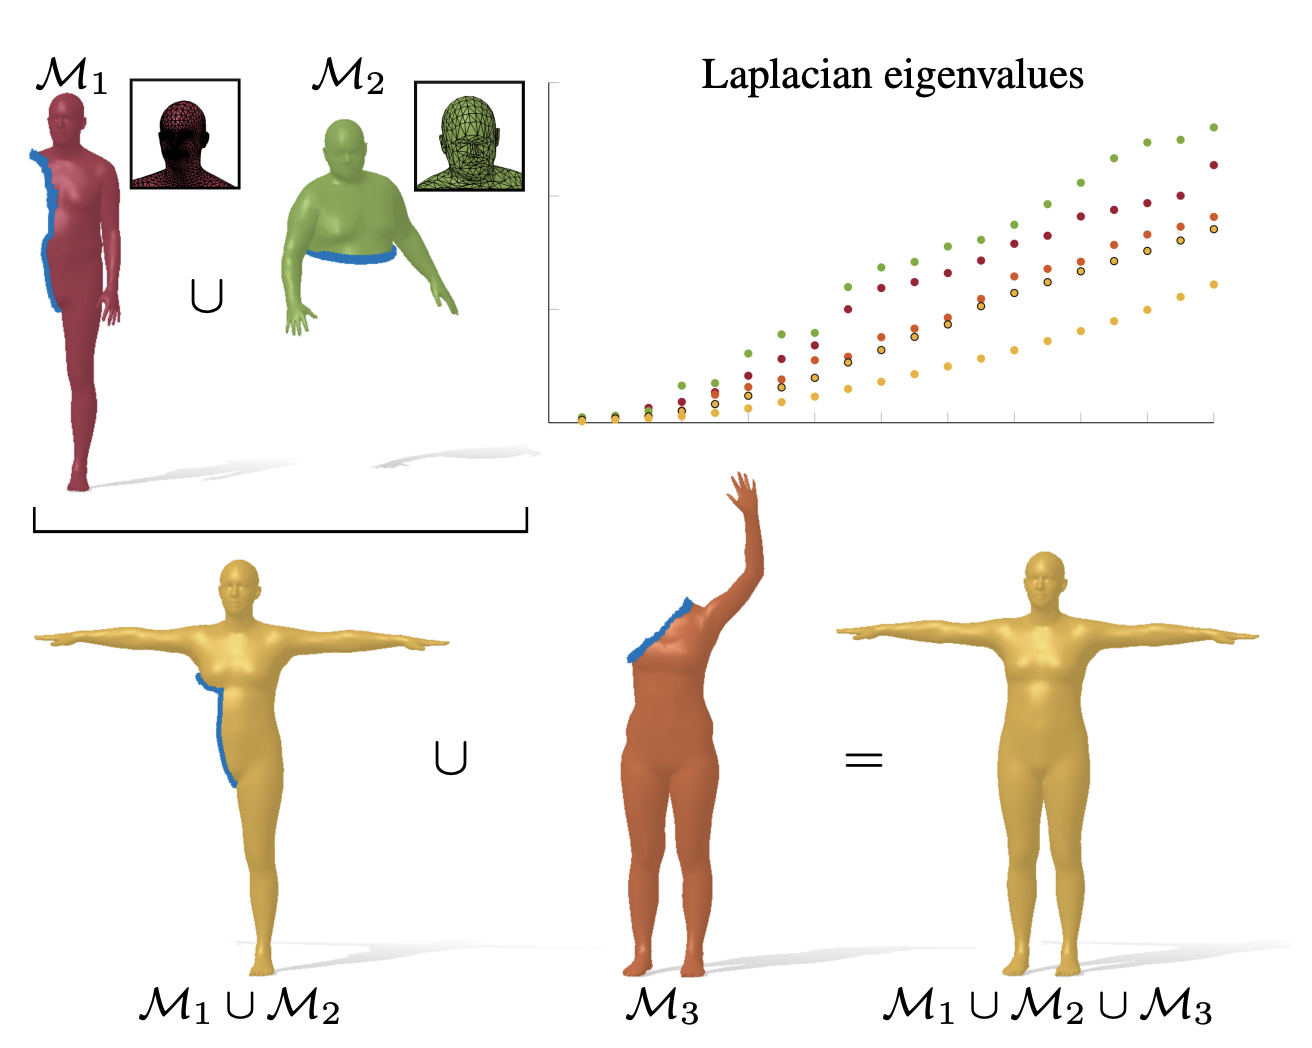
}Learning Spectral Unions of Partial Deformable 3D Shapes Luca Moschella, Simone Melzi, Luca Cosmo, Filippo Maggioli, Or Litany, Maks Ovsjanikov, Leonidas Guibas, Emanuele Rodolà Eurographics 2022 @inproceedings{moschella2022learning,
title = {Learning Spectral Unions of Partial Deformable 3D Shapes},
author = {Moschella, Luca and Melzi, Simone and Cosmo, Luca and Maggioli, Filippo and Litany, Or and Ovsjanikov, Maks and Guibas, Leonidas and Rodol{\`a}, Emanuele},
year = {2022},
venue = {Eurographics 2022},
booktitle = {Computer Graphics Forum},
volume = {41},
pages = {407--417},
image = {./OL_files/spectral_unions_teaser.png},
paper = {https://arxiv.org/abs/2104.00514},
number = {2}
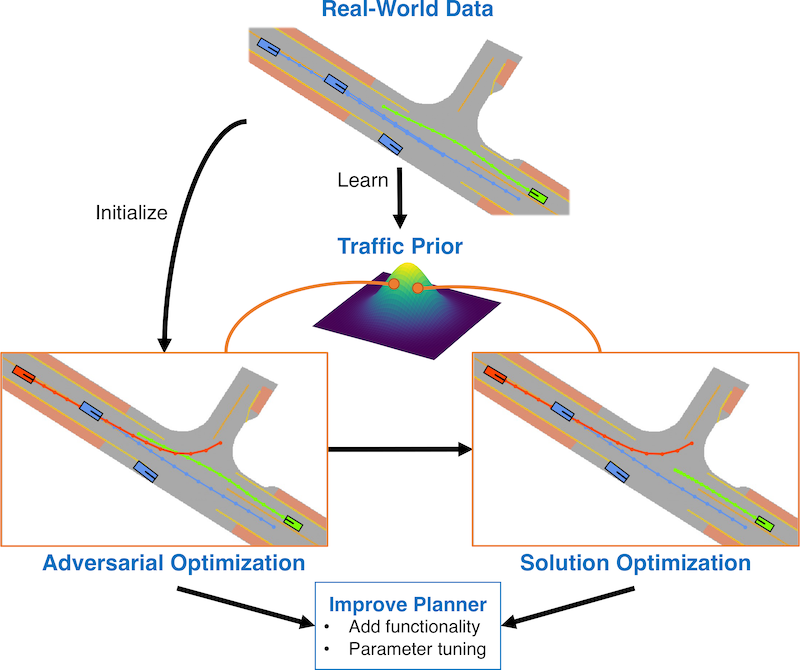
}Generating Useful Accident-Prone Driving Scenarios via a Learned Traffic Prior Davis Rempe, Jonah Philion, Leonidas J. Guibas, Sanja Fidler, Or Litany CVPR 2022 @article{rempe2022generating,
title = {Generating Useful Accident-Prone Driving Scenarios via a Learned Traffic Prior},
author = {Rempe, Davis and Philion, Jonah and Guibas, Leonidas J. and Fidler, Sanja and Litany, Or},
year = {2022},
venue = {CVPR 2022},
journal = {CVPR},
image = {./OL_files/strive_teaser.png},
paper = {https://arxiv.org/abs/2112.05077},
page = {https://nv-tlabs.github.io/STRIVE/},
code = {https://github.com/nv-tlabs/STRIVE}
}Neural Fields as Learnable Kernels for 3D Reconstruction Francis Williams*, Zan Gojcic*, Sameh Khamis, Denis Zorin, Joan Bruna, Sanja Fidler, Or Litany CVPR 2022 @article{williams2021neural,
title = {Neural Fields as Learnable Kernels for 3D Reconstruction},
author = {Williams, Francis and Gojcic, Zan and Khamis, Sameh and Zorin, Denis and Bruna, Joan and Fidler, Sanja and Litany, Or},
equalcontrib = {1, 2},
year = {2022},
venue = {CVPR 2022},
journal = {CVPR},
image = {./OL_files/NKF_teaser.png},
paper = {https://arxiv.org/abs/2111.13674},
page = {https://nv-tlabs.github.io/nkf/}
}Neural Fields in Visual Computing and Beyond Yiheng Xie, Towaki Takikawa, Shunsuke Saito, Or Litany, Shiqin Yan, Numair Khan, Federico Tombari, James Tompkin, Vincent Sitzmann, Srinath Sridhar Eurographics 2022 STAR @inproceedings{xie2022neural,
title = {Neural Fields in Visual Computing and Beyond},
author = {Xie, Yiheng and Takikawa, Towaki and Saito, Shunsuke and Litany, Or and Yan, Shiqin and Khan, Numair and Tombari, Federico and Tompkin, James and Sitzmann, Vincent and Sridhar, Srinath},
year = {2022},
venue = {Eurographics 2022 STAR},
booktitle = {Computer Graphics Forum},
volume = {41},
pages = {641--676},
image = {./OL_files/neural_fields_review_teaser.png},
paper = {https://arxiv.org/abs/2111.11426},
page = {https://neuralfields.cs.brown.edu/},
number = {2}
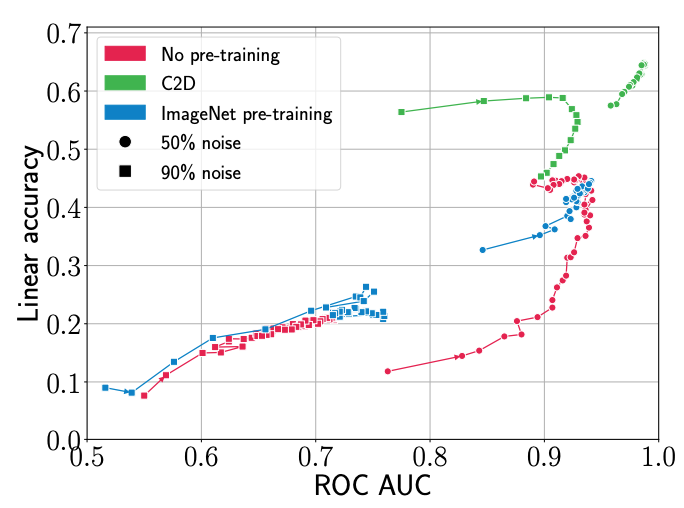
}Contrast to Divide: Self-Supervised Pre-Training for Learning with Noisy Labels Evgenii Zheltonozhskii, Chaim Baskin, Avi Mendelson, Alex M. Bronstein, Or Litany WACV 2022 @article{zheltonozhskii2021contrast,
title = {Contrast to Divide: Self-Supervised Pre-Training for Learning with Noisy Labels},
author = {Zheltonozhskii, Evgenii and Baskin, Chaim and Mendelson, Avi and Bronstein, Alex M. and Litany, Or},
year = {2021},
venue = {WACV 2022},
journal = {WACV 2022},
image = {./OL_files/C2D_teaser.png},
paper = {https://arxiv.org/abs/2103.13646}
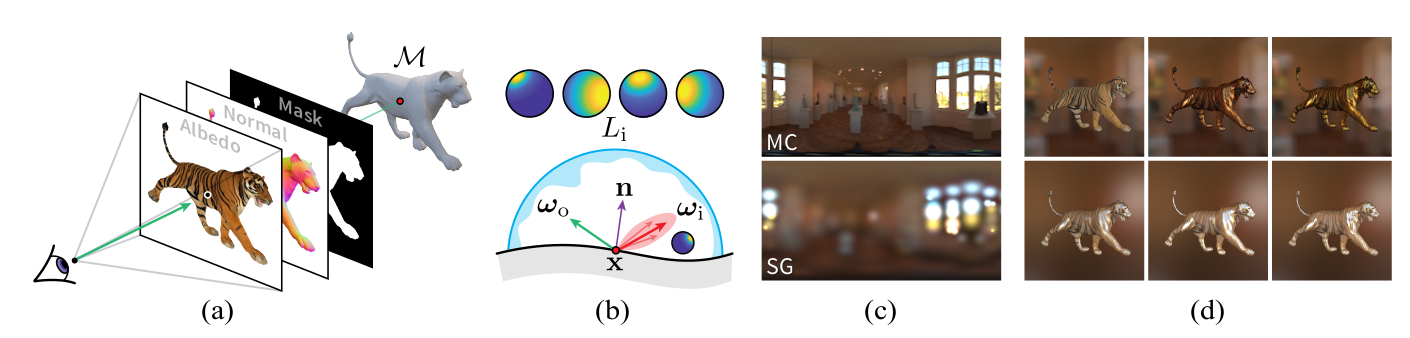
}2021DIB-R++: Learning to Predict Lighting and Material with a Hybrid Differentiable Renderer Wenzheng Chen, Joey Litalien, Jun Gao, Zian Wang, Clement Fuji Tsang, Sameh Khamis, Or Litany, Sanja Fidler NeurIPS 2021 @article{chen2021dib,
title = {DIB-R++: Learning to Predict Lighting and Material with a Hybrid Differentiable Renderer},
author = {Chen, Wenzheng and Litalien, Joey and Gao, Jun and Wang, Zian and Tsang, Clement Fuji and Khamis, Sameh and Litany, Or and Fidler, Sanja},
year = {2021},
venue = {NeurIPS 2021},
journal = {Advances in Neural Information Processing Systems (NeurIPS)},
image = {./OL_files/dibrplus_teaser.png},
paper = {https://arxiv.org/abs/2111.00140},
page = {https://nv-tlabs.github.io/DIBRPlus/}
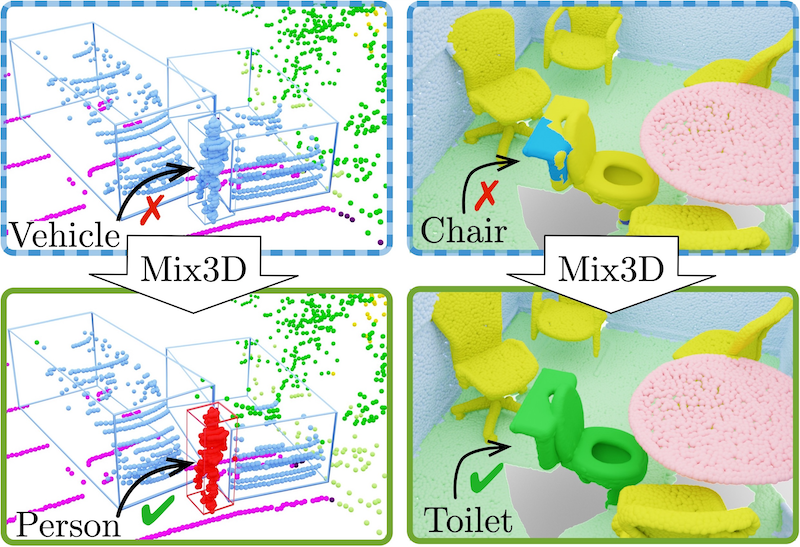
}Mix3D: Out-of-Context Data Augmentation for 3D Scenes Alexey Nekrasov, Jonas Schult, Or Litany, Bastian Leibe, Francis Engelmann 3DV 2021 @article{nekrasov2021mix3d,
title = {Mix3D: Out-of-Context Data Augmentation for 3D Scenes},
author = {Nekrasov, Alexey and Schult, Jonas and Litany, Or and Leibe, Bastian and Engelmann, Francis},
year = {2021},
venue = {3DV 2021},
journal = {3DV 2021},
image = {./OL_files/mix3d_teaser.png},
paper = {https://arxiv.org/abs/2110.02210},
page = {https://kumuji.github.io/mix3d/}
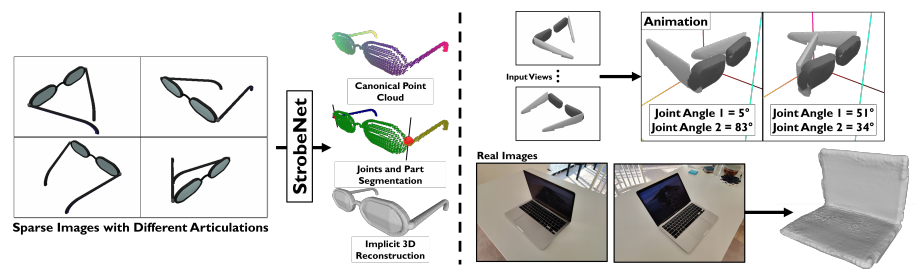
}StrobeNet: Category-Level Multiview Reconstruction of Articulated Objects Ge Zhang, Or Litany, Srinath Sridhar, Leonidas Guibas Preprint @article{zhang2021strobenet,
title = {{StrobeNet}: Category-Level Multiview Reconstruction of Articulated Objects},
author = {Zhang, Ge and Litany, Or and Sridhar, Srinath and Guibas, Leonidas},
year = {2021},
venue = {Preprint},
journal = {arXiv preprint arXiv:2105.08016},
image = {./OL_files/strobenet.png},
paper = {https://arxiv.org/abs/2105.08016},
page = {https://dzhange.github.io/StrobeNet/}
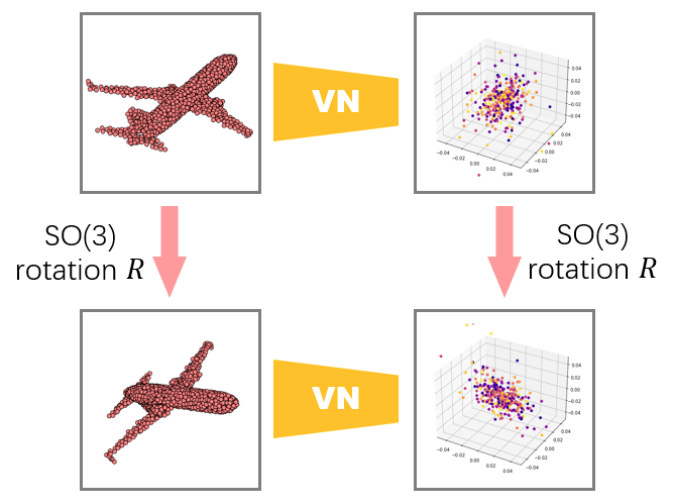
}Vector Neurons: A General Framework for SO(3)-Equivariant Networks Congyue Deng, Or Litany, Yueqi Duan, Adrien Poulenard, Andrea Tagliasacchi, Leonidas Guibas ICCV 2021 @article{deng2021vector,
title = {Vector Neurons: A General Framework for {SO(3)}-Equivariant Networks},
author = {Deng, Congyue and Litany, Or and Duan, Yueqi and Poulenard, Adrien and Tagliasacchi, Andrea and Guibas, Leonidas},
year = {2021},
venue = {ICCV 2021},
journal = {ICCV 2021},
image = {./OL_files/VNN_teaser.png},
paper = {https://arxiv.org/abs/2104.12229}
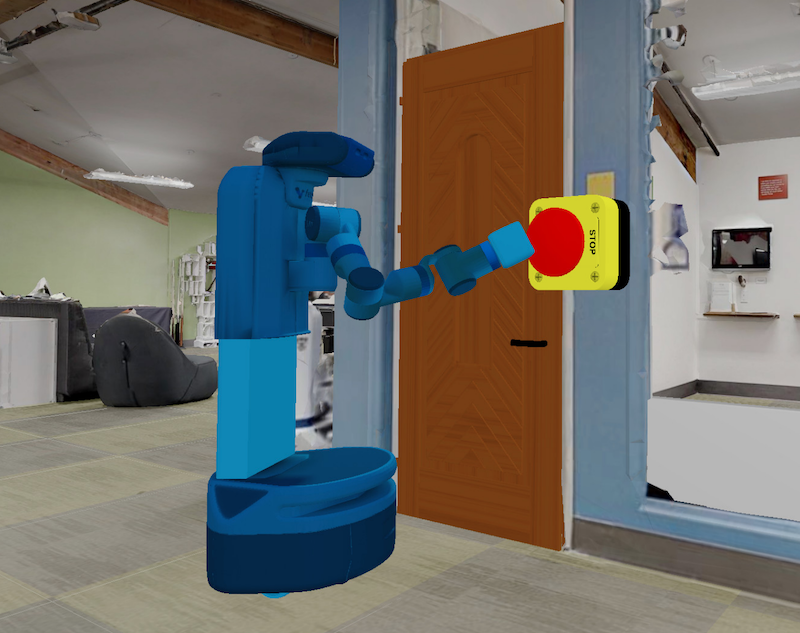
}ReLMoGen: Integrating Motion Generation in Reinforcement Learning for Mobile Manipulation Fei Xia, Chengshu Li, Roberto Martı́n-Martı́n, Or Litany, Alexander Toshev, Silvio Savarese ICRA 2021 @inproceedings{xia2021relmogen,
title = {{ReLMoGen}: Integrating Motion Generation in Reinforcement Learning for Mobile Manipulation},
author = {Xia, Fei and Li, Chengshu and Mart{\'\i}n-Mart{\'\i}n, Roberto and Litany, Or and Toshev, Alexander and Savarese, Silvio},
year = {2021},
venue = {ICRA 2021},
booktitle = {2021 IEEE International Conference on Robotics and Automation (ICRA)},
pages = {4583--4590},
image = {./OL_files/relmogen_teaser.png},
paper = {https://arxiv.org/abs/2008.07792},
talk = {https://youtu.be/mTaJ9xQMiD0?t=2083},
organization = {IEEE}
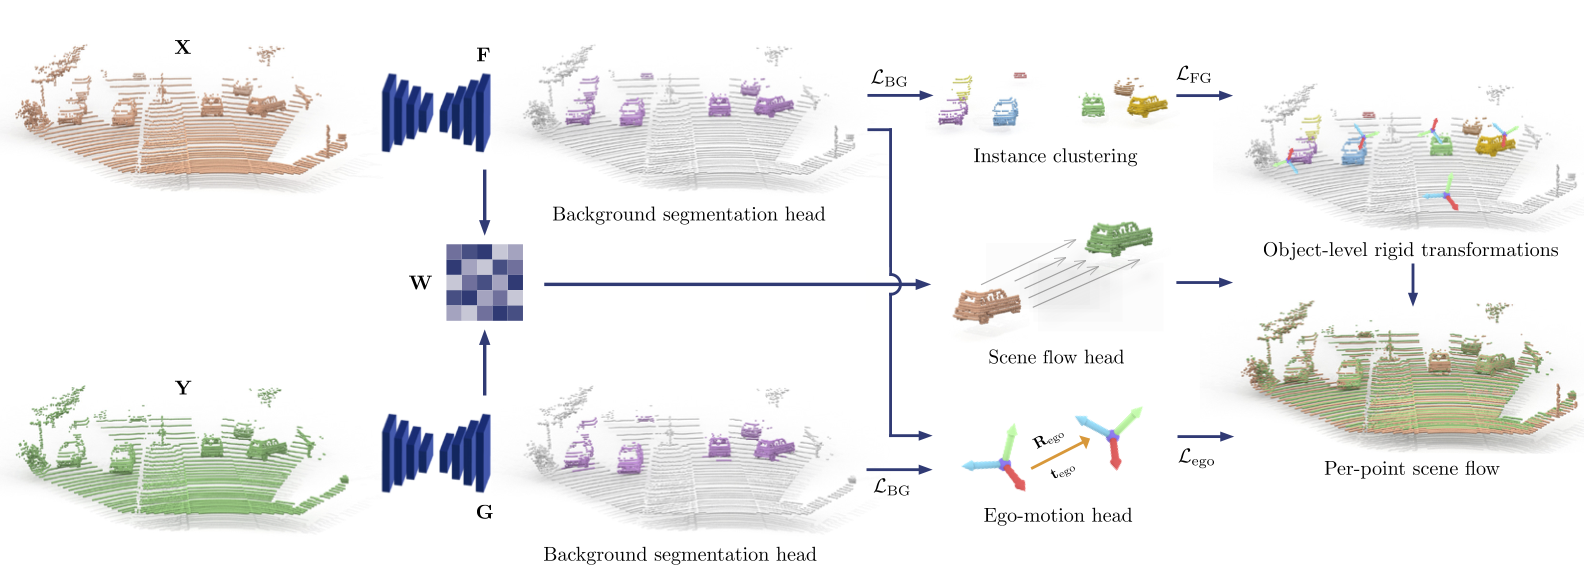
}Weakly Supervised Learning of Rigid 3D Scene Flow Zan Gojcic, Or Litany, Andreas Wieser, Leonidas J. Guibas, Tolga Birdal CVPR 2021 @article{gojcic2021weakly,
title = {Weakly Supervised Learning of Rigid 3D Scene Flow},
author = {Gojcic, Zan and Litany, Or and Wieser, Andreas and Guibas, Leonidas J. and Birdal, Tolga},
year = {2021},
venue = {CVPR 2021},
journal = {CVPR 2021},
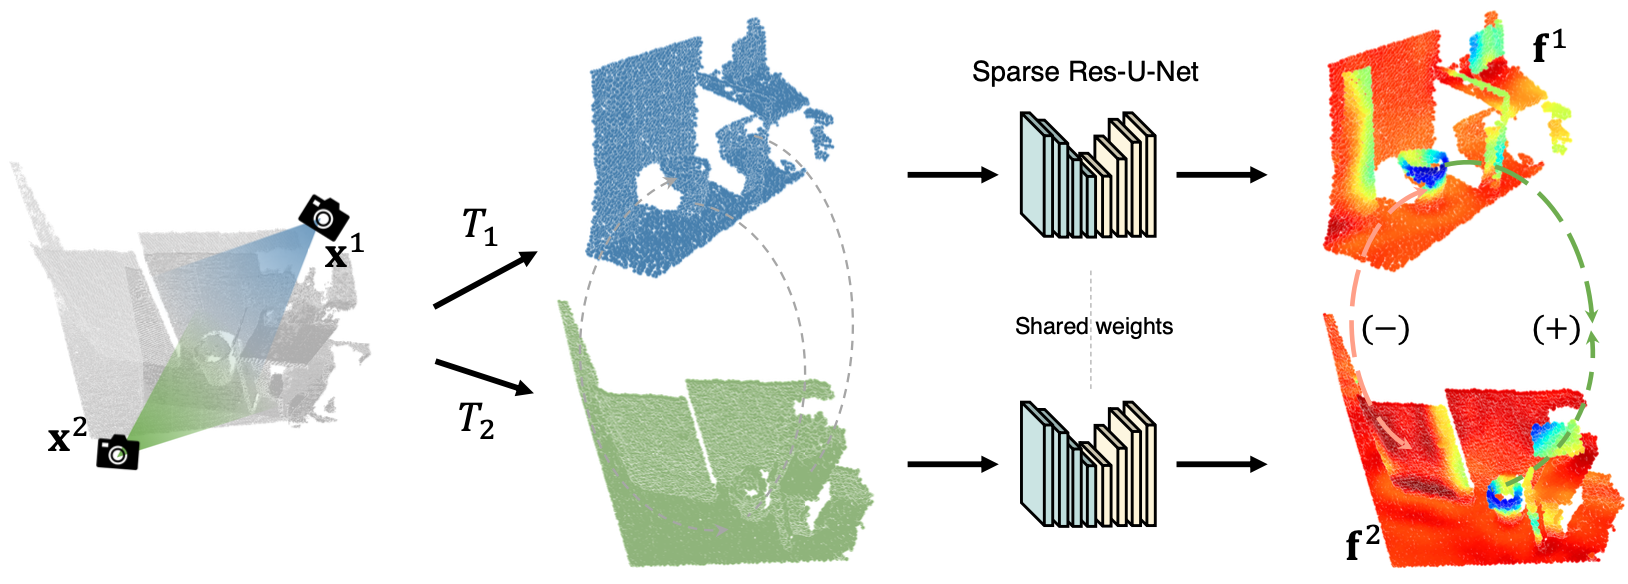
image = {./OL_files/weakly_cvpr21.png},
paper = {https://arxiv.org/abs/2102.08945},
page = {https://3dsceneflow.github.io/}
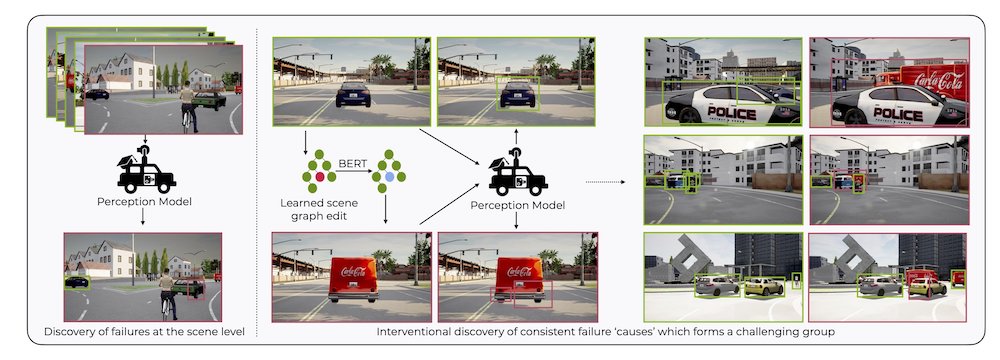
}Causal BERT: Improving Object Detection by Searching for Challenging Groups Cinjon Resnick, Or Litany, Amlan Kar, Karsten Kreis, James Lucas, Kyunghyun Cho, Sanja Fidler ICCV workshop @inproceedings{resnick2021causal,
title = {Causal {BERT}: Improving Object Detection by Searching for Challenging Groups},
author = {Resnick, Cinjon and Litany, Or and Kar, Amlan and Kreis, Karsten and Lucas, James and Cho, Kyunghyun and Fidler, Sanja},
year = {2021},
venue = {ICCV workshop},
booktitle = {Proceedings of the IEEE/CVF International Conference on Computer Vision},
pages = {2972--2981},
image = {./OL_files/causal_scene_bert.jpeg},
paper = {https://arxiv.org/abs/2202.03651}
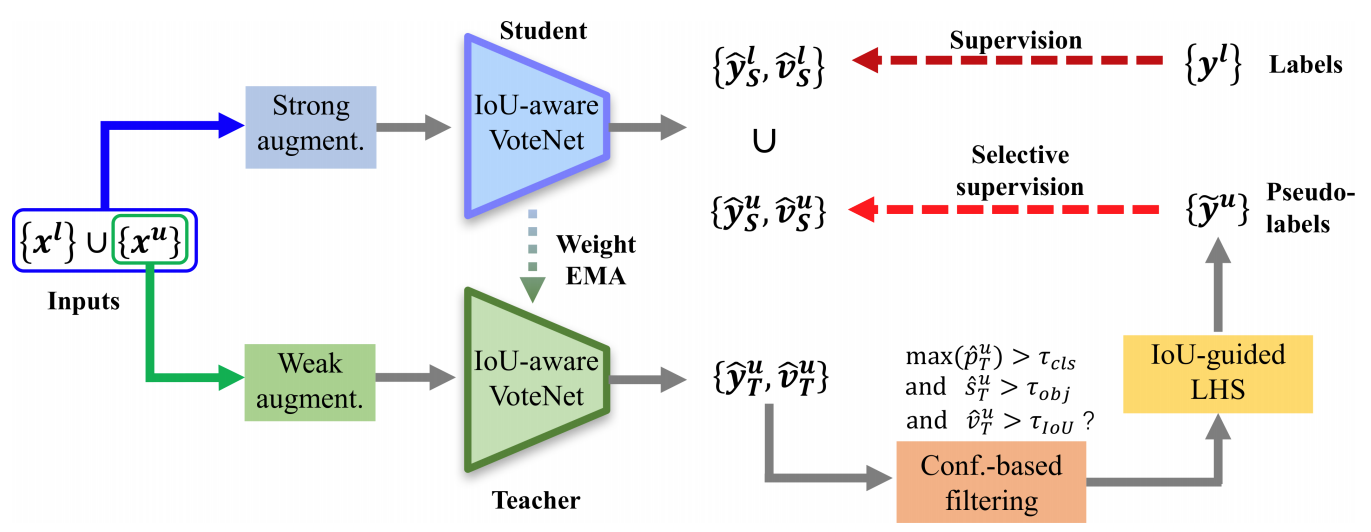
}3DIoUMatch: Leveraging IoU Prediction for Semi-Supervised 3D Object Detection He Wang*, Yezhen Cong*, Or Litany, Yue Gao, Leonidas J. Guibas CVPR 2021 @article{wang20203dioumatch,
title = {3DIoUMatch: Leveraging IoU Prediction for Semi-Supervised 3D Object Detection},
author = {Wang, He and Cong, Yezhen and Litany, Or and Gao, Yue and Guibas, Leonidas J.},
equalcontrib = {1, 2},
year = {2020},
venue = {CVPR 2021},
journal = {CVPR 2021},
image = {./OL_files/3dioumatch.png},
paper = {https://arxiv.org/abs/2012.04355},
page = {https://thu17cyz.github.io/3DIoUMatch/}
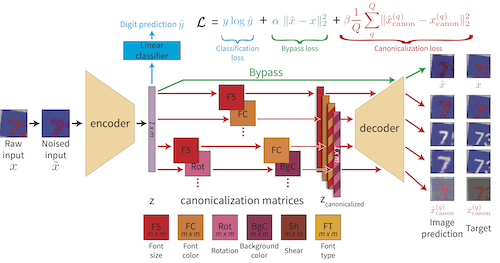
}Representation Learning Through Latent Canonicalizations Or Litany, Ari Morcos, Srinath Sridhar, Leonidas Guibas, Judy Hoffman WACV 2021 @article{litany2020representation,
title = {Representation Learning Through Latent Canonicalizations},
author = {Litany, Or and Morcos, Ari and Sridhar, Srinath and Guibas, Leonidas and Hoffman, Judy},
year = {2020},
venue = {WACV 2021},
journal = {WACV 2021},
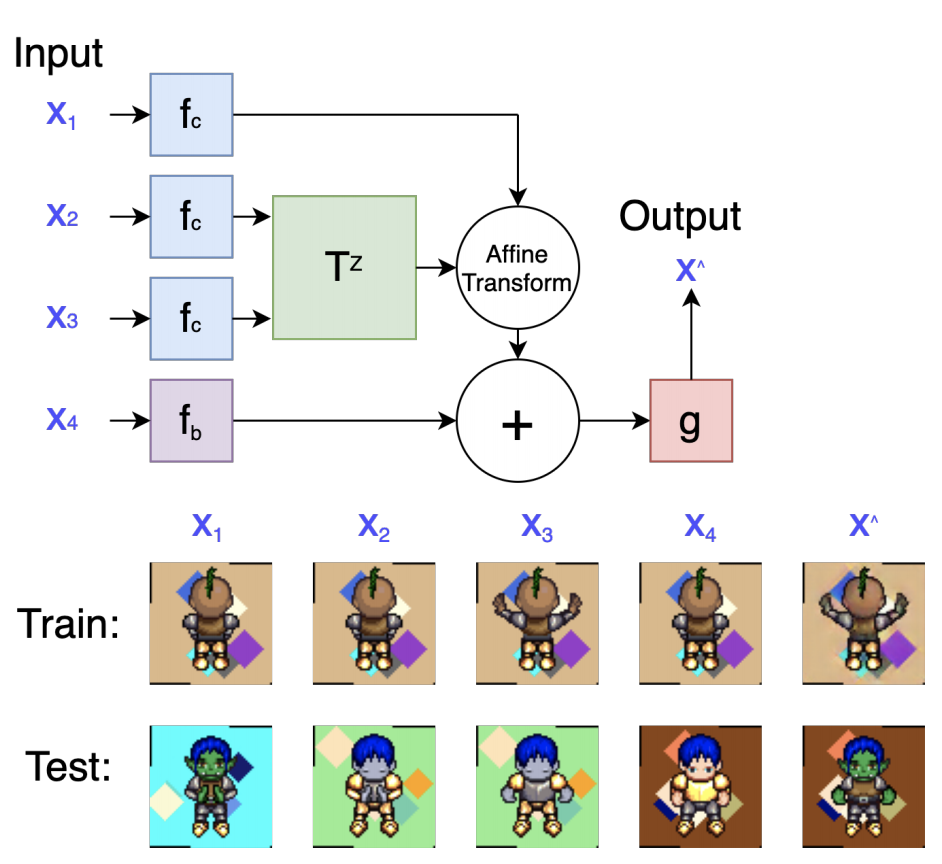
image = {./OL_files/canonicalizers.png},
paper = {https://arxiv.org/abs/2002.11829},
talk = {https://youtu.be/l1Dh4vHuYQ4}
}Continuous Geodesic Convolutions for Learning on 3D Shapes Zhangsihao Yang, Or Litany, Tolga Birdal, Srinath Sridhar, Leonidas Guibas WACV 2021 @article{yang2020continuous,
title = {Continuous Geodesic Convolutions for Learning on 3D Shapes},
author = {Yang, Zhangsihao and Litany, Or and Birdal, Tolga and Sridhar, Srinath and Guibas, Leonidas},
year = {2020},
venue = {WACV 2021},
journal = {WACV 2021},
image = {./OL_files/contConv.png},
paper = {https://arxiv.org/abs/2002.02506}
}2020Human 3D keypoints via spatial uncertainty modeling Francis Williams, Or Litany, Avneesh Sud, Kevin Swersky, Andrea Tagliasacchi Preprint @article{williams2020human,
title = {Human 3D keypoints via spatial uncertainty modeling},
author = {Williams, Francis and Litany, Or and Sud, Avneesh and Swersky, Kevin and Tagliasacchi, Andrea},
year = {2020},
venue = {Preprint},
journal = {arXiv preprint arXiv:2012.10518},
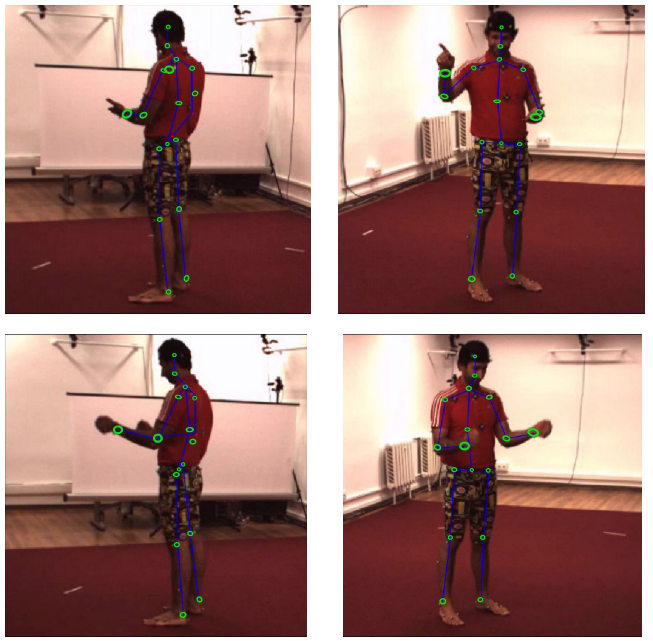
image = {./OL_files/3d_keypoint_estimation.png},
paper = {https://arxiv.org/abs/2012.10518}
}Learned Equivariant Rendering without Transformation Supervision Cinjon Resnick, Or Litany, Hugo Larochelle, Joan Bruna, Kyunghyun Cho Neurips 2020 DiffCVGP workshop @inproceedings{resnick2020learned,
title = {Learned Equivariant Rendering without Transformation Supervision},
author = {Resnick, Cinjon and Litany, Or and Larochelle, Hugo and Bruna, Joan and Cho, Kyunghyun},
year = {2020},
venue = {Neurips 2020 DiffCVGP workshop},
booktitle = {Diffcvgp workshop http://montrealrobotics.ca/diffcvgp/},
image = {./OL_files/equi_render.png},
paper = {https://arxiv.org/abs/2011.05787v1}
}Object-Centric Multi-View Aggregation Shubham Tulsiani, Or Litany, Charles R. Qi, He Wang, Leonidas J. Guibas Preprint @article{tulsiani2020object,
title = {Object-Centric Multi-View Aggregation},
author = {Tulsiani, Shubham and Litany, Or and Qi, Charles R. and Wang, He and Guibas, Leonidas J.},
year = {2020},
venue = {Preprint},
journal = {arXiv preprint arXiv:2007.10300},
image = {./OL_files/mva_teaser.png},
paper = {http://arxiv.org/abs/2007.10300}
}PointContrast: Unsupervised Pre-training for 3D Point Cloud Understanding Saining Xie, Jiatao Gu, Demi Guo, Charles R. Qi, Leonidas J. Guibas, Or Litany ECCV 2020Spotlight @inproceedings{xie2020pointcontrast,
title = {PointContrast: Unsupervised Pre-training for 3D Point Cloud Understanding},
author = {Xie, Saining and Gu, Jiatao and Guo, Demi and Qi, Charles R. and Guibas, Leonidas J. and Litany, Or},
year = {2020},
venue = {ECCV 2020},
booktitle = {ECCV 2020 Spotlight},
image = {./OL_files/pointContrast.png},
paper = {https://arxiv.org/abs/2007.10985},
award = {Spotlight}
}Towards Precise Completion of Deformable Shapes Oshri Halimi, Ido Imanuel, Or Litany, Giovanni Trappolini, Emanuele Rodolà, Leonidas Guibas, Ron Kimmel ECCV 2020 @inproceedings{halimi2020towards,
title = {Towards Precise Completion of Deformable Shapes},
author = {Halimi, Oshri and Imanuel, Ido and Litany, Or and Trappolini, Giovanni and Rodol{\`a}, Emanuele and Guibas, Leonidas and Kimmel, Ron},
year = {2020},
venue = {ECCV 2020},
booktitle = {Computer Vision--ECCV 2020: 16th European Conference, Glasgow, UK, August 23--28, 2020, Proceedings, Part XXIV 16},
pages = {359--377},
image = {./OL_files/theWhole.png},
paper = {https://arxiv.org/abs/2001.09650},
organization = {Springer International Publishing}
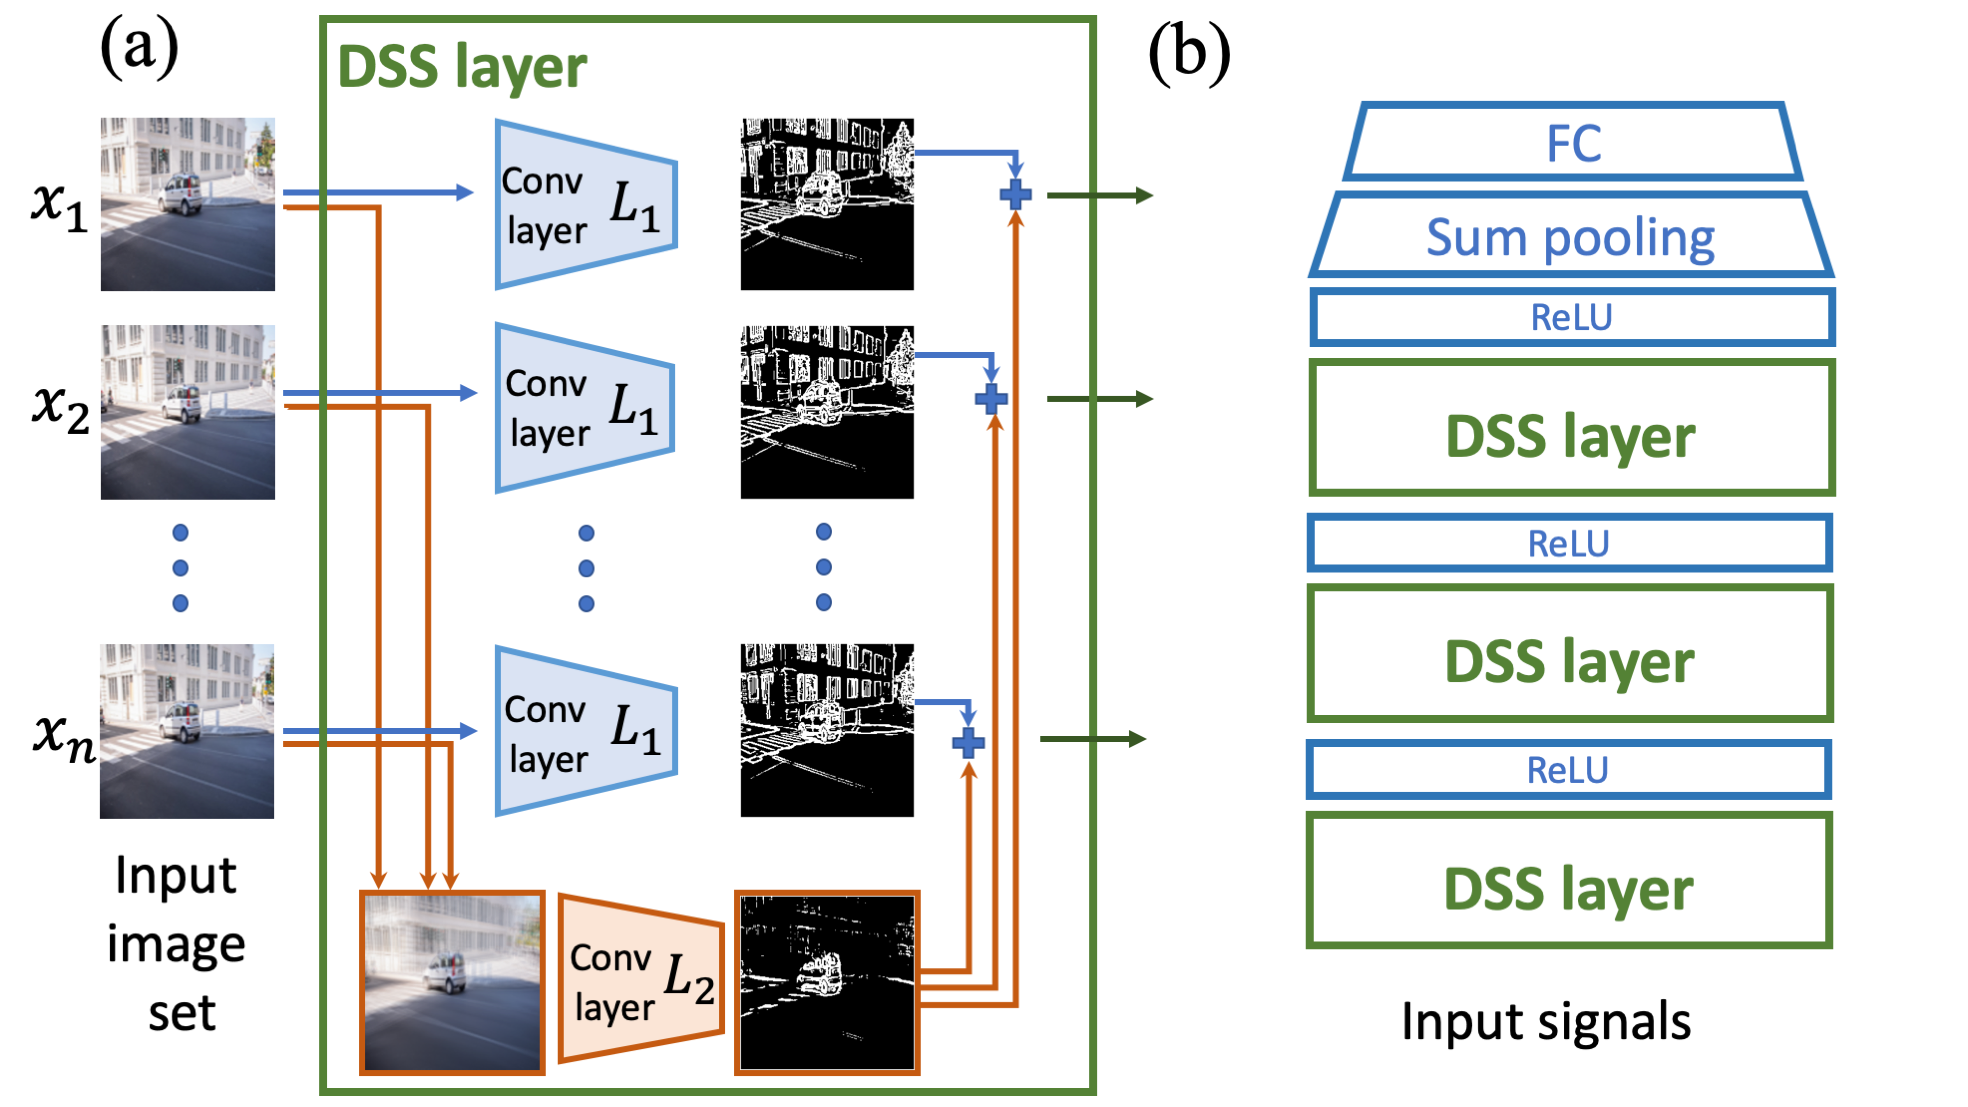
}On Learning Sets of Symmetric Elements Haggai Maron, Or Litany, Gal Chechik, Ethan Fetaya ICML 2020Outstanding Paper Award @inproceedings{maron2020learning,
title = {On Learning Sets of Symmetric Elements},
author = {Maron, Haggai and Litany, Or and Chechik, Gal and Fetaya, Ethan},
year = {2020},
venue = {ICML 2020},
booktitle = {ICML 2020 -- Outstanding paper award},
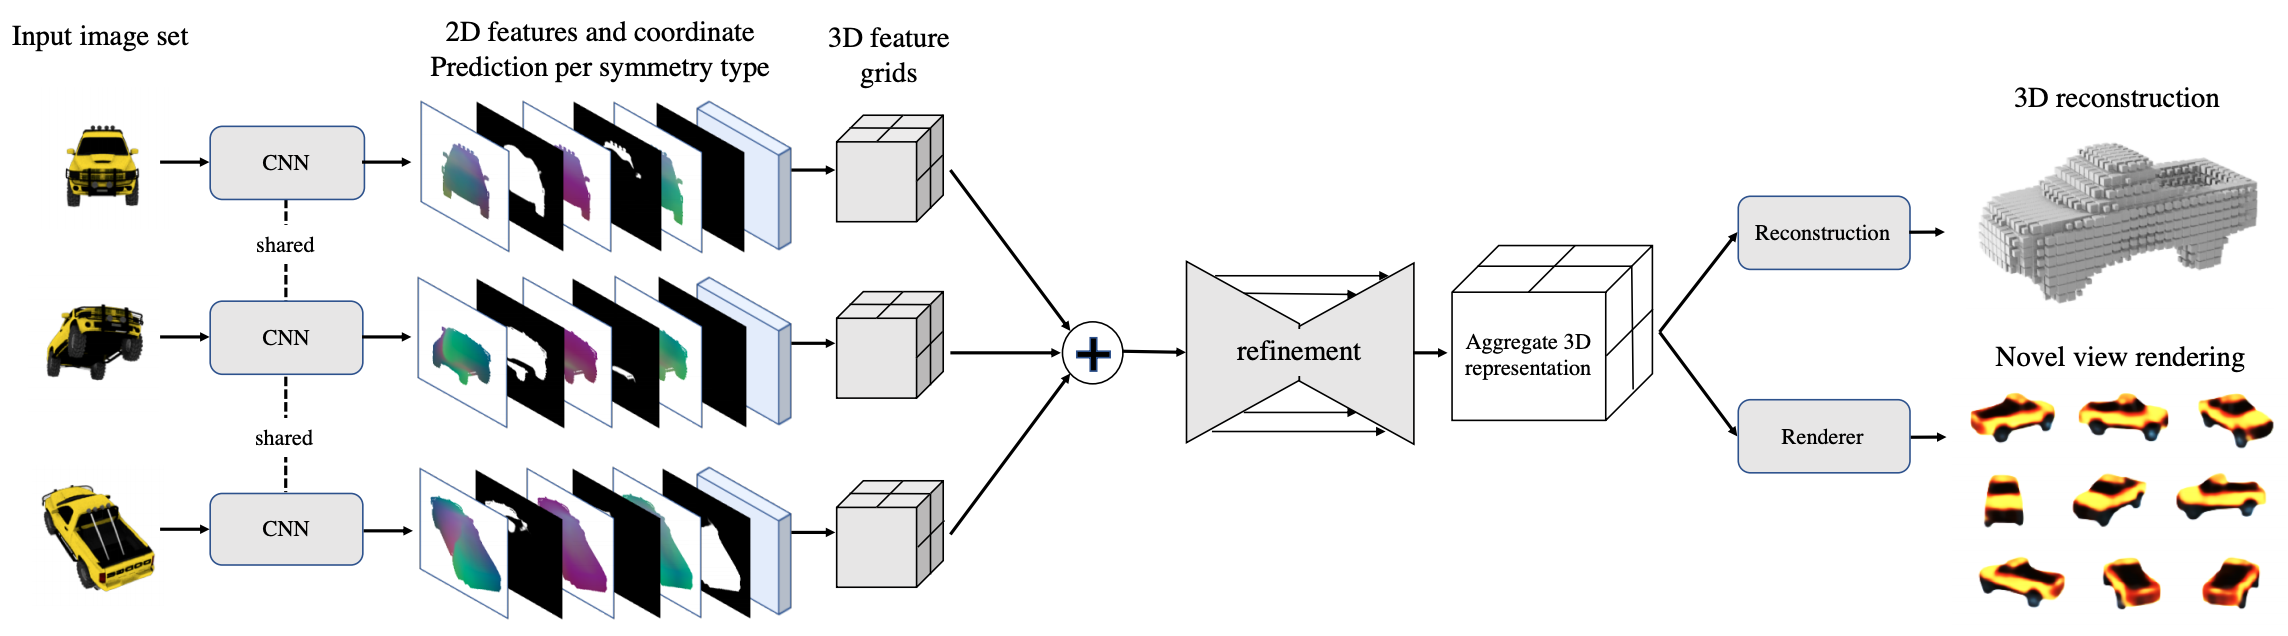
image = {./OL_files/dss_layer.png},
paper = {https://arxiv.org/abs/2002.08599},
award = {Outstanding Paper Award}
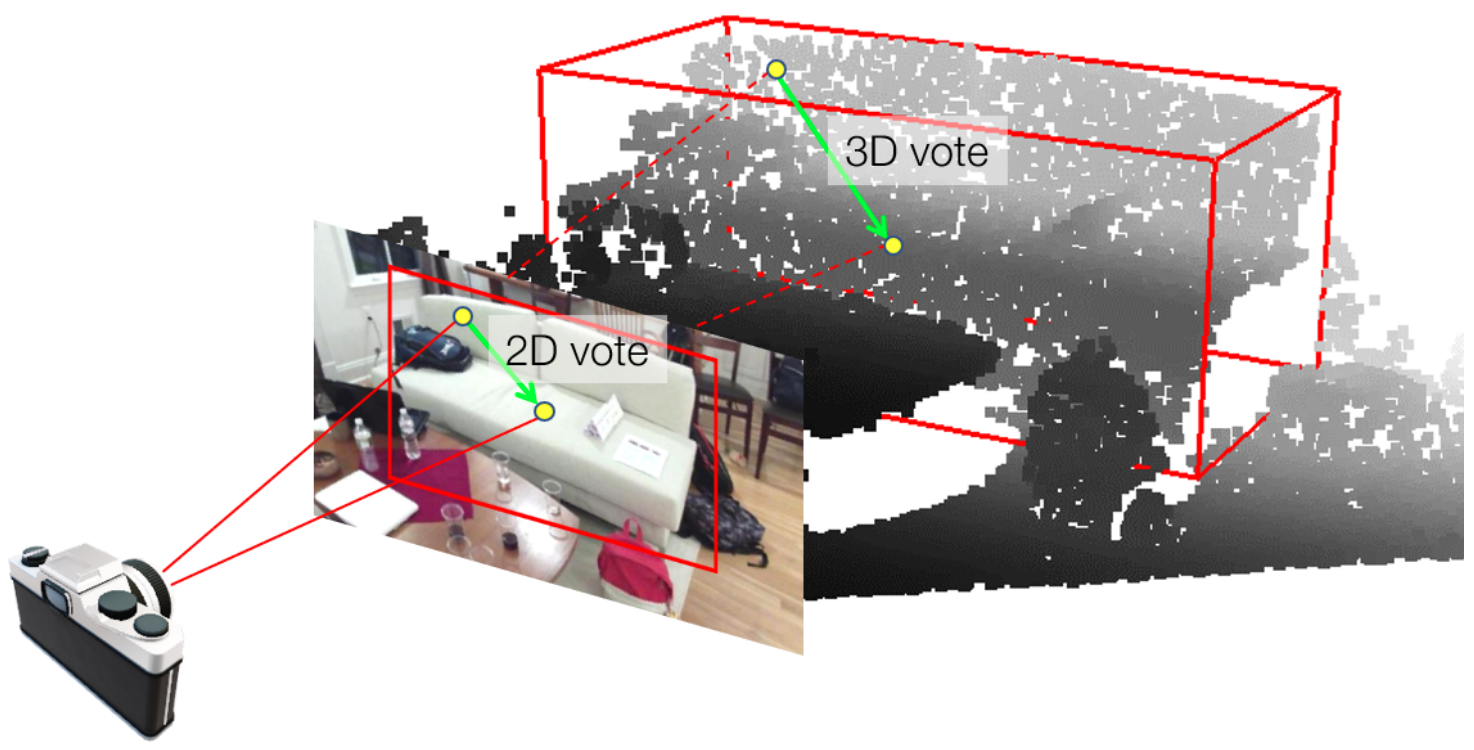
}ImVoteNet: Boosting 3D Object Detection in Point Clouds with Image Votes Charles R. Qi, Xinlei Chen, Or Litany, Leonidas J. Guibas CVPR 2020 @inproceedings{qi2020imvotenet,
title = {ImVoteNet: Boosting 3D Object Detection in Point Clouds with Image Votes},
author = {Qi, Charles R. and Chen, Xinlei and Litany, Or and Guibas, Leonidas J.},
year = {2020},
venue = {CVPR 2020},
booktitle = {CVPR 2020},
image = {./OL_files/imvote.png},
paper = {https://arxiv.org/abs/2001.10692},
talk = {https://www.youtube.com/watch?v=xCnbvgMAg-Y}
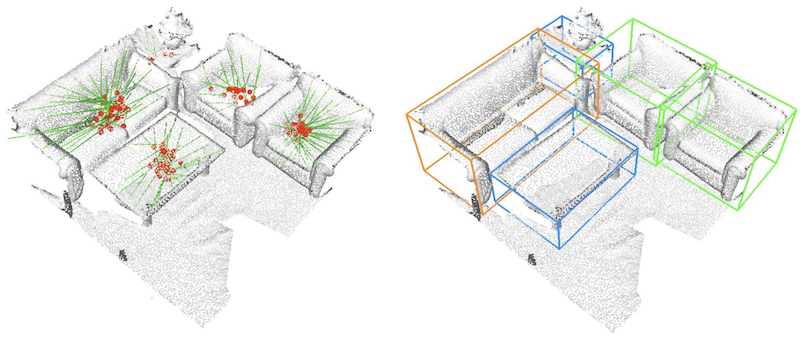
}2019Deep Hough Voting for 3D Object Detection in Point Clouds Charles R. Qi, Or Litany, Kaiming He, Leonidas J. Guibas ICCV, 2019Best Paper Nomination @inproceedings{qi2019deep,
title = {Deep Hough Voting for 3D Object Detection in Point Clouds},
author = {Qi, Charles R. and Litany, Or and He, Kaiming and Guibas, Leonidas J.},
year = {2019},
venue = {ICCV, 2019},
booktitle = {ICCV 2019 (Oral, Best Paper Nomination)},
image = {./OL_files/DHV_teaser.png},
paper = {https://arxiv.org/pdf/1904.09664.pdf},
code = {https://github.com/facebookresearch/votenet},
slides = {./OL_files/talks/deep_hough_voting.pdf},
talk = {https://youtu.be/2ntDYowHbZs?t=4585},
award = {Best Paper Nomination}
}Dual-primal graph convolutional networks Federico Monti, Oleksandr Shchur, Aleksandar Bojchevski, Or Litany, Stephan Günnemann, Michael M. Bronstein GEM workshop at ECML-PKDD, 2019Oral presentation @article{monti2018dual,
title = {Dual-primal graph convolutional networks},
author = {Monti, Federico and Shchur, Oleksandr and Bojchevski, Aleksandar and Litany, Or and G{\"u}nnemann, Stephan and Bronstein, Michael M.},
year = {2018},
venue = {GEM workshop at ECML-PKDD, 2019},
journal = {arXiv preprint arXiv:1806.00770},
image = {./OL_files/dualprimal.png},
paper = {https://arxiv.org/pdf/1806.00770.pdf},
award = {Oral presentation}
}SOSELETO: A Unified Approach to Transfer Learning and Training with Noisy Labels Or Litany, Daniel Freedman ICLR workshop on Learning from Limited Labeled Data, 2019Best Paper Award @inproceedings{litany2019soseleto,
title = {SOSELETO: A Unified Approach to Transfer Learning and Training with Noisy Labels},
author = {Litany, Or and Freedman, Daniel},
year = {2019},
venue = {ICLR workshop on Learning from Limited Labeled Data, 2019},
booktitle = {ICLR workshop on Learning from Limited Labeled Data (LLD) -- Best Paper Award},
image = {./OL_files/soseleto.png},
paper = {https://arxiv.org/pdf/1805.09622.pdf},
code = {https://github.com/orlitany/SOSELETO},
slides = {./OL_files/SOSELETO_presentation.pdf},
poster = {./OL_files/SOSELETO_ICLR19_poster.pdf},
talk = {https://slideslive.com/38915746},
award = {Best Paper Award}
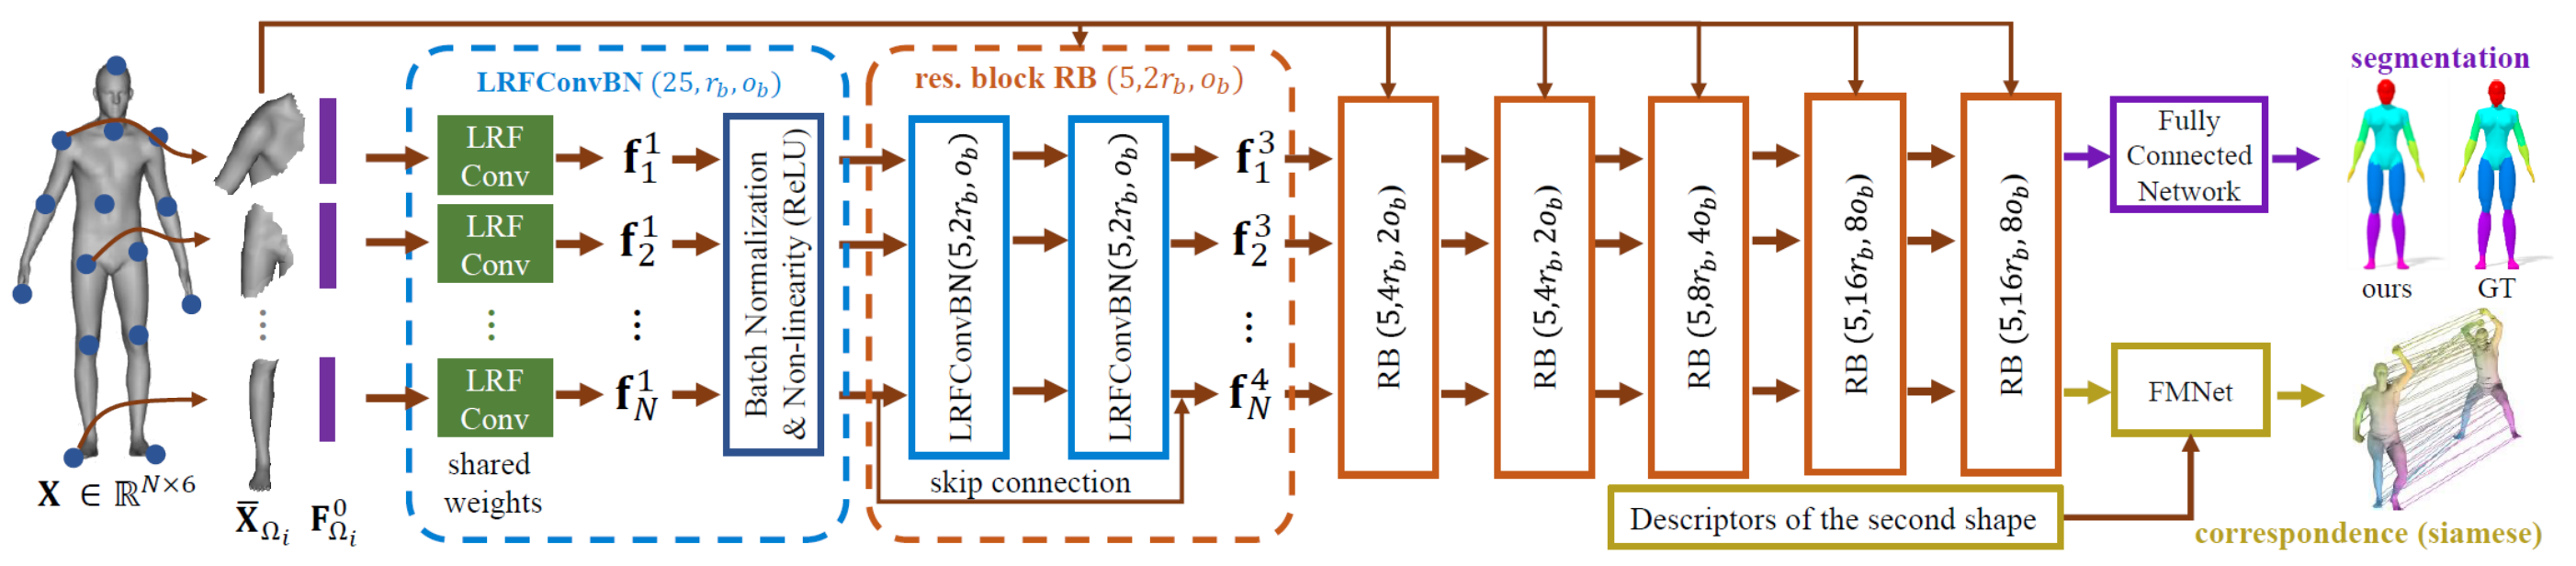
}Unsupervised Learning of Dense Shape Correspondence Oshri Halimi, Or Litany, Emanuele Rodolà, Alex M. Bronstein, Ron Kimmel Computer Vision and Pattern Recognition (CVPR), 2019Oral presentation @inproceedings{halimi2019unsupervised,
title = {Unsupervised Learning of Dense Shape Correspondence},
author = {Halimi, Oshri and Litany, Or and Rodol{\`a}, Emanuele and Bronstein, Alex M. and Kimmel, Ron},
year = {2019},
venue = {Computer Vision and Pattern Recognition (CVPR), 2019},
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
pages = {4370--4379},
image = {./OL_files/unsupervised_fmnet.png},
paper = {https://arxiv.org/pdf/1812.02415.pdf},
code = {https://github.com/OshriHalimi/unsupervised_learning_of_dense_shape_correspondence},
talk = {https://www.linkedin.com/feed/update/urn:li:activity:6547910607310598144},
award = {Oral presentation}
}2018Deformable Shape Completion with Graph Convolutional Autoencoders Or Litany, Alex Bronstein, Michael Bronstein, Ameesh Makadia Computer Vision and Pattern Recognition (CVPR), 2018 @inproceedings{litany2018deformable,
title = {Deformable Shape Completion with Graph Convolutional Autoencoders},
author = {Litany, Or and Bronstein, Alex and Bronstein, Michael and Makadia, Ameesh},
year = {2018},
venue = {Computer Vision and Pattern Recognition (CVPR), 2018},
booktitle = {Proceedings of the IEEE conference on computer vision and pattern recognition},
pages = {1886--1895},
image = {./OL_files/shapeComp.png},
paper = {https://arxiv.org/pdf/1712.00268v1.pdf}
}Partial Single-and Multishape Dense Correspondence Using Functional Maps Or Litany, Emanuele Rodolà, Alex Bronstein, Michael Bronstein, Daniel Cremers Handbook of Numerical Analysis, Elsevier, 2018 @incollection{litany2018partial,
title = {Partial Single-and Multishape Dense Correspondence Using Functional Maps},
author = {Litany, Or and Rodol{\`a}, Emanuele and Bronstein, Alex and Bronstein, Michael and Cremers, Daniel},
year = {2018},
venue = {Handbook of Numerical Analysis, Elsevier, 2018},
booktitle = {Handbook of Numerical Analysis},
publisher = {Elsevier},
volume = {19},
pages = {55--90},
image = {./OL_files/pfm_book.png},
paper = {https://www.sciencedirect.com/science/article/pii/S1570865918300097}
}Class-Aware Fully Convolutional Gaussian and Poisson Denoising Tal Remez, Or Litany, Raja Giryes, Alex M. Bronstein IEEE Transactions on Image Processing, 2018 @article{remez2018class,
title = {Class-Aware Fully Convolutional {Gaussian} and {Poisson} Denoising},
author = {Remez, Tal and Litany, Or and Giryes, Raja and Bronstein, Alex M.},
year = {2018},
venue = {IEEE Transactions on Image Processing, 2018},
journal = {IEEE Transactions on Image Processing},
publisher = {IEEE},
volume = {27},
pages = {5707--5722},
image = {./OL_files/class_aware_poiss.png},
paper = {https://arxiv.org/pdf/1808.06562.pdf},
code = {https://github.com/TalRemez/deep_class_aware_denoising},
number = {11}
}2017Efficient Deformable Shape Correspondence via Kernel Matching Zorah Lähner, Matthias Vestner, Amit Boyarski, Or Litany, Ron Slossberg, Tal Remez, Emanuele Rodolà, Alex Bronstein, Michael Bronstein, Ron Kimmel, Daniel Cremers Intl. Conference on 3D Vision (3DV), 2017 @article{lahner2017efficient,
title = {Efficient Deformable Shape Correspondence via Kernel Matching},
author = {L{\"a}hner, Zorah and Vestner, Matthias and Boyarski, Amit and Litany, Or and Slossberg, Ron and Remez, Tal and Rodol{\`a}, Emanuele and Bronstein, Alex and Bronstein, Michael and Kimmel, Ron and Cremers, Daniel},
year = {2017},
venue = {Intl. Conference on 3D Vision (3DV), 2017},
journal = {3DV},
image = {./OL_files/vestner-3dv17.png},
paper = {https://arxiv.org/pdf/1707.08991.pdf},
code = {https://github.com/zorah/KernelMatching}
}Deep Functional Maps: Structured Prediction for Dense Shape Correspondence Or Litany, Tal Remez, Emanuele Rodolà, Alex Bronstein, Michael Bronstein ICCV, 2017 @inproceedings{litany2017deep,
title = {Deep Functional Maps: Structured Prediction for Dense Shape Correspondence},
author = {Litany, Or and Remez, Tal and Rodol{\`a}, Emanuele and Bronstein, Alex and Bronstein, Michael},
year = {2017},
venue = {ICCV, 2017},
booktitle = {Proceedings of the IEEE international conference on computer vision},
pages = {5659--5667},
image = {./OL_files/FMNet.png},
paper = {http://vision.in.tum.de/_media/spezial/bib/litany-iccv17.pdf},
code = {https://github.com/orlitany/DeepFunctionalMaps}
}Deep Class-Aware Image Denoising Tal Remez, Or Litany, Raja Giryes, Alex M. Bronstein IEEE International Conference on Image Processing (ICIP), 2017 @inproceedings{remez2017deep,
title = {Deep Class-Aware Image Denoising},
author = {Remez, Tal and Litany, Or and Giryes, Raja and Bronstein, Alex M.},
year = {2017},
venue = {IEEE International Conference on Image Processing (ICIP), 2017},
booktitle = {2017 international conference on sampling theory and applications (SampTA)},
pages = {138--142},
image = {./OL_files/clsawrden.png},
paper = {https://arxiv.org/abs/1701.01698},
code = {https://github.com/TalRemez/deep_class_aware_denoising},
organization = {IEEE}
}Cloud Dictionary: Sparse Coding and Modeling for Point Clouds Or Litany*, Tal Remez*, Alex Bronstein Signal Processing with Adaptive Sparse Structured Representations (SPARS), 2017 @article{litany2017cloud,
title = {Cloud Dictionary: Sparse Coding and Modeling for Point Clouds},
author = {Litany, Or and Remez, Tal and Bronstein, Alex},
equalcontrib = {1, 2},
year = {2017},
venue = {Signal Processing with Adaptive Sparse Structured Representations (SPARS), 2017},
journal = {SPARS},
image = {./OL_files/clouddict.png},
paper = {https://arxiv.org/pdf/1612.04956v1}
}Fully Spectral Partial Shape Matching Or Litany, Emanuele Rodolà, Alex M. Bronstein, Michael M. Bronstein Computer Graphics Forum, Vol. 36(2), 2017Presented at Eurographics, 2017 @inproceedings{litany2017fully,
title = {Fully Spectral Partial Shape Matching},
author = {Litany, Or and Rodol{\`a}, Emanuele and Bronstein, Alex M. and Bronstein, Michael M.},
year = {2017},
venue = {Computer Graphics Forum, Vol. 36(2), 2017},
booktitle = {Computer Graphics Forum},
volume = {36},
image = {./OL_files/fullyspectral.png},
paper = {http://vision.in.tum.de/_media/spezial/bib/litany-eg17.pdf},
code = {https://github.com/orlitany/FSPM},
award = {Presented at Eurographics, 2017},
number = {2},
organization = {The Eurographics Association and John Wiley \& Sons Ltd.}
}SHREC’17: Deformable Shape Retrieval with Missing Parts Emanuele Rodolà, Luca Cosmo, Or Litany, Michael M. Bronstein, Alex M. Bronstein, et al. EUROGRAPHICS Workshop on 3D Object Retrieval (3DOR), 2017 @inproceedings{rodola2017shrec,
title = {{SHREC}’17: Deformable Shape Retrieval with Missing Parts},
author = {Rodol{\`a}, Emanuele and Cosmo, Luca and Litany, Or and Bronstein, Michael M. and Bronstein, Alex M. and others},
year = {2017},
venue = {EUROGRAPHICS Workshop on 3D Object Retrieval (3DOR), 2017},
booktitle = {Proceedings of the Eurographics Workshop on 3D Object Retrieval, Lisbon, Portugal},
pages = {23--24},
image = {./OL_files/shrec17.png},
paper = {http://vision.in.tum.de/_media/spezial/bib/shrec17partial.pdf},
code = {http://vision.in.tum.de/_media/spezial/bib/shrec17-baseline.zip},
dataset = {https://sites.google.com/view/shrec17/}
}ASIST: Automatic Semantically Invariant Scene Transformation Or Litany, Tal Remez, Daniel Freedman, Lior Shapira, Alex Bronstein, Ran Gal Computer Vision and Image Understanding (CVIU), 2017 @article{litany2017asist,
title = {{ASIST}: Automatic Semantically Invariant Scene Transformation},
author = {Litany, Or and Remez, Tal and Freedman, Daniel and Shapira, Lior and Bronstein, Alex and Gal, Ran},
year = {2017},
venue = {Computer Vision and Image Understanding (CVIU), 2017},
journal = {Computer Vision and Image Understanding},
publisher = {Academic Press},
volume = {157},
pages = {284--299},
image = {./OL_files/asist.png},
paper = {http://arxiv.org/abs/1512.01515}
}2016Non-Rigid Puzzles Or Litany, Emanuele Rodolà, Alex Bronstein, Michael Bronstein, Daniel Cremers Computer Graphics Forum, Wiley, volume 35, 2016SGP Best Paper Award @inproceedings{litany2016non,
title = {Non-Rigid Puzzles},
author = {Litany, Or and Rodol{\`a}, Emanuele and Bronstein, Alex and Bronstein, Michael and Cremers, Daniel},
year = {2016},
venue = {Computer Graphics Forum, Wiley, volume 35, 2016},
booktitle = {Computer Graphics Forum},
volume = {35},
pages = {135--143},
image = {./OL_files/puzzles.png},
paper = {http://vision.in.tum.de/_media/spezial/bib/litany16.pdf},
code = {https://github.com/orlitany/NonRigidPuzzles},
award = {SGP Best Paper Award},
number = {5},
organization = {The Eurographics Association and John Wiley \& Sons Ltd.}
}A picture is worth a billion bits: Real-time image reconstruction from dense binary threshold pixels Tal Remez*, Or Litany*, Alex Bronstein International Conference on Computational Photography (ICCP), 2016 @inproceedings{remez2016picture,
title = {A picture is worth a billion bits: Real-time image reconstruction from dense binary threshold pixels},
author = {Remez, Tal and Litany, Or and Bronstein, Alex},
equalcontrib = {1, 2},
year = {2016},
venue = {International Conference on Computational Photography (ICCP), 2016},
booktitle = {2016 IEEE International Conference on Computational Photography (ICCP)},
pages = {1--9},
image = {./OL_files/binarycam.png},
paper = {https://arxiv.org/pdf/1510.04601.pdf},
organization = {IEEE}
}FPGA system for real-time computational extended depth of field imaging using phase aperture coding Tal Remez, Or Litany, Shachar Yoseff, Harel Haim, Alex Bronstein Preprint @article{remez2016fpga,
title = {FPGA system for real-time computational extended depth of field imaging using phase aperture coding},
author = {Remez, Tal and Litany, Or and Yoseff, Shachar and Haim, Harel and Bronstein, Alex},
year = {2016},
venue = {Preprint},
journal = {arXiv preprint arXiv:1608.01074},
image = {./OL_files/fpga.png},
paper = {https://arxiv.org/abs/1608.01074}
}2015Image reconstruction from dense binary pixels Or Litany*, Tal Remez*, Alex Bronstein Signal Processing with Adaptive Sparse Structured Representations (SPARS), 2015 @misc{litany2015image,
title = {Image reconstruction from dense binary pixels},
author = {Or Litany and Tal Remez and Alex Bronstein},
equalcontrib = {1, 2},
year = {2015},
venue = {Signal Processing with Adaptive Sparse Structured Representations (SPARS), 2015},
archiveprefix = {arXiv preprint arXiv:1512.01774},
image = {./OL_files/binarycamspars.png},
paper = {http://arxiv.org/abs/1512.01774}
}2012Putting the Pieces Together: Regularized Multi-part Shape Matching Or Litany, Alexander M. Bronstein, Michael M. Bronstein Workshop on Nonrigid Shape Analysis and Deformable Image Alignment (NORDIA), 2012 @inproceedings{litany2012putting,
title = {Putting the Pieces Together: Regularized Multi-part Shape Matching},
author = {Litany, Or and Bronstein, Alexander M. and Bronstein, Michael M.},
year = {2012},
venue = {Workshop on Nonrigid Shape Analysis and Deformable Image Alignment (NORDIA), 2012},
booktitle = {ECCV Workshops (1)},
pages = {1--11},
image = {./OL_files/rigidpuzzles.png},
paper = {https://vista.cs.technion.ac.il/wp-content/uploads/2018/10/LitBroBroNORDIA12.pdf}
} |