|
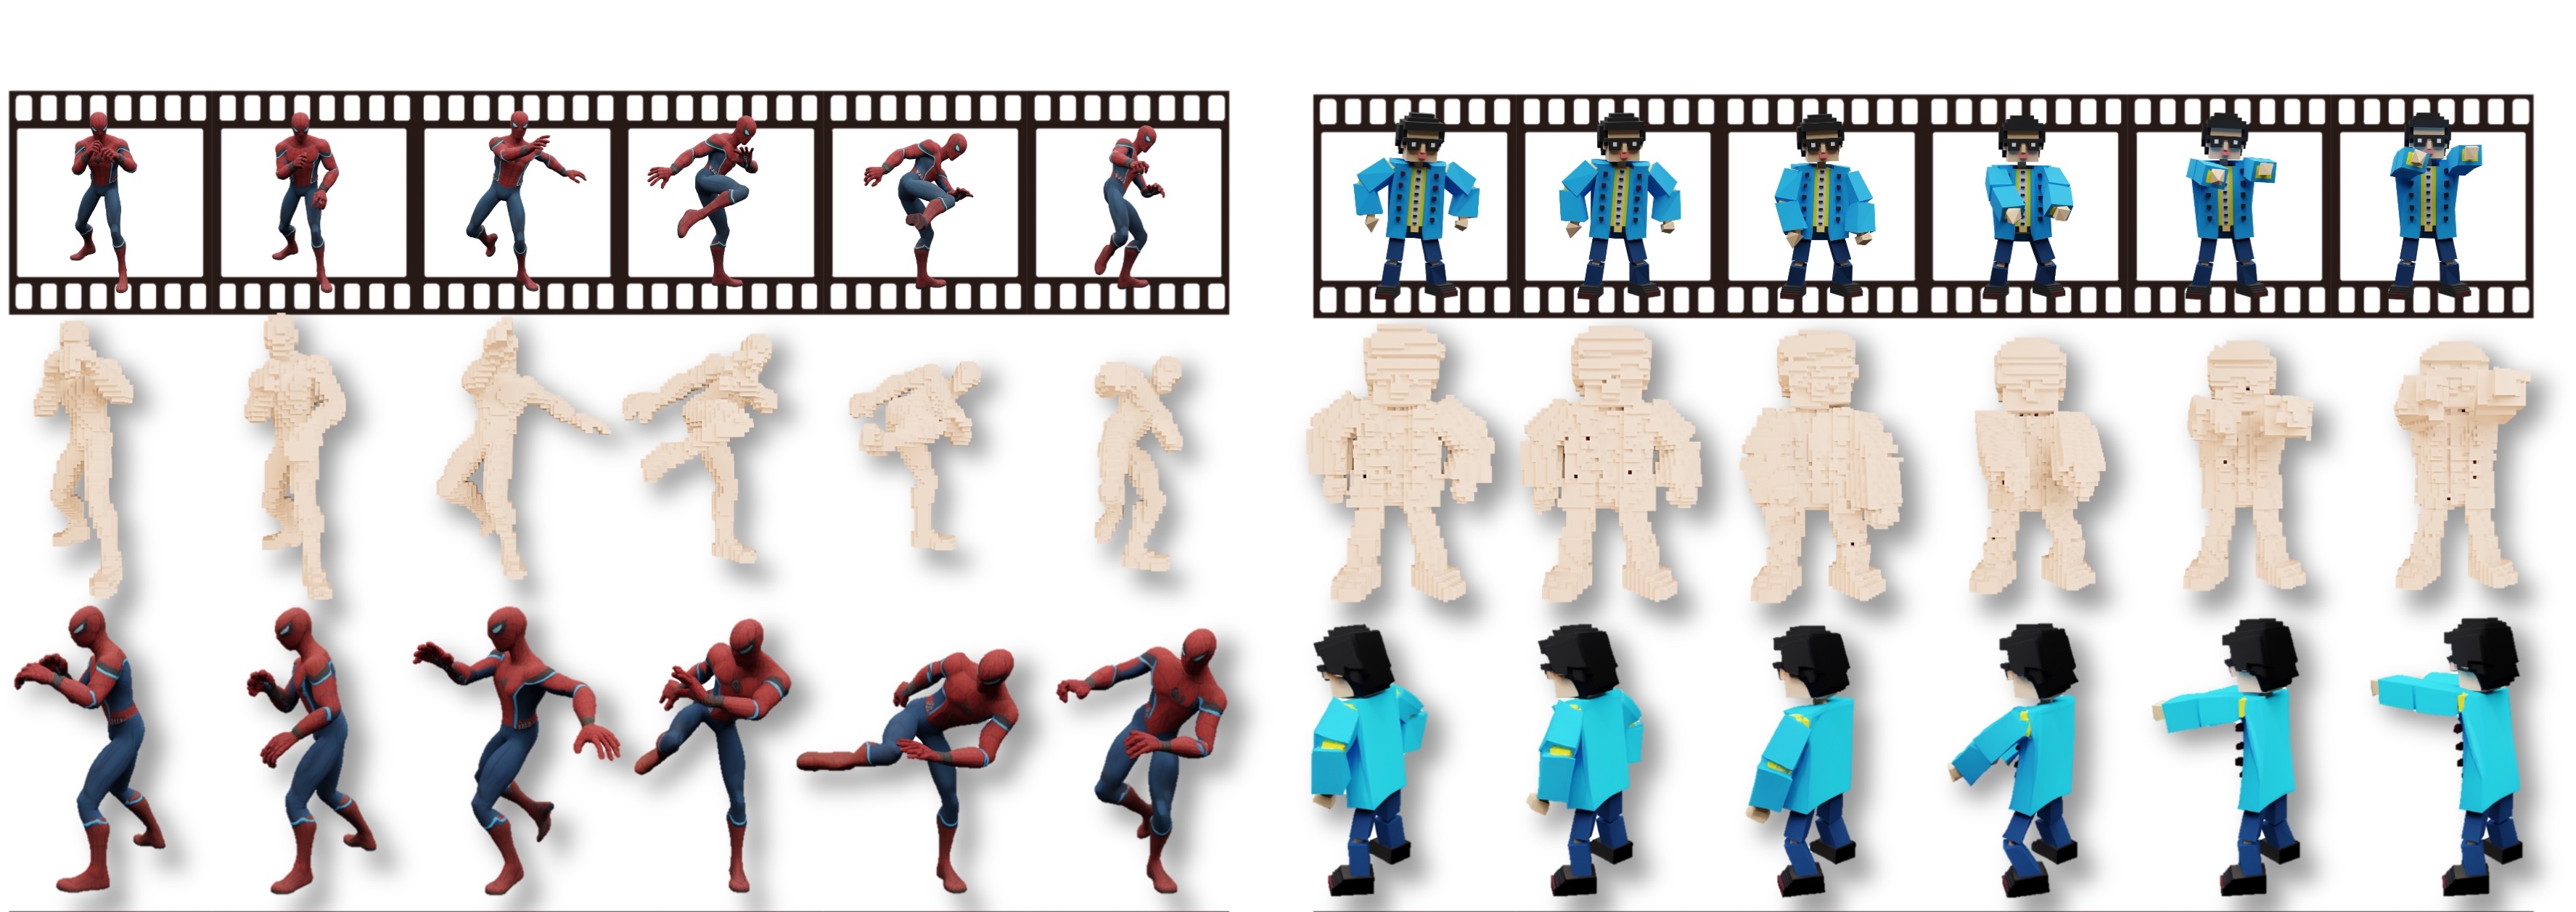
In my research, I consistently leverage the inherent structure of visual data.
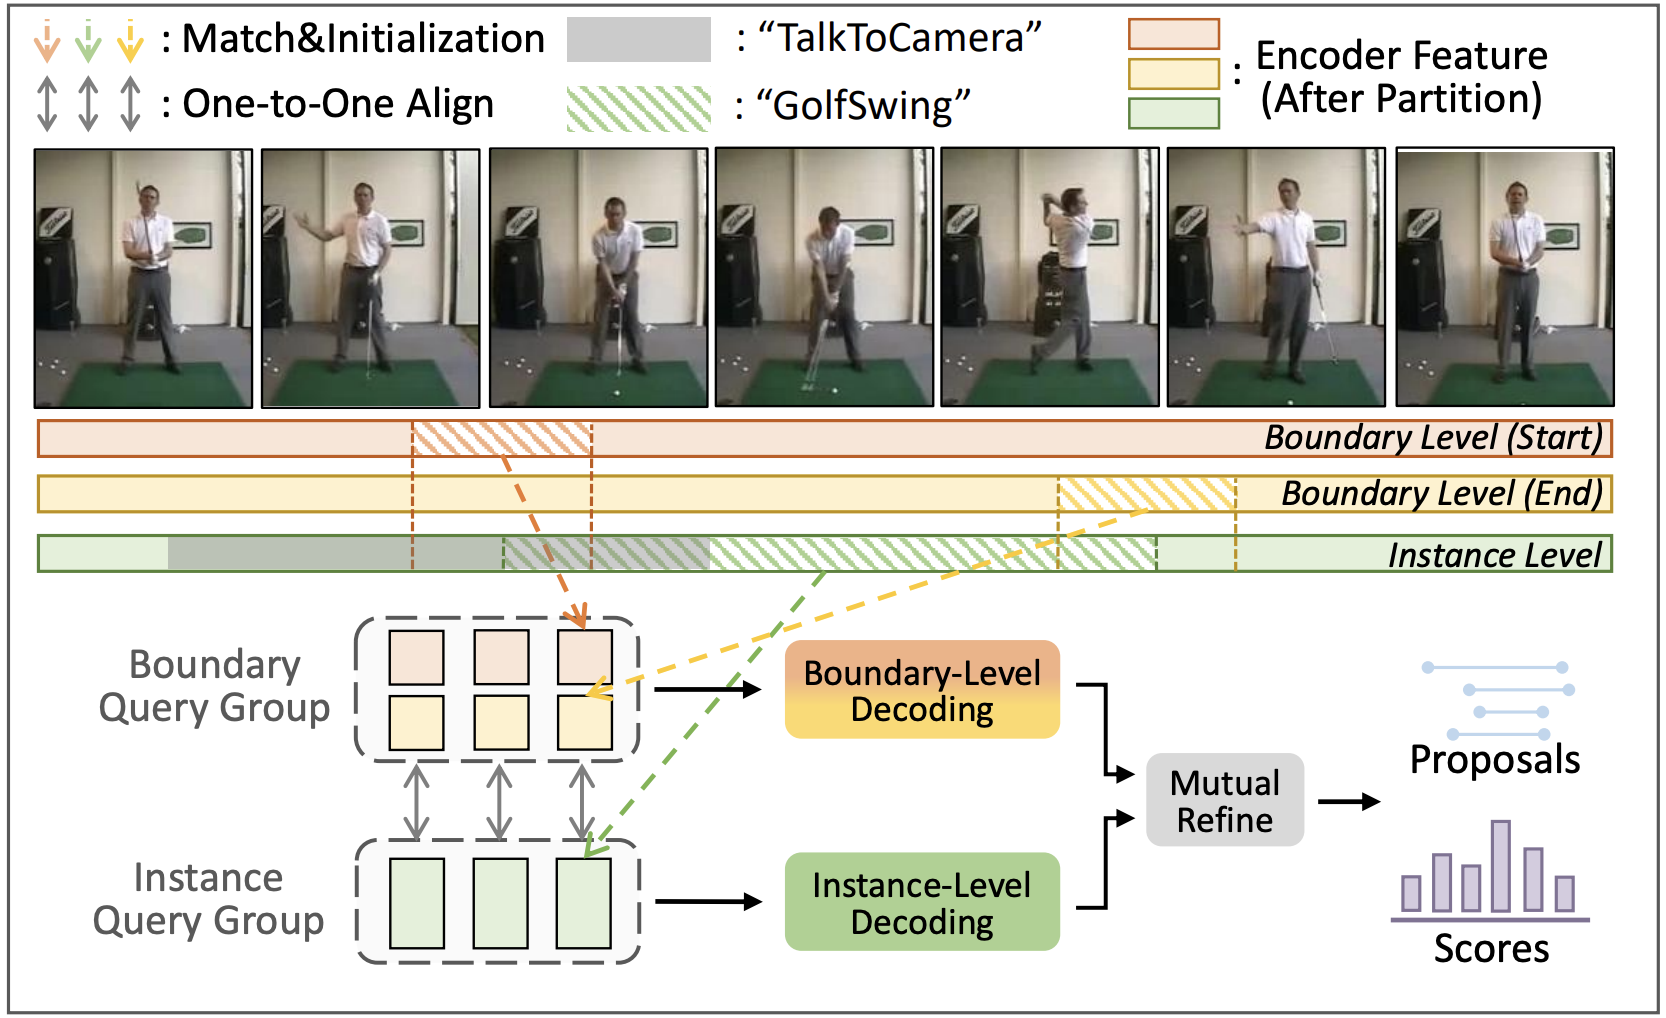
In video understanding, I exploit the natural temporal and semantic structure of videos to enable efficient perception.
In visual scene generation, I study how structured scene representations support reliable and controllable creation and manipulation of visual content.
|
|
Talk2Move: Reinforcement Learning for Text-Instructed Object-Level Geometric Transformation in Scenes
Jing Tan,
Zhaoyang Zhang,
Yantao Shen,
Jiarui Cai,
Shuo Yang,
Jiajun Wu,
Wei Xia,
Zhuowen Tu,
Stefano Soatto
CVPR, 2026 (Highlight)
project page /
code /
arXiv
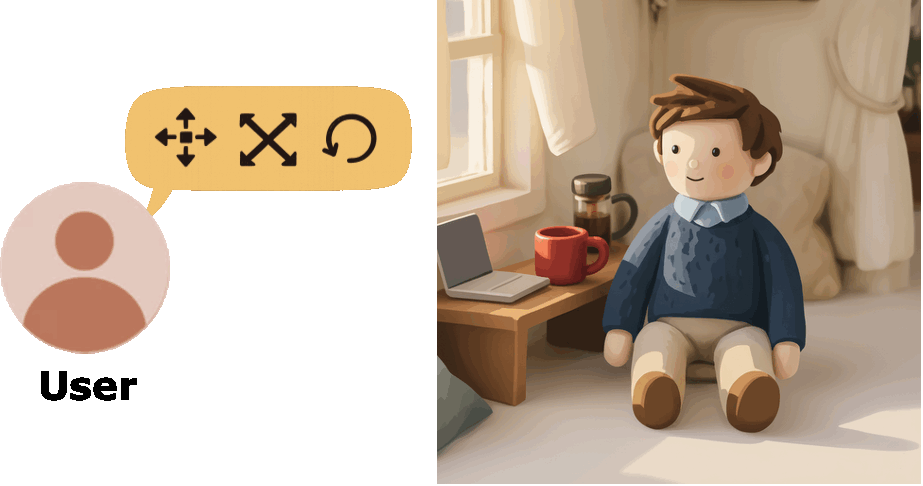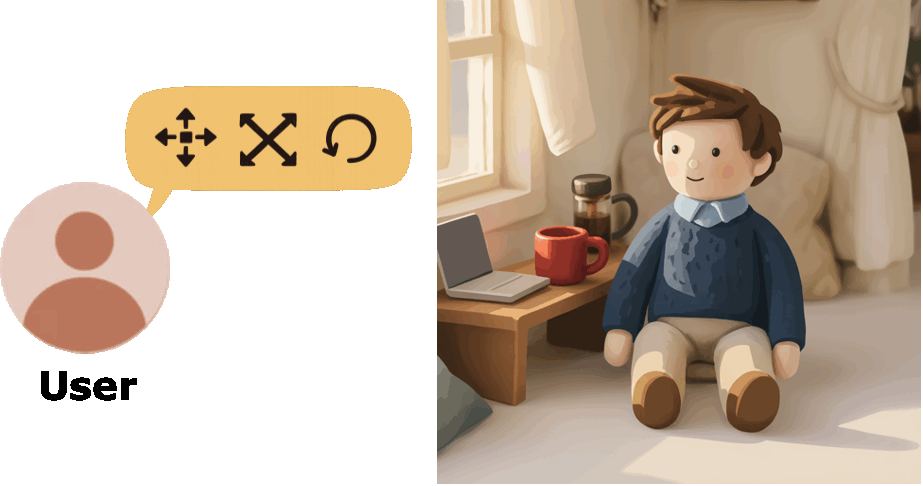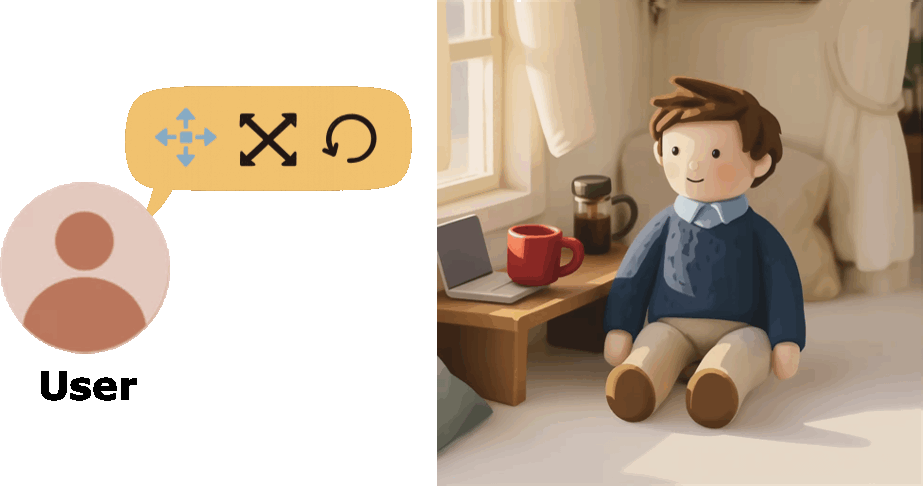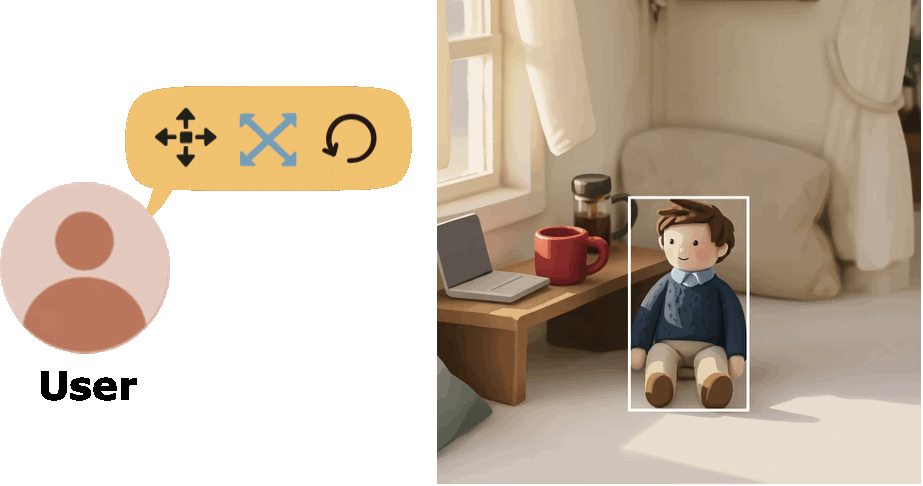
We show, in the context of geometric object transformations in scene images, that RL is more suitable than SFT to solve visual editing problems with verifiable rewards, in terms of data efficiency and editing accuracy.
|
|
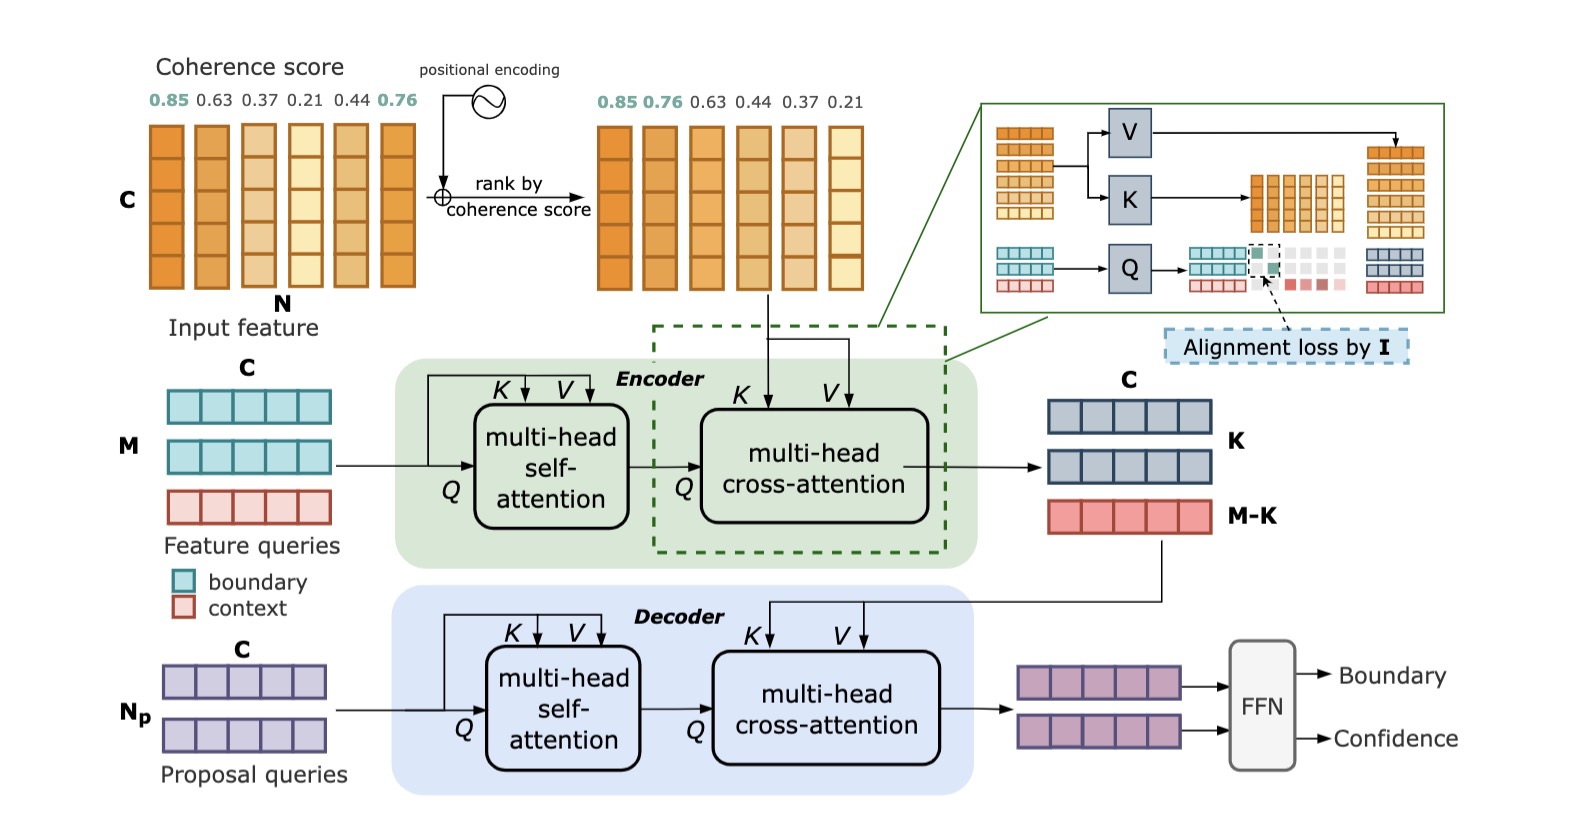
Temporal Perceiver: A General Architecture for Arbitrary Boundary Detection
Jing Tan, Yuhong Wang,
Gangshan Wu,
Limin Wang
T-PAMI, 2023
arXiv /
code /
blog
We present Temporal Perceiver (TP), a general architecture based on Transformer decoders as a unified solution to detect arbitrary generic boundaries, including shot-level, event-level and scene-level temporal boundaries.
|
|
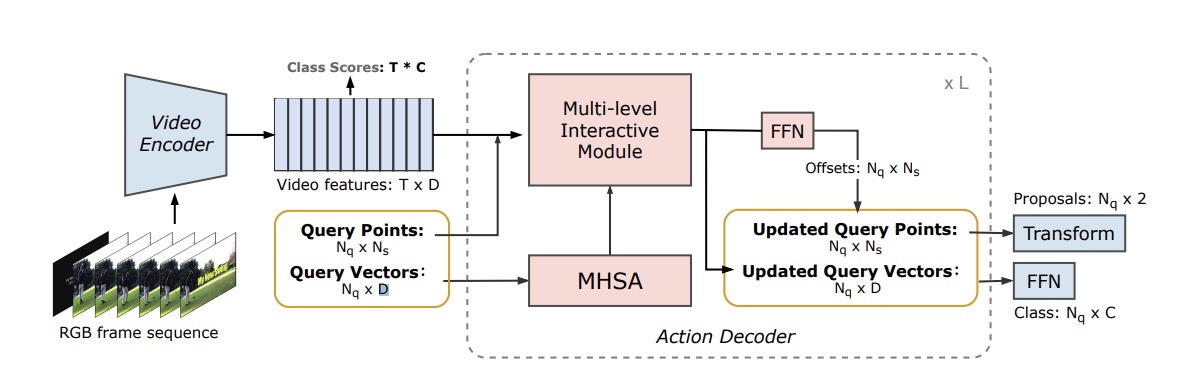
PointTAD: Multi-Label Temporal Action Detection with Learnable Query Points
Jing Tan, Xiaotong Zhao, Xintian Shi, Bin Kang,
Limin Wang
NeurIPS, 2022
arXiv /
code /
blog
PointTAD effectively tackles multi-label TAD by introducing a set of learnable query points to represent the action keyframes.
|
|
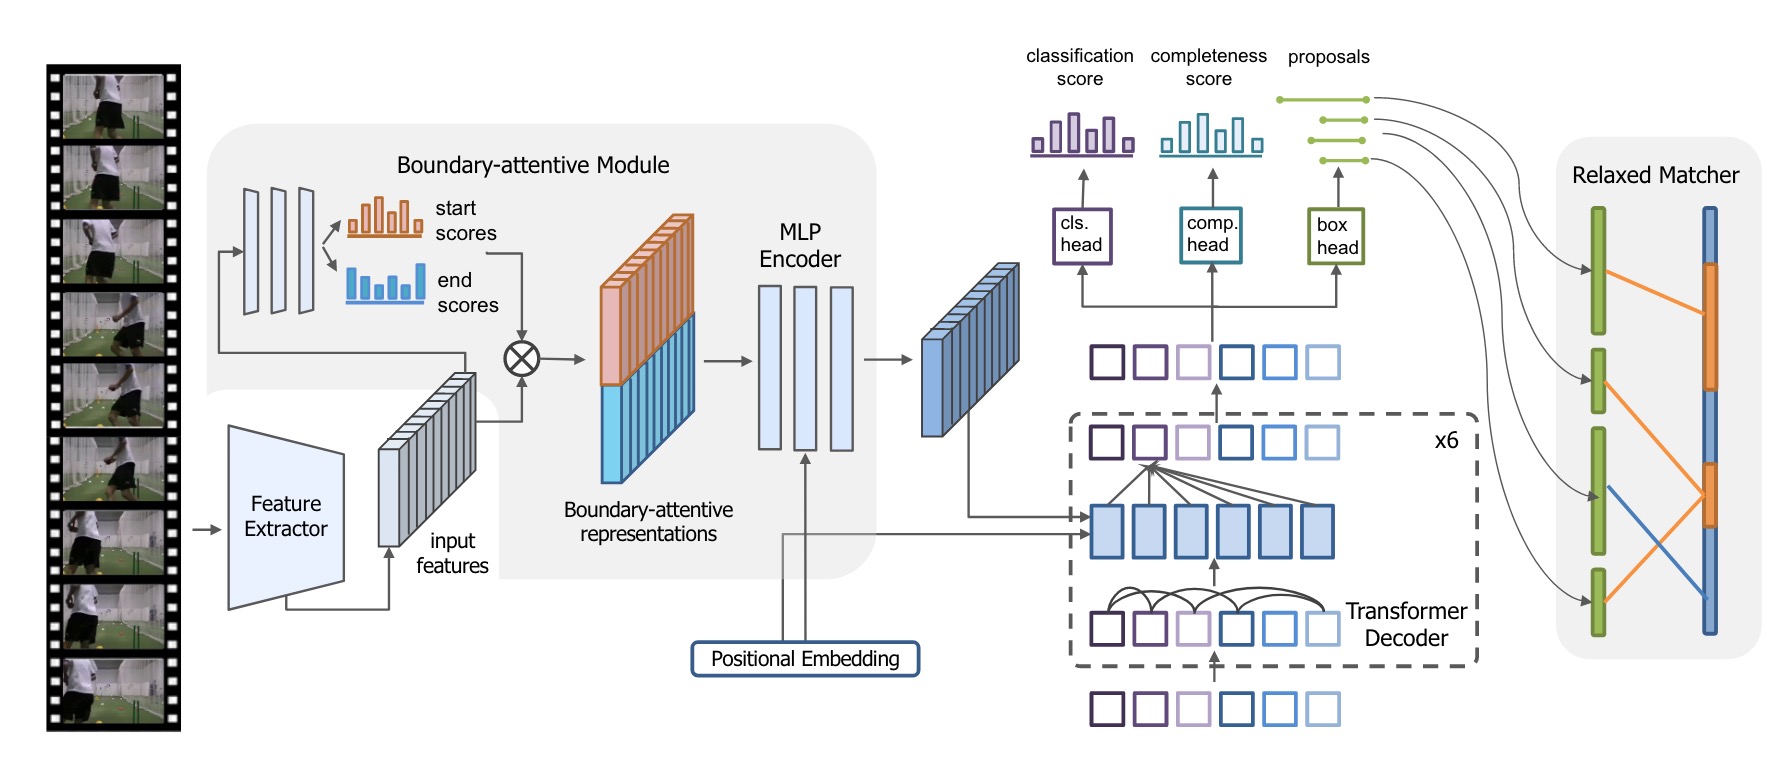
Relaxed Transformer Decoders for Direct Action Proposal Generation
Jing Tan*,
Jiaqi Tang*,
Limin Wang,
Gangshan Wu
ICCV, 2021 (* equal contribution)
pdf /
code /
blog
The first transformer-based framework for temporal action proposal generation.
|
Here are some collaborative works on 3D object generation and video generation related topics.
|
|
HumanVid: Demystifying Training Data for Camera-controllable Human Image Animation
Zhenzhi Wang,
Yixuan Li,
Yanhong Zeng,
Youqing Fang,
Yuwei Guo,
Wenran Liu,
Jing Tan,
Kai Chen,
Tianfan Xue,
Bo Dai,
Dahua Lin
NeurIPS D&B Track, 2024
project page /
arXiv /
code
Camera-controllable human image animation dataset and framework.
|
Experience
|
AWS Agentic AI
Applied Scientist Intern
June 2025 – Nov. 2025
Bellevue, WA, US
|
-
Conducted research in collaboration with
Prof. Zhuowen Tu and
Prof. Jiajun Wu
on reinforcement learning–guided spatial-aware image editing,
with Yantao Shen
as the internship manager.
-
Leveraged RLVR to enable precise geometric object transformations
in images following text instructions.
|
Tencent, PCG
Research Intern
Dec. 2021 – Mar. 2023
Beijing, China
|
- Worked on multi-label temporal action detection via learnable query points.
-
Developed a more general video action detection framework capable of
localizing specific actions among multiple simultaneous actions.
|
Selected Honors & Awards
- CSIG Master’s Thesis Incentive Program Awardee, China Society of Image and Graphics, 2025
- Outstanding Master’s Thesis Award (3/226), Nanjing University, 2024
- National Scholarship (6/226), Ministry of Education of China, 2022
- 3rd Place, GEBD-LOVEU Challenge @ CVPR Workshop, 2022
|
Academic Services
-
Regular Conference reviewer for CVPR, ICCV, ECCV, NeurIPS, ICML, ICLR; Reviewer for SIGGRAPH 2025.
-
Journal reviewer for IJCV and TIP.
-
Teaching Assistant for
IERG4998
and
IERG4999
at CUHK.
|
|