GeezerVisonThe World Wide Web, restored to 800 pixels of glory. |
| Home|About|Gaming cabinet|Archives|How it works|Starter sites |
GeezerVison is showing www.fullstackpython.com — Exporting pandas DataFrames into SQLite with SQLAlchemy Exporting pandas DataFrames into SQLite with SQLAlchemy
Posted by
Matt Makai on March 30, 2020.
It is common when performing exploratory data analysis, for example when examining COVID-19 data with pandas, to load from files like a CSV, XML, or JSON into a pandas DataFrame. You may then do some work with the data in the DataFrame and want to store it in a more durable location like a relational database. This tutorial walks through how to load a pandas DataFrame from a CSV file, pull out some data from the full data set, then save the subset of data to a SQLite database using SQLAlchemy. Configuring our development environmentMake sure you have Python 3 installed. As of right now, Python 3.8.2 is the latest version of Python. During this tutorial we're also going to use:
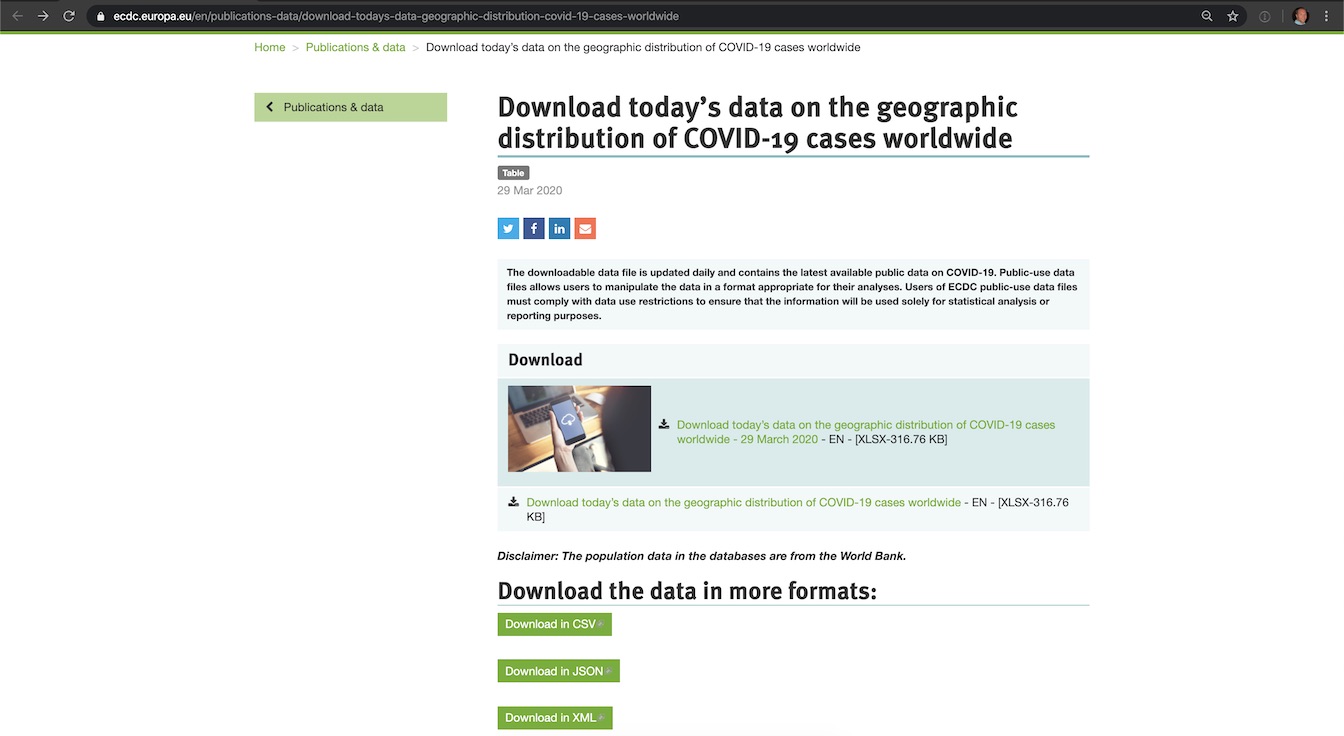
Install the above code libraries into a new Python virtual environment using the following commands: python -m venv pandasexport source pandasexport/bin/activate pip install pandas==1.0.3 sqlalchemy==1.3.15 Our development environment is now ready to download an example COVID-19 data set, load it into a pandas DataFrame, perform some analysis on it then save into a SQLite database. Obtaining COVID-19 dataGo to the download today’s data on the geographic distribution of COVID-19 cases worldwide page in your web browser. It should look something like the following screenshot.
There should be a link to download the data in CSV format, but the organization has changed the page layout several times in the past few weeks, which makes it difficult to find formats other than Excel (XLSX). If you have trouble obtaining the CSV version, just download this one from GitHub which is pegged to a copy downloaded on March 28th, 2020. Importing the CSV into pandasThe raw data is in a CSV file and we need to load it into memory via a pandas DataFrame. Start by running the Python Read-Evaluate-Print Loop (REPL) on the command line: python >>> The REPL is ready to execute code, but we first need to import the pandas library so we can use it. from pandas import read_csv
df = read_csv("covid-19-cases-march-28-2020.csv", encoding="ISO-8859-1")
The data is now loaded into the When we run the df.count() Next, we'll take this set of 7320 rows of data and slice out only the rows that pertain to the United States. Creating a new DataFrame from the original DataFrameWe can pick out all of the rows of data for a single country using
a pandas function to match the save_df = df[df['countriesAndTerritories']=="United_States_of_America"] The save_df You should see something like the following output: dateRep day month year cases deaths countriesAndTerritories geoId countryterritoryCode popData2018 7082 28/03/2020 28 3 2020 18695 411 United_States_of_America US USA 327167434.0 7083 27/03/2020 27 3 2020 16797 246 United_States_of_America US USA 327167434.0 7084 26/03/2020 26 3 2020 13963 249 United_States_of_America US USA 327167434.0 7085 25/03/2020 25 3 2020 8789 211 United_States_of_America US USA 327167434.0 7086 24/03/2020 24 3 2020 11236 119 United_States_of_America US USA 327167434.0 ... ... ... ... ... ... ... ... ... ... ... 7166 04/01/2020 4 1 2020 0 0 United_States_of_America US USA 327167434.0 7167 03/01/2020 3 1 2020 0 0 United_States_of_America US USA 327167434.0 7168 02/01/2020 2 1 2020 0 0 United_States_of_America US USA 327167434.0 7169 01/01/2020 1 1 2020 0 0 United_States_of_America US USA 327167434.0 7170 31/12/2019 31 12 2019 0 0 United_States_of_America US USA 327167434.0 [89 rows x 10 columns] 89 rows of data out of the original 7320 rows. Let's proceed with saving this subset to a SQLite relational database. Saving the DataFrame to SQLiteWe are going to use SQLAlchemy to create a connection
to a new SQLite database, which in this example will be stored in file
named Start by importing the from sqlalchemy import create_engine Create the connection using the imported engine = create_engine('sqlite:///save_pandas.db', echo=True)
sqlite_connection = engine.connect()
We set 2020-03-29 20:44:08,198 INFO sqlalchemy.engine.base.Engine SELECT CAST('test plain returns' AS VARCHAR(60)) AS anon_1 2020-03-29 20:44:08,198 INFO sqlalchemy.engine.base.Engine () 2020-03-29 20:44:08,199 INFO sqlalchemy.engine.base.Engine SELECT CAST('test unicode returns' AS VARCHAR(60)) AS anon_1 2020-03-29 20:44:08,199 INFO sqlalchemy.engine.base.Engine () <sqlalchemy.engine.base.Connection object at 0x7fd4d932ec88> Set a variable name with the string of a table name you would like
to create. Then use that variable when invoking the Note that in this case we are going to fail if the table already
exists in the database. You can change sqlite_table = "Covid19" save_df.to_sql(sqlite_table, sqlite_connection, if_exists='fail') The echo output should spin up with a bunch of output. 2020-03-29 20:45:09,066 INFO sqlalchemy.engine.base.Engine PRAGMA main.table_info("Covid19") 2020-03-29 20:45:09,066 INFO sqlalchemy.engine.base.Engine () 2020-03-29 20:45:09,067 INFO sqlalchemy.engine.base.Engine PRAGMA temp.table_info("Covid19") 2020-03-29 20:45:09,067 INFO sqlalchemy.engine.base.Engine () 2020-03-29 20:45:09,069 INFO sqlalchemy.engine.base.Engine CREATE TABLE "Covid19" ( "index" BIGINT, "dateRep" TEXT, day BIGINT, month BIGINT, year BIGINT, cases BIGINT, deaths BIGINT, "countriesAndTerritories" TEXT, "geoId" TEXT, "countryterritoryCode" TEXT, "popData2018" FLOAT ) 2020-03-29 20:45:09,069 INFO sqlalchemy.engine.base.Engine () 2020-03-29 20:45:09,070 INFO sqlalchemy.engine.base.Engine COMMIT 2020-03-29 20:45:09,070 INFO sqlalchemy.engine.base.Engine CREATE INDEX "ix_Covid19_index" ON "Covid19" ("index") 2020-03-29 20:45:09,070 INFO sqlalchemy.engine.base.Engine () 2020-03-29 20:45:09,071 INFO sqlalchemy.engine.base.Engine COMMIT 2020-03-29 20:45:09,072 INFO sqlalchemy.engine.base.Engine BEGIN (implicit) 2020-03-29 20:45:09,074 INFO sqlalchemy.engine.base.Engine INSERT INTO "Covid19" ("index", "dateRep", day, month, year, cases, deaths, "countriesAndTerritories", "geoId", "countryterritoryCode", "popData2018") VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?) 2020-03-29 20:45:09,074 INFO sqlalchemy.engine.base.Engine ((7082, '28/03/2020', 28, 3, 2020, 18695, 411, 'United_States_of_America', 'US', 'USA', 327167434.0), (7083, '27/03/2020', 27, 3, 2020, 16797, 246, 'United_States_of_America', 'US', 'USA', 327167434.0), (7084, '26/03/2020', 26, 3, 2020, 13963, 249, 'United_States_of_America', 'US', 'USA', 327167434.0), (7085, '25/03/2020', 25, 3, 2020, 8789, 211, 'United_States_of_America', 'US', 'USA', 327167434.0), (7086, '24/03/2020', 24, 3, 2020, 11236, 119, 'United_States_of_America', 'US', 'USA', 327167434.0), (7087, '23/03/2020', 23, 3, 2020, 8459, 131, 'United_States_of_America', 'US', 'USA', 327167434.0), (7088, '22/03/2020', 22, 3, 2020, 7123, 80, 'United_States_of_America', 'US', 'USA', 327167434.0), (7089, '21/03/2020', 21, 3, 2020, 5374, 110, 'United_States_of_America', 'US', 'USA', 327167434.0) ... displaying 10 of 89 total bound parameter sets ... (7169, '01/01/2020', 1, 1, 2020, 0, 0, 'United_States_of_America', 'US', 'USA', 327167434.0), (7170, '31/12/2019', 31, 12, 2019, 0, 0, 'United_States_of_America', 'US', 'USA', 327167434.0)) 2020-03-29 20:45:09,074 INFO sqlalchemy.engine.base.Engine COMMIT 2020-03-29 20:45:09,075 INFO sqlalchemy.engine.base.Engine SELECT name FROM sqlite_master WHERE type='table' ORDER BY name 2020-03-29 20:45:09,075 INFO sqlalchemy.engine.base.Engine () Our table with all of its data should now be all set. Close the database connection. sqlite_connection.close() We can take a look at the data through the On the command line (not in the Python REPL), type: sqlite3 This will open up the command line prompt to interact with SQLite
databases. However, we are not yet connected to our SQLite version 3.28.0 2019-04-15 14:49:49 Enter ".help" for usage hints. Connected to a transient in-memory database. Use ".open FILENAME" to reopen on a persistent database. sqlite> Use the sqlite> .open save_pandas.db sqlite> select * from Covid19; The SQLite explorer should produce output like you see below: 7082|28/03/2020|28|3|2020|18695|411|United_States_of_America|US|USA|327167434.0 7083|27/03/2020|27|3|2020|16797|246|United_States_of_America|US|USA|327167434.0 7084|26/03/2020|26|3|2020|13963|249|United_States_of_America|US|USA|327167434.0 7085|25/03/2020|25|3|2020|8789|211|United_States_of_America|US|USA|327167434.0 7086|24/03/2020|24|3|2020|11236|119|United_States_of_America|US|USA|327167434.0 7087|23/03/2020|23|3|2020|8459|131|United_States_of_America|US|USA|327167434.0 7088|22/03/2020|22|3|2020|7123|80|United_States_of_America|US|USA|327167434.0 7089|21/03/2020|21|3|2020|5374|110|United_States_of_America|US|USA|327167434.0 7090|20/03/2020|20|3|2020|4835|0|United_States_of_America|US|USA|327167434.0 7091|19/03/2020|19|3|2020|2988|42|United_States_of_America|US|USA|327167434.0 7092|18/03/2020|18|3|2020|1766|23|United_States_of_America|US|USA|327167434.0 7093|17/03/2020|17|3|2020|887|16|United_States_of_America|US|USA|327167434.0 7094|16/03/2020|16|3|2020|823|12|United_States_of_America|US|USA|327167434.0 7095|15/03/2020|15|3|2020|777|10|United_States_of_America|US|USA|327167434.0 7096|14/03/2020|14|3|2020|511|7|United_States_of_America|US|USA|327167434.0 7097|13/03/2020|13|3|2020|351|10|United_States_of_America|US|USA|327167434.0 7098|12/03/2020|12|3|2020|287|2|United_States_of_America|US|USA|327167434.0 7099|11/03/2020|11|3|2020|271|2|United_States_of_America|US|USA|327167434.0 7100|10/03/2020|10|3|2020|200|5|United_States_of_America|US|USA|327167434.0 7101|09/03/2020|9|3|2020|121|4|United_States_of_America|US|USA|327167434.0 7102|08/03/2020|8|3|2020|95|3|United_States_of_America|US|USA|327167434.0 7103|07/03/2020|7|3|2020|105|2|United_States_of_America|US|USA|327167434.0 7104|06/03/2020|6|3|2020|74|1|United_States_of_America|US|USA|327167434.0 7105|05/03/2020|5|3|2020|34|2|United_States_of_America|US|USA|327167434.0 7106|04/03/2020|4|3|2020|22|3|United_States_of_America|US|USA|327167434.0 7107|03/03/2020|3|3|2020|14|4|United_States_of_America|US|USA|327167434.0 7108|02/03/2020|2|3|2020|20|1|United_States_of_America|US|USA|327167434.0 7109|01/03/2020|1|3|2020|3|1|United_States_of_America|US|USA|327167434.0 7110|29/02/2020|29|2|2020|6|0|United_States_of_America|US|USA|327167434.0 7111|28/02/2020|28|2|2020|1|0|United_States_of_America|US|USA|327167434.0 7112|27/02/2020|27|2|2020|6|0|United_States_of_America|US|USA|327167434.0 7113|26/02/2020|26|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7114|25/02/2020|25|2|2020|18|0|United_States_of_America|US|USA|327167434.0 7115|24/02/2020|24|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7116|23/02/2020|23|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7117|22/02/2020|22|2|2020|19|0|United_States_of_America|US|USA|327167434.0 7118|21/02/2020|21|2|2020|1|0|United_States_of_America|US|USA|327167434.0 7119|20/02/2020|20|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7120|19/02/2020|19|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7121|18/02/2020|18|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7122|17/02/2020|17|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7123|16/02/2020|16|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7124|15/02/2020|15|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7125|14/02/2020|14|2|2020|1|0|United_States_of_America|US|USA|327167434.0 7126|13/02/2020|13|2|2020|1|0|United_States_of_America|US|USA|327167434.0 7127|12/02/2020|12|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7128|11/02/2020|11|2|2020|1|0|United_States_of_America|US|USA|327167434.0 7129|10/02/2020|10|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7130|09/02/2020|9|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7131|08/02/2020|8|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7132|07/02/2020|7|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7133|06/02/2020|6|2|2020|1|0|United_States_of_America|US|USA|327167434.0 7134|05/02/2020|5|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7135|04/02/2020|4|2|2020|0|0|United_States_of_America|US|USA|327167434.0 7136|03/02/2020|3|2|2020|3|0|United_States_of_America|US|USA|327167434.0 7137|02/02/2020|2|2|2020|1|0|United_States_of_America|US|USA|327167434.0 7138|01/02/2020|1|2|2020|1|0|United_States_of_America|US|USA|327167434.0 7139|31/01/2020|31|1|2020|1|0|United_States_of_America|US|USA|327167434.0 7140|30/01/2020|30|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7141|29/01/2020|29|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7142|28/01/2020|28|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7143|27/01/2020|27|1|2020|3|0|United_States_of_America|US|USA|327167434.0 7144|26/01/2020|26|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7145|25/01/2020|25|1|2020|1|0|United_States_of_America|US|USA|327167434.0 7146|24/01/2020|24|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7147|23/01/2020|23|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7148|22/01/2020|22|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7149|21/01/2020|21|1|2020|1|0|United_States_of_America|US|USA|327167434.0 7150|20/01/2020|20|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7151|19/01/2020|19|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7152|18/01/2020|18|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7153|17/01/2020|17|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7154|16/01/2020|16|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7155|15/01/2020|15|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7156|14/01/2020|14|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7157|13/01/2020|13|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7158|12/01/2020|12|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7159|11/01/2020|11|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7160|10/01/2020|10|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7161|09/01/2020|9|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7162|08/01/2020|8|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7163|07/01/2020|7|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7164|06/01/2020|6|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7165|05/01/2020|5|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7166|04/01/2020|4|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7167|03/01/2020|3|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7168|02/01/2020|2|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7169|01/01/2020|1|1|2020|0|0|United_States_of_America|US|USA|327167434.0 7170|31/12/2019|31|12|2019|0|0|United_States_of_America|US|USA|327167434.0 sqlite> All of the data with the What's Next?We just imported data from a CSV into a pandas DataFrame, selected a subset of that data then saved it to a relational database. You should take a look at the Learning pandas by Exploring COVID-19 Data tutorial to learn more about how to select subsets of data from a larger DataFrame, or head to the pandas page for more tutorials by the rest of the Python community. You can also get an idea of what to code next in your Python project by reading the Full Stack Python table of contents page. Questions? Contact me via Twitter @fullstackpython or @mattmakai. I'm also on GitHub with the username mattmakai. Something wrong with this post? Fork this page's source on GitHub and submit a pull request. |
| You are visitor 01402503 — GeezerVison does not store the pages you look up. Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required. |