GeezerVisonThe World Wide Web, restored to 800 pixels of glory. |
| Home|About|Gaming cabinet|Archives|How it works|Starter sites |
GeezerVison is showing x-decoder-vl.github.io — Towards a Generalized Multi-Modal Foundation Model Towards a Generalized Multimodal Foundation Model
Along the track of X-Decoder, SEEM, and FIND, our goal is to build a foundation model that extendable to a wide range of vision and vision-language tasks without any overhead!
X-Decoder (CVPR 2023)"Generalized Decoding for Pixel, Image, and Language" [1] shortened as X-Decoder is a generalized decoding system that is applicable to various vision-language tasks with a unified architecture. The input and output modalities spans vision-language while the granularity spans pixel-image. 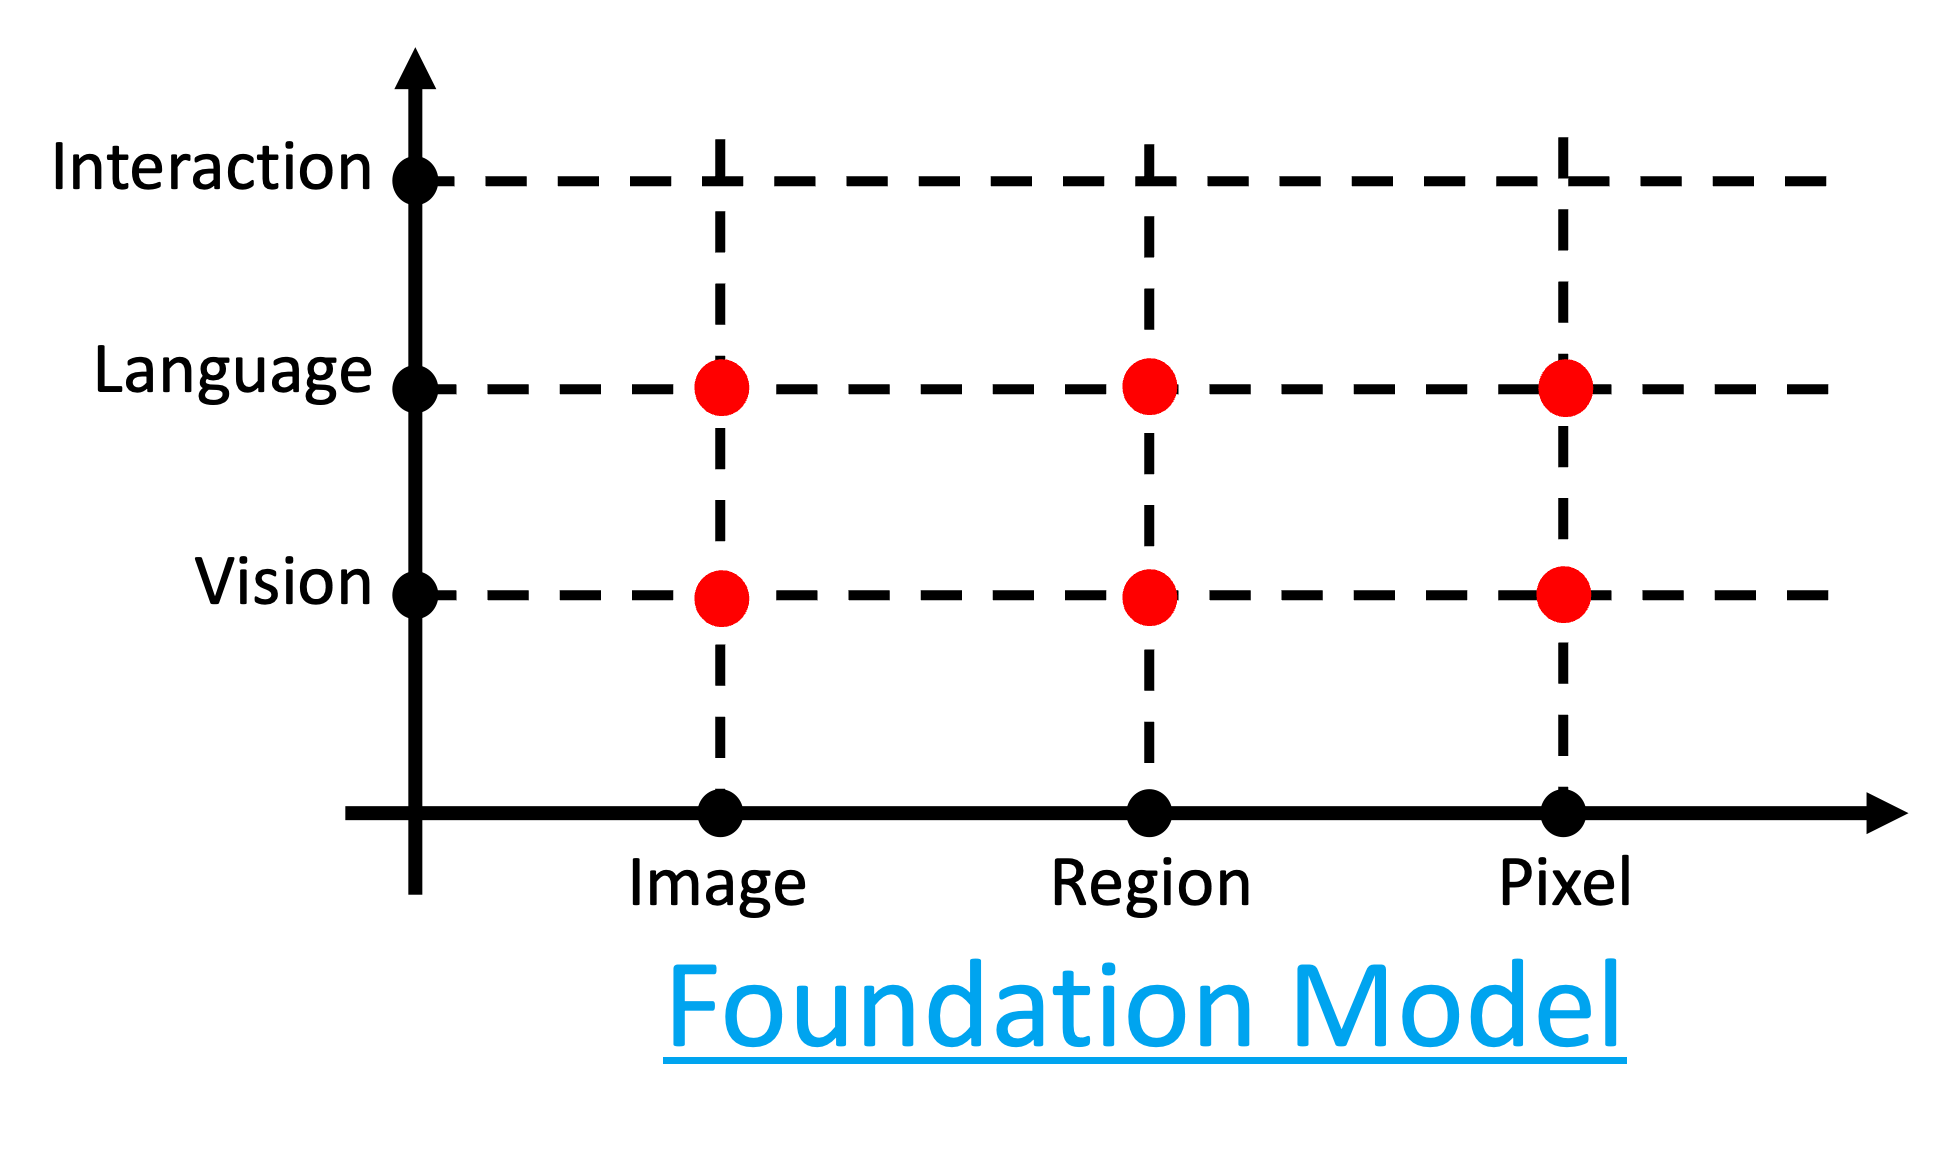
SEEM (NeurIPS 2023)"Segment Everything Everywhere All-at-Once" [2] denoted as SEEM in extending X-Decoder with human interaction capability, where human can refer a segment with scribble, box, point, and etc. Meanwhile, it accepts prompts span vision-language in a composite manner. 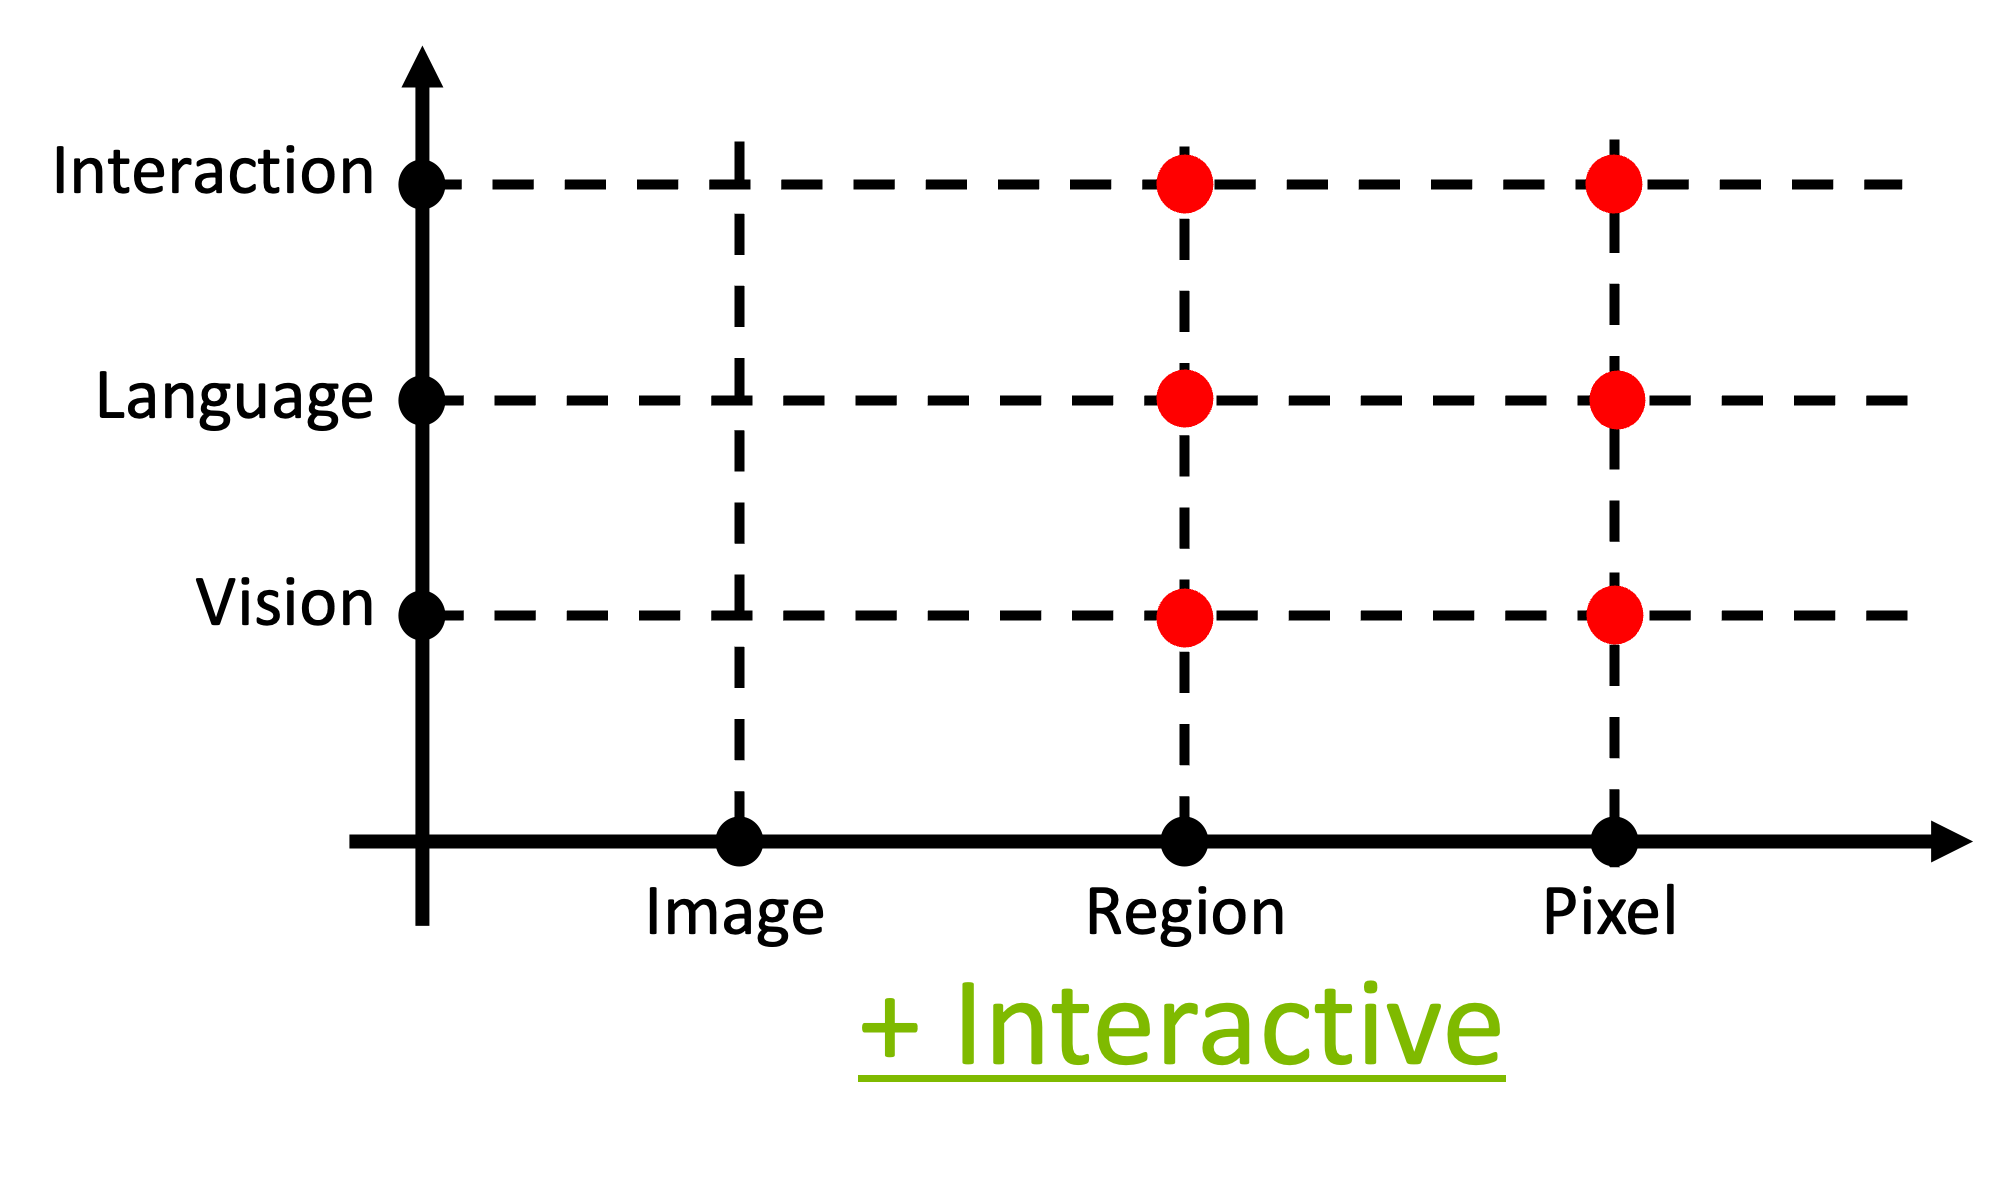
FIND (New!)"Interfacing Foundation Models' Embeddings" denoted as FIND introduces a generalized interface for foundation models. It aligns an embedding space with interleaved reasoning capability for pretrained-and-fixed foundation models (e.g. X-Decoder, UniCL, SAM, LLaMA). 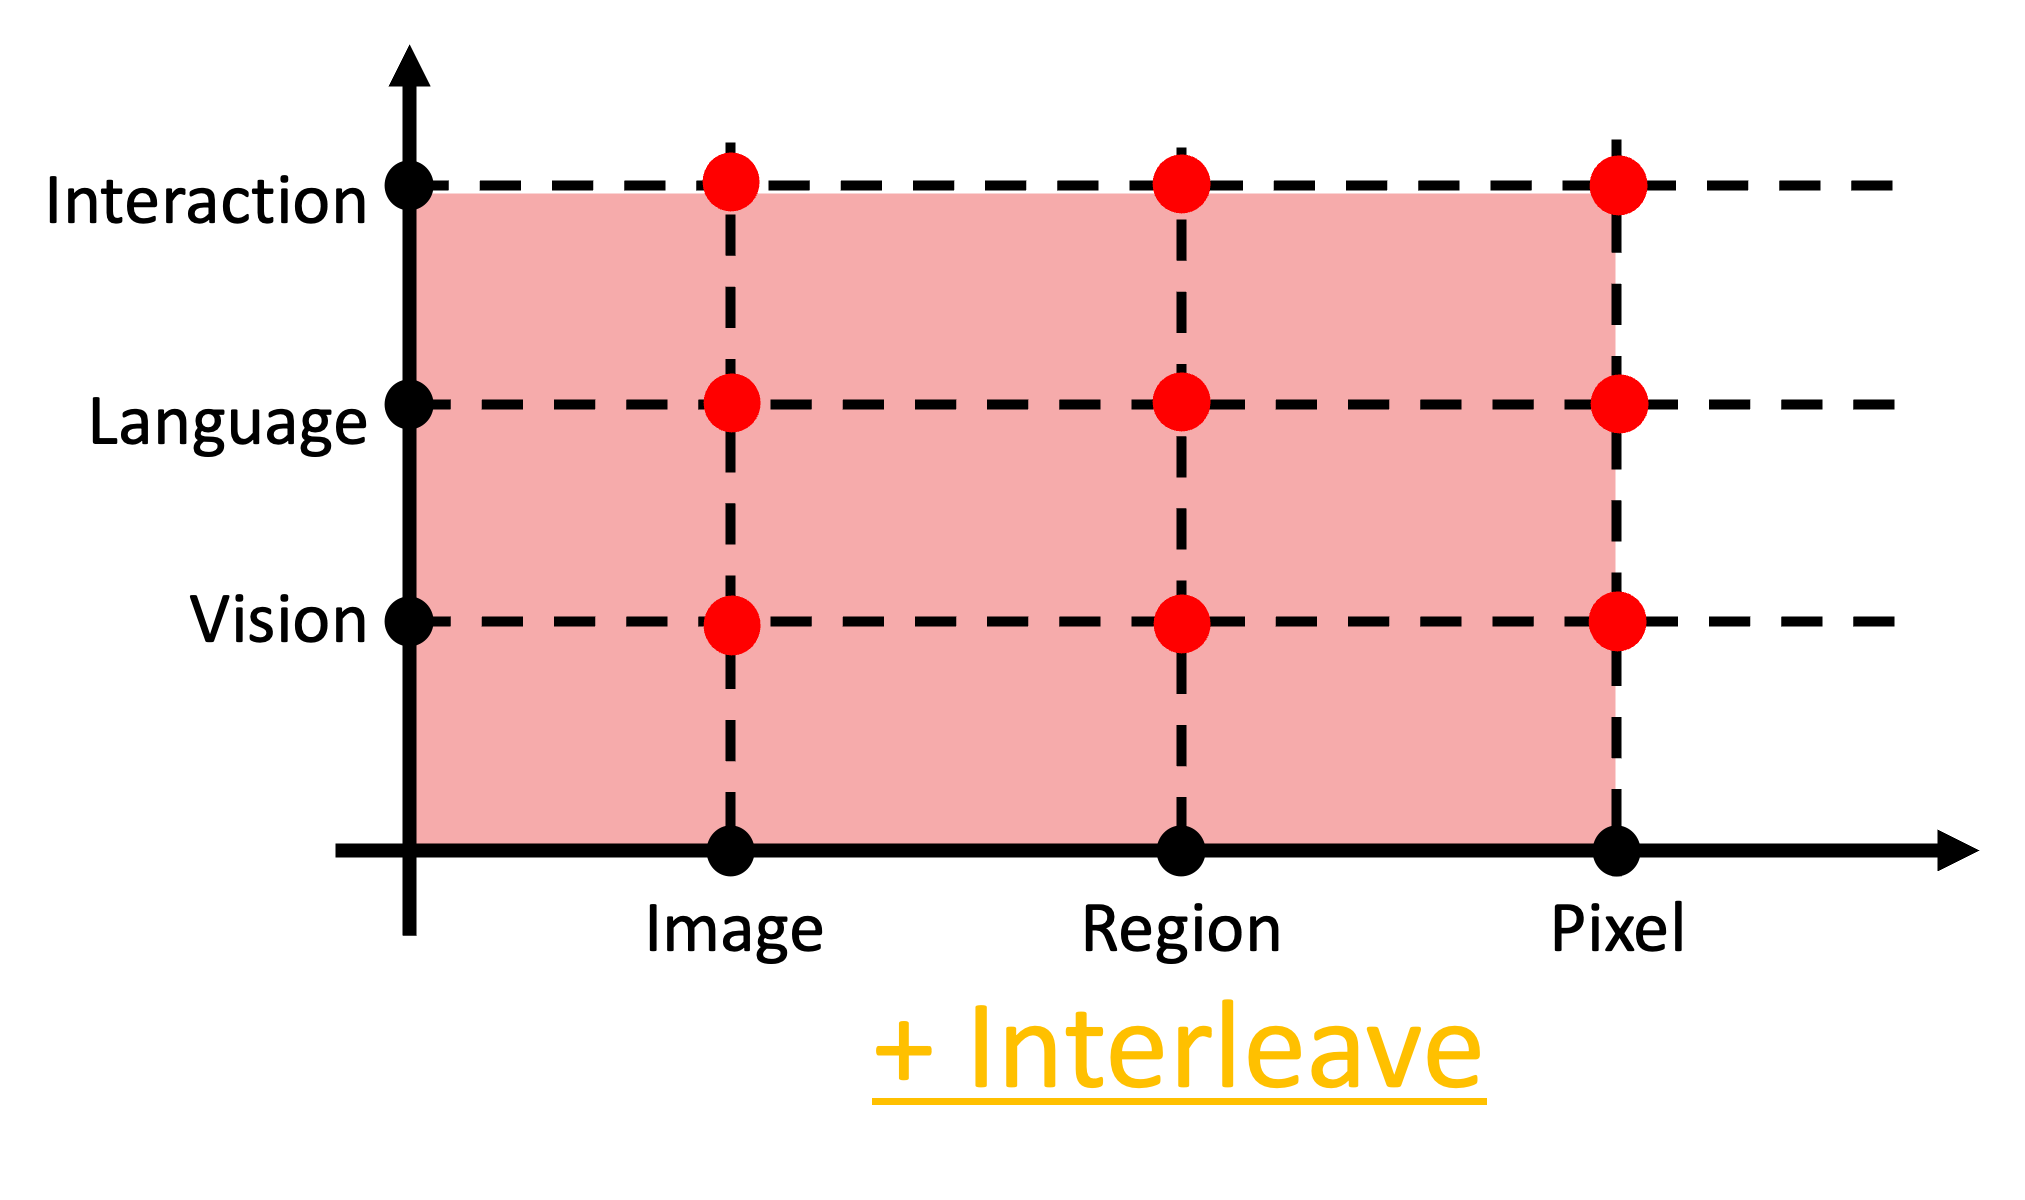
▶ FIND

FIND interfacing foundation models for an interleaved embedding space.
▶ SEEM
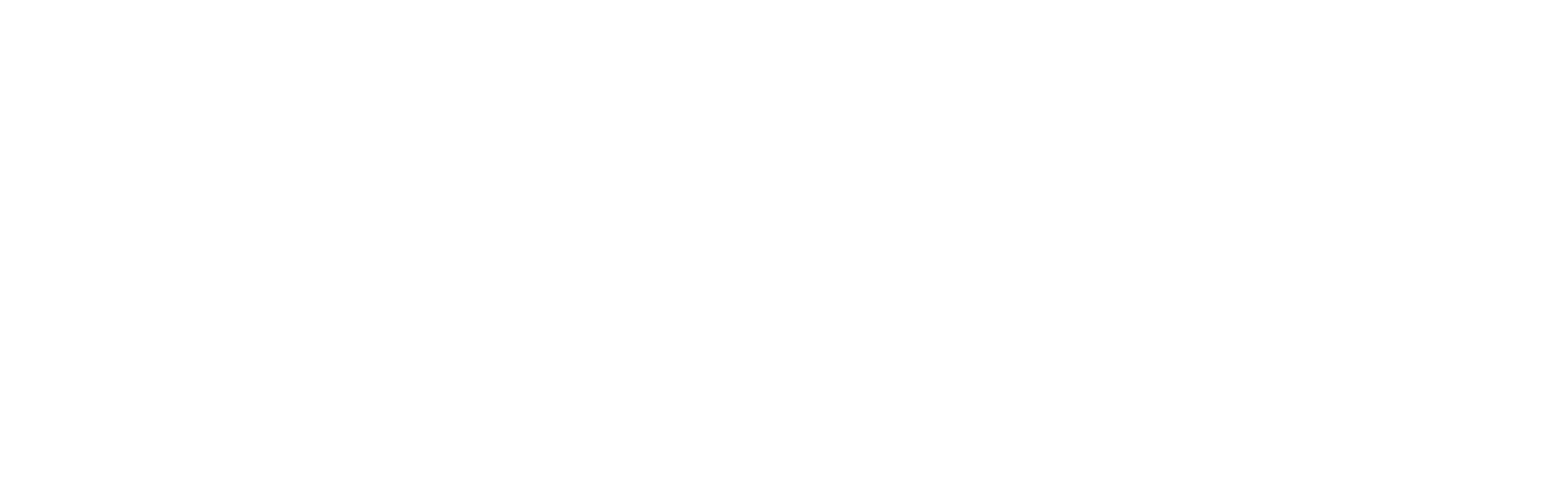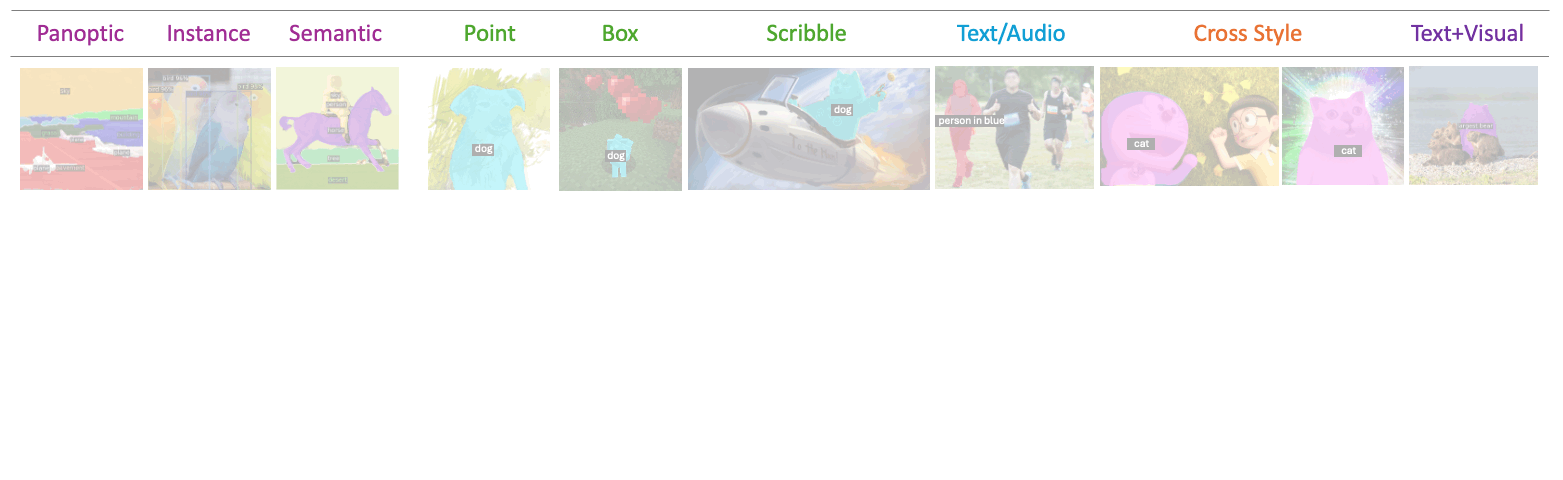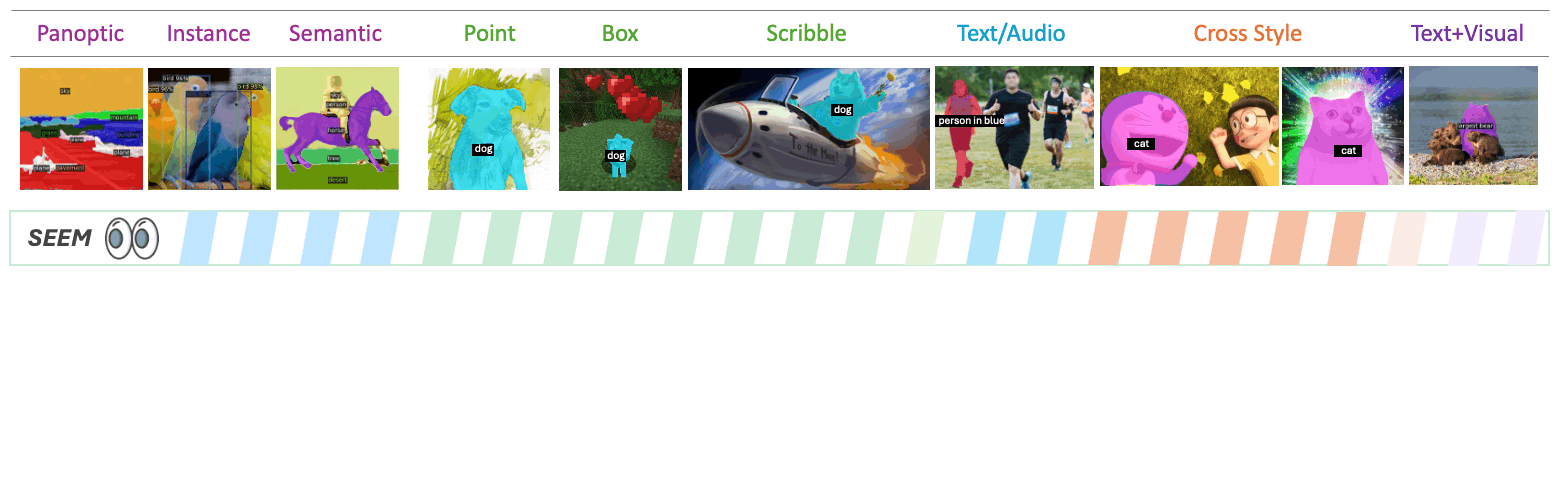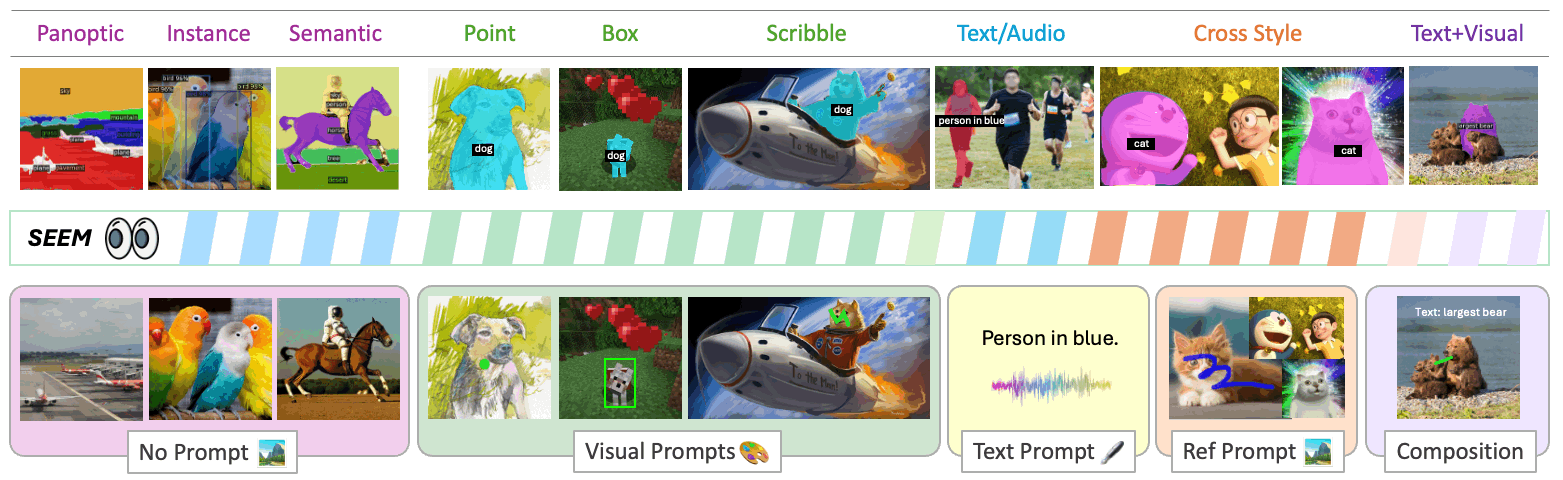
SEEM supports a wide range of prompt types including text, scribble, ref-image, and etc.
▶ X-Deocder

X-Decoder is a single model trained to support a wide range of vision and vision-language tasks. BibTeXAcknowledgementThis website is adapted from Nerfies, licensed under a Creative Commons Attribution-ShareAlike 4.0 International License. |
| You are visitor 01402503 — GeezerVison does not store the pages you look up. Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required. |