GeezerVisonThe World Wide Web, restored to 800 pixels of glory. | ||||||||||||||||||||||||
| Home|About|Gaming cabinet|Archives|How it works|Starter sites | ||||||||||||||||||||||||
GeezerVison is showing computingforgeeks.com — Qdrant REST API and gRPC Client Guide | ComputingForGeeks Qdrant exposes the same operations through two protocols. REST lives on port 6333 and is what every browser, every curl one-liner, and every monitoring dashboard speaks. gRPC lives on port 6334 and is what production services reach for when latency budgets are tight. Both share the same storage, the same query semantics, and the same auth model. The question is which one to use where and how to wire them up correctly. If you are running Python on the client side, a recent Python install on Ubuntu is the only base requirement; the SDK pulls everything else. Original content from computingforgeeks.com - post 168068This guide walks the full surface area on a real Qdrant 1.18.1 cluster with API key auth enabled. Every command was executed against a live node, every latency number is a real measurement, and every gotcha came up during testing. By the end you will have working REST examples with curl, a Python async client, a native Python gRPC stub, and a Go client running against the same data. Tested May 2026 on Ubuntu 24.04.4 LTS with Qdrant 1.18.1, qdrant-client 1.18.0, Go 1.22.2, grpcio 1.80. When to pick REST vs gRPCThe two protocols are not interchangeable in performance characteristics. REST goes over HTTP/1.1 with JSON bodies. Every request opens (or reuses) a TCP+TLS connection, serializes JSON, and parses JSON on the way back. gRPC rides HTTP/2 with binary protobuf payloads, multiplexes many calls on one connection, and avoids JSON entirely.
Use REST for ad-hoc exploration, dashboards, debugging from a shell, and any service that needs to be language-agnostic. Use gRPC for ingestion services that push millions of points, latency-sensitive inference paths, and Go or Rust callers that prefer typed clients over JSON wrangling. Cluster setup with API key authThe test cluster runs Qdrant 1.18.1 in Docker on a single Ubuntu 24.04 host, listening on both ports with an API key enforced. Replicate this on your own box before running the examples: Once the container is up, prove that the API key is actually enforced. A request without the header gets rejected, the same request with it goes through: The same key authorizes both protocols. On REST the key travels in the Collections: create, list, get, delete via RESTPin the values that repeat across every command into shell variables. Change them in one place and paste the rest as-is: Create a collection with a single 384-dim Cosine vector: The response confirms the create with an operation status. The wall time is measured by the server, not the client: List collections, then inspect the new one. Notice that The detail call answers three questions at once: is the collection healthy (status), how big is it (points_count), and what does its config say (vector size, distance, shard count). Use this in monitoring scripts. Points: upsert, batch, retrieve, delete via RESTUpsert sends one or more points in a single request. Pass Qdrant returns an operation id you can use to poll asynchronous status. With One real ceiling worth knowing: the REST endpoint rejects payloads larger than 32 MiB. A 5,000-point batch of 384-dim float vectors plus a payload comes out to roughly 37 MB of JSON and fails with Retrieve specific points by id, then count exact totals: Delete by filter is one of the operations that surprise newcomers. Instead of building an id list yourself, hand Qdrant a payload filter and let the server enumerate the matches. The example below drops every point with price under 20: A real query call from the same shell, with payload-only response shape and a 10-call latency probe, looks like this on the terminal:  Search with query_points (the modern API)The The Qdrant Web UI Console reaches the same endpoint with the same body. Open 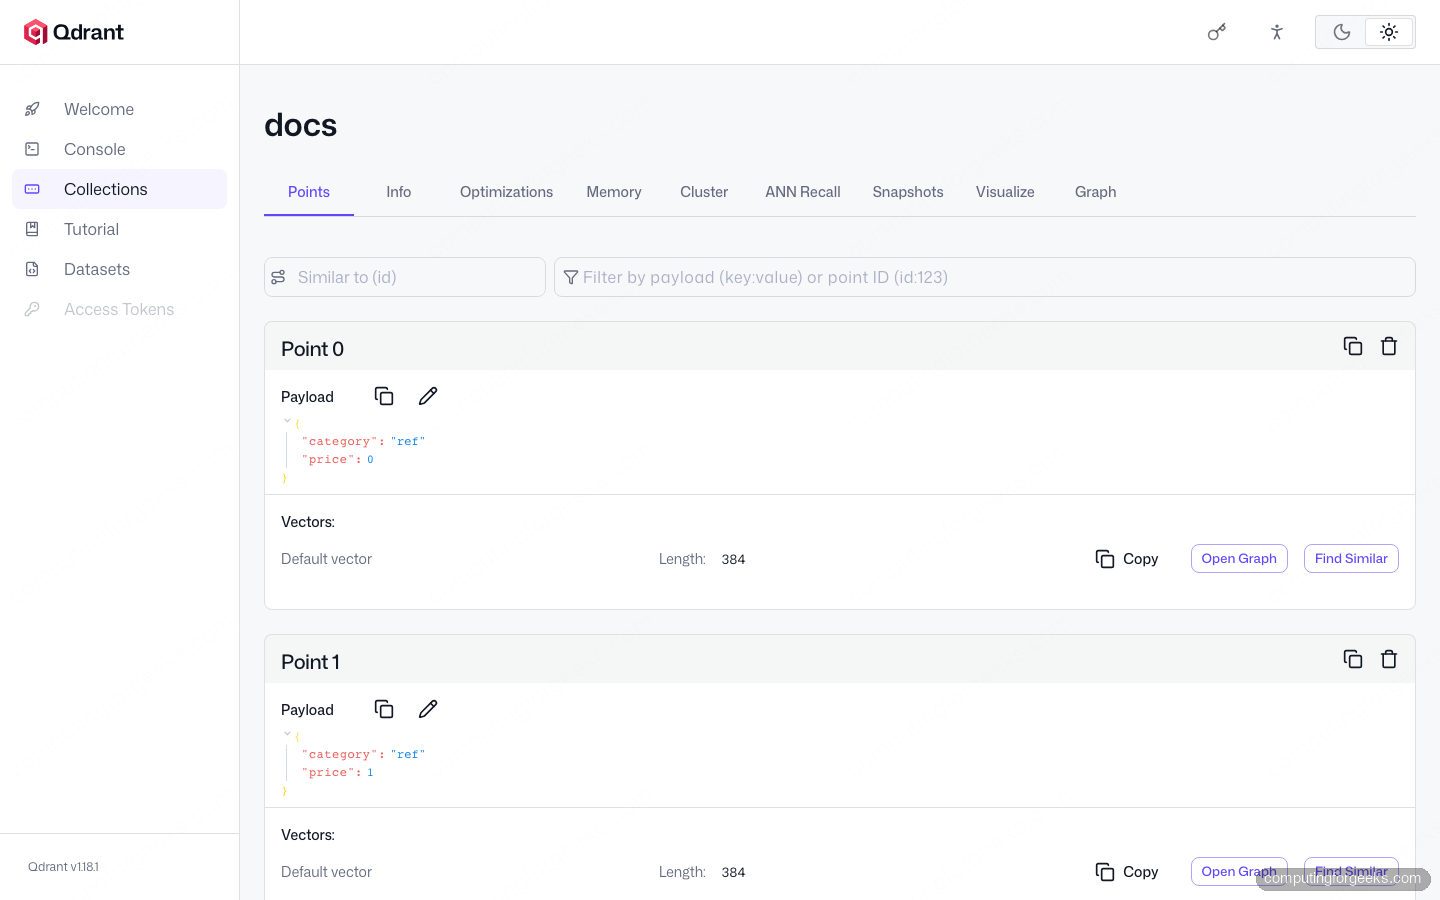 The other read endpoint is Snapshots and cluster status via RESTTrigger a snapshot of one collection, then list existing snapshots. The name is generated by the server and includes a timestamp, so save it from the create response if you intend to download it later: The cluster endpoint reports whether distributed mode is on. A single-node deployment returns Python async REST client with real timingFor application code the Python client wraps both protocols. The async variant ( Below is the benchmark used to produce the timing numbers in this guide. It seeds a collection with 5,000 random points (in 1,000-point batches to stay under the 32 MiB JSON cap), then times 100 sequential The Run the benchmark and the timing speaks for itself. gRPC is roughly 2x faster on a single read at the p50, and the gap widens at p95: Two takeaways. First, for a single read REST is fine: 2.4 ms at the median is invisible to a human and acceptable for almost any web request. Second, with HTTP/1.1 keep-alive and async fan-out, REST still delivers 632 req/s of pure search throughput from one Python process, which is enough for most production read paths.  Native Python gRPC client (no wrapper)For low-level work the qdrant-client package ships the generated protobuf stubs. Importing them directly bypasses the high-level wrapper and gives you raw RPC calls. You need this when you want full control over channel options, deadlines, or when you are integrating into an existing gRPC service mesh: The query call uses the same nested-message structure protobuf demands. Note Real output from the cluster shows the server reporting a 0.29 ms processing time and the client measuring 0.72 ms of wall time. The gap is the gRPC layer doing its work over loopback. On a real network the gap widens but the ratio of REST to gRPC stays roughly the same. Go gRPC client with the official SDKThe Go client wraps the same generated stubs with a tighter ergonomic surface. Initialize a module and pull the SDK: The full client below creates a collection, upserts 5 points with mixed payload types (string + float), then queries with payload included. The Run it with  The Go SDK warns at startup if API key is used over a non-TLS channel. That warning is informational only on a localhost-bound test cluster, but it is a real concern in production. Always pair API key auth with TLS in any environment outside your laptop. Retry pattern and backpressureNetwork calls fail. The pattern that holds up in production is a short retry loop with exponential backoff plus jitter, scoped only to transient classes of error. Client errors (4xx) must never retry: they are bugs in your request, and hammering Qdrant with the same broken payload only fills logs. The wrapper covers the realistic failure modes: Qdrant returning a 503 during a planned restart, a transient connection reset under load, or a TCP RST from a Kubernetes pod eviction. It avoids the trap of retrying a 404 (the collection genuinely does not exist) or a 400 (the body is malformed).  For rate limiting Qdrant itself does not implement per-key quotas. You either front it with an L7 proxy (Envoy, Nginx limit_req) when you need quota enforcement, or you implement client-side concurrency caps. The simplest cap is an Gotchas worth rememberingFive real traps showed up during testing. Each one cost time to diagnose and none of them are obvious from the docs:
Choosing between protocols, one decision at a timeMost teams end up using both. REST handles operational work (curl from runbooks, dashboards, browser-based debugging). gRPC handles the read path of latency-sensitive services. Three concrete rules of thumb that hold up:
The protocols share storage, security, and semantics. The choice is purely about wire-format ergonomics versus tail latency, and every Qdrant cluster you ever touch will let you pick per-caller without code changes to the server. For an end-to-end example that ties REST queries into an Ollama LLM, see our self-hosted RAG walkthrough, which uses the same payload shapes against pgvector and translates one-for-one to Qdrant. 
Josphat Mutai
Founder of Computingforgeeks. Senior Systems Engineer with over a decade of hands-on experience building and managing production infrastructure. Core expertise in Linux/UNIX administration, cloud platforms (AWS, GCP, Azure), and Kubernetes ecosystems (EKS, GKE, OpenShift). Deep experience with virtualization (KVM, Proxmox, OpenStack), infrastructure as code (Terraform, Terragrunt, Ansible, Crossplane), GitOps workflows (ArgoCD, FluxCD), Nix/NixOS, and container orchestration at scale. Currently focused on integrating AI and LLMs into DevOps and platform engineering workflows. Every guide on this site is tested on real systems before publishing. Keep reading AI
Ollama Models Cheat Sheet: Best Models by VRAM, Tested (PDF)  AI
Open Source LLM Comparison Table (2026)  AI
Claude Code Cheat Sheet: Commands, Shortcuts and Flags (PDF)  AI
OpenClaw Security Hardening with Ollama: Sandbox, Tools, Skills  Databases
Monitor QuestDB With Prometheus and Grafana: Metrics and Alerts  Databases
Install PostgreSQL 11 on Ubuntu 22.04|20.04|18.04|16.04 Leave a Comment Cancel reply
| ||||||||||||||||||||||||
| You are visitor 01402503 — GeezerVison does not store the pages you look up. Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required. |