GeezerVisonThe World Wide Web, restored to 800 pixels of glory. |
| Home|About|Gaming cabinet|Archives|How it works|Starter sites |
GeezerVison is showing dream2flow.github.io — Dream2Flow Dream2Flow: Bridging Video Generation and Open-World Manipulation with 3D Object FlowStanford University
* Corresponding author | † Equal advising
International Conference on Robotics and Automation (ICRA) 2026
Best Paper Award at the SRRA Workshop at ICRA 2026
Dream2Flow turns generated human-object interaction videos into 3D object flow that robots can track, enabling open-world manipulation without task-specific demonstrations. AbstractGenerative video modeling has emerged as a compelling tool to zero-shot reason about plausible physical interactions for open-world manipulation. Yet, it remains a challenge to translate such human-led motions into the low-level actions demanded by robotic systems. We observe that given an initial image and task instruction, these models excel at synthesizing sensible object motions. Thus, we introduce Dream2Flow, a framework that bridges video generation and robotic control through 3D object flow as an intermediate representation. Our method reconstructs 3D object motions from generated videos and formulates manipulation as object trajectory tracking. By separating the state changes from the actuators that realize those changes, Dream2Flow overcomes the embodiment gap and enables zero-shot guidance from pre-trained video models to manipulate objects of diverse categories—including rigid, articulated, deformable, and granular. Through trajectory optimization or reinforcement learning, Dream2Flow converts reconstructed 3D object flow into executable low-level commands without task-specific demonstrations. Simulation and real-world experiments highlight 3D object flow as a general and scalable interface for adapting video generation models to open-world robotic manipulation. Walkthrough VideoGenerated Video Quality Across EmbodimentsWe compare generated video quality across different state-of-the-art video generation models and embodiments. Each column corresponds to a model with each row corresponding to a different embodiment. We notice that for certain tasks, the fine-grained interactions between robot end-effectors and the objects are not realistic and/or the robot fails to complete the task, but the object motion remains reasonable when a human performs the actions.
Kling 2.6 Reasonable Generation Robot-object penetration, no gripper motion No gripper motion Veo 3.1 Reasonable Generation Robot-object penetration, no gripper motion, morphing Gripper not open before grasp Sora 2 Reasonable Generation Task incomplete Task incomplete Dream2Flow
Click on different components to learn more about the pipeline
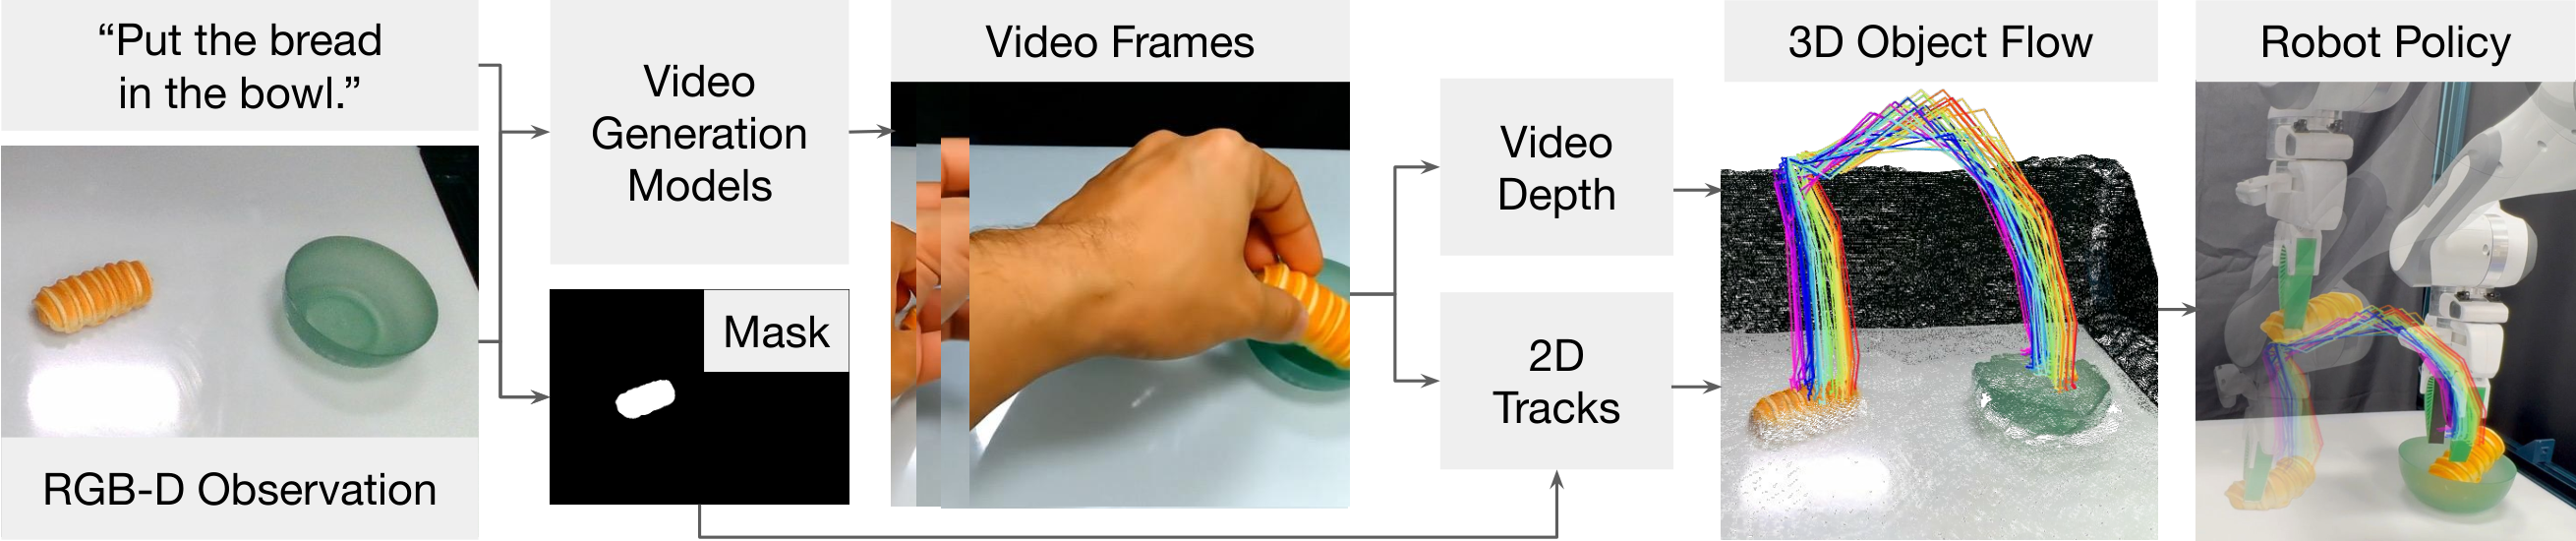
Given a task instruction and an initial RGB-D observation, an image-to-video model synthesizes video frames conditioned on the instruction. We additionally obtain object masks, video depth, and point tracking from vision foundation models, which are used to reconstruct 3D object flow. Finally, a robot policy tracks the 3D object flow to generate executable actions. ResultsInteractive 3D visualizations of object flows extracted from generated videos. Click on different thumbnails to explore different tasks and their corresponding 3D flows. 
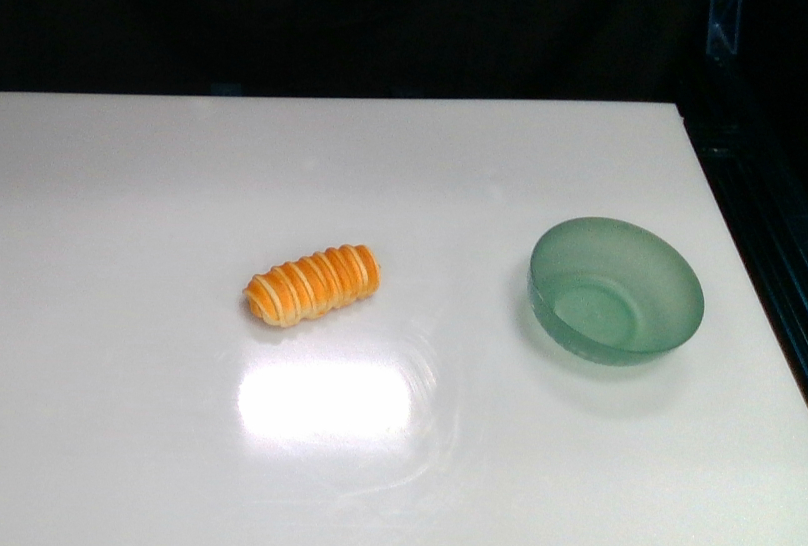
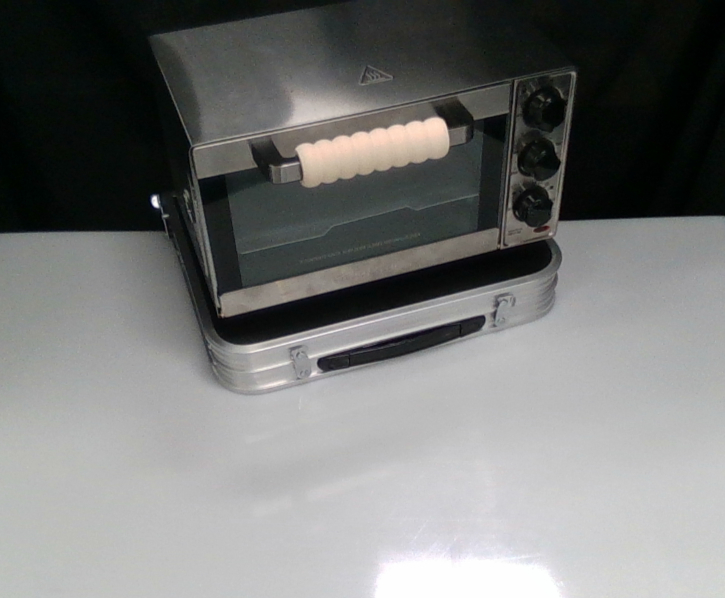
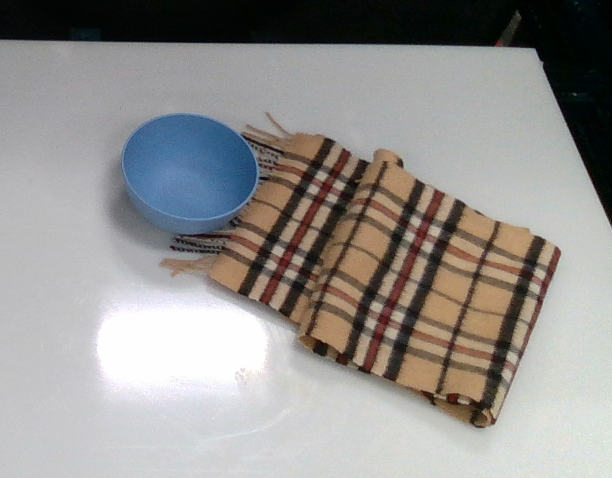
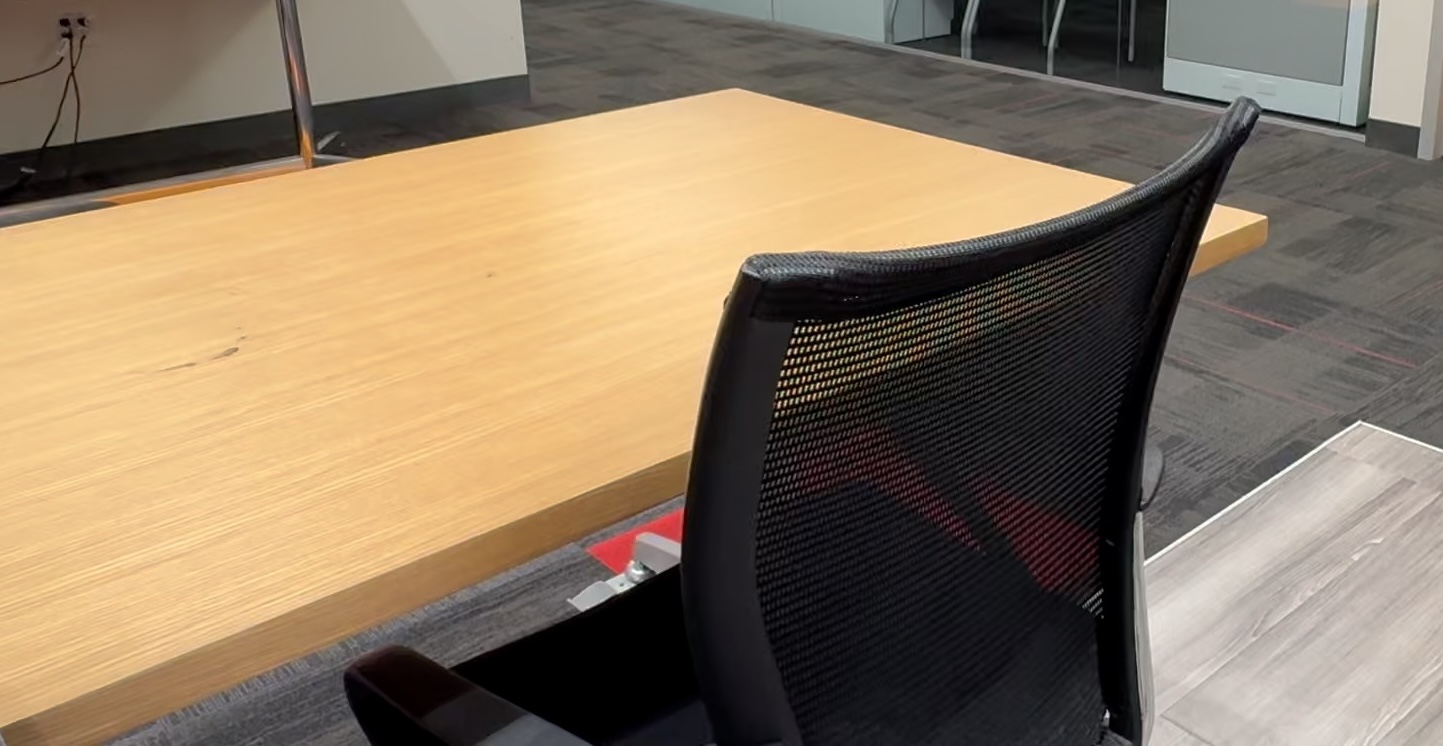
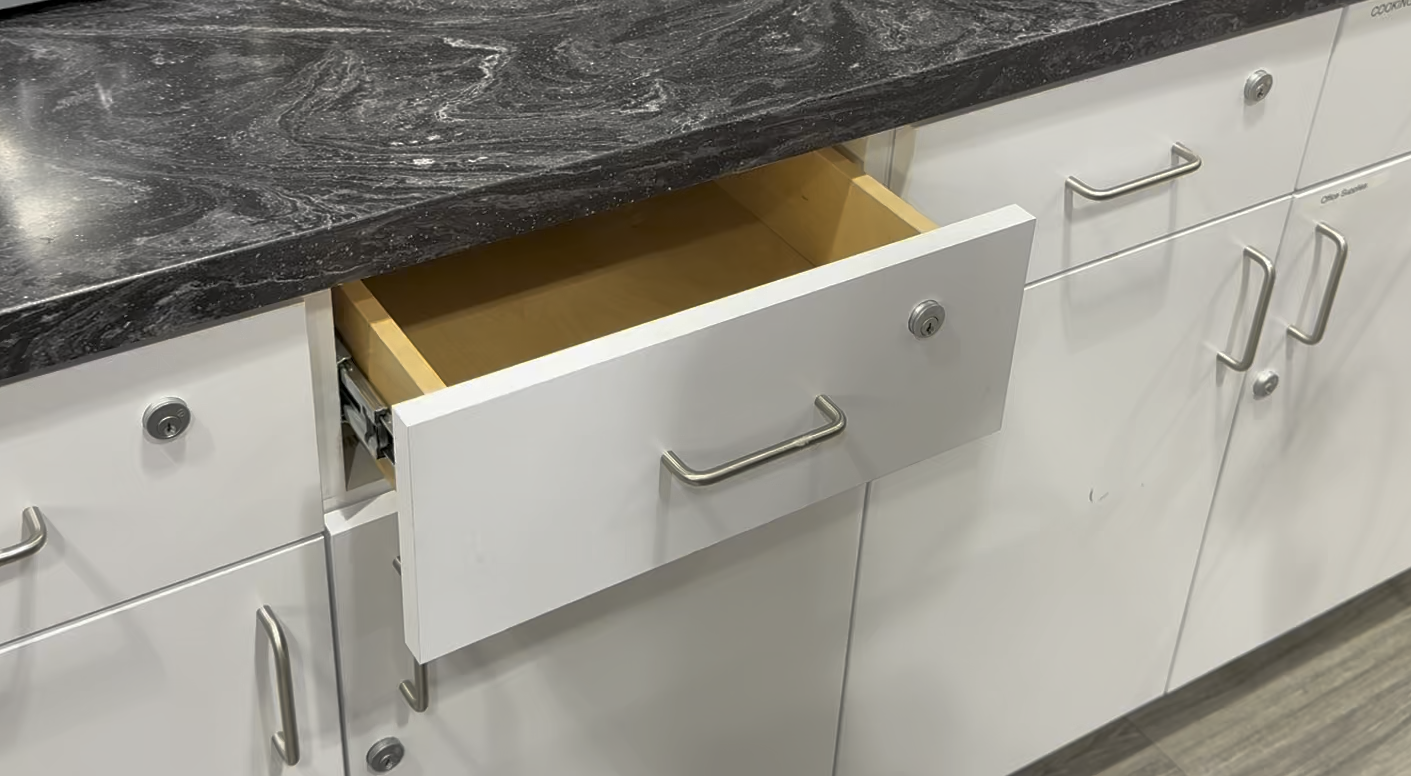
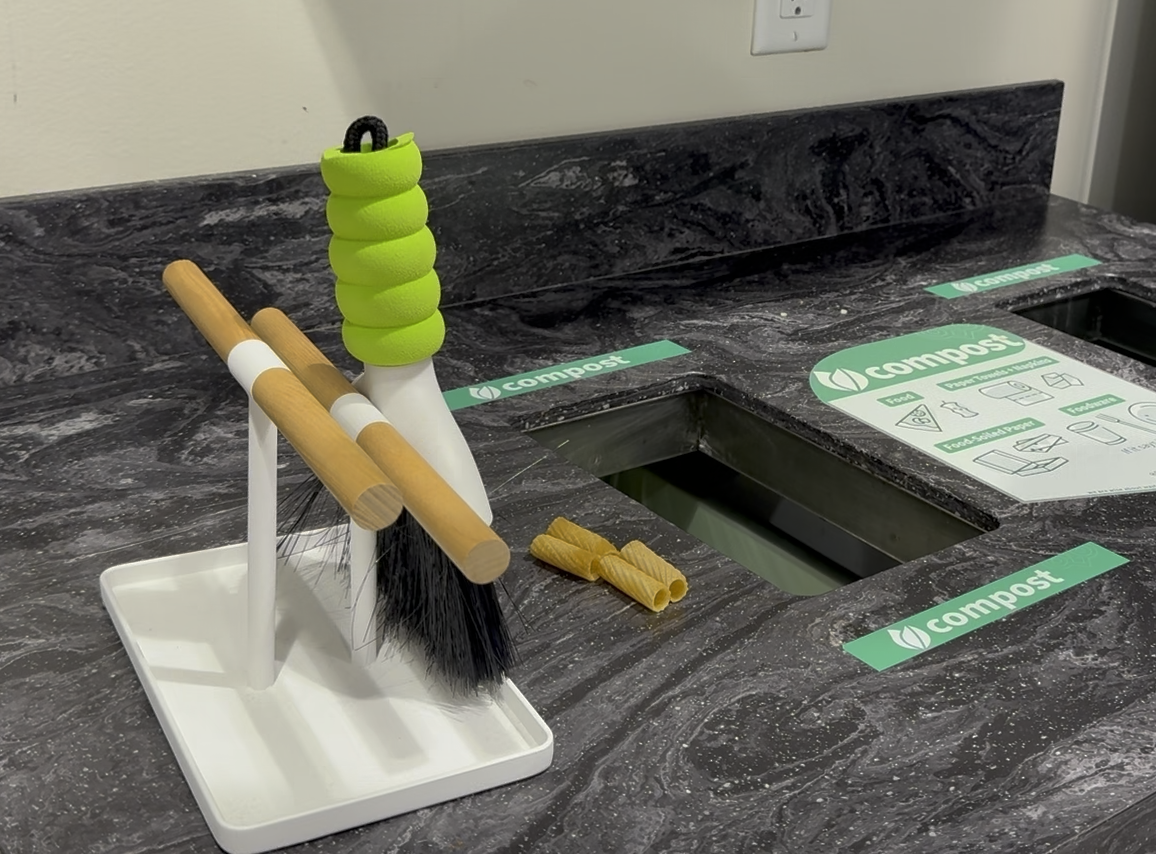
Input RGB
Generated Video
Video Depth
2D Tracks
3D Object Flow from Generated Videos
Click and move me
Robot Execution
Robustness EvaluationTo assess Dream2Flow's generalization to different object instances, backgrounds, and camera viewing angles, we conduct an additional five trials each for six different variants of the Put Bread in Bowl task.
Hover over each video for more information
Object Instance Background Camera Viewing Angle Same Scene, Different TasksDream2Flow inherits the ability to follow different instructions in the same scene from video generation models. Move the donut to the green bowl. Put the bread in the light blue bowl. Place the mug in the green bowl. 3D Object Flow as a RewardThe 3D object flow extracted by Dream2Flow serves as an embodiment-agnostic reward signal for reinforcement learning. We demonstrate that policies trained with 3D object flow rewards achieve comparable performance to those trained with handcrafted object state rewards across diverse embodiments, including a Franka Panda, a Boston Dynamics Spot, and a Fourier GR1 humanoid. Franka Panda Spot GR1 Humanoid Failure ModesWe analyze the failure modes of Dream2Flow across all 60 real-world trials. On the left is a Sankey diagram showing failure modes across different stages of the pipeline. Click on one of the failure modes in the Sankey diagram to learn more. On the right is a description of the selected failure mode and an example video.
Click on a failure mode to see details
Object Morphing
The video generation model substantially changes the shape or appearance of the object, making 2D tracking fail.
The bread morphs into a croissant during the video.
BibTeX@article{dharmarajan2025dream2flow,
title={Dream2Flow: Bridging Video Generation and Open-World Manipulation with 3D Object Flow},
author={Dharmarajan, Karthik and Huang, Wenlong and Wu, Jiajun and Fei-Fei, Li and Zhang, Ruohan},
journal={arXiv preprint arXiv:2512.24766},
year={2025}
}
|
| You are visitor 01402503 — GeezerVison does not store the pages you look up. Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required. |