GeezerVisonThe World Wide Web, restored to 800 pixels of glory. | ||||||||||||||||||||||||||||||||||||||
| Home|About|Gaming cabinet|Archives|How it works|Starter sites | ||||||||||||||||||||||||||||||||||||||
GeezerVison is showing feathr-ai.github.io — Feathr |


| Name | Description | Platform |
|---|---|---|
| NYC Taxi Demo | Quickstart notebook that showcases how to define, materialize, and register features with NYC taxi-fare prediction sample data. | Azure Synapse, Databricks, Local Spark |
| Databricks Quickstart NYC Taxi Demo | Quickstart Databricks notebook with NYC taxi-fare prediction sample data. | Databricks |
| Feature Embedding | Feathr UDF example showing how to define and use feature embedding with a pre-trained Transformer model and hotel review sample data. | Databricks |
| Fraud Detection Demo | An example to demonstrate Feature Store using multiple data sources such as user account and transaction data. | Azure Synapse, Databricks, Local Spark |
| Product Recommendation Demo | Feathr Feature Store example notebook with a product recommendation scenario | Azure Synapse, Databricks, Local Spark |
🔡 Feathr Highlighted Capabilities
Please read Feathr Full Capabilities for more examples. Below are a few selected ones:
Feathr UI
Feathr provides an intuitive UI so you can search and explore all the available features and their corresponding lineages.
You can use Feathr UI to search features, identify data sources, track feature lineages and manage access controls. Check out the latest live demo here to see what Feathr UI can do for you. Use one of following accounts when you are prompted to login:
- A work or school organization account, includes Office 365 subscribers.
- Microsoft personal account, this means an account can access to Skype, Outlook.com, OneDrive, and Xbox LIVE.
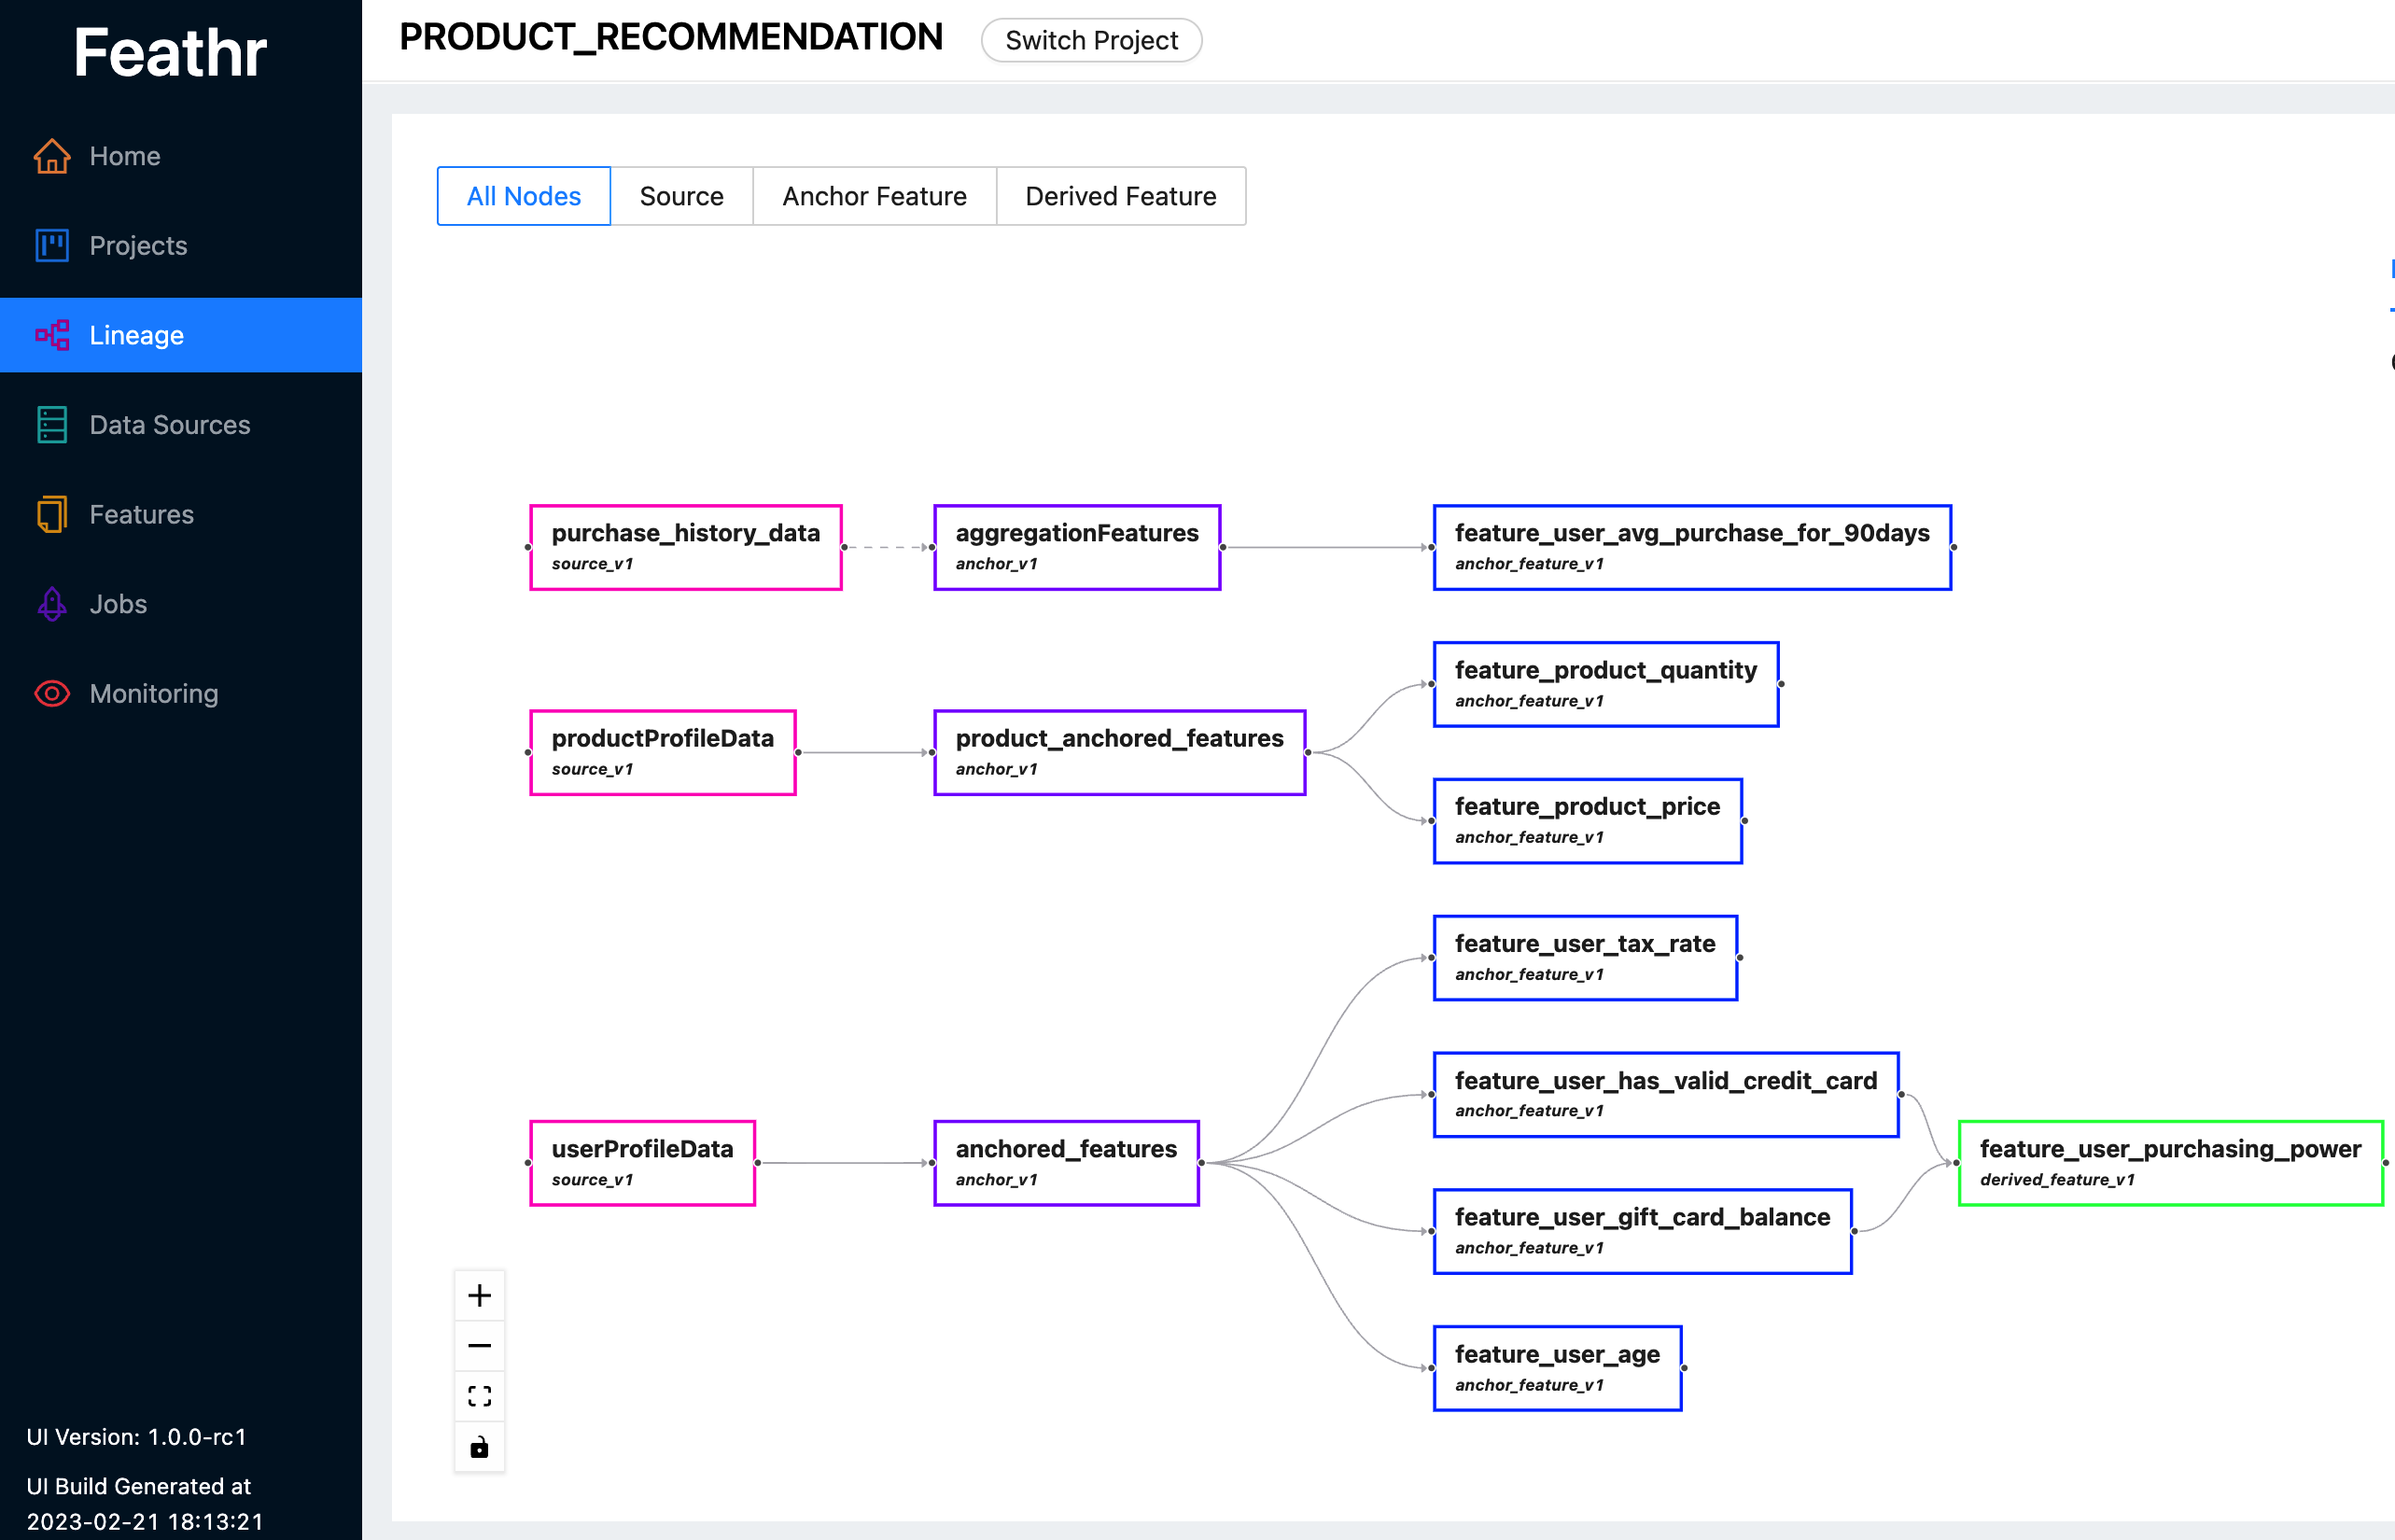
For more information on the Feathr UI and the registry behind it, please refer to Feathr Feature Registry
Rich UDF Support
Feathr has highly customizable UDFs with native PySpark and Spark SQL integration to lower learning curve for data scientists:
def add_new_dropoff_and_fare_amount_column(df: DataFrame):
    df = df.withColumn("f_day_of_week", dayofweek("lpep_dropoff_datetime"))
    df = df.withColumn("fare_amount_cents", df.fare_amount.cast('double') * 100)
    return df

batch_source = HdfsSource(name="nycTaxiBatchSource",
                        path="abfss://[email protected]/demo_data/green_tripdata_2020-04.csv",
                        preprocessing=add_new_dropoff_and_fare_amount_column,
                        event_timestamp_column="new_lpep_dropoff_datetime",
                        timestamp_format="yyyy-MM-dd HH:mm:ss")
Defining Window Aggregation Features with Point-in-time correctness
agg_features = [Feature(name="f_location_avg_fare",
                        key=location_id,                          # Query/join key of the feature(group)
                        feature_type=FLOAT,
                        transform=WindowAggTransformation(        # Window Aggregation transformation
                            agg_expr="cast_float(fare_amount)",
                            agg_func="AVG",                       # Apply average aggregation over the window
                            window="90d")),                       # Over a 90-day window
                ]

agg_anchor = FeatureAnchor(name="aggregationFeatures",
                           source=batch_source,
                           features=agg_features)
Define Features on Top of Other Features - Derived Features
# Compute a new feature(a.k.a. derived feature) on top of an existing feature
derived_feature = DerivedFeature(name="f_trip_time_distance",
                                 feature_type=FLOAT,
                                 key=trip_key,
                                 input_features=[f_trip_distance, f_trip_time_duration],
                                 transform="f_trip_distance * f_trip_time_duration")

# Another example to compute embedding similarity
user_embedding = Feature(name="user_embedding", feature_type=DENSE_VECTOR, key=user_key)
item_embedding = Feature(name="item_embedding", feature_type=DENSE_VECTOR, key=item_key)

user_item_similarity = DerivedFeature(name="user_item_similarity",
                                      feature_type=FLOAT,
                                      key=[user_key, item_key],
                                      input_features=[user_embedding, item_embedding],
                                      transform="cosine_similarity(user_embedding, item_embedding)")
Define Streaming Features
Read the Streaming Source Ingestion Guide for more details.
Point in Time Joins
Read Point-in-time Correctness and Point-in-time Join in Feathr for more details.
Running Feathr Examples
Follow the quick start Jupyter Notebook to try it out. There is also a companion quick start guide containing a bit more explanation on the notebook.
🗣️ Tech Talks on Feathr
- Introduction to Feathr - Beginner’s guide
- Document Intelligence using Azure Feature Store (Feathr) and SynapseML
- Notebook tutorial: Build a Product Recommendation Machine Learning Model with Feathr Feature Store
- Feathr talk in Feature Store Summit
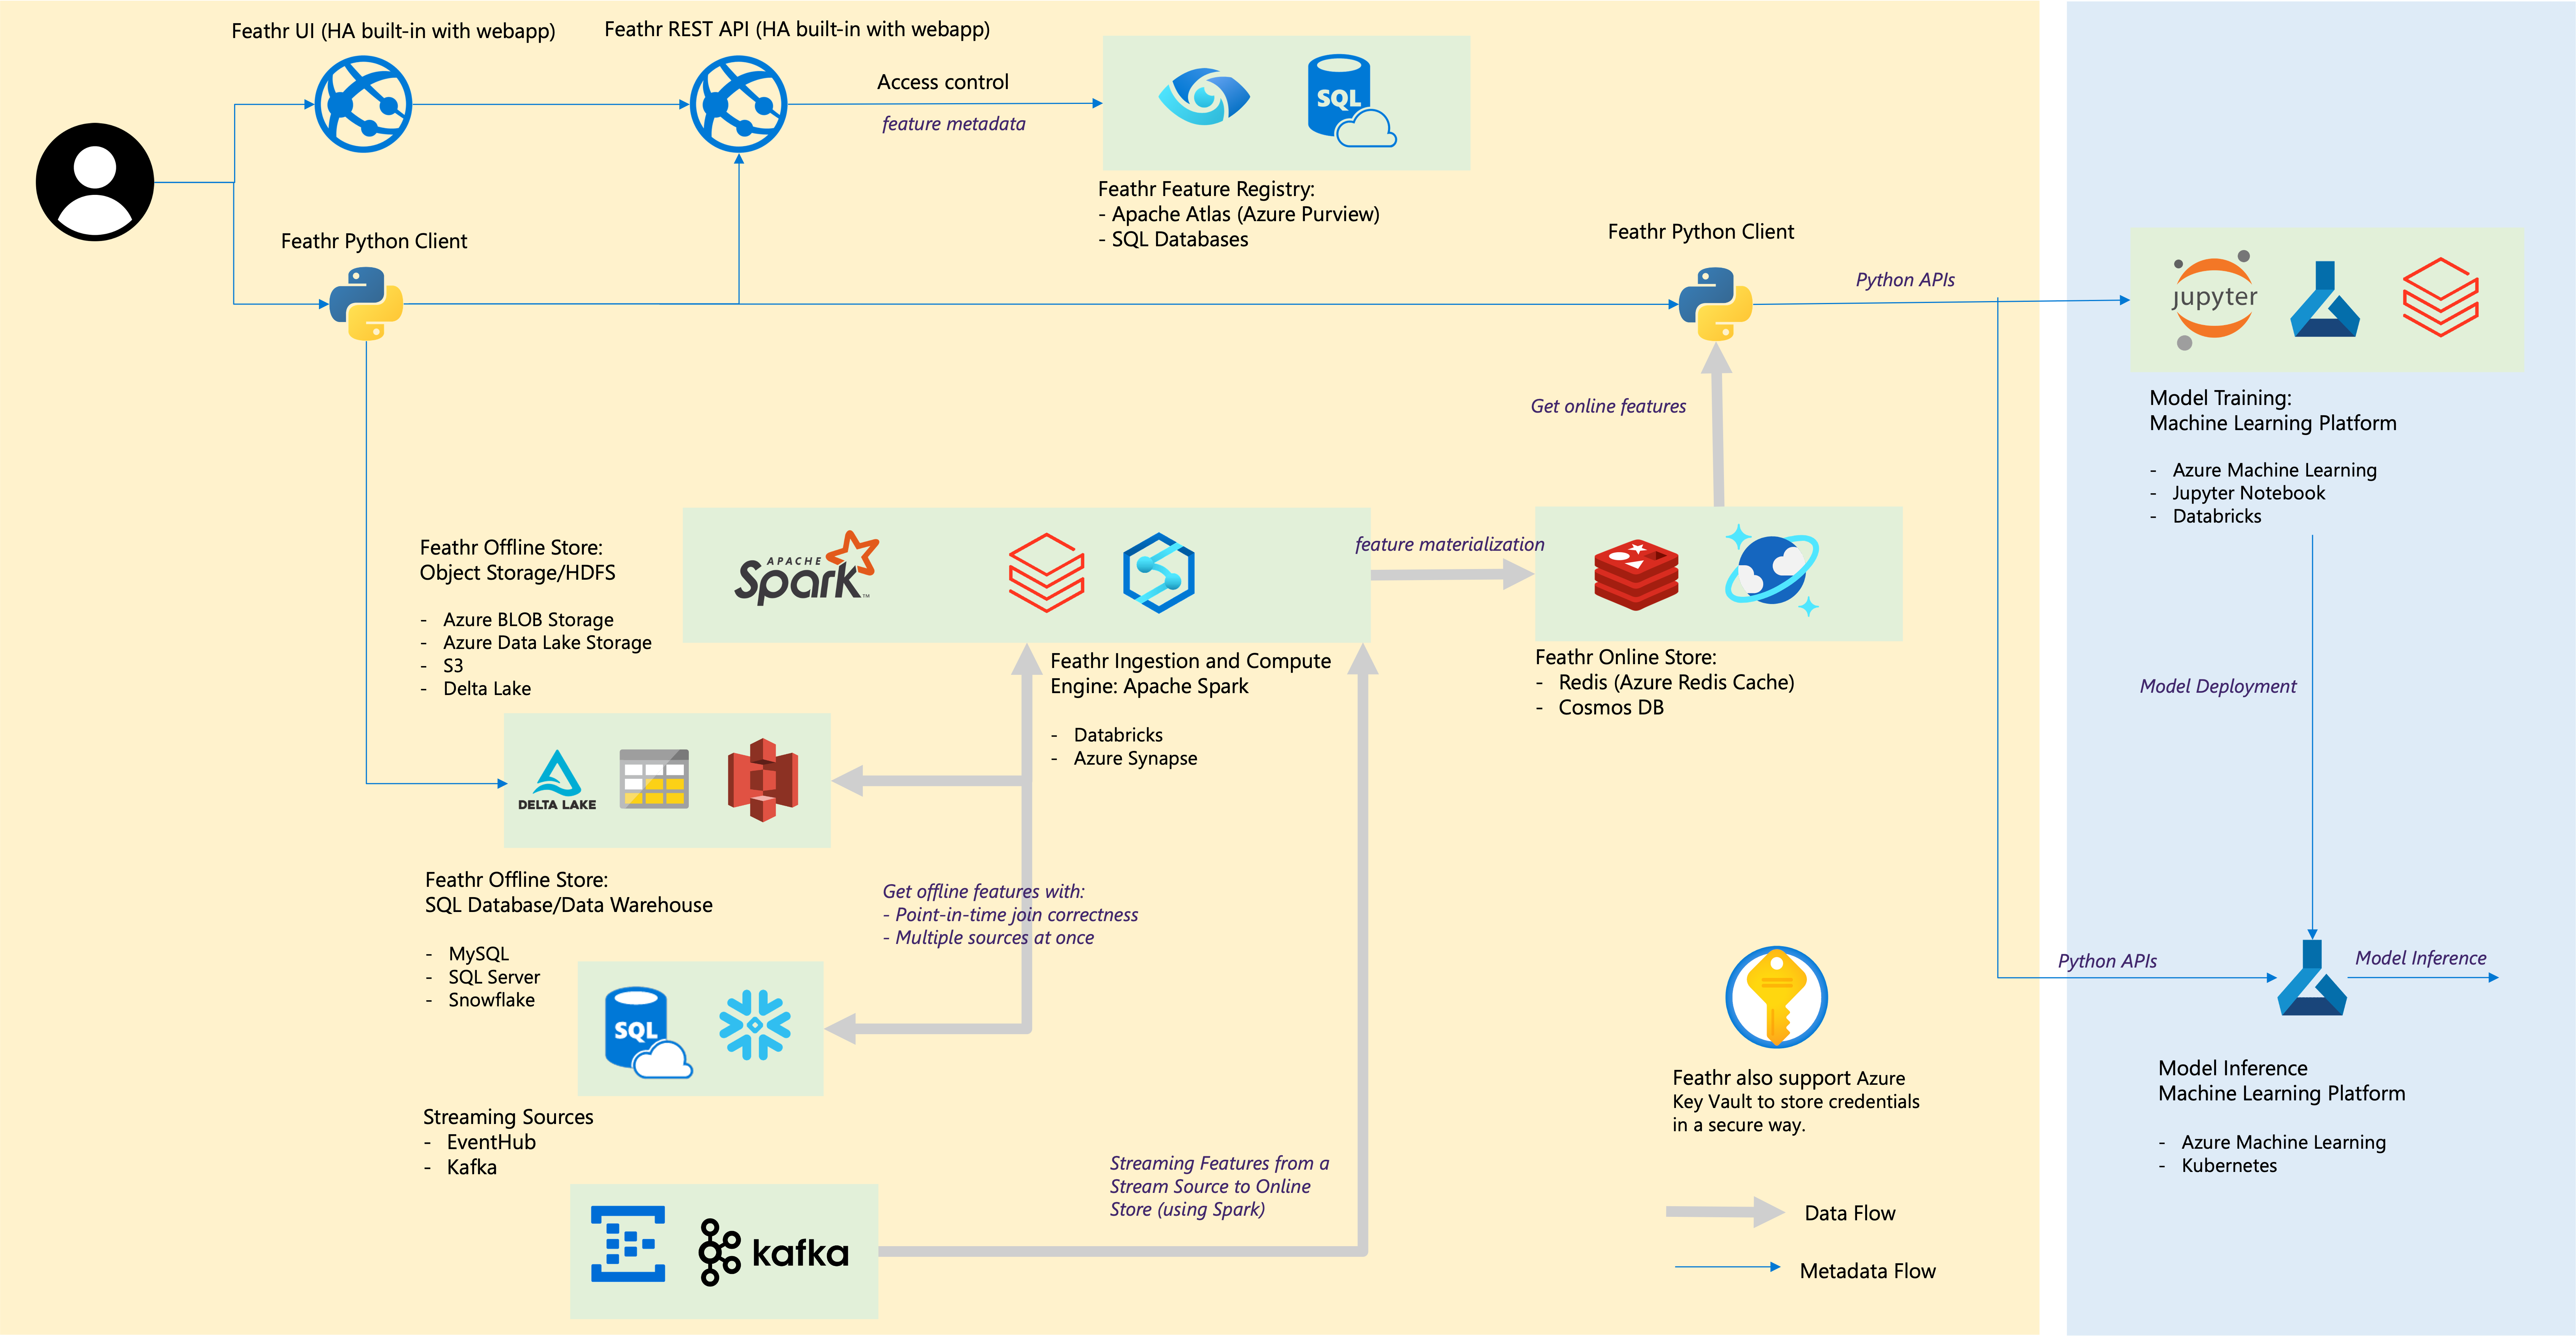
⚙️ Cloud Integrations and Architecture
| Feathr component | Cloud Integrations |
|---|---|
| Offline store – Object Store | Azure Blob Storage, Azure ADLS Gen2, AWS S3 |
| Offline store – SQL | Azure SQL DB, Azure Synapse Dedicated SQL Pools, Azure SQL in VM, Snowflake |
| Streaming Source | Kafka, EventHub |
| Online store | Redis, Azure Cosmos DB |
| Feature Registry and Governance | Azure Purview, ANSI SQL such as Azure SQL Server |
| Compute Engine | Azure Synapse Spark Pools, Databricks |
| Machine Learning Platform | Azure Machine Learning, Jupyter Notebook, Databricks Notebook |
| File Format | Parquet, ORC, Avro, JSON, Delta Lake, CSV |
| Credentials | Azure Key Vault |
🚀 Roadmap
- More Feathr online client libraries such as Java
- Support feature versioning
- Support feature monitoring
👨👨👦👦 Community Guidelines
Build for the community and build by the community. Check out Community Guidelines.
📢 Slack Channel
Join our Slack channel for questions and discussions (or click the invitation link).
Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required.