This project use the python API to implement some customized functonalities such specifing the information, set the range to crawl or select the type of output file including json, xlsx and pdf. For more information, please check the github repo of PyPtt.
use your favorite virtual environment tool to install the dependencies, my choice will be the pipenv
pipenv install
note that the current working directory should be 'src'
- input your ptt id and password
- select the board and what kinds of content you want to see(0 is the specific option according to my preference)
- 3)date
- 5)content
- 15)push_content
- 16)boo_content
- 17)arrow_content
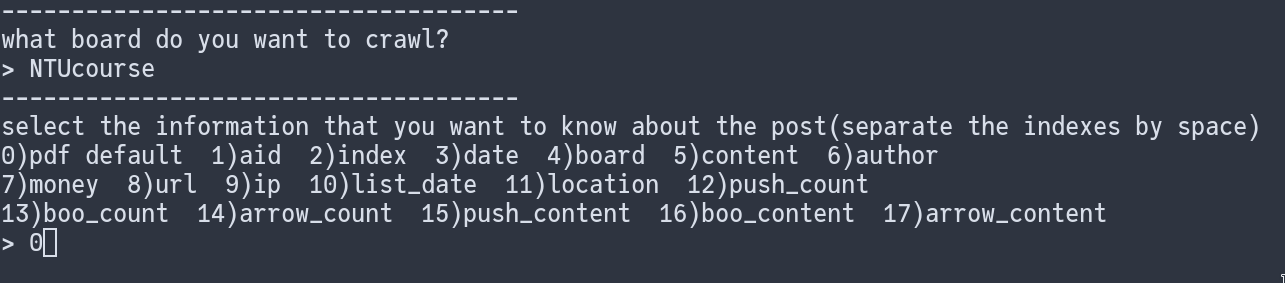
- select the format

command to execute the script(with pipenv)
using pipenv
pipenv run python src/main.py
def login(self):
    try:
        self.bot.login(self.id, self.password)
    except PTT.exceptions.LoginError:
        self.bot.log('warning: fail to log in')
        sys.exit()
    except PTT.exceptions.WrongIDorPassword:
        self.bot.log('warning: wrong password or id')
        sys.exit()
    except PTT.exceptions.LoginTooOften:
        self.bot.log('try too often, please wait for a moment to log in')
        sys.exit()
    except self.bot.unregistered_user:
        self.bot.log('warning: the user is not registered')
    self.bot.log('log in successfully!')
def get_push_info(self, post):
    push_info_dict = {}
    count_push = count_boo = count_arrow = get_push_content = get_boo_content = get_arrow_content = False
    for index in self.push_indexes:
        if index == 12:
            count_push = True
            push_info_dict['push_count'] = 0
        elif index == 13:
            count_boo = True
            push_info_dict['boo_count'] = 0
        elif index == 14:
            count_arrow = True
            push_info_dict['arrow_count'] = 0
        elif index == 15:
            get_push_content = True
            push_info_dict['push_coontent'] = []
        elif index == 16:
            get_boo_content = True
            push_info_dict['boo_content'] = []
        elif index == 17:
            get_arrow_content = True
            push_info_dict['arrow_content'] = []

    for push in post.push_list:
        if push.type == PTT.data_type.push_type.PUSH and count_push:
            push_info_dict['push_count'] += 1
        if push.type == PTT.data_type.push_type.PUSH and get_push_content:
            push_info_dict['push_coontent'].append(push.content.replace(' ', ''))
        if push.type == PTT.data_type.push_type.BOO and count_boo:
            push_info_dict['boo_count'] += 1
        if push.type == PTT.data_type.push_type.BOO and get_boo_content:
            push_info_dict['boo_content'].append(push.content.replace(' ', ''))
        if push.type == PTT.data_type.push_type.ARROW and count_arrow:
            push_info_dict['arrow_count'] += 1
        if push.type == PTT.data_type.push_type.ARROW and get_arrow_content:
            push_info_dict['arrow_content'].append(push.content.replace(' ', ''))

    return push_info_dict
def output_excel(dataList, path):
    wb = xw.Book()
    sheet = wb.sheets[0]

    cols = list(dataList[0].keys())
    last_col = chr(65+(len(cols)-1))

    # set the format for the cell
    sheet.range(f'A1:{last_col}1').api.Font.Bold = True
    sheet.range(f'A1:{last_col}1').api.Font.Name = 'Microsoft YaHei'
    sheet.range(f'A1:{last_col}1').api.HorizontalAlignment = -4108
    sheet.range(f'A1:{last_col}1').api.VerticalAlignment = -4107
    sheet.range(f'A1:{last_col}1').row_height = 17.4

    # set the columns name
    ars = 65
    for item in cols:
        colName = chr(ars)
        sheet.range(f'{colName}1').value = item
        ars += 1
    sheet.autofit(axis='columns')

    # insert the value
    for i in range(len(dataList)):
        write = list(dataList[i].values())
        ars = 65
        for element in write:
            colName = chr(ars)
            if isinstance(element, list):
                total_comment = ''
                for index, comment in enumerate(element):
                    index = f'{index+1}.'
                    total_comment = total_comment + index + comment + ' '
                sheet.range(f'{colName}{i+2}').value = total_comment
            else:
                sheet.range(f'{colName}{i+2}').value = element
            ars += 1

    wb.save(path)
def output_pdf(dataList, path):
    pdf = PDF()
    pdf.set_margins(left=20, right=20, top=15)

    pdf.set_auto_page_break(auto = True, margin = 15)  # Set auto page break
    pdf.add_page()
    pdf.print_header()
    for index, dataDict in enumerate(dataList):
        items = list(dataDict.items())
        for item in items:
            if item[0] == 'title':
                pdf.paragraph_title(f'{index+1}', f'{item[1]}\n')
            else:
                pdf.paragraph_body(item)
        # pdf.ln(10)
        pdf.add_page()

    pdf.output(path)
def output_json(dataList, path):
    file = open(path, 'w', encoding="utf-8")
    for data in dataList:
        jsonString = json.dumps(data, ensure_ascii=False)
        file.write(jsonString + '\n')
    file.close()