GeezerVison is showing github.com — Build software better, together
Here are
25 public repositories
matching this topic...
Language:
All
Filter by language
Sort:
Most stars
Sort options
[EMNLP 2026] 📚 A curated list of Awesome Efficient dLLMs Papers with Codes
[NeurIPS 2026] DMax: Aggressive Parallel Decoding for dLLMs
-
Updated
Sep 28, 2026
-
Python
[ICML 2026] When Drafts Evolve: Speculative Decoding Meets Online Learning
-
Updated
Jul 27, 2026
-
Python
Repository of the paper "Accelerating Transformer Inference for Translation via Parallel Decoding"
-
Updated
Mar 15, 2024
-
Python
A 4B diffusion grounding model for fast, precise visual evidence extraction. Unifies diverse grounding tasks through parallel decoding, with optional self-speculative decoding delivering 4.51x autoregressive throughput on COCO.
-
Updated
Oct 31, 2026
-
Python
[ICML 2026] Jacobi Forcing: Fast and Accurate Diffusion-style Decoding
-
Updated
Feb 20, 2026
-
Python
[ICLR 2026 Oral] Locality-aware Parallel Decoding for Efficient Autoregressive Image Generation
-
Updated
May 8, 2026
-
Python
[ICLR 2026] Autoregressive Image Generation with Randomized Parallel Decoding
-
Updated
Feb 16, 2026
-
Python
JEV-inspired parallel decisions for CUDA LLMs. One context, many decisions. vLLM API, game-agent examples, and reproducible benchmarks.
-
Updated
Sep 18, 2026
-
JavaScript
[ICLR 2026] dParallel: Learnable Parallel Decoding for dLLMs
-
Updated
Apr 12, 2026
-
Python
[ICLR 2026] ParallelBench: Understanding the Tradeoffs of Parallel Decoding in Diffusion LLMs
-
Updated
Mar 27, 2026
-
Python
Implementation of Flash-DLM (paper: FlashDLM: Accelerating Diffusion Language Models via Efficient KV Caching and Guided Diffusion). Provides training-free methods to accelerate diffusion language model inference.
-
Updated
Nov 25, 2025
-
Python
Parallel Decoding of Language Models: A Survey. A systematic survey of parallel decoding, covering speculative decoding, diffusion LLMs, etc...
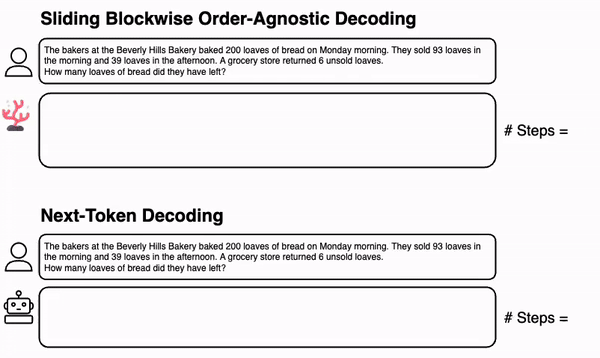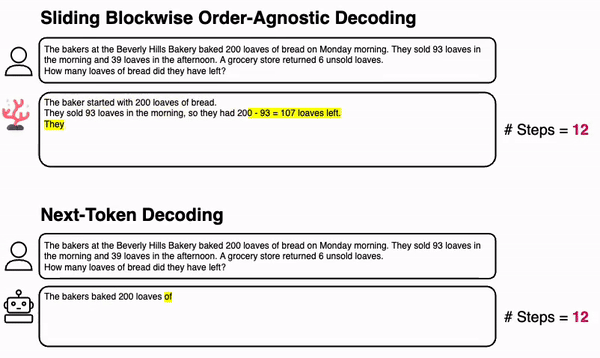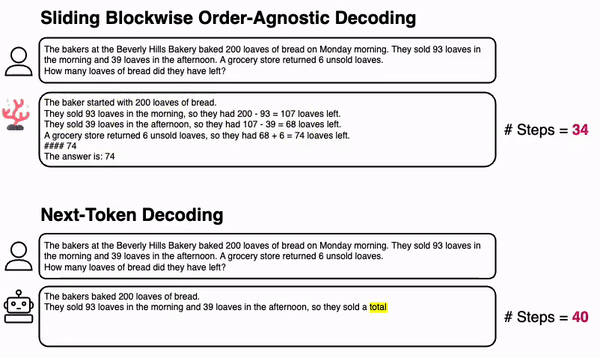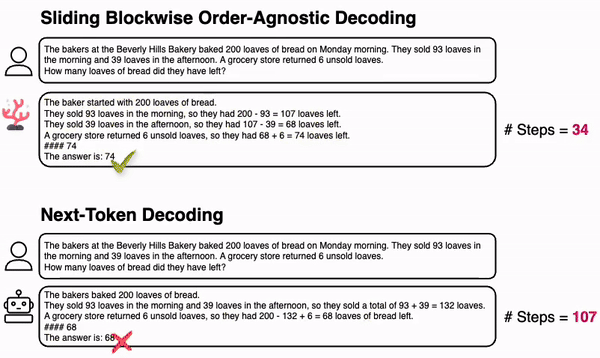
This repository contains the source code for COrAL, an Order-Agnostic Language Modeling framework for Efficient Iterative Refinement.
-
Updated
Apr 2, 2025
-
Python

Run Next-Concept Modeling (NCM) on the Apple Silicon GPU with MLX: HazyResearch's released checkpoints with verified parity to PyTorch, plus from-scratch training and benchmarks.
-
Updated
Nov 8, 2026
-
Python
Predictive-State Flows (PSF): a flow prior generates K predictive states, each summarizing only the preceding blocks; a block decoder writes all blocks in parallel. Code and checkpoints for arXiv 2610.12898.
-
Updated
Oct 22, 2026
-
Python
Strata 125B MoE + JEV mode: llama.cpp fork with parallel-decision endpoints (yes/no in ~10ms), an MCP server, and a llama-swap router swarm for Claude Code & DeepSeek Harness.
Diffusion VLM papers indexed with one feature schema, plus decode-behaviour traces measured through a single instrumentation path
-
Updated
Aug 3, 2026
-
Python
Educational implementation and visualization of autoregressive, DFlash-inspired, and DFlash2-inspired LLM decoding with a tiny Transformer benchmark.
-
Updated
Sep 9, 2026
-
Python
What parallel commitment costs a masked diffusion LM: a 4-page note, measured on a task with a decidable verifier. Produced by the Rust stack (candle-mi -> canvas).
Add this topic to your repo
To associate your repository with the
parallel-decoding
topic, visit your repo's landing page and select "manage topics."
Learn more
|