GeezerVisonThe World Wide Web, restored to 800 pixels of glory. | ||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||
| Home|About|Gaming cabinet|Archives|How it works|Starter sites | ||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||
GeezerVison is showing pbpython.com — Tips for Selecting Columns in a DataFrame - Practical Business Python 
IntroductionThis article will discuss several tips and shortcuts for using Why Do We Care About Selecting Columns?In many standard data science examples, there are a relatively small number of columns. For example, Titanic has 8, Iris has 4, and Boston Housing has 14. Real-life data sets are messy and often include a lot of extra (potentially unnecessary) columns. In data science problems you may need to select a subset of columns for one or more of the following reasons:
Regardless of the reason, you may not need these techniques all the time. When you do, though, the tricks outlined below can reduce the amount of time you spend wrangling columns of data. Also, if you like this type of content, I encourage you to check out Kevin Markham’s pandas tricks which served as an inspiration for a couple of the tips below. The DataIn order to illustrate some examples, I’m going to use a quirky data set from the Central Park Squirrel Census. Yes, apparently there was an effort to count and catalog squirrels in Central Park. I thought this would be a fun example to work through. It also gave me a chance to include a squirrel image (credit: GeorgeB2) in my post :) . This data set includes 3,023 rows of data and 31 columns. While 31 columns is not a tremendous number of columns, it is a useful example to illustrate the concepts you might apply to data with many more columns. If you want to follow along, you can view the notebook or pull it directly from github. Let’s get started by reading in the data. import pandas as pd import numpy as np df = pd.read_csv( 'https://data.cityofnewyork.us/api/views/vfnx-vebw/rows.csv?accessType=DOWNLOAD&bom=true&format=true' ) Sometimes it gets tricky to remember each column name and where it is by index. Here is a simple list comprehension to build up a reference list of all columns and their index. col_mapping = [f"{c[0]}:{c[1]}" for c in enumerate(df.columns)] Which creates a list like this: ['0:X', '1:Y', '2:Unique Squirrel ID', '3:Hectare', '4:Shift', '5:Date', ... '33:Borough Boundaries', '34:City Council Districts', '35:Police Precincts'] In some cases if you might want to rename a bunch of columns, you can use a dictionary comprehension to create a dictionary view of the data: col_mapping_dict = {c[0]:c[1] for c in enumerate(df.columns)} Which creates this dictionary: {0: 'X', 1: 'Y', 2: 'Unique Squirrel ID', 3: 'Hectare', 4: 'Shift', 5: 'Date', ... 33: 'Borough Boundaries', 34: 'City Council Districts', 35: 'Police Precincts'} Having these variables defined can be useful as you progress through your analysis. Instead of repeatedly looking at your original file, you can just double check the variable name during your analysis. One other common task I frequently have is to rename a bunch of columns that are inconsistently named across
files. I use a dictionary to easily rename all the columns using something like Here is a quick example with this data set. Note that we pass in the df_cols = pd.read_clipboard(sep='\t') col_mapping = {c[1]:'' for c in enumerate(df_cols.columns)} Which creates a dictionary that is relatively easy to populate with new names: {'X': '', 'Y': '', 'Unique': '', 'Squirrel': '', 'ID': '', 'Hectare': '', 'Shift': '', ... 'Police': '', 'Precincts': ''} As an added bonus, you could even use an Excel file to set up the column renaming and automate the whole process. That tip is outside the scope of this article. If you are interested though, let me know in the comments. Using ilocThe primary function we will walk through is panda’s Here’s a simple graphic to illustrate the primary usage for 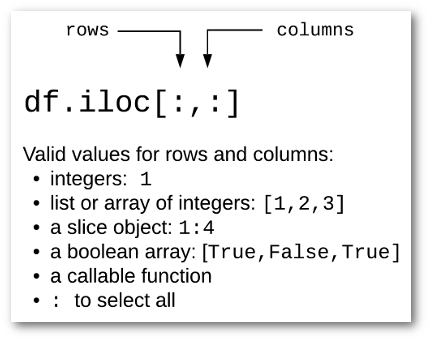
For instance, if you want to look at just the Squirrel ID column of data for all rows: df.iloc[:, 2] 0 37F-PM-1014-03
1 37E-PM-1006-03
2 2E-AM-1010-03
3 5D-PM-1018-05
4 39B-AM-1018-01
...
3018 30B-AM-1007-04
3019 19A-PM-1013-05
3020 22D-PM-1012-07
3021 29B-PM-1010-02
3022 5E-PM-1012-01
Name: Unique Squirrel ID, Length: 3023, dtype: object
If you want to look at the X and Y location as well as the ID, you can pass
in a list of integers df.iloc[:, [0,1,2]]
3023 rows × 3 columns Typing all the columns is not the most efficient, so we can use slicing notation to make this a little easier to understand: df.iloc[:, 0:3] Which will generate the same output as above. If you have some experience with python lists, and have used pandas a bit; all of this usage should make sense. These points are pandas 101 concepts but we will build up from here. While both of these approaches are straightforward, what if you want to combine the list of integers with the slice notation? You might try something like this: df.iloc[:, [0:3,15:19]] File "<ipython-input-56-6f5b3426f412>", line 1
df.iloc[:, [0:3,15:19]]
^
SyntaxError: invalid syntax
Or, you could try something like this: df.iloc[:, 0:3,15:19] IndexingError: Too many indexers Hmmm. That obviously doesn’t work but seems like it would be useful for selecting ranges as well as individual columns. Fortunately there is a numpy object that can help us out. The Here’s a slightly more elaborate example to show how it works on a combination of individual list items and sliced ranges: np.r_[0:3,15:19,24,25] array([ 0, 1, 2, 15, 16, 17, 18, 24, 25]) That’s kind of cool. This object has converted the combination of integer lists and slice notation
into a single list which we can pass to df.iloc[:, np.r_[0:3,15:19,24,25]]
3023 rows × 20 columns Here is another tip. You may also use this notation when reading data using df_2 = pd.read_csv( 'https://data.cityofnewyork.us/api/views/vfnx-vebw/rows.csv?accessType=DOWNLOAD&bom=true&format=true', usecols=np.r_[1,2,5:8,15:30], ) I find this notation helpful when you have a data set where you want to keep non-sequential columns and do not want to type out the full names of all the columns. One caveat I would make is that you need to be careful when using the slice notation and keep in mind that the last number in the range will not be included in the generated list of numbers. For example, if we specify the range np.r_[2:4] array([2, 3]) If you want to include column index 4, use One final comment on np.r_[2:10:2] array([2, 4, 6, 8]) This is a bit of a more advanced option and is not going to be intuitively obvious to a new pandas user. However if you ever find yourself parsing a lot of columns by index, this might be a useful tool to navigate a tricky scenario. iloc and boolean arraysOne of the most powerful ways to filter columns is to pass a boolean array to The most important concept is that we don’t generate a boolean array by hand but use the output from
another pandas function to generate the array and feed it to In this case, we can use the If we want to see which columns contain the word “run”: run_cols = df.columns.str.contains('run', case=False) print(run_cols) array([False, False, False, False, False, False, False, False, False,
False, False, False, False, False, False, True, False, False,
False, False, False, False, False, False, False, False, False,
False, True, False, False, False, False, False, False, False])
Then we can pass this new array of boolean values to select only two columns: df.iloc[:, run_cols].head()
In practice, many people will use a df.iloc[:, lambda df:df.columns.str.contains('run', case=False)] The benefits of using df.iloc[:, lambda df: df.columns.str.contains('district|precinct|boundaries', case=False)].head()
We can even combine all these concepts together by using the results of the boolean array to get the index
then use The example below can be simplified by using Here is an example where we want to get all the location related columns as well as the squirrel ID into a DataFrame: location_cols = df.columns.str.contains('district|precinct|boundaries', case=False) location_indices = [i for i, col in enumerate(location_cols) if col] df.iloc[:, np.r_[0:3,location_indices]].head()
This code is a little complicated since we are using a conditional list comprehension and might be overkill for selecting 7 columns. The important concept is that you know it is possible and can refer back to this article when you need it for your own analysis. FilterIn the original article, I did not include any information about using pandas DataFrame filter
to select columns. I think this mainly because If you want to select the columns that have “Districts” in the name, you can use df.filter(like='Districts')
You can also use a regex so it is easy to look for columns that contain one or more patterns: df.filter(regex='ing|Date')
The more complex df.filter(regex='District|Precinct|Boundaries') CaveatsOne item to keep in mind when dealing with numerical indexing of columns is that you need to understand where your data comes from. If you expect you ID column to always be in a specific location and it changes order in the data, you could face problems with your subsequent data processing. This situation is where your domain knowledge and expertise comes into play to make sure the solution is robust enough for the given situation. SummaryMost of my data analysis involves filtering and selecting data at the row level. However
there are times when it is helpful to work with data in a column-wise fashion. Pandas
Changes
Tags
pandas
Comments | ||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||
| You are visitor 01402503 — GeezerVison does not store the pages you look up. Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required. |