GeezerVisonThe World Wide Web, restored to 800 pixels of glory. |
| Home|About|Gaming cabinet|Archives|How it works|Starter sites |
GeezerVison is showing spark.apache.org — Apache Spark™ - Unified Engine for large-scale data analytics Unified engine for large-scale data analyticsGet StartedWhat is Apache Spark™?Apache Spark™ is a multi-language engine for executing data engineering,
data science, and machine learning on single-node machines or clusters.
Simple.
Fast. Scalable. Unified.
Key features

Batch/streaming data
Unify the processing of your data in batches and real-time streaming, using your preferred language: Python, SQL, Scala, Java or R.

SQL analytics
Execute fast, distributed ANSI SQL queries for dashboarding and ad-hoc reporting. Runs faster than most data warehouses.

Data science at scale
Perform Exploratory Data Analysis (EDA) on petabyte-scale data without having to resort to downsampling

Machine learning
Train machine learning algorithms on a laptop and use the same code to scale to fault-tolerant clusters of thousands of machines.
Run now
Install with 'pip'
$ pip install pyspark $ pyspark Use the official Docker image
$ docker run -it --rm spark:python3 /opt/spark/bin/pyspark Run now
$ docker run -it --rm spark /opt/spark/bin/spark-sql spark-sql> Run now
$ docker run -it --rm spark /opt/spark/bin/spark-shell scala> Run now
$ docker run -it --rm spark /opt/spark/bin/spark-shell scala> Run now
$ docker run -it --rm spark:r /opt/spark/bin/sparkR > The most widely-used
engine for scalable computing
Thousands of
companies, including 80% of the Fortune 500, use Apache Spark™.
Over 2,000 contributors to the open source project from industry and academia. Ecosystem
Apache Spark™ integrates with your favorite frameworks, helping to scale them to thousands of machines.
Data science and Machine learning
       SQL analytics and BI
      Storage and Infrastructure
           Spark SQL engine: under the hood
Apache Spark™ is built on an advanced distributed SQL engine
for large-scale data
Adaptive Query Execution
Spark SQL adapts the execution plan at runtime, such as automatically setting the number of reducers and join algorithms.
Support for ANSI SQL
Use the same SQL you’re already comfortable with.
Structured and unstructured data
Spark SQL works on structured tables and unstructured data such as JSON or images. TPC-DS 1TB No-Stats With vs. Without Adaptive Query Execution
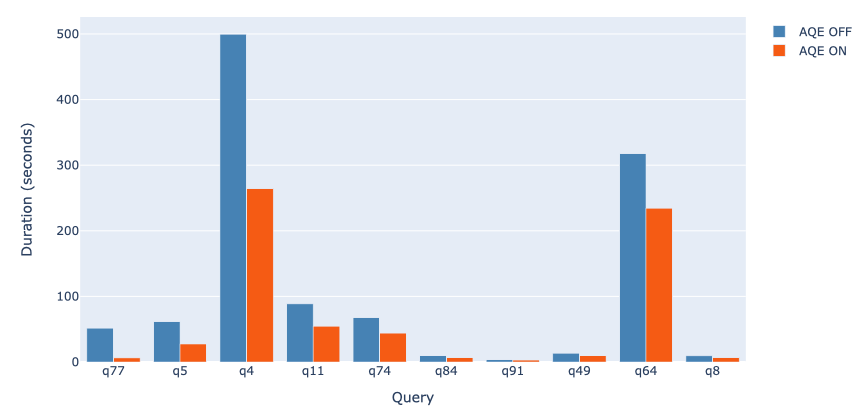
Accelerates TPC-DS queries up to 8x
Join the community
Spark has a thriving open source community, with
contributors from around the globe building features, documentation and assisting other users.
|
| You are visitor 01402503 — GeezerVison does not store the pages you look up. Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required. |
 Mailing list
 Source code
 News and events
 How to contribute
 Issue tracking
 Committers