GeezerVisonThe World Wide Web, restored to 800 pixels of glory. |
| Home|About|Gaming cabinet|Archives|How it works|Starter sites |
GeezerVison is showing spark.apache.org — Spark Structured Streaming | Apache Spark Spark Structured StreamingSpark Structured Streaming makes it easy to build streaming applications and pipelines with the same and familiar Spark APIs. Spark Structured Streaming has two different modes:
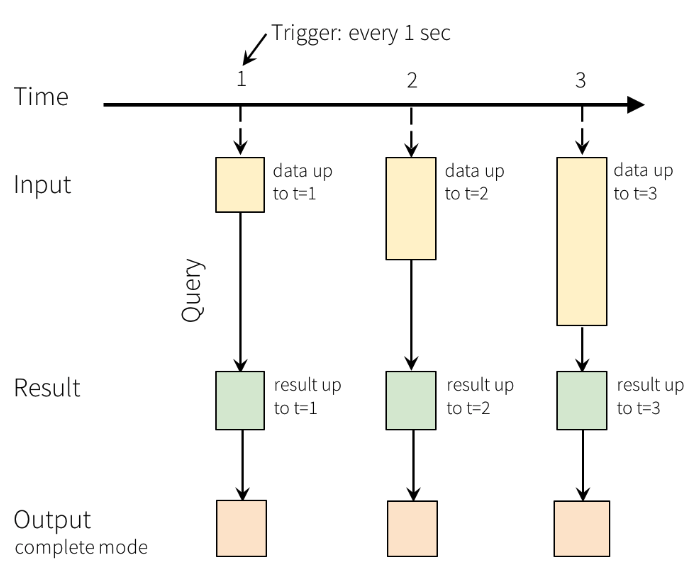
Both modes share the exact same codebase, so you can move between cost-effective ETL and sub-second operational streaming with only small changes to your query. Easy to useSpark Structured Streaming abstracts away complex streaming concepts such as incremental processing, checkpointing, and watermarks so you can build streaming applications without learning new tools. Shifting from minute-level ETL to millisecond-scale operational streaming is mostly a trigger change. Real-time Mode also requires the Update output mode and supports a defined subset of sources, operators, and sinks. Micro-batch mode — second- or minute-level latency for analytical ETL:
spark
.readStream .select($"value".cast("string").alias("jsonData")) .select(from_json($"jsonData", jsonSchema).alias("payload")) .writeStream .trigger(Trigger.ProcessingTime("1 minute")) .start() Real-time Mode — millisecond-scale latency for operational workloads. Switch the trigger and set the output mode to
spark
.readStream .select($"value".cast("string").alias("jsonData")) .select(from_json($"jsonData", jsonSchema).alias("payload")) .writeStream .outputMode("update") .trigger(Trigger.RealTime("5 minutes")) .start() Unified batch and streaming APIsSpark Structured Streaming provides the same structured APIs (DataFrames and Datasets) as Spark, so you don’t need to develop on or maintain two different technology stacks for batch and streaming. The same codebase scales from historical batch processing to real-time inference, and unified APIs make it easy to migrate existing batch Spark jobs to streaming.
Built for both analytical and operational workloadsRun cost-effective ETL and sub-second operational applications on the same engine. Spark Structured Streaming supports both micro-batch and Real-time execution, so you can change latency targets largely through the trigger, within Real-time Mode’s supported set of sources, operators, and sinks.
Low latency and cost-effectiveSpark Structured Streaming uses the same underlying architecture as Spark, so you can take advantage of all the performance and cost optimizations built into the Spark engine. While micro-batch execution provides highly cost-effective processing for analytical ETL, Real-time Mode uses continuous processing with pipelined and streaming shuffles to reach single-digit millisecond latencies for stateless workloads. Run mission-critical operational workloads with ultra-low latency.
Getting startedTo get started with Spark Structured Streaming:
CommunitySpark Structured Streaming is developed as part of Apache Spark. It thus gets tested and updated with each Spark release. If you have questions about the system, ask on the Spark mailing lists. The Spark Structured Streaming developers welcome contributions. If you’d like to help out, read how to contribute to Spark, and send us a patch! Latest News
|
| You are visitor 01402503 — GeezerVison does not store the pages you look up. Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required. |