GV

GeezerVison

The World Wide Web, restored to 800 pixels of glory.

Home|About|Gaming cabinet|Archives|How it works|Starter sites

On this site

  • TensorFold.
  • Inceptionmember
  • Enterprise
  • Benchmarks
  • How to
  • Our brand
  • Agent traffic
  • Contribute
  • Company brief
  • Runbook

This view

  • Original page
  • New address

GeezerVison is showing tensorfold.dev — TensorFold | Run LLMs, Fast.

Run LLMs, Fast.

Run open models on the GPUs you own, with native Metal and CUDA inference.

Download for MacRead the how-to guide ↗

App 1.0.0 · Engine 1.2.0 · Apple silicon · macOS 13.3+

Apache-2.0OpenAI-compatibleAnthropic API

  • Apple Silicon
  • NVIDIA CUDA
  • AMD HIP / Vulkan
Install the CLIMetal · CUDA
$
curl -fsSL https://tensorfold.dev/install.sh | sh
Scale beyond one machineExplore StarLight

Your models.
Your workspace.

Choose a local model, start its server and connect the tools you use.

See how it works ↗
The TensorFold app model library showing a cached Qwen3.5 2B model and its Start server action.
Real app capture · App beta 8 · Example workspace

Models running with TensorFold

  • QwenAlibaba
  • NemotronNVIDIA
  • GLMZ.ai
  • LFMLiquid AI

Proud to contribute to.

Omarchy

Powering CUDA AI in Omarchy.

TensorFold powers Omarchy’s NVIDIA model recipes, including DGX Spark, N1x and paired Sparks.

Explore Omarchy local AI ↗
ComfyUI

Bringing TensorFold to ComfyUI.

An experimental TensorFold integration for ComfyUI’s creative workflows. Contribution in progress.

Follow the contribution ↗

Inference,
measured.

Real runs on named hardware.
Open the release. Inspect the conditions.

Recorded performanceRelease 1.0.6 ↗
874tokens per second
NVIDIA

Nemotron 3.5 Lightning

RTX PRO 6000 Blackwell

Greedy code decode with drafting enabled, an MLX affine 4-bit checkpoint and the CUDA engine.

Each number is its own release measurement, on the model and machine named under it: not a like-for-like comparison.

Community benchmarks ↗

One stream.
More work per pass.

Drafted tokens. Reused prompts. Connected machines.

Read the implementation ↗

Check the work together.

On supported models, a drafter proposes several tokens and the target checks them together, committing only the matching prefix.

StarLight.Your fleet.
Your organisation's AI.

Free, open-source AI infrastructure for enterprise fleets. Share Macs and GPU servers with company sign-in, model deployments and project budgets. All improvements land on GitHub.

Start a pilot ↗Review the evaluation pack ↗

Support through project backing.

Deploy and manage it yourself for free, without direct support. For deployment help or long-term support, back the project through donations or sponsorship and agree a support scope with us.

Discuss backing & support ↗
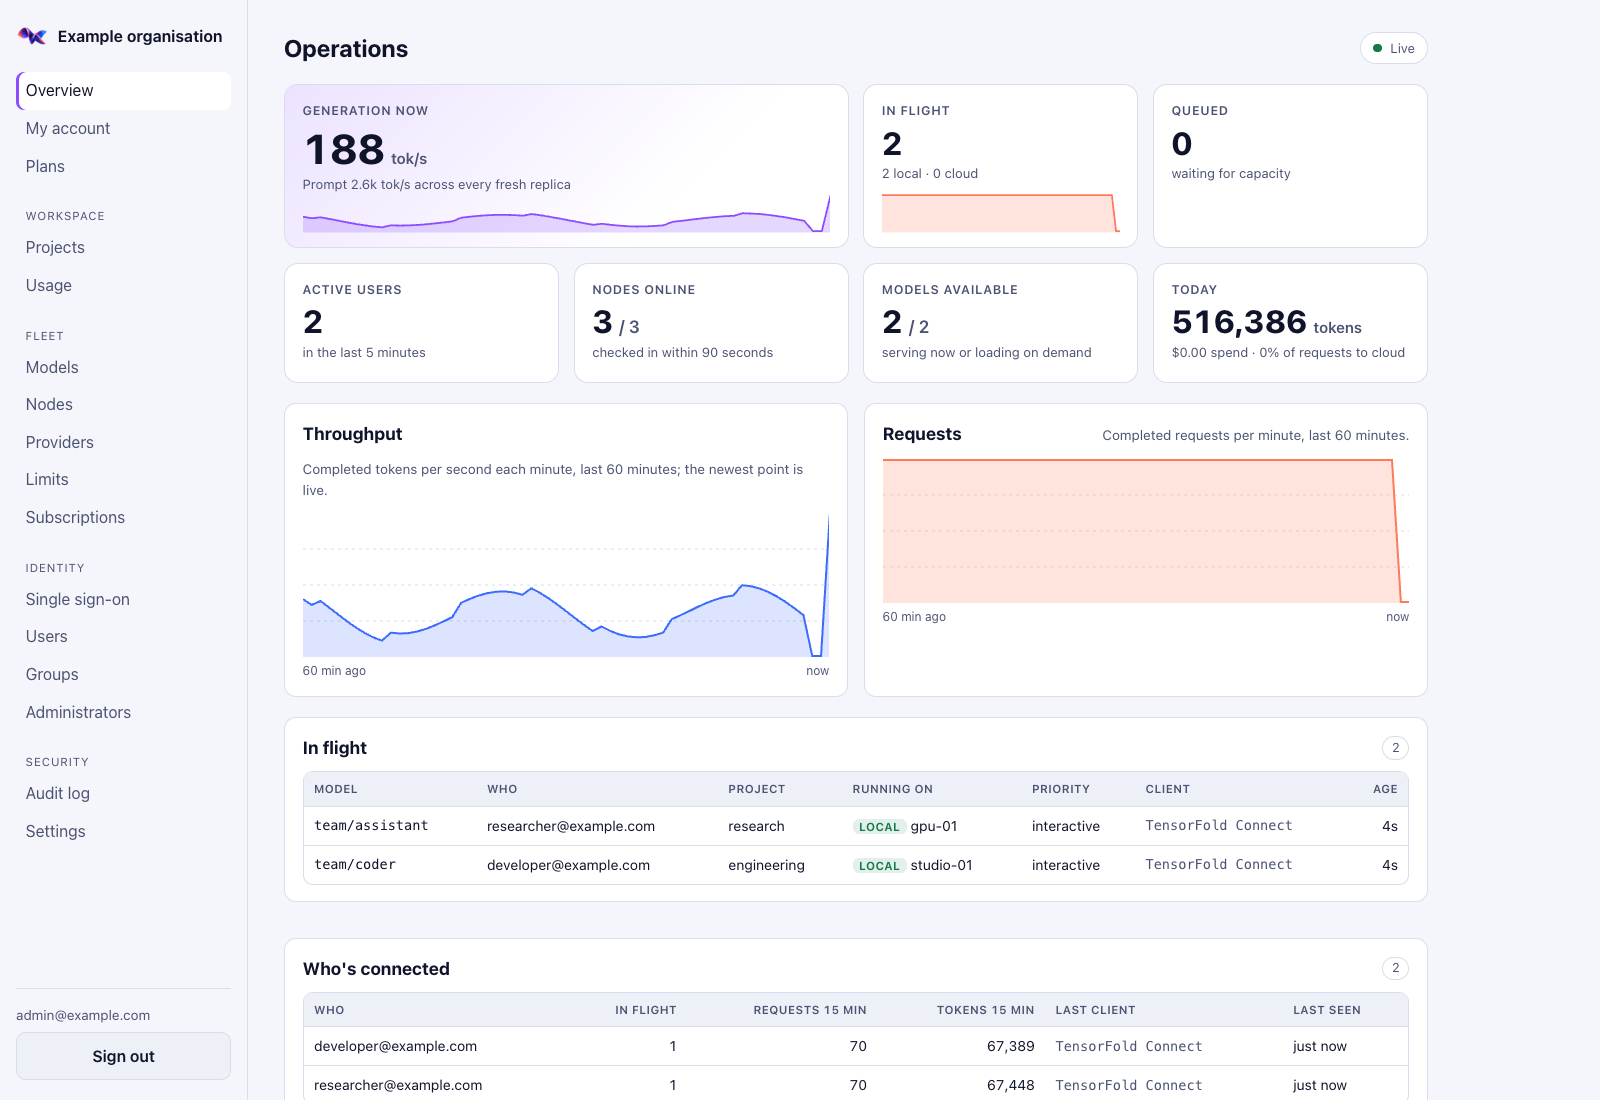
The running StarLight operations console showing example organisation and fleet data.
The StarLight operations consoleExample organisation and usage data

See what your hardware can do.

Compare community runs on named hardware, inspect the receipts and share your results.

Explore the leaderboard ↗
NVIDIA
Inception member

Part of NVIDIA's startup program.

Recipes developed with Mia's AI Lab

With thanks to Mia and her team for their patches, setup and testing.

Explore the collaboration ↗
Concept illustration of a satellite above Earth

Preparing
for orbit.

Deployment in preparation.

A satellite deployment is in preparation. Hardware results will follow qualification.

Concept illustration.

Get involved.

Enterprise deployment & support ↗Contribute to TensorFold ↗Investment & partnerships ↗
You are visitor 01402503 — GeezerVison does not store the pages you look up.
Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required.