GeezerVisonThe World Wide Web, restored to 800 pixels of glory. |
| Home|About|Gaming cabinet|Archives|How it works|Starter sites |
GeezerVison is showing thepythoncode.com — Data Cleaning with Pandas in Python - The Python Code Before we get started, have you tried our new Python Code Assistant? It's like having an expert coder at your fingertips. Check it out! Data cleaning is a process for preparing a dataset for further analysis. During the data cleaning phase, we standardize the data in our dataset by removing any values that could lead to erroneous conclusions. Drawing conclusions based on faulty data can have costly or disastrous consequences, so it is important to base our analysis on clean data. In this tutorial, we will explore several techniques for cleaning data, so we can conduct an analysis with our dataset in the best possible condition. Table of content: Generating the DatasetWe will generate our own dirty data to guarantee that we can practice multiple data cleaning techniques on one dataset. We will simulate a dataset that represents data collected on donors across the United States for a particular organization. Information has been collected to capture these donors' names, addresses, and donation amounts. We will simulate dirty data by randomly introducing inconsistencies in the dataset. Simulation CodeWe will build our simulation code by creating a set of helper functions. Go ahead and create a file named The The The The The Finally, the Now that we have walked through all the functions in the We need the Finally, the After the import statements, add the following code to complete our simulator: The
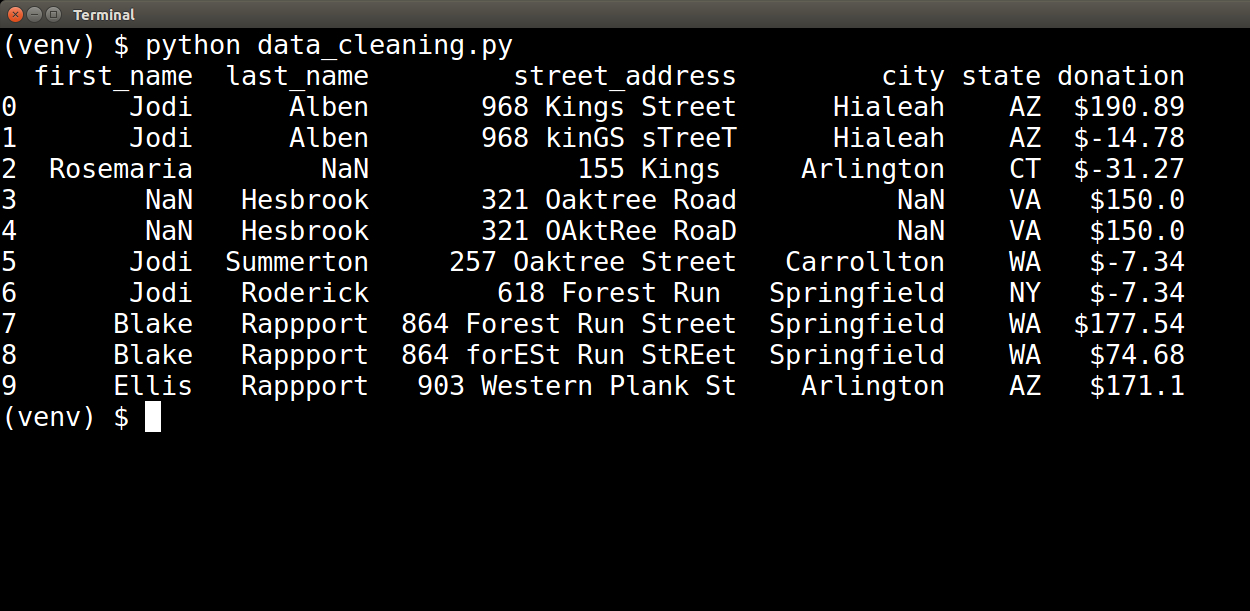
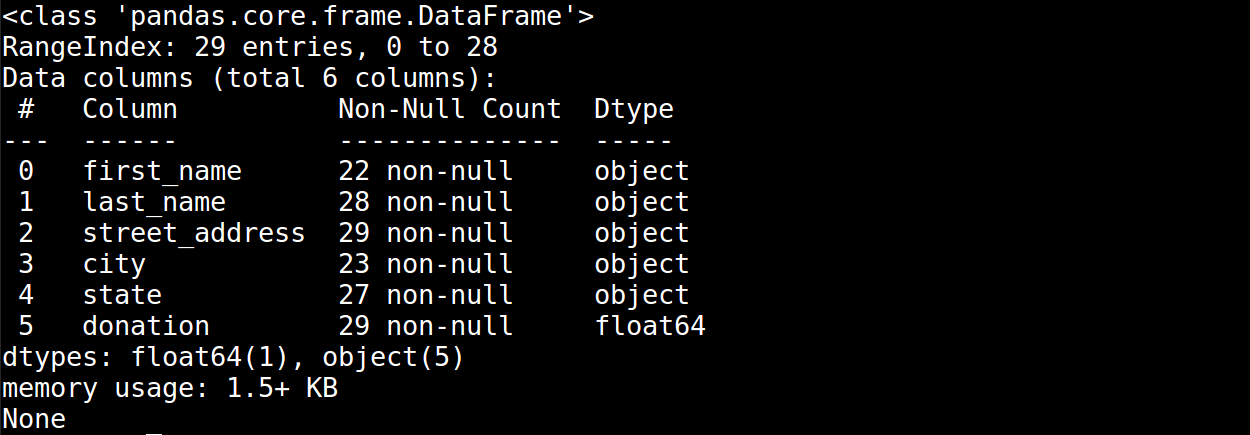
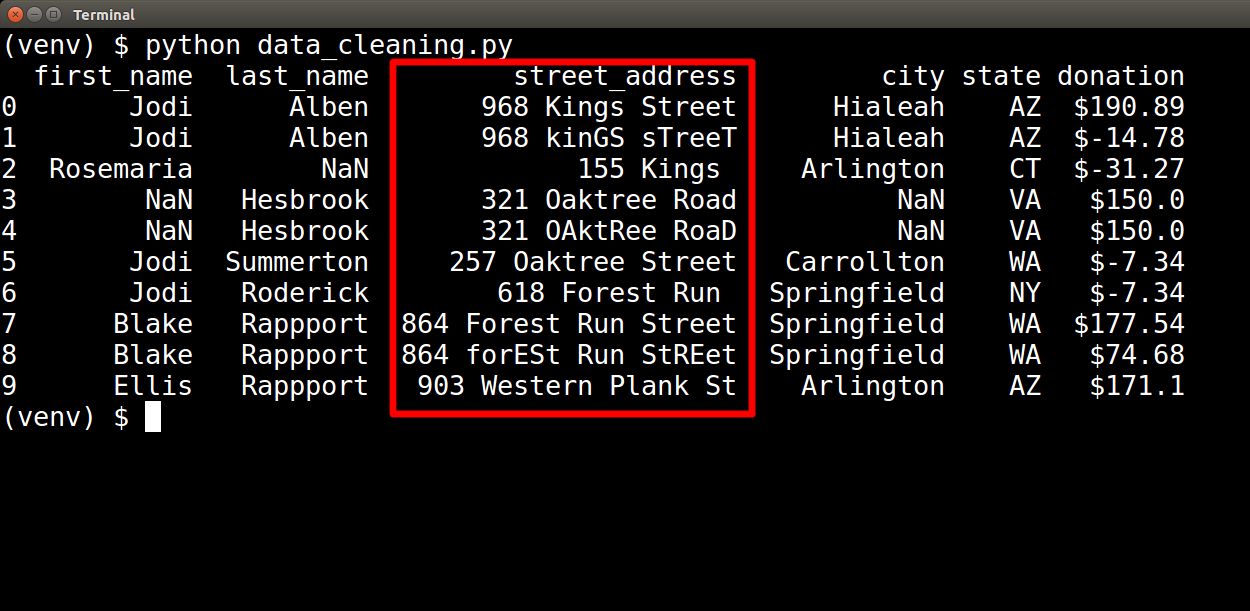
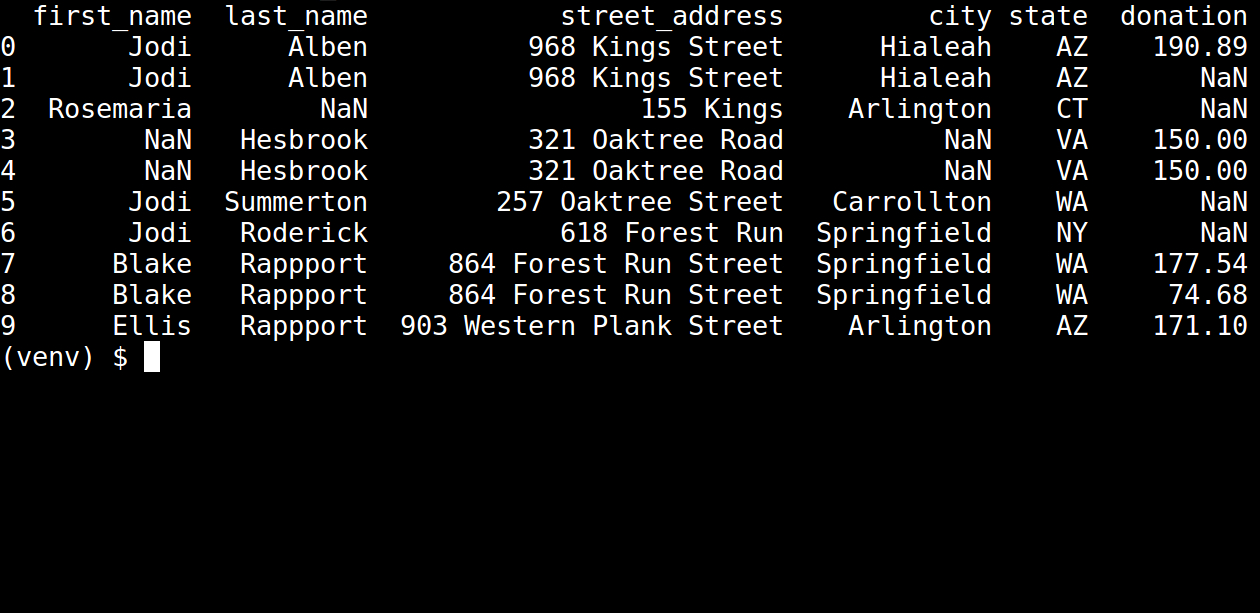
The dataset includes values that exemplify various types of problems that will need to be cleaned up. When you run the We will use the data in the Diagnosing ProblemsBefore we begin the data cleaning process, we need to diagnose the problems in our dataset. To diagnose problems, we first need to have context. Having context means we need to understand the data's domain, have a particular use case for the dataset in mind, and learn as much as possible about how the data was collected. By establishing context, we can develop a feeling of where to hunt for potential problems. As mentioned above, we know our dataset represents information about donors for a particular organization that lives in various locations across the United States. Our task is to find information on the amount of money donated by donors living in certain regions of the United States. We also know that all values in our dataset are stored as strings. With that context in mind, let's create a new script in which we will use We use the Next, we import our data file into Running this script generates the following output:
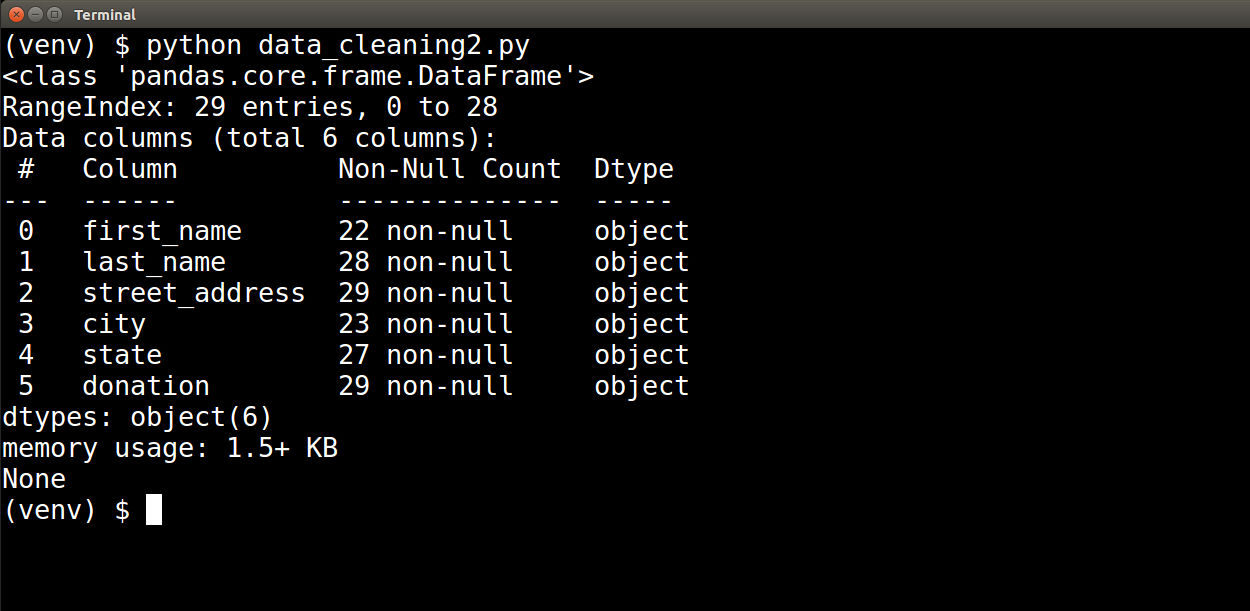
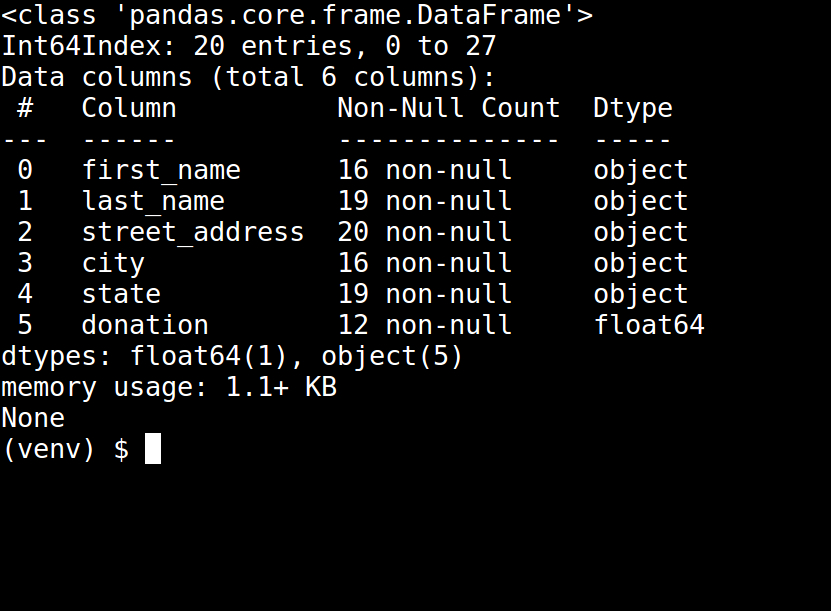
Visual InspectionsUpon visual inspection, we can identify several issues. First, we see the value Also, we can see street addresses that are inconsistent. "864 Forest Run Street" and "864 forESt Run StREet" represent the same address, although their casing differs. We do not want these to be treated as different addresses, so we must clean up this inconsistency. Finally, in the donation column, we see negative dollar amounts. A negative dollar amount does not make sense within the context of donations. These values are out-of-range, so we must determine how to handle them. Visual inspection of the data helped us diagnose missing values, inconsistent data, and out-of-range values. However, we do not need to rely on visual inspection alone. Pandas have other tools we can use to diagnose these and other issues as well. Other Diagnostic ToolsWhat if "dirty" data values were not present in our visual sample? There are other ways to diagnose a dataset's problems using pandas. For example, to determine if there are missing values, you can run the following script: Calling the
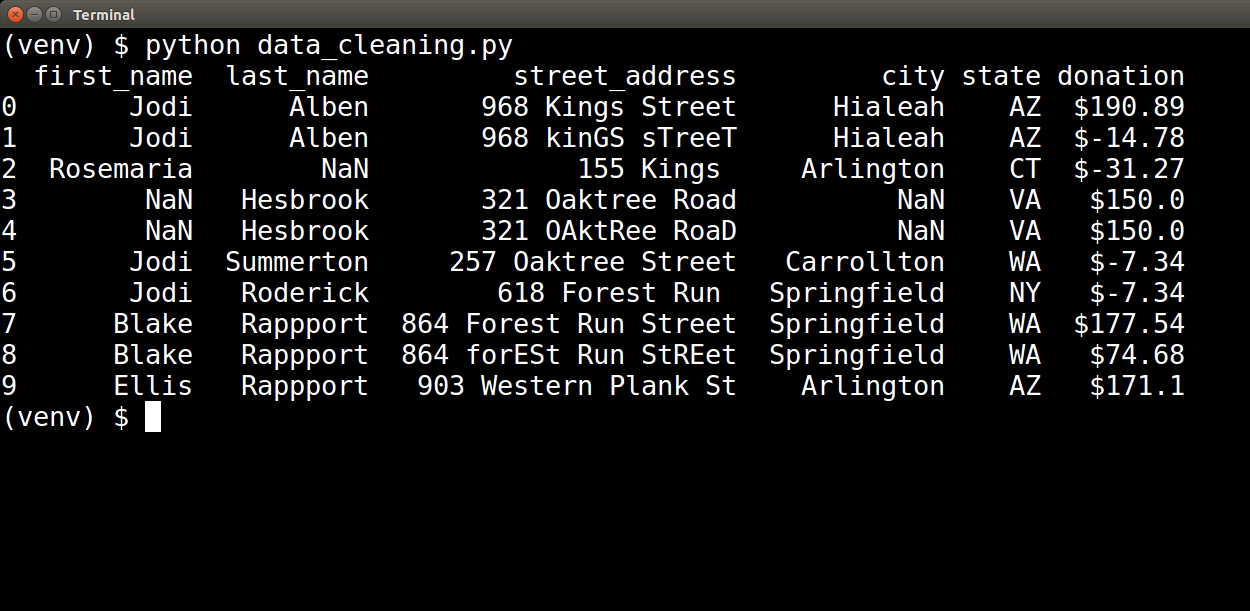
At the top of the output, we see the following two lines: RangeIndex: 29 entries, 0 to 28Data columns (total 6 columns):This indicates that our dataset contains twenty-nine records and six attributes. Below this information, we see a table that lists total non-null entries and the data type for each of the six attributes. Based on this table, we can see that the Given that we will need to perform mathematical calculations on the donation value, this table helped us diagnose a data type issue. Pandas has another powerful tool that will help us diagnose duplication of records. However, we need to clean the data up a bit before applying it. Let's go ahead and start cleaning up some of the issues we diagnosed in our dataset. Cleaning the DataData TypesFirst, we will tackle the data type issue we just discovered. Currently, donation-related values have a type of object. Pandas uses the object data type for strings. We need to convert from the object data type into a numerical data type. But first, let's take another quick look at the strings in the donation column. Notice that these strings start with a dollar symbol (
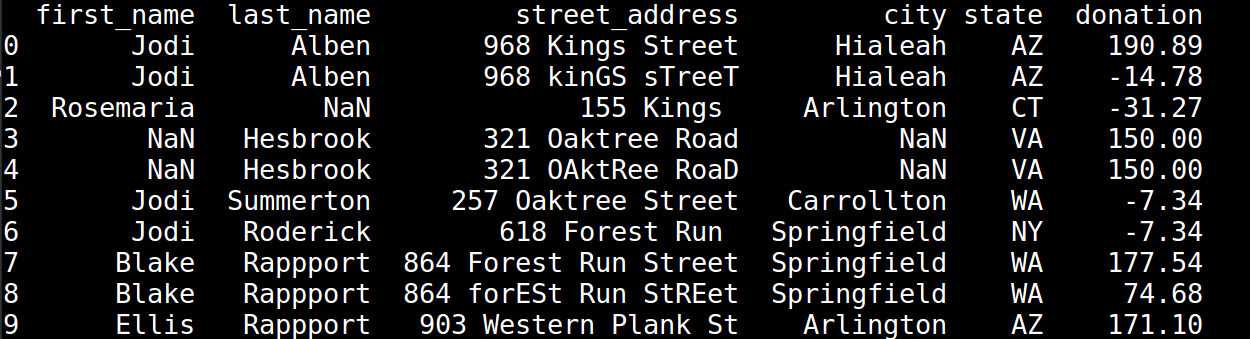
Before attempting to convert these strings into numbers, we need to eliminate the dollar symbol. We can remove the dollar symbol from the donation values by using the following code: To cast the donation values from a string to a float, we can use the following code: Create another script that puts all this together: Running the script above will produce the following two tables:
As you can see, the donation values are represented with a numerical data type. Now we will be able to run calculations on those values. InconsistencyNow that we have addressed the data type issues we diagnosed, let's turn to the problem of inconsistent data. In our diagnostic step, we saw data inconsistency in the
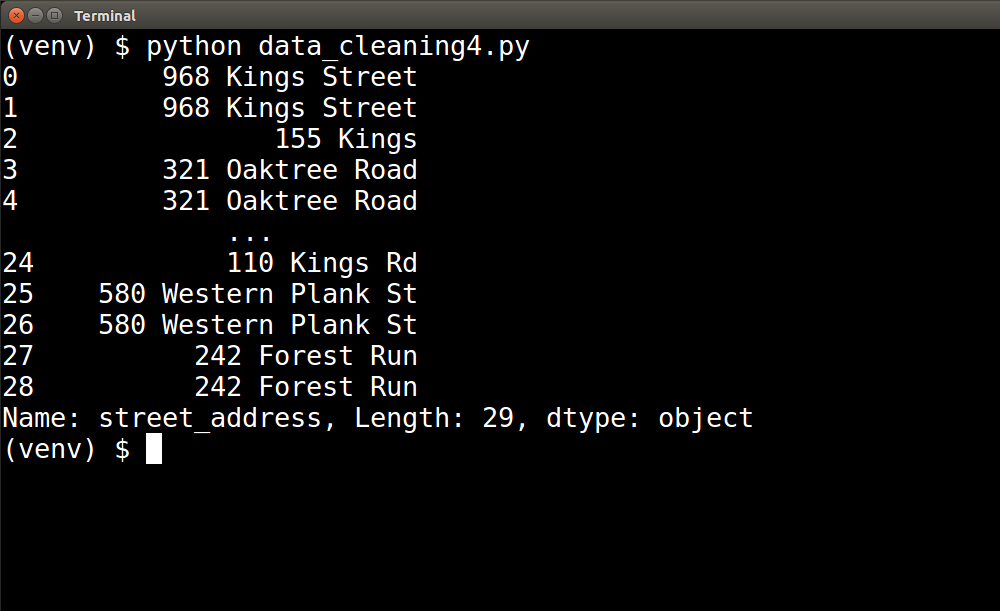
There are three types of inconsistencies here. First, we have inconsistent capitalization. Next, we have inconsistent usage of abbreviations. For example, in some cases, we see "Street," while in others, we see "St." And finally, we have some incomplete street addresses, such as "155 Kings", as pictured above. To clean up the capitalization issue, we will add the following code to the script we used to convert the donation data type: On line 20, we use: To break the To do that, we will create a function that capitalizes every string in the list except for the first string. We skip the first string because that string represents the number part of the Once we have the function that we want to apply to each row of the At this point, our We need to take the final step of converting the list of strings back into a single string with each word separated by a space (' '). We can do that by using the following line of code: Once we have added all of these updates to our script, we can run the script to produce the following printout of the
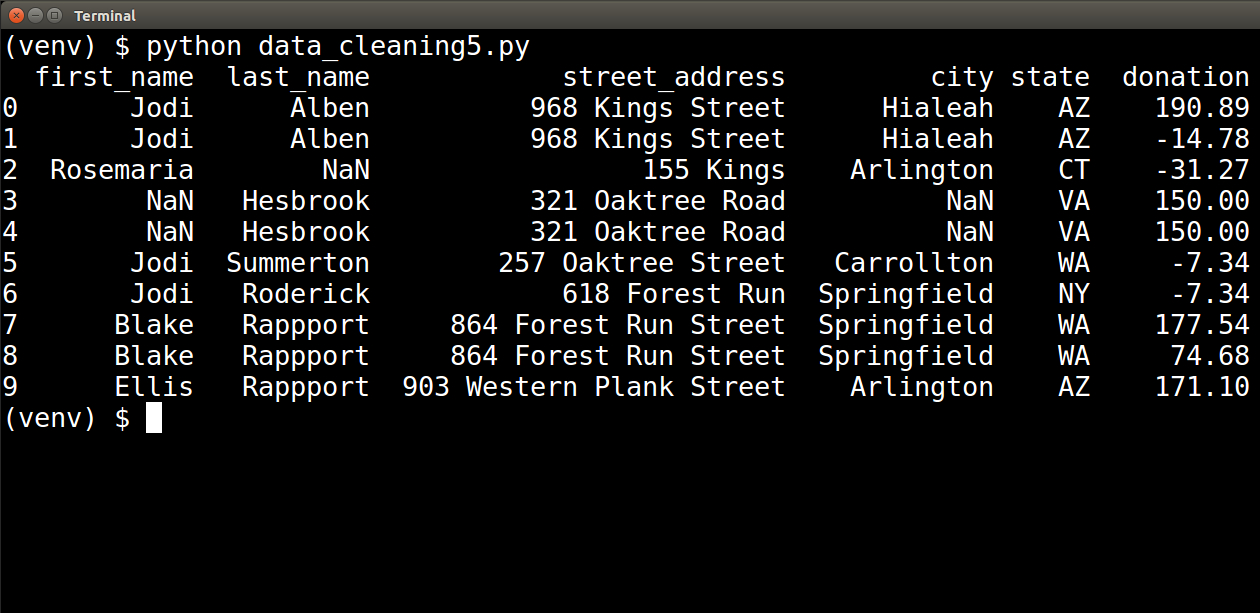
Now we need to handle the second inconsistency issue: inconsistent usage of abbreviations. Let's extend the code we just created for capitalizations. Here, we combine the work of capitalizing each word in the string with that of expanding abbreviated road types. When we run the updated script pictured above, we will see the following:
Finally, we must decide what to do with incomplete addresses. This is where we must rely on context once again to help guide our decision. We must determine whether those errors indicate garbage data that we do not want to include in our analysis. For our purposes in this article, we will leave records with incomplete addresses at this stage. An incomplete Out-Of-Range and Duplicate ValuesNext, we need to look at the outliers in our dataset. As mentioned before, any negative donation values do not make sense within the context of our problem domain. If we include these negative values in our donation calculations, they will erroneously skew our totals. This is a strong signal for garbage data, so we will simply filter out any records with negative donation values. To filter out records that have negative donation values, we can add the following code to our script: We create a Boolean Series and assign it to the We then use that Boolean Series to filter out the negative values in our donation Series. We keep those values that are not out of range. Once we run the updated script, we should be able to see the following table:
Notice that all the negative donation values have been filtered out. In the table, the value Duplicate records should also be removed from our dataset. In our donor scenario, it is unlikely to have a duplicate donation from the same person living at the same address. Much like the negative donation values, these types of duplicates are strong signals for garbage data. They could skew the results of any calculations we run on the donation attribute. We will need to remove them as well. Add the following code to our script to create a new data frame that does not have rows with the same first name, last name, street address, city, and state. This code will keep the first occurrence of any such row and drop any duplicates. Running the updated script will generate the following info table:
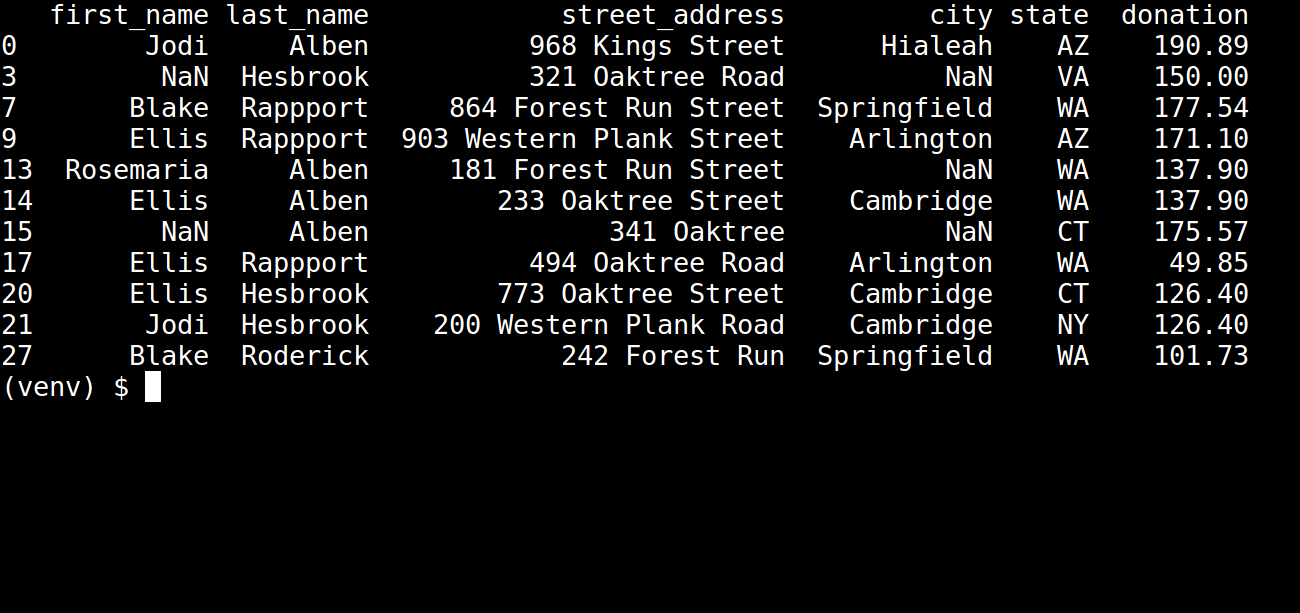
Notice the number of total records in our Missing ValuesEarlier in the article, we saw that we had several missing values across different attributes of the dataset. These missing values were initially in the We intentionally saved this step until the end so we could see what remained in our dataset after going through all the other cleaning techniques. Some missing values are tolerable, while others would prevent our dataset analysis. At this point, we can see that any rows with a missing donation are useless for us, so we will drop those. Also, a missing state value will throw off our attempt to aggregate donation information by region of the United States. That being the case, we will also opt to drop those rows. To drop rows with a missing donation or state values, we can add the following code to our script: This code will drop any rows that have
Our dataset looks much cleaner now! Now that we have finished cleaning our data, we can export the clean dataset into a new This clean dataset file ( ConclusionIn this article, we looked at the process of cleaning data. The process starts by diagnosing the different ways in which our dataset may be inconsistent. From there, we have many techniques available to clean the data. It is important to have context in the domain of our problem to know which technique is the best fit for the problems we see in our dataset. Cleaning data is critical because it can help us to avoid drawing erroneous conclusions and acting on faulty assumptions. If you would like to learn how to explore your data after cleaning it, then go over to my blog, where you will learn about Exploratory Data Analysis in Python. You can get all the scripts used in this tutorial here. Learn also: K-Fold Cross Validation using Scikit-Learn in Python Happy coding ♥ Liked what you read? You'll love what you can learn from our AI-powered Code Explainer. Check it out!
Sharing is caring!
Read also
K-Fold Cross Validation using Scikit-Learn in PythonLearn how you can perform K-Fold cross validation technique using the scikit-learn library in Python. 
Logistic Regression using PyTorch in PythonLearn how to perform logistic regression algorithm using the PyTorch deep learning framework on a customer churn example dataset in Python. 
Customer Churn Prediction: A Complete Guide in PythonLearn how to perform data analysis and make predictive models to predict customer churn effectively in Python using sklearn, seaborn and more. CommentsGot a coding query or need some guidance before you comment? Check out this Python Code Assistant for expert advice and handy tips. It's like having a coding tutor right in your fingertips! |
| You are visitor 01402503 — GeezerVison does not store the pages you look up. Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required. |