GeezerVisonThe World Wide Web, restored to 800 pixels of glory. |
| Home|About|Gaming cabinet|Archives|How it works|Starter sites |
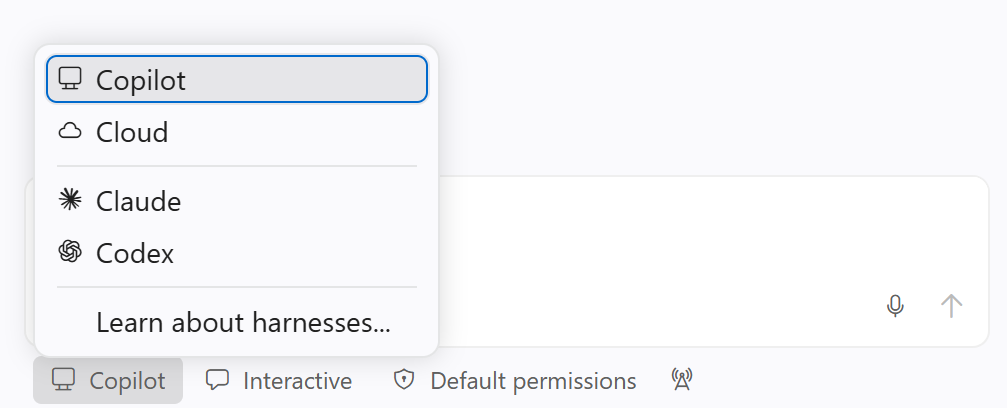
GeezerVison is showing code.visualstudio.com — Models & Agent Harnesses - Visual Studio Code Use the agent harness and models you wantVS Code lets you choose the harness and model separately. Work with GitHub Copilot, Claude Code, or Codex, then choose a model from Anthropic, OpenAI, Google, Microsoft, or an open-weight model. Switch either one when the task changes. Choose how your agent worksPick the agent harness you want, the model it uses, and where your requests run. Use the harness you already knowRun GitHub Copilot, Claude Code, or Codex in VS Code. Each harness brings its own tools, permissions, and way of working with your code. Pick a model for the taskChoose from several providers and open-weight models. Compare speed, reasoning, and context limits instead of using the same model for every job. Decide where requests runUse your provider subscription, send requests through an endpoint you control, or run a model locally when you need offline access or want code to stay on your machine. The harness controls how the work gets doneThe agent harness determines where work runs, how it interacts with your workspace, and when it asks for approval. Switch harnesses mid-session and VS Code carries your conversation history and context along with it. Learn about code isolation and handoff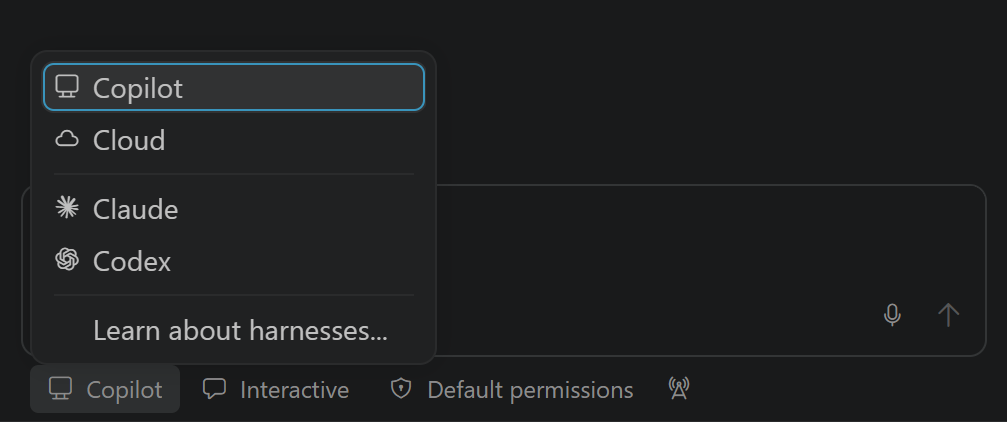
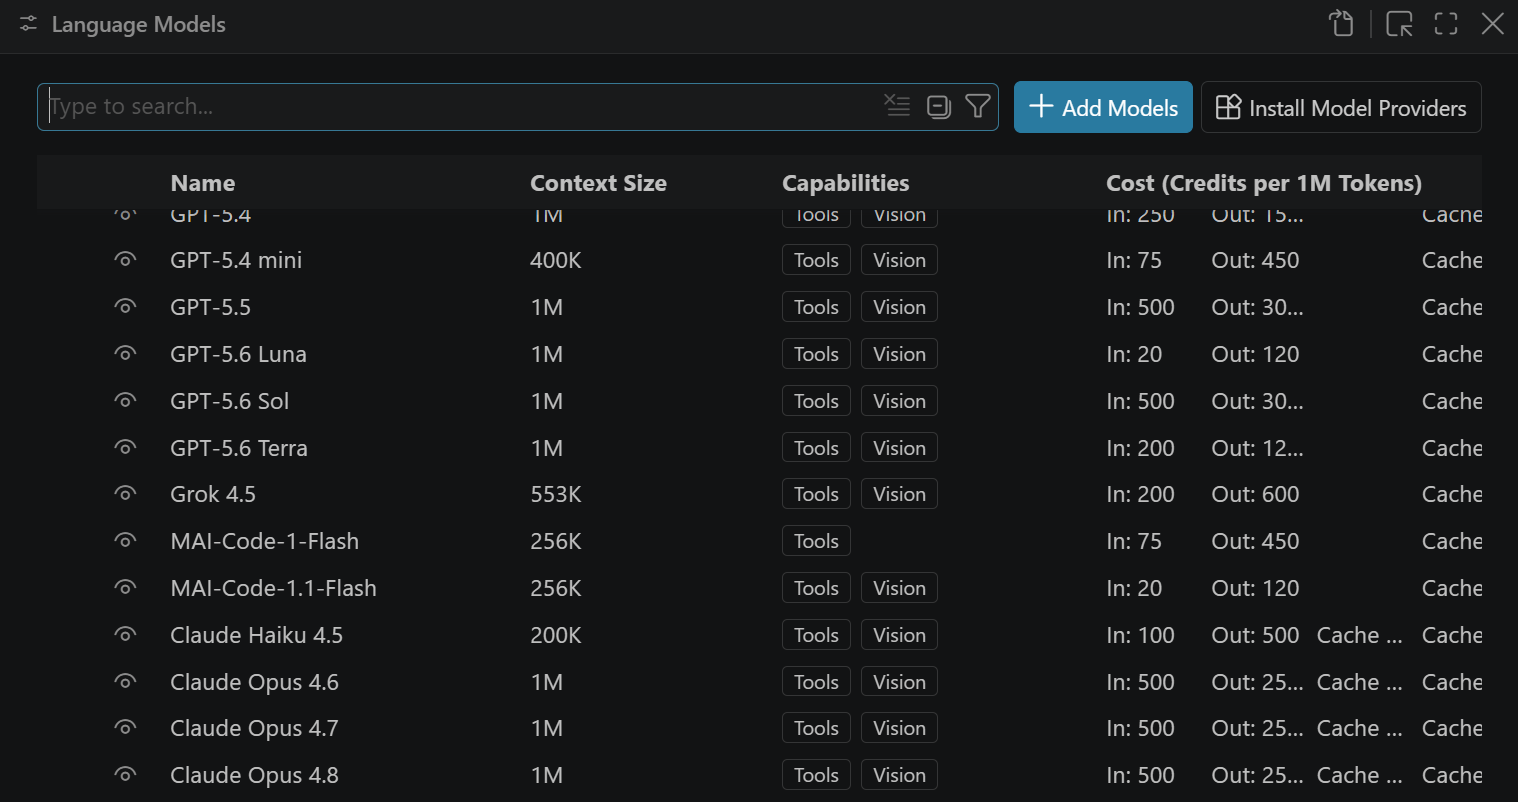
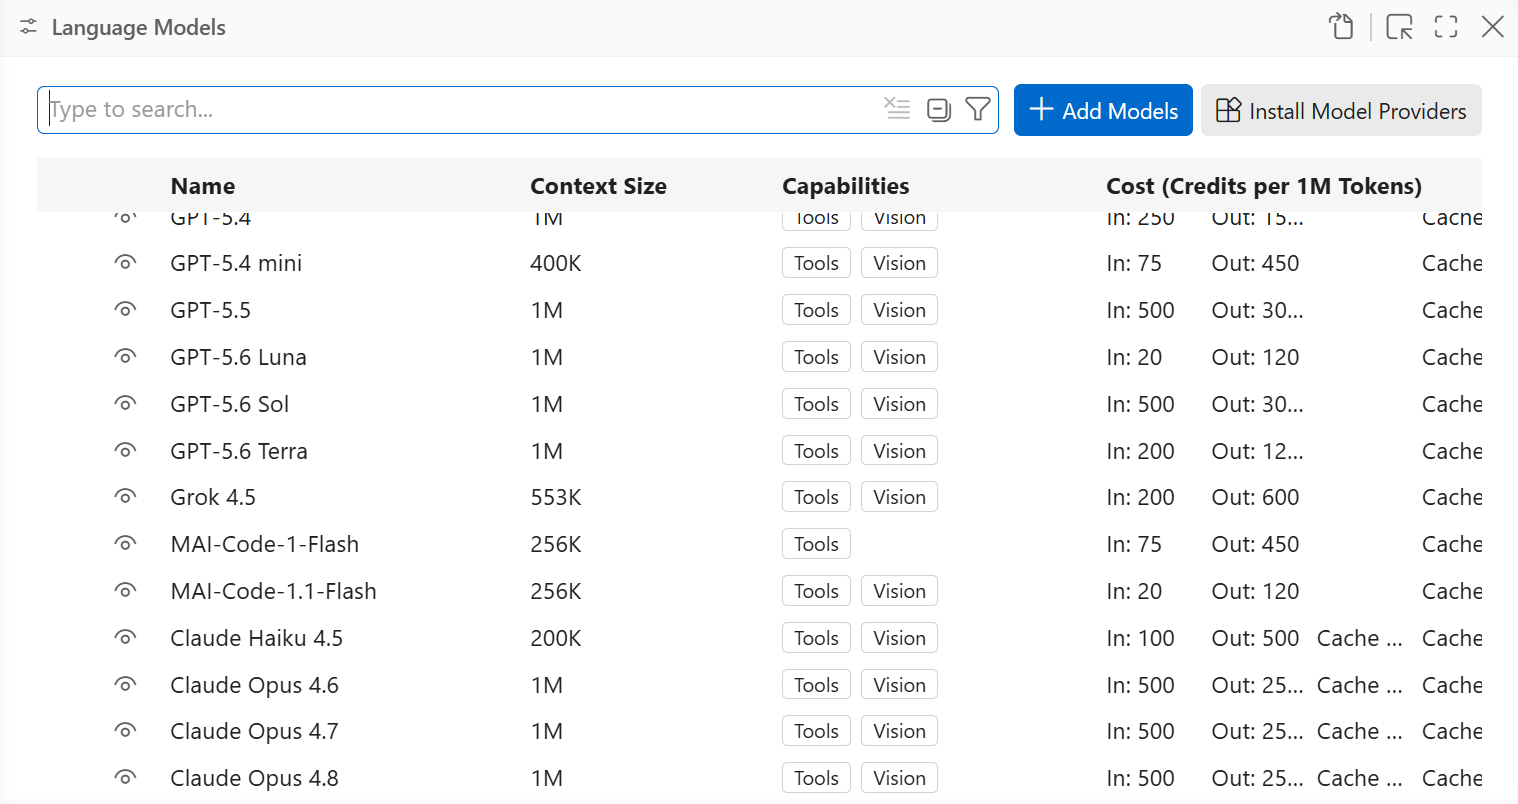
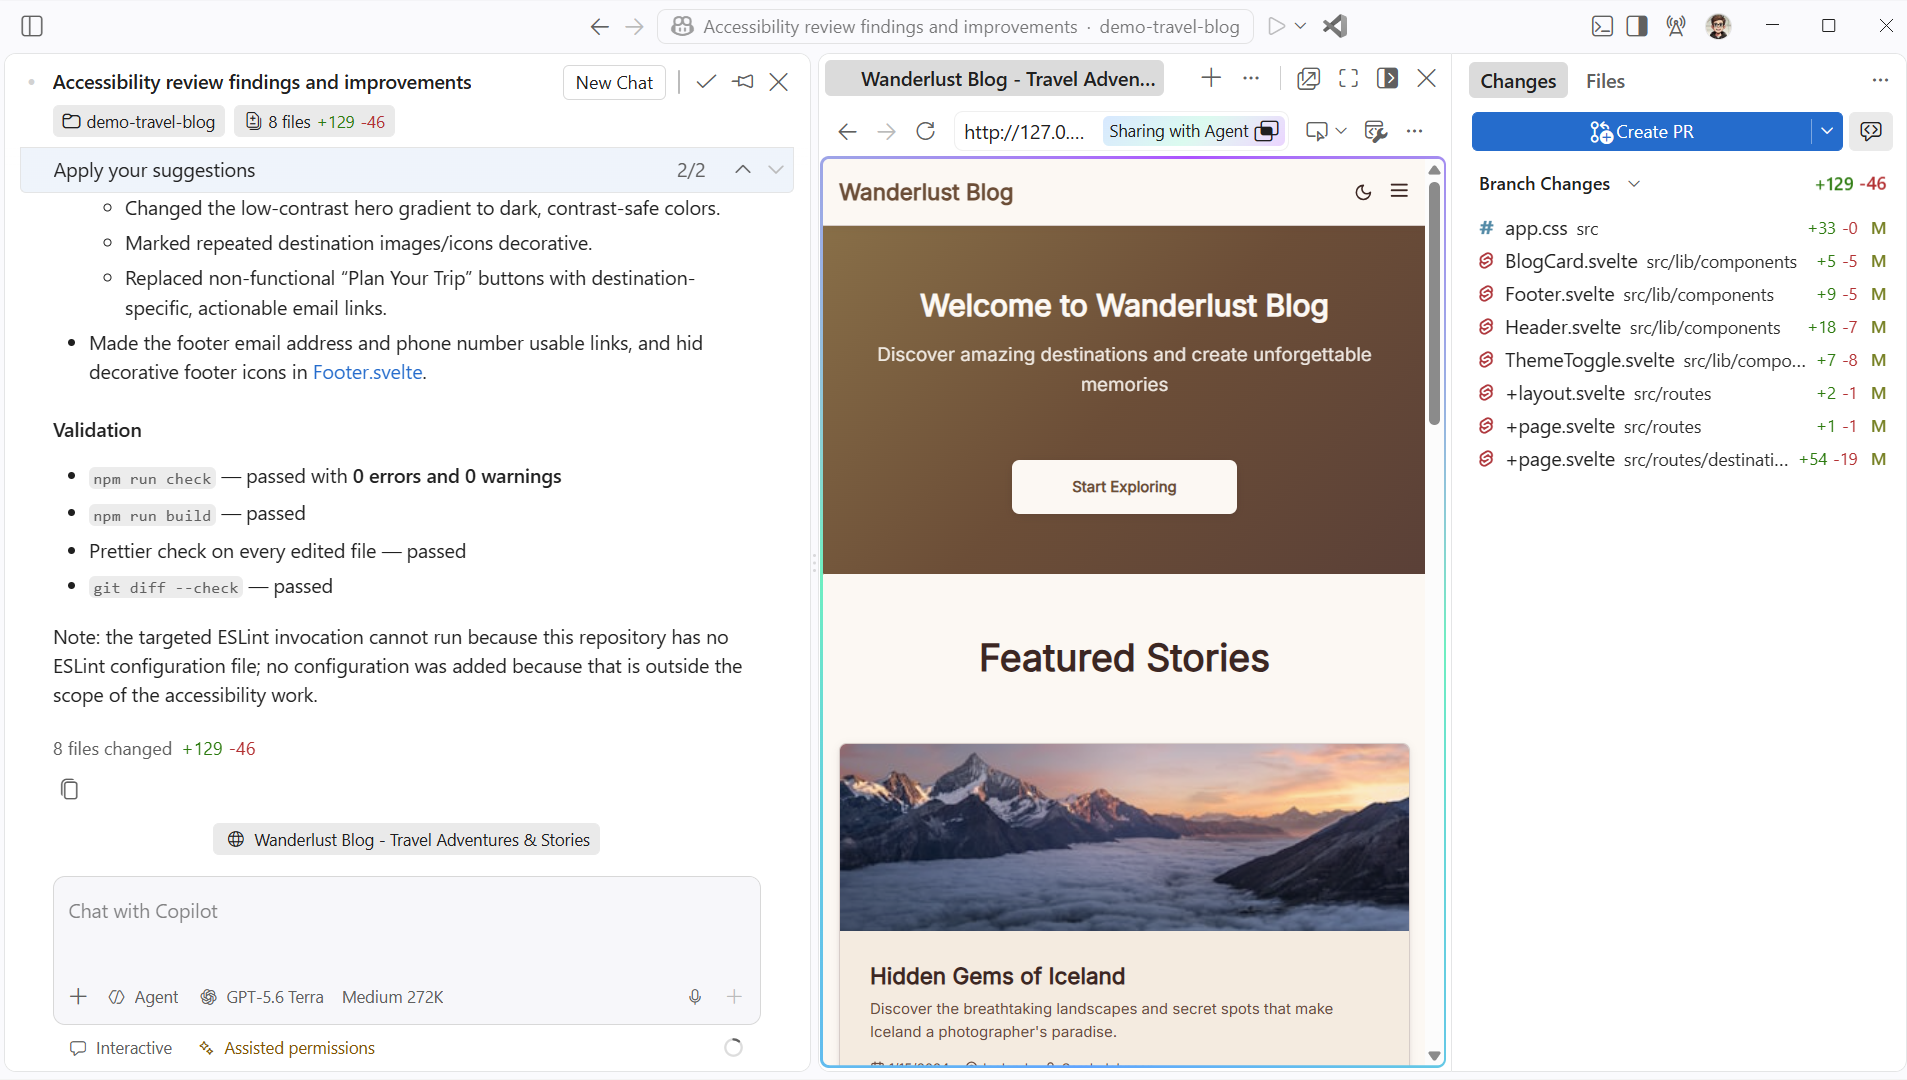
Pair it with the right modelSwitch models as your needs change, compare how they handle the same task, and adopt new releases as they land. See supported language modelsGet more from every AI creditModels use AI credits at different rates. Check the rate before you start, then choose the model that gives the task enough capability without spending more than it needs. Optimize AI credit usage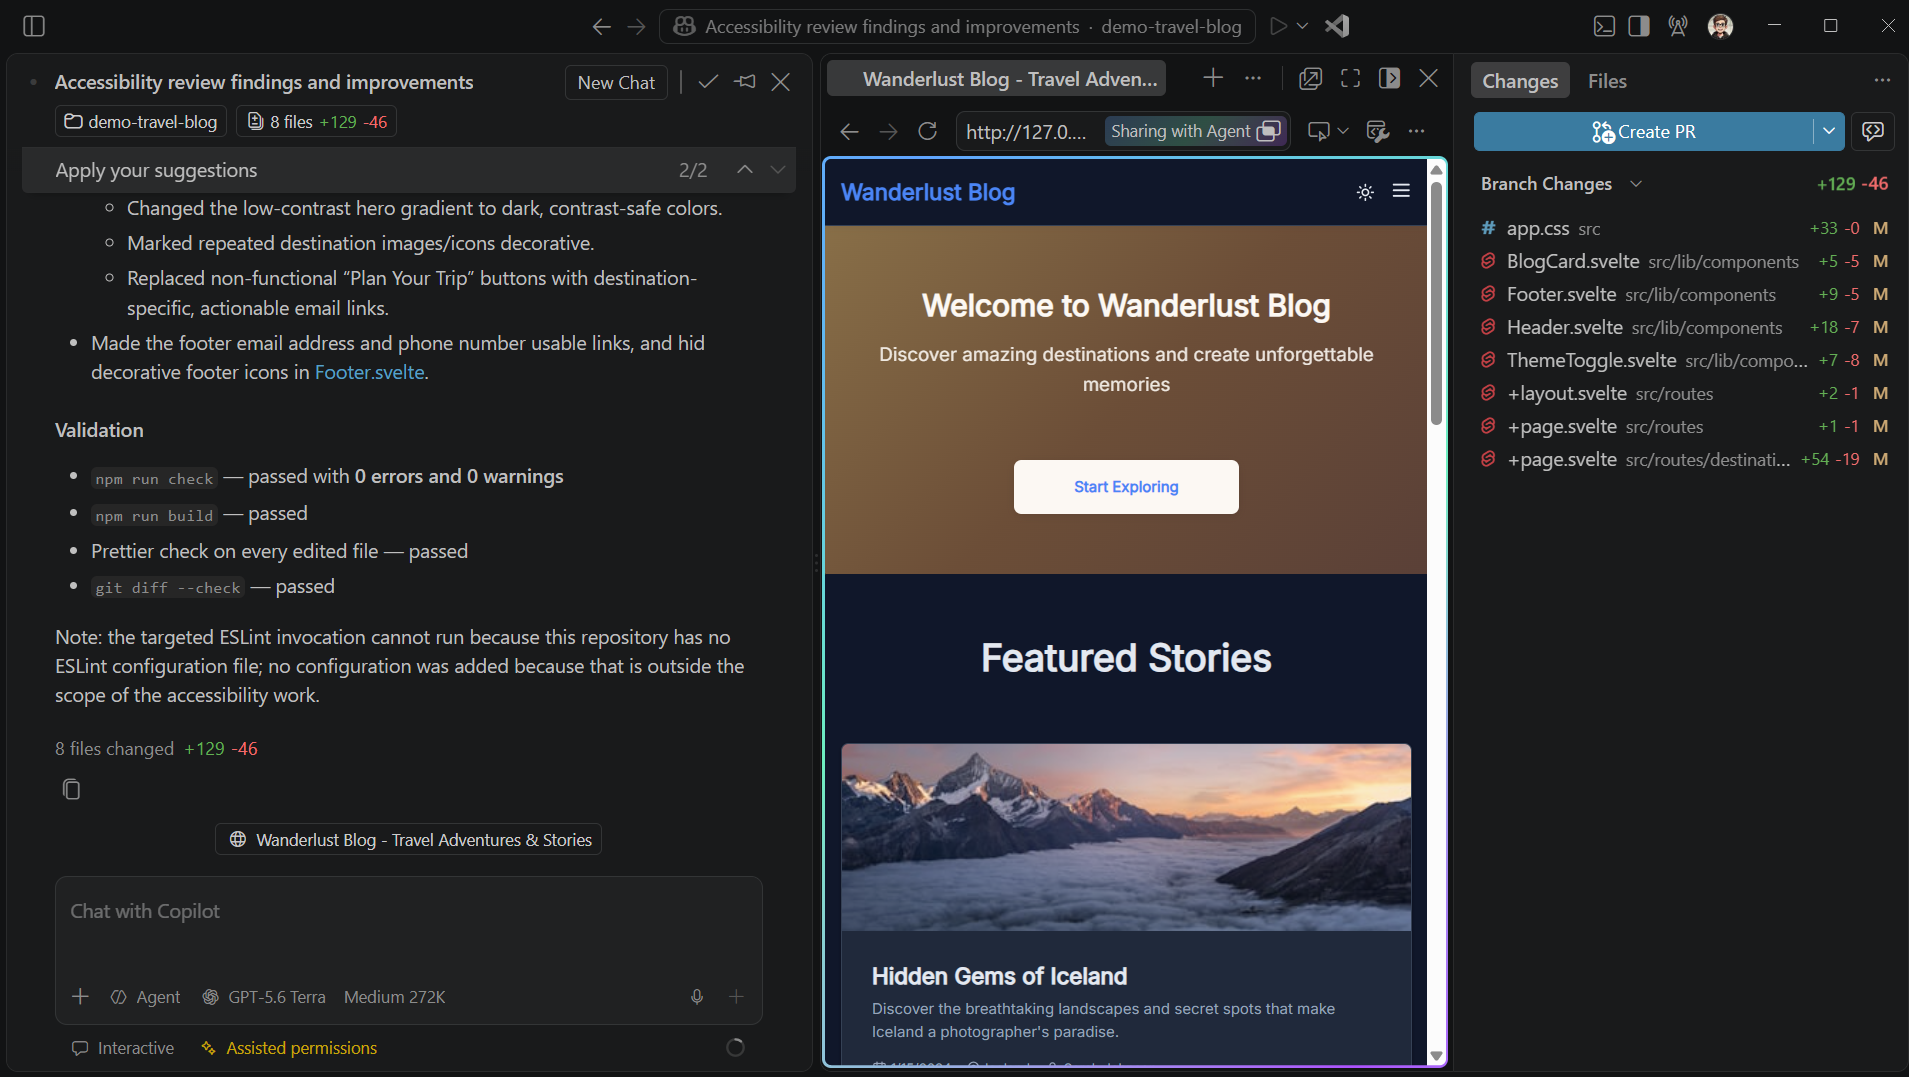
Bring your own keyConnect a provider account with your own API key, or send model requests through infrastructure you control. You can also run supported models locally when the work needs to stay offline or on your machine. Configure your own model provider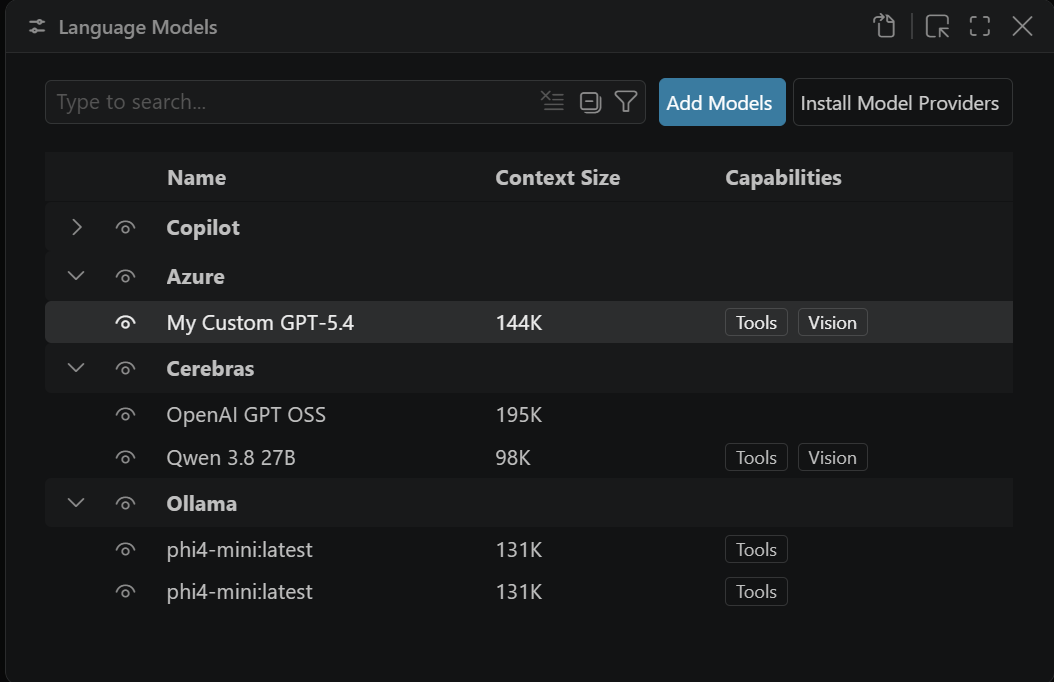
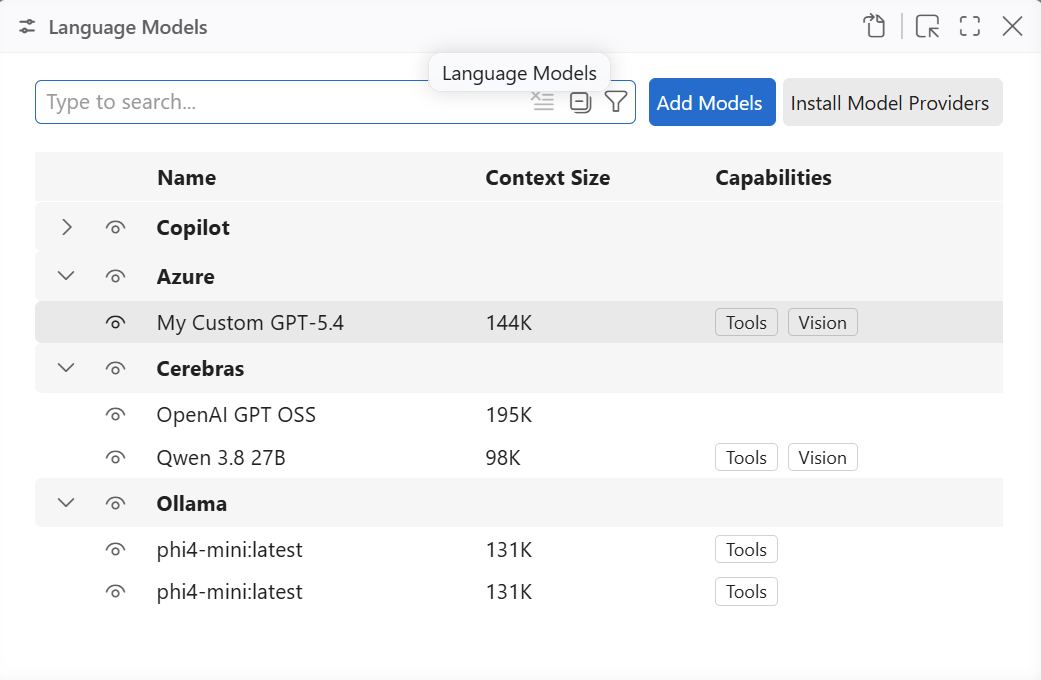
And much moreLanguage modelsSee which models are available, how to add a provider, and how to switch between them. Auto model selectionLet VS Code route each request to an efficient model based on task complexity and service health. Configure thinking effortDial reasoning up for complex problems, or down to reduce latency and AI credit use. Cache ExplorerDiagnose prompt cache misses between requests to reduce token cost and latency. Custom agentsPin a specific model to a purpose-built agent so the right one is always used for the job. Pick the harness and model that fit the workStart with the harness and model you already know. Switch when the work needs different tools, stronger reasoning, lower cost, or local execution. |
| You are visitor 01402503 — GeezerVison does not store the pages you look up. Best viewed with Netscape Navigator 4.7 or Internet Explorer 6 at 800×600. No cookies required. |
 Download